Though there are three versions of the DP-750 practice braindumps: the PDF, Software and APP online, i love the PDF version the most for its printable advantage which is unique and special. After printing, you not only can bring the DP-750 study materials with you wherever you go, but also can make notes on the paper at your liberty, which may help you to understand the contents of our DP-750 Learning Materials. Do not wait and hesitate any longer, your time is precious!
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
>> Valid Braindumps DP-750 Book <<
Our DP-750 training quiz is provided by PDF, Software/PC, and App/Online, which allows you to choose a suitable way to study anytime and anywhere. The PDF versions of DP-750 study materials can be printed into a paper file, more convenient to read and take notes. You can also try the simulated exam environment with DP-750 software on PC. Anyway, you can practice the key knowledge repeatedly with our DP-750 test prep, and at the same time, you can consolidate your weaknesses more specifically.
NEW QUESTION # 56
What is the best way to reduce Databricks compute cost for intermittent workloads?
Answer: B
Explanation:
Autoscaling adjusts resources based on workload demand, and auto-termination shuts down idle clusters, reducing cost significantly. All-purpose clusters are always on. Increasing size raises cost. Single-node clusters limit scalability and are not suitable for production workloads.
NEW QUESTION # 57
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.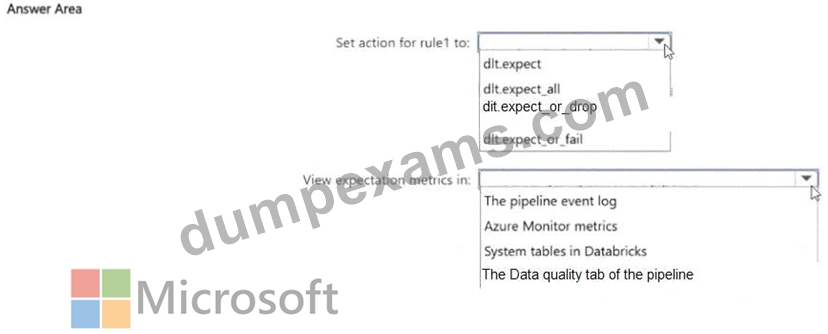
Answer:
Explanation: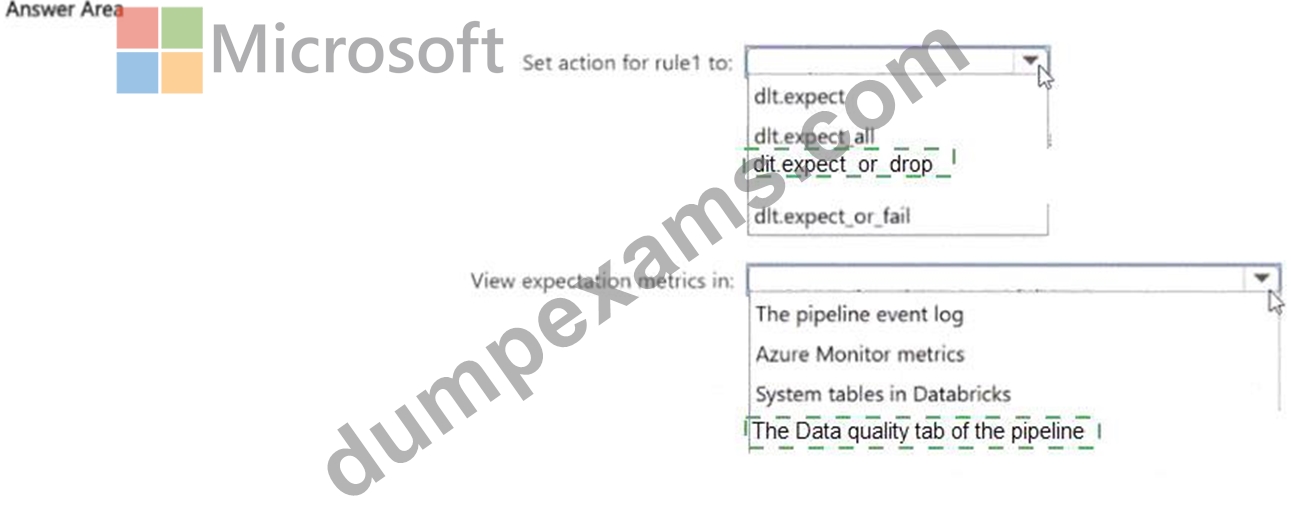
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 58
Which feature helps reduce data scan during query execution in Delta Lake?
Answer: D
Explanation:
Delta Lake uses data skipping based on file-level statistics (min/max values). This reduces unnecessary file scans and improves query performance. VACUUM removes old files but does not improve query speed. Cluster restart has no impact on query optimization.
NEW QUESTION # 59
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.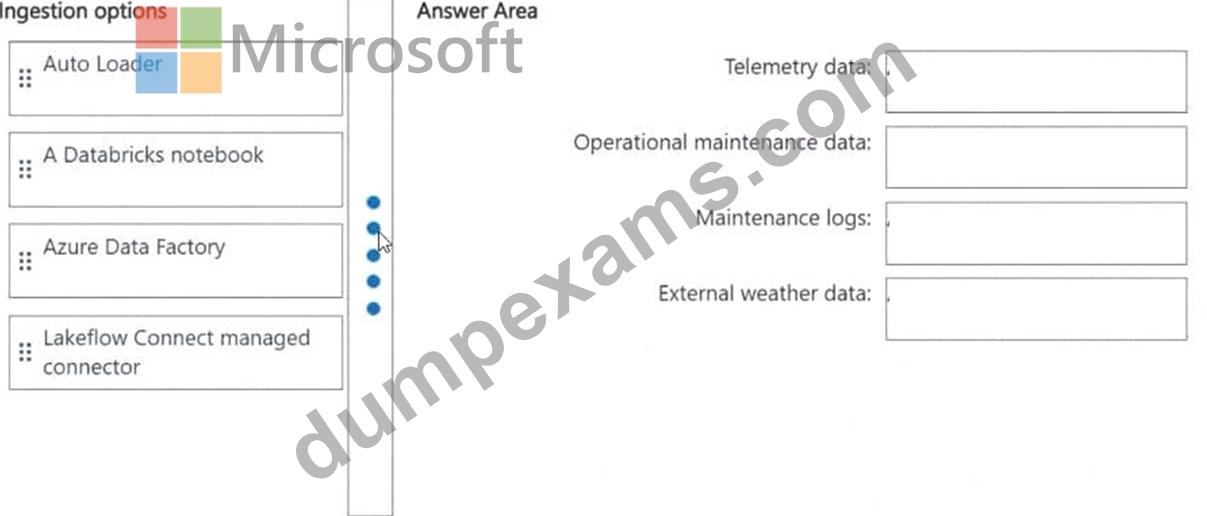
Answer:
Explanation: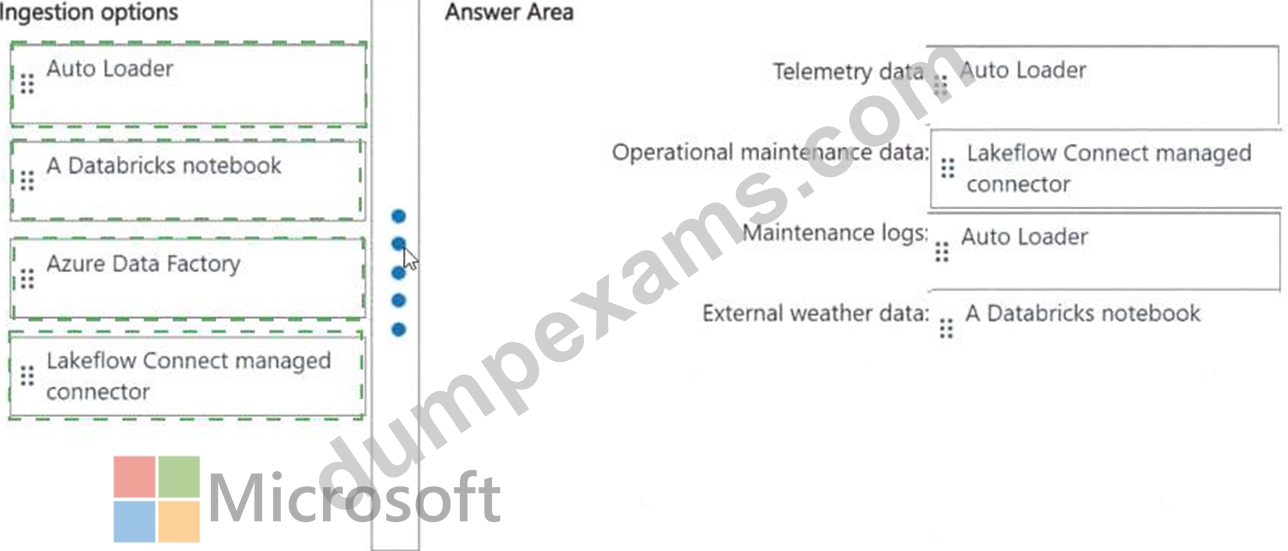
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 60
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Finance
* A schema named Purchases in the Finance catalog
* A table named Transactions in the Purchases schema
You need to ensure that a user named finance_user can query the Transactions table. The solution must follow the principle of least privilege.
Which permission should you grant to finance_user for each object? To answer, drag the appropriate permissions to the correct objects. Each permission may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.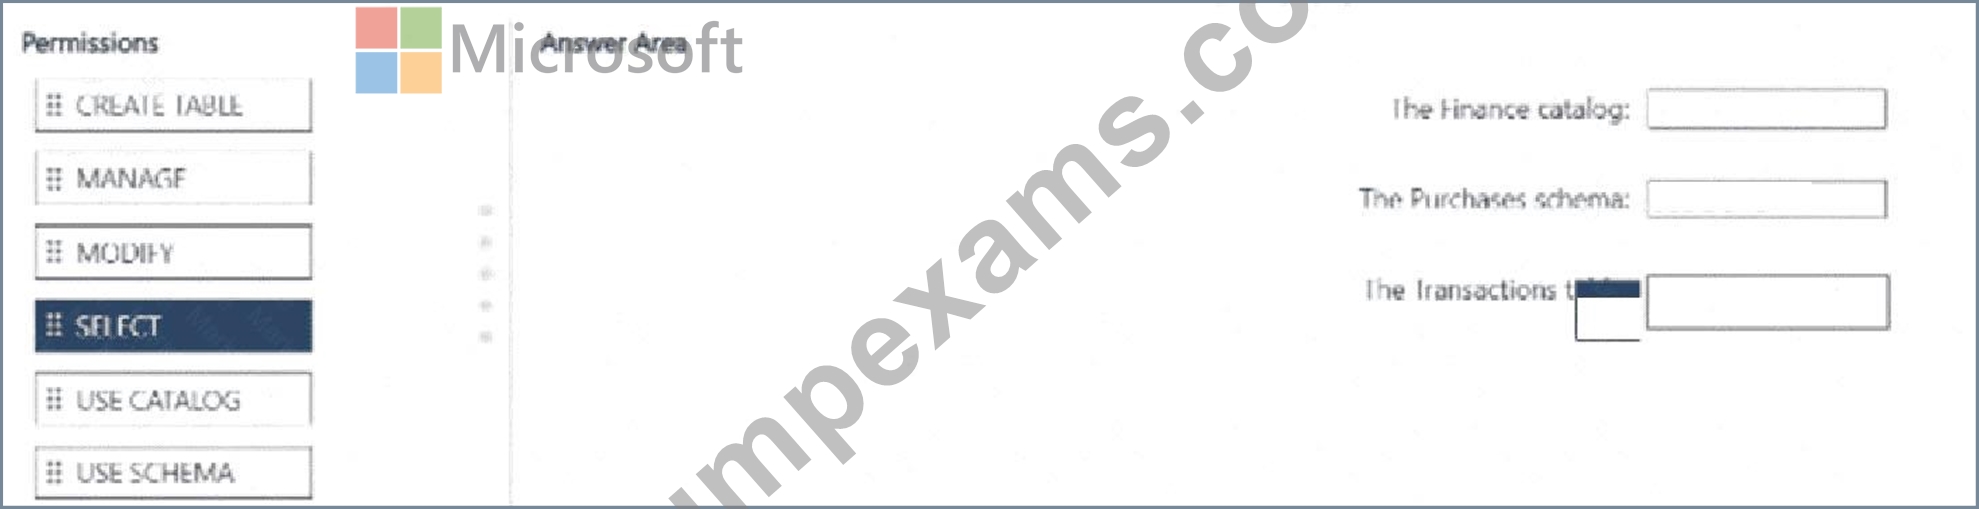
Answer:
Explanation: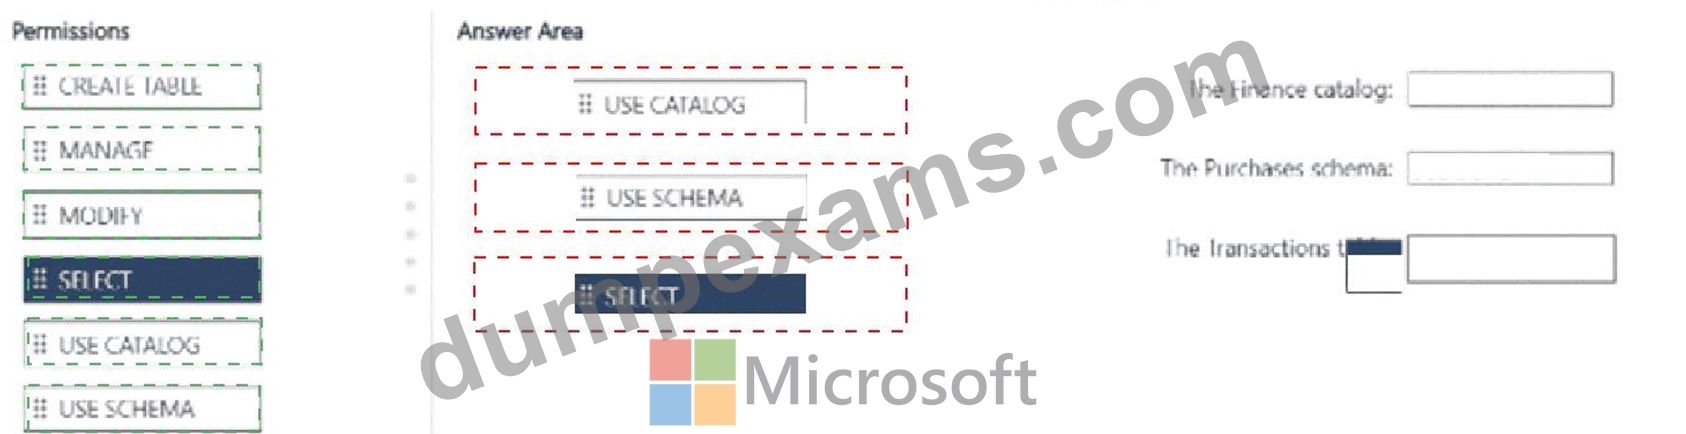
* The Finance catalog: USE CATALOG
* The Purchases schema: USE SCHEMA
* The Transactions table: SELECT
NEW QUESTION # 61
......
Considering many exam candidates are in a state of anguished mood to prepare for the DP-750 exam, our company made three versions of DP-750 real exam materials to offer help. All these variants due to our customer-oriented tenets. As a responsible company over ten years, we are trustworthy. In the competitive economy, this company cannot remain in the business for long. But we keep being the leading position in contrast. We are reactive to your concerns and also proactive to new trends happened in this DP-750 Exam.
New DP-750 Test Papers: https://www.dumpexams.com/DP-750-real-answers.html