P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by LatestCram: https://drive.google.com/open?id=1LrHZvEtpxUzq2BMUoiYbdx9Ir-HGZ7Nn
There are a number of distinctions of our DP-100 Exam Questions that make it superior to those offered in the market. Firstly, you will find that there are three different vesions of our DP-100 learning guide: the PDF, Software and APP online. Though the content is the same, but the displays are all different. And you can study in all kind of conditions if you have three of them. Secondly, the prices of every version are favourable. And you can buy the Value Pack with discounted price.
Microsoft DP-100 (Designing and Implementing a Data Science Solution on Azure) Certification Exam is one of the most sought-after certification exams for data science professionals. It is designed to test your skills and knowledge in designing and implementing data science solutions on the Azure platform. Designing and Implementing a Data Science Solution on Azure certification exam is a great way to validate your expertise in data science and demonstrate your ability to leverage Azure technologies to solve complex business problems.
>> Reliable DP-100 Exam Materials <<
The DP-100 exam is on trend but the main problem that every applicant faces while preparing for it is not making the right choice of the DP-100 Questions. They struggle to find the right platform to get actual DP-100 exam questions and achieve their goals. LatestCram has made the product after seeing the students struggle to solve their issues and help them pass the DP-100 Certification Exam on the first try. LatestCram has designed this DP-100 practice test material after consulting with a lot of professionals and getting their good reviews so our customers can clear DP-100 certification exam quickly and improve themselves.
Microsoft doesn’t provide detailed information regarding its exams, including the DP-100 certification test. The total number of questions in exam is not published on the official website, but the candidates can expect to encounter about 40-60 items in their delivery of their test. There is also a high probability that they will face scenario-based questions with single-answer and multiple-answer options. The duration is all about 120 minutes. The exam is available in several languages, including Japanese, English, Simplified Chinese, and Korean.
The Microsoft DP-100 exam can be taken at any nearest Pearson VUE testing center or online as a proctored option. The cost for the exam is $165 in the United States but the price is usually different in other countries due to taxation. To find out the actual pricing for your country, simply check the official webpage.
To pass the DP-100 Exam, you will need to have a solid understanding of statistical concepts, data analysis techniques, and programming languages such as Python and R. You should also have experience working with big data technologies like Hadoop and Spark, as well as experience deploying models to production environments.
NEW QUESTION # 185
Hotspot Question
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.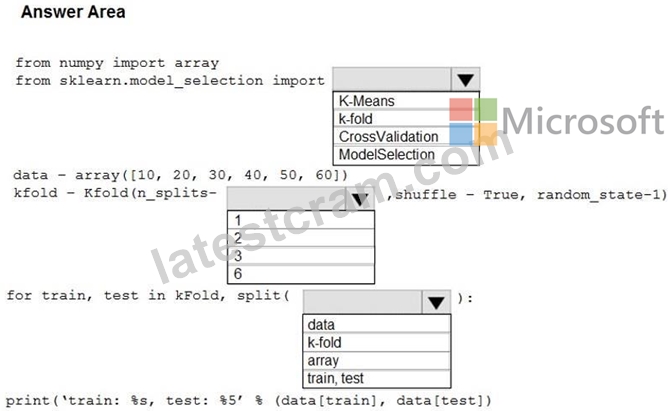
Answer:
Explanation: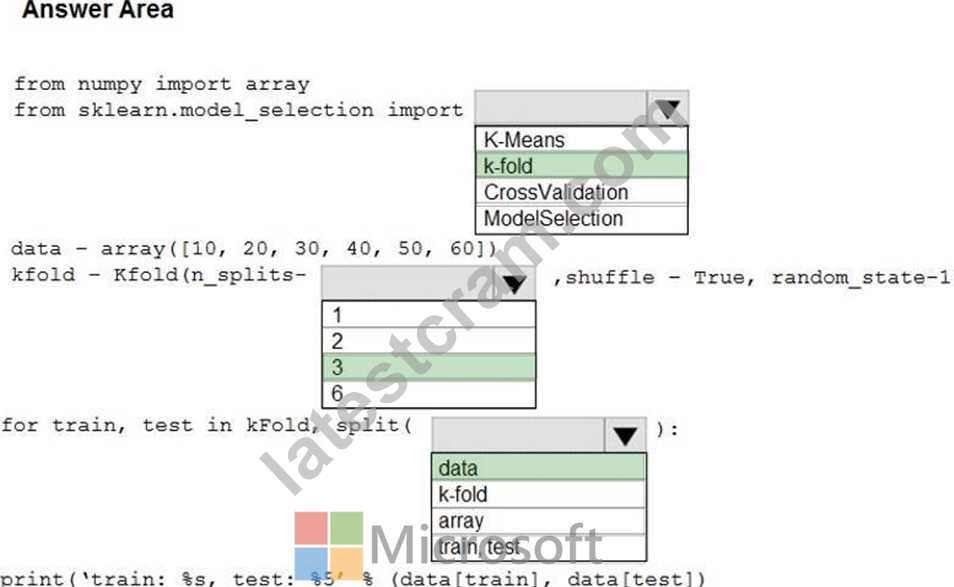
Explanation:
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default). The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
... print("TRAIN:", train_index, "TEST:", test_index)
... X_train, X_test = X[train_index], X[test_index]
... y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 186
You need to identify the methods for dividing the data according, to the testing requirements.
Which properties should you select? To answer, select the appropriate option-, m the answer area. NOTE:
Each correct selection is worth one point.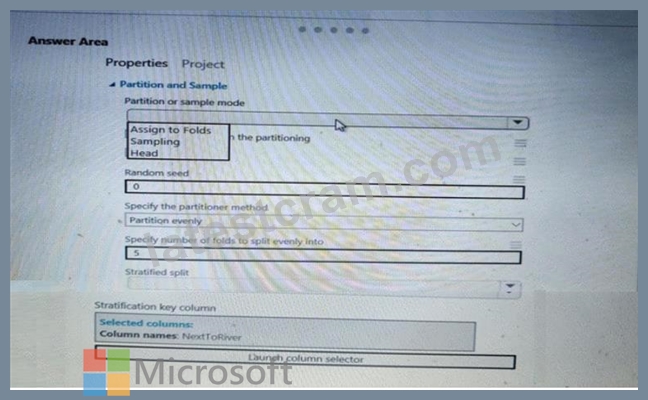
Answer:
Explanation: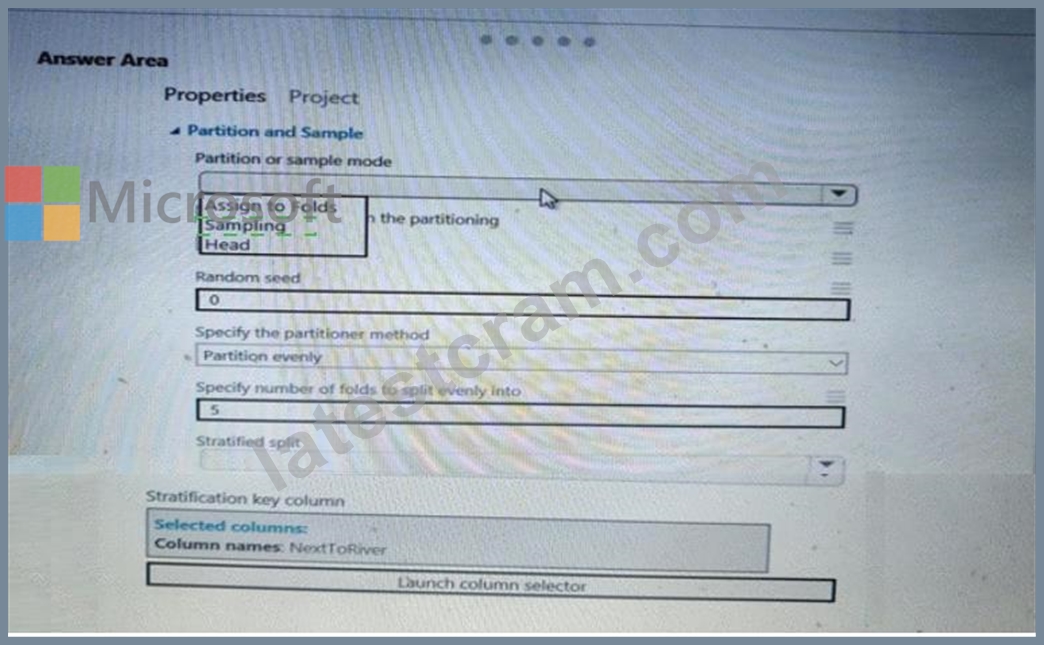
NEW QUESTION # 187
You create a binary classification model by using Azure Machine Learning Studio.
You must tune hyperparameters by performing a parameter sweep of the model. The parameter sweep must meet the following requirements:
* iterate all possible combinations of hyperparameters
* minimize computing resources required to perform the sweep
* You need to perform a parameter sweep of the model.
Which parameter sweep mode should you use?
Answer: B
Explanation:
Explanation
Maximum number of runs on random grid: This option also controls the number of iterations over a random sampling of parameter values, but the values are not generated randomly from the specified range; instead, a matrix is created of all possible combinations of parameter values and a random sampling is taken over the matrix. This method is more efficient and less prone to regional oversampling or undersampling.
If you are training a model that supports an integrated parameter sweep, you can also set a range of seed values to use and iterate over the random seeds as well. This is optional, but can be useful for avoiding bias introduced by seed selection.
Topic 2, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: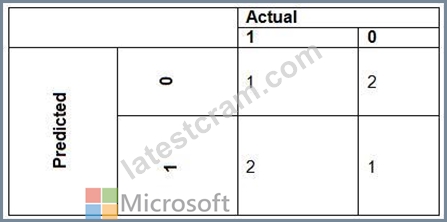
The ad propensity model uses proposed cost factors shown in the following diagram: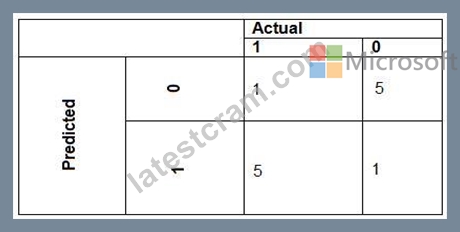
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: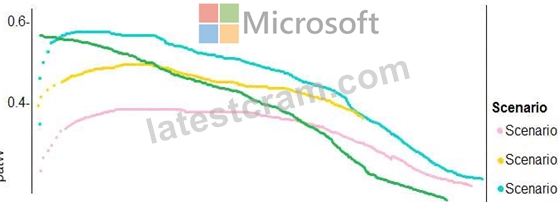
Penalty detection and sentiment
Findings
*Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
*Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
*Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
*Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
*Global penalty detection models must be trained by using dynamic runtime graph computation during training.
*Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
*Ad response rates declined.
*Drops were not consistent across ad styles.
*The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
*Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
*All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
*Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
*The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
NEW QUESTION # 188
You use Azure Machine Learning Designer lo load the following datasets into an experiment:
Dataset1: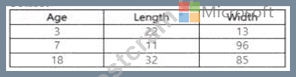
Dataset2: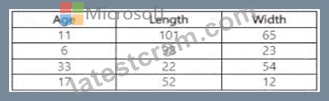
You need to create a dataset that has the same columns and header row as the input datasets and contains all rows from both input datasets.
Solution: Use the Add Rows component.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 189
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: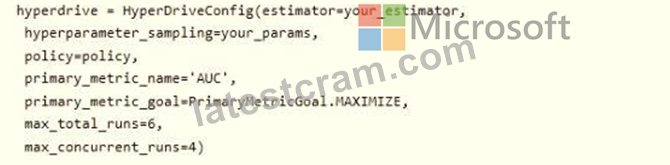
variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted. You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric. Solution: Run the following code: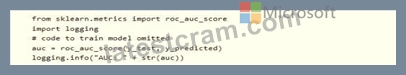
Does the solution meet the goal?
Answer: B
Explanation:
Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 190
......
Latest DP-100 Questions: https://www.latestcram.com/DP-100-exam-cram-questions.html
What's more, part of that LatestCram DP-100 dumps now are free: https://drive.google.com/open?id=1LrHZvEtpxUzq2BMUoiYbdx9Ir-HGZ7Nn