P.S. Kostenlose 2026 Microsoft DP-100 Prüfungsfragen sind auf Google Drive freigegeben von DeutschPrüfung verfügbar: https://drive.google.com/open?id=1kcnUDQakkkLRS4WZzCAUNneVrpEXqakV
Alle Menschen haben ihre eigenes Ziel, aber wir haben ein gleiches Ziel, dass Sie Microsoft DP-100 Prüfung bestehen. Dieses Ziel zu erreichen ist vielleicht nur ein kleiner Schritt für Ihre Entwicklung im IT-Gebiet. Aber es ist der ganze Wert unserer Microsoft DP-100 Prüfungssoftware. Wir tun alles wir können, um die Prüfungsaufgaben zu erweitern. Und die Prüfungsunterlagen werden von unsere IT-Profis analysiert. Dadurch können Sie unbelastet und effizient benutzen. Um zu garantieren, dass die Microsoft DP-100 Unterlagen, die Sie benutzen, am neuesten ist, bieten wir einjährige kostenlose Aktualisierung.
| Section | Objectives |
|---|---|
| Topic 1: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 2: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Topic 3: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 4: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 5: Design and prepare a machine learning solution | - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace - Manage compute and data assets |
Viele Leute, die in der IT-Branche arbeiten, wissen die mühsame Vorbereitung auf die Microsoft DP-100 Prüfung. Wir DeutschPrüfung können doch den Schwierigkeitsgrad der Microsoft DP-100 Prüfung nicht ändern, aber wir können die Schwierigkeitsgrad der Vorbereitung für Sie vermindern. Ihre Angst vor der Microsoft DP-100 Prüfung wird beseitigen, solange Sie die Prüfungsunterlagen von unserem Technik-Team probiert haben. Wir tun unser Bestes, um Ihnen zu helfen, Ihre Konfidenz für Microsoft DP-100 zu verstärken!
503. Frage
You deploy a real-time inference service for a trained model.
The deployed model supports a business-critical application, and it is important to be able to monitor the data submitted to the web service and the predictions the data generates.
You need to implement a monitoring solution for the deployed model using minimal administrative effort.
What should you do?
Antwort: A
Begründung:
Explanation
Configure logging with Azure Machine Learning studio
You can also enable Azure Application Insights from Azure Machine Learning studio. When you're ready to deploy your model as a web service, use the following steps to enable Application Insights:
1. Sign in to the studio at https://ml.azure.com.
2. Go to Models and select the model you want to deploy.
3. Select +Deploy.
4. Populate the Deploy model form.
5. Expand the Advanced menu.
6. Select Enable Application Insights diagnostics and data collection.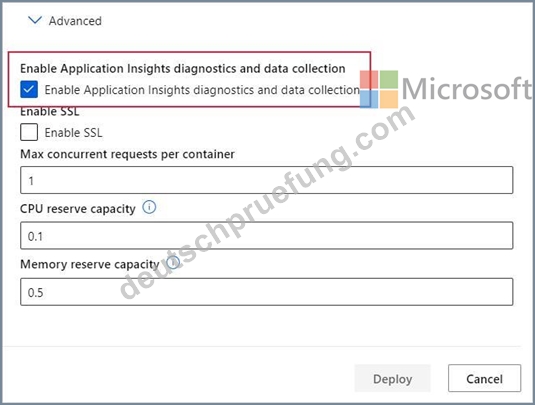
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-enable-app-insights
504. Frage
You tram and register a model by using the Azure Machine Learning Python SDK v2 in a local workstation. Python 3.7 and Visual Studio Code are instated on the workstation.
When you try to deploy the model into production to a Kubernetes online endpoint you experience an error in the scoring script that causes deployment to fail.
You need to debug the service on the local workstation before deploying the service to production.
Which three actions should you perform m sequence? To answer, move the appropriate actions from the list of actions from the answer area and arrange them in the correct order.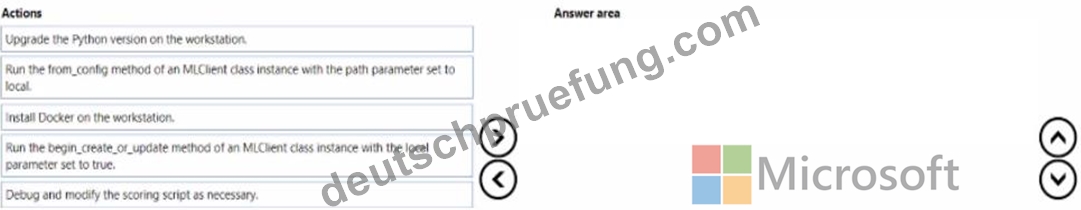
Antwort:
Begründung: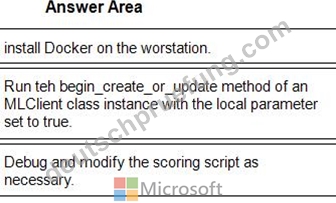
1 - install Docker on the worstation.
2 - Run teh begin_create_or_update method of an MLClient class instance with the local parameter set to true.
3 - Debug and modify the scoring script as necessary.
505. Frage
You train a model by using Azure Machine Learning. You use Azure Blob Storage to store production data.
The model must be re-trained when new data is uploaded to Azure Blob Storage. You need to minimize development and coding.
You need to configure Azure services to develop a re-training solution.
Which Azure services should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.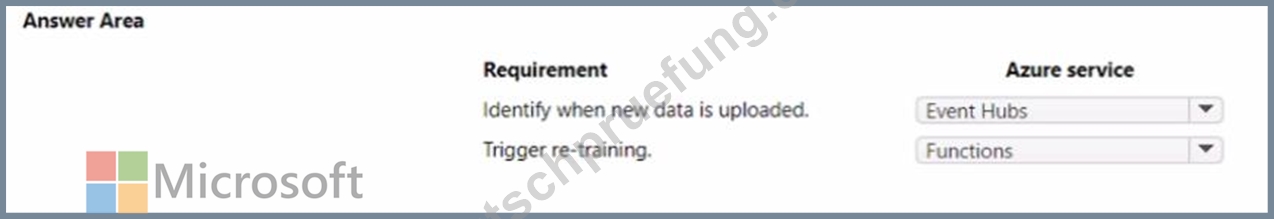
Antwort:
Begründung: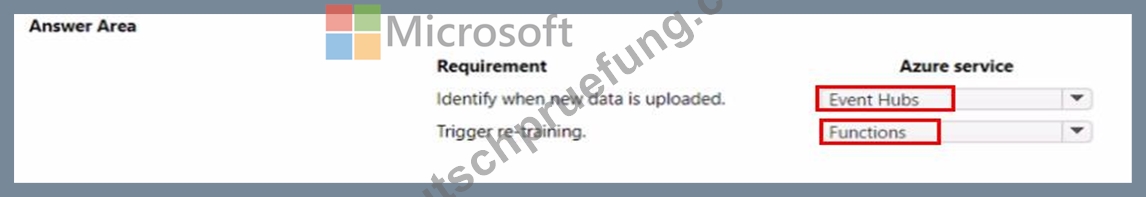
506. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: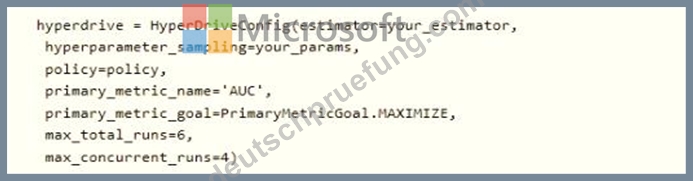
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric. Solution: Run the following code: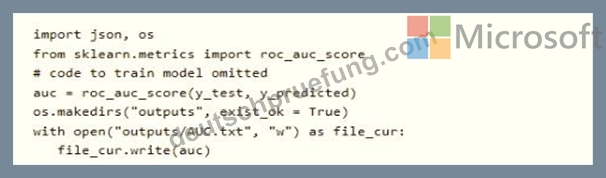
Does the solution meet the goal?
Antwort: B
Begründung:
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
507. Frage
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
Antwort: C
Begründung:
Explanation/Reference:
Explanation:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Incorrect Answers:
B: The Pearson correlation coefficient, sometimes called Pearson's R test, is a statistical value that measures the linear relationship between two variables. By examining the coefficient values, you can infer something about the strength of the relationship between the two variables, and whether they are positively correlated or negatively correlated.
C: Spearman's correlation coefficient is designed for use with non-parametric and non-normally distributed data. Spearman's coefficient is a nonparametric measure of statistical dependence between two variables, and is sometimes denoted by the Greek letter rho. The Spearman's coefficient expresses the degree to which two variables are monotonically related. It is also called Spearman rank correlation, because it can be used with ordinal variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/fisher-linear- discriminant-analysis
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear- correlation Testlet 2 Case study Overview You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: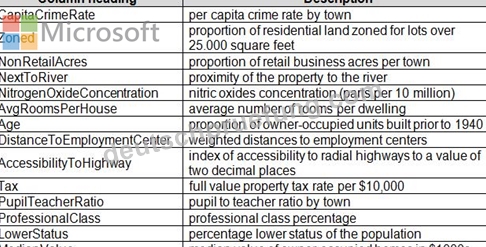
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column. The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning.
You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
508. Frage
......
Wenn Sie sich noch anstrengend bemühen, die Microsoft DP-100 Prüfung zu bestehen, kann DeutschPrüfung Ihren Traum verwirklichen. Die Schulungsunterlagen zur Microsoft DP-100 Zertifizierung von DeutschPrüfung sind die besten und bieten Ihnen auch eine gute Plattform zum Lernen. Die Frage lautet, wie Sie sich auf die Prüfung vorbereiten sollen, um die DP-100 Prüfung 100% zu bestehen. Die Antwort ist ganz einfach. Sie sollen die Fragenkataloge zur Microsoft DP-100 Zertifizierung von DeutschPrüfung wählen. Mit ihr können Sie sich ganz entspannt auf die DP-100 Prüfung vorbereiten.
DP-100 Testengine: https://www.deutschpruefung.com/DP-100-deutsch-pruefungsfragen.html
Außerdem sind jetzt einige Teile dieser DeutschPrüfung DP-100 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1kcnUDQakkkLRS4WZzCAUNneVrpEXqakV