ちなみに、Xhs1991 HPE7-J01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1NDFGoIEeYneAmEWEADIzpopgZF5ZwttG
今日、雇用市場での競争HPE7-J01は過去のどの時代よりも激しくなっています。 Xhs1991良い仕事を見つけたいなら、あなたは良い能力と熟練した主要な知識を所有していなければなりません。 そのため、最高の学習教材を提供するため、HPのHPE7-J01認定を取得する必要があります。 当社のHP試験トレントは高品質で効率的であり、テストに合格するのに役立ちます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Emerging Technologies and Solutions | 10% | - Software-defined storage and modern architectures
|
| Topic 2: Storage Architecture and Design | 30% | - HPE storage portfolio architecture
|
| Topic 3: Deployment and Integration | 20% | - Installation and configuration
|
| Topic 4: Data Protection and Availability | 25% | - Backup and recovery strategies
|
| Topic 5: Management and Optimization | 15% | - Monitoring and administration
|
当社HPが採用した「小利益」の方針により、すべてのお客様と当社の間で双方に有利な状況を達成することを目指しているため、HPE7-J01のすべてのお客様の信頼を獲得することができました。 当社Xhs1991が長年にわたってこのHPE7-J01試験問題の分野で業界のリーダーになっており、当社のHPE7-J01試験のAdvanced HPE Storage Architect Solutions Written Exam教材が世界中でこんなに迅速に販売されているにもかかわらず、手頃な価格を維持しているのはそのためです。 すべてのお客様向けのHPE7-J01学習ガイドであり、有名なブランドを活用したくない。
質問 # 36
Match the fibre channel topology to its use case. Each answer will be used once.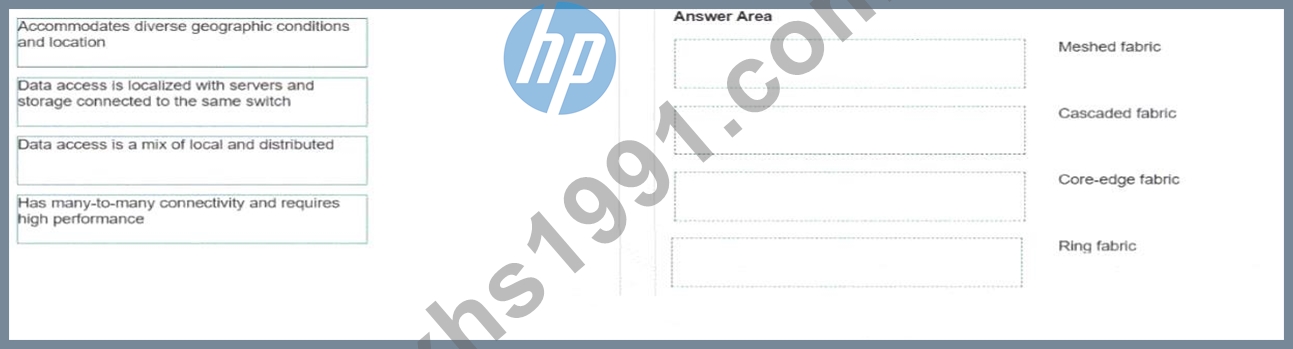
正解:
解説: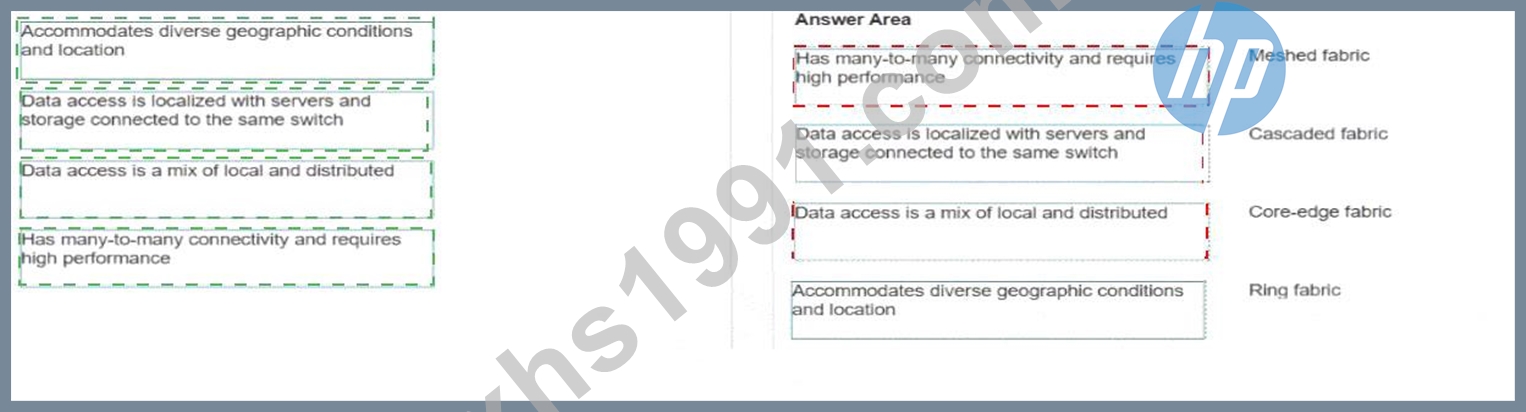
Explanation:
* Meshed fabric: Has many-to-many connectivity and requires high performance.
* Cascaded fabric: Data access is localized with servers and storage connected to the same switch.
* Core-edge fabric: Data access is a mix of local and distributed.
* Ring fabric: Accommodates diverse geographic conditions and location.
In the design of modern Storage Area Networks (SANs), selecting the right topology is critical for balancing performance, scalability, and cost. Each of these Brocade/HPE B-series architectures serves a specific workload profile:
Meshed Fabric: This design provides the highest level of redundancy and performance by connecting switches in an "any-to-any" pattern. Because every switch is connected to multiple other switches, it provides many-to- many connectivity and minimized "hop counts," making it ideal for high-performance environments where application traffic is unpredictable and widely distributed.
Cascaded Fabric: The simplest topology, where switches are connected in a serial or daisy-chain fashion. It is most effective in small environments where data access is localized-meaning the server and the storage it needs are physically connected to the same switch, minimizing Inter-Switch Link (ISL) traversal.
Core-Edge Fabric: The standard for enterprise data centers. Servers are connected to "Edge" switches, and storage is connected to a high-capacity "Core". This allows for a mix of local and distributed data access.
Large enterprises use this to scale easily by adding edge switches without disrupting the core storage connectivity.
Ring Fabric: By connecting switches in a closed loop, this topology is designed to accommodate diverse geographic conditions. If a single link between two locations fails, traffic can be re-routed the other way around the ring. This provides a cost-effective way to link multiple sites or campus buildings while maintaining fabric integrity.
質問 # 37
Which statement is correct regarding Fibre Channel over IP (FCIP)?
正解:D
解説:
Fibre Channel over IP (FCIP), as defined by IETF RFC 3821, is a tunneling protocol used to interconnect Fibre Channel (FC) storage area networks (SANs) over long distances using standard IP infrastructure. One of the primary architectural reasons for choosing FCIP over native Fibre Channel extension is its ability to overcome distance constraints.
Native Fibre Channel is governed by a flow-control mechanism called Buffer-to-Buffer (BB) Credits. In a native FC link, a frame cannot be sent until the sender has a "credit" from the receiver. As the distance between sites increases, the time it takes for an acknowledgment (and thus the return of a credit) to travel back significantly increases. This creates a "protocol drop-off" where performance collapses once the distance exceeds the available buffer memory. In contrast, FCIP encapsulates FC frames into TCP/IP segments. TCP/IP uses a different flow- control mechanism called windowing.
By moving the transport to TCP/IP, the storage traffic is no longer strictly bound by the physical light-propagation constraints of the FC buffer-credit mechanism. While latency still increases with distance (governed by the speed of light in fiber), FCIP provides no fixed protocol distance limitation, making it possible to replicate data across continents or globally (asynchronous replication) as long as the IP network provides a path.
質問 # 38
During a storage assessment, the architect discovers workload peaks only occur during quarter- end reporting. The customer wants cost optimization without overprovisioning. Which HPE consumption model fits best?
正解:C
解説:
HPE GreenLake flexible capacity allows customers to pay for baseline resources while scaling temporarily for peak demand. This avoids overbuying infrastructure and aligns spending with usage. Traditional CapEx often results in unused capacity and reduced financial efficiency.
質問 # 39
Which two configurations will result in an outage with an HPE GreenLake for File Storage solution, where a Quorum Witness has been configured and is operational? (Choose two.)
正解:B、C
解説:
The HPE GreenLake for File Storage (based on the Alletra MP X10000 and VAST Data architecture) utilizes a Disaggregated Shared-Everything (DASE) architecture where CNodes (Compute Nodes) manage the file system logic and metadata. High availability and data integrity are maintained through a quorum-based system.
In a standard cluster environment, a strict majority of nodes ($n/2 + 1$) must be operational to maintain the "Quorum," which is the state required to acknowledge I/O and prevent "split-brain" scenarios. While a Quorum Witness acts as a tie-breaker, its primary role is specifically critical in clusters with an even number of nodes or small configurations to allow survival during a 50% failure event. According to the HPE Advanced Storage architectural guidelines, configurations that hit or exceed the 50% failure threshold can trigger an outage if the quorum votes cannot be satisfied:
Option E (Six CNodes with three failed): In a 6-node cluster, a majority is 4. With exactly 3 nodes failed (50%), the system reaches a "tie" state. Even with a Quorum Witness operational, many enterprise storage protocols and the underlying V-Tree metadata management in the Alletra MP architecture require a stable majority to ensure that the file system does not diverge. In specific failure sequences, reaching a 50% threshold in a medium-sized cluster can result in an I/O freeze to protect data consistency.
Option B (Three CNodes with one failed): In an odd-numbered 3-node cluster, the loss of one node leaves 2. While 2/3 is a majority, the system is now "at-risk." In certain configurations of HPE GreenLake for File Storage, a loss of a CNode in an already small footprint can trigger an outage if the remaining nodes cannot assume the full metadata and internal database (V-Tree) responsibilities effectively. Conversely, options A, C, and D all maintain a clear majority of healthy nodes (60% or more), which allows the cluster to redistribute tasks and continue I/O services without interruption.
質問 # 40
A customer is concerned about the long distances between their data centers and significant latencies that might exist between the SAN fabrics at the two data centers. Since SCSI write operations can involve multiple handshake messages between the target and initiator, which Brocade feature should be used to double the recommended distance, but maintain the same latency as a shorter haul link?
正解:C
解説:
Standard SCSI write operations are inherently sensitive to distance because they require multiple round-trip handshakes before data is actually transmitted. A typical write involves: 1) the Command, 2) a Transfer Ready (XFER_RDY) response from the target, 3) the Data, and 4) the Status. In a long- distance SAN, each of these round trips adds significant "latency wait time," severely degrading performance as distance increases.
To solve this, Brocade (HPE B-series) utilizes a protocol optimization feature known as FastWrite.
FastWrite works by creating a Proxy Target (PT) local to the initiator host and a Proxy Initiator (PI) local to the target storage device. When the host issues a SCSI write command, the local Brocade switch (acting as the Proxy Target) immediately sends the XFER_RDY back to the host without waiting for the signal to travel across the long-distance link. This allows the host to send the data segment immediately. By eliminating the need for every handshake message to traverse the distance multiple times, FastWrite significantly reduces the aggregate latency felt by the application. Architecturally, this enables customers to extend their SAN fabrics over double the distance (and often much further) while maintaining performance comparable to a significantly shorter link. This is critical for asynchronous replication and remote copy applications that issue large I/O blocks.
質問 # 41
......
人の職業の発展は彼の能力によって進めます。権威的な国際的な証明書は能力に一番よい証明です。HPのHPE7-J01試験の認証はあなたの需要する証明です。この試験に合格したいなら、よく準備する必要があります。Xhs1991の提供するHPのHPE7-J01試験の資料は経験の豊富なチームに整理されています。現在あなたもこのような珍しい資料を得られます。我々のウェブサイトであなたはHPのHPE7-J01試験のソフトを購入できます。
HPE7-J01復習時間: https://www.xhs1991.com/HPE7-J01.html
P.S.Xhs1991がGoogle Driveで共有している無料の2026 HP HPE7-J01ダンプ:https://drive.google.com/open?id=1NDFGoIEeYneAmEWEADIzpopgZF5ZwttG