We have the DP-750 bootcamp , it aims at helping you increase the pass rate , the pass rate of our company is 98%, we can ensure that you can pass the exam by using the DP-750 bootcamp. We have knowledge point as well as the answers to help you finish the traiing materials, if you like, it also has the offline version, so that you can continue the study at anytime
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
>> DP-750 Valid Test Review <<
Besides this PDF format, Microsoft DP-750 practice exams in desktop and web-based versions are available to aid you in recognizing both your weaker and stronger concepts. These real Microsoft DP-750 Exam Simulator exams also points out your mistakes regarding the Microsoft DP-750 exam preparation.
NEW QUESTION # 46
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.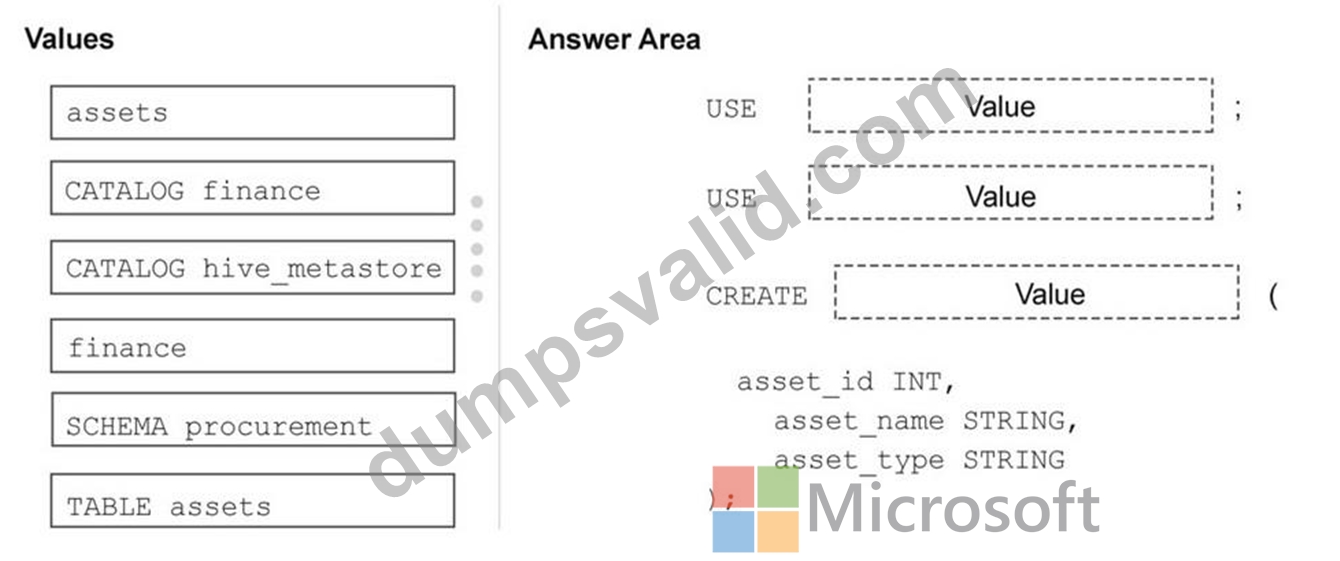
Answer:
Explanation: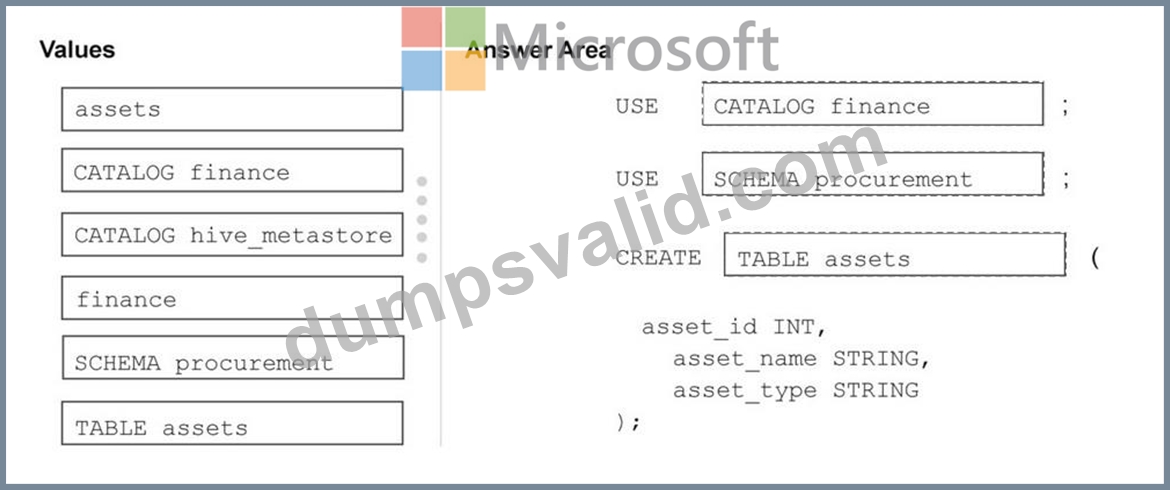
NEW QUESTION # 47
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 48
You have an Azure Databricks workspace named Workspace1 that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1. Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, the merge fails due to conflicts.
You need to merge Branch1 into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: B
Explanation:
To resolve the merge conflict and keep all changes from both branches, you must pull the updated main branch into your feature branch, resolve the conflicts manually within Databricks or a local Git tool, and then merge.
Reference:
https://devactivity.com/insights/streamlining-your-git-workflow-resolving-branch-behind-main- issues-in-your-git-repo/
NEW QUESTION # 49
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: C
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 50
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A Databricks Access Connector is an Azure resource that provides a managed identity for Databricks to authenticate to Azure Storage services. It is an authentication bridge - nothing more. Creating one doesn't register any external database, doesn't create any Unity Catalog objects representing DB1, and doesn't enable querying of SQL Server data from Databricks.
An Access Connector is a prerequisite for setting up storage credentials and external locations in Unity Catalog (to access ADLS Gen2, for example), but it has no role in Lakehouse Federation or foreign catalog creation. It cannot expose an external database's schemas and tables in Unity Catalog alongside native objects.
The correct solution for this scenario is a foreign catalog (Q47), which requires a connection object pointing to DB1 - not an Access Connector.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 51
......
The result of your exam is directly related with the DP-750 learning materials you choose. So our company is of particular concern to your exam review. Getting the certificate of the exam is just a start. Our DP-750 practice engine may bring far-reaching influence for you. Any demands about this kind of exam of you can be satisfied by our DP-750 training quiz. So our DP-750 exam questions are of positive interest to your future.
Useful DP-750 Dumps: https://www.dumpsvalid.com/DP-750-still-valid-exam.html