Microsoft DP-750시험은 PassTIP 에서 출시한Microsoft DP-750덤프로 도전하시면 됩니다. Microsoft DP-750 덤프를 페펙트하게 공부하시면 시험을 한번에 패스할수 있습니다. 구매후 일년무료 업데이트 서비스를 제공해드리기에Microsoft DP-750시험문제가 변경되어도 업데이트된 덤프를 받으면 가장 최신시험에 대비할수 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> Microsoft DP-750최신 업데이트버전 인증시험자료 <<
우리PassTIP에는 아주 엘리트 한 전문가들로 구성된 팀입니다 그들은 끈임 없는 연구와 자기자신만의 지식으로 많은 IT관연 덤프자료를 만들어 냄으로 여러분의 꿈을 이루어드립니다, 기존의 시험문제와 답과 시험문제분석 등입니다. PassTIP에서 제공하는Microsoft DP-750시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다. PassTIP덤프들은 모두 보장하는 덤프들이며 여러분은 과감히 PassTIP의 덤프를 장바구니에 넣으세요. PassTIP에서 여러분의 꿈을 이루어 드립니다.
질문 # 39
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.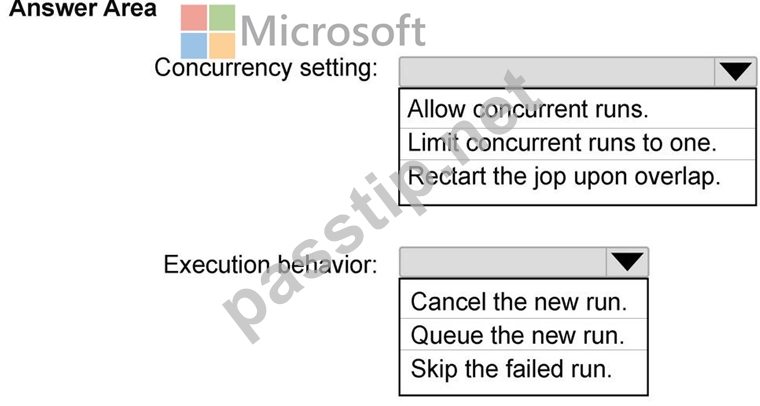
정답:
설명: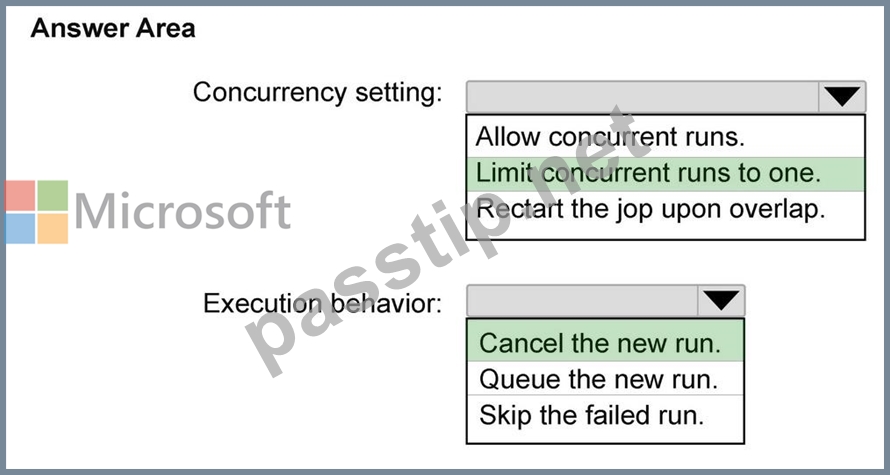
질문 # 40
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.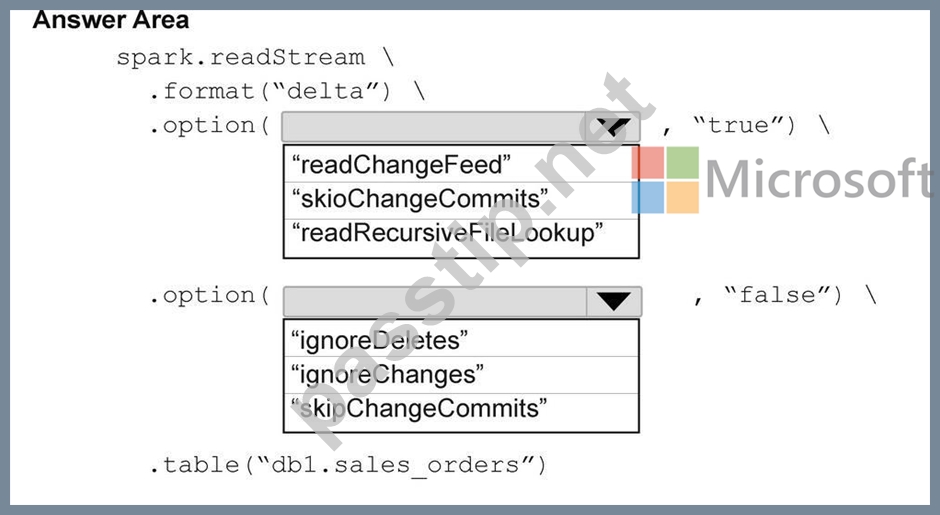
정답:
설명: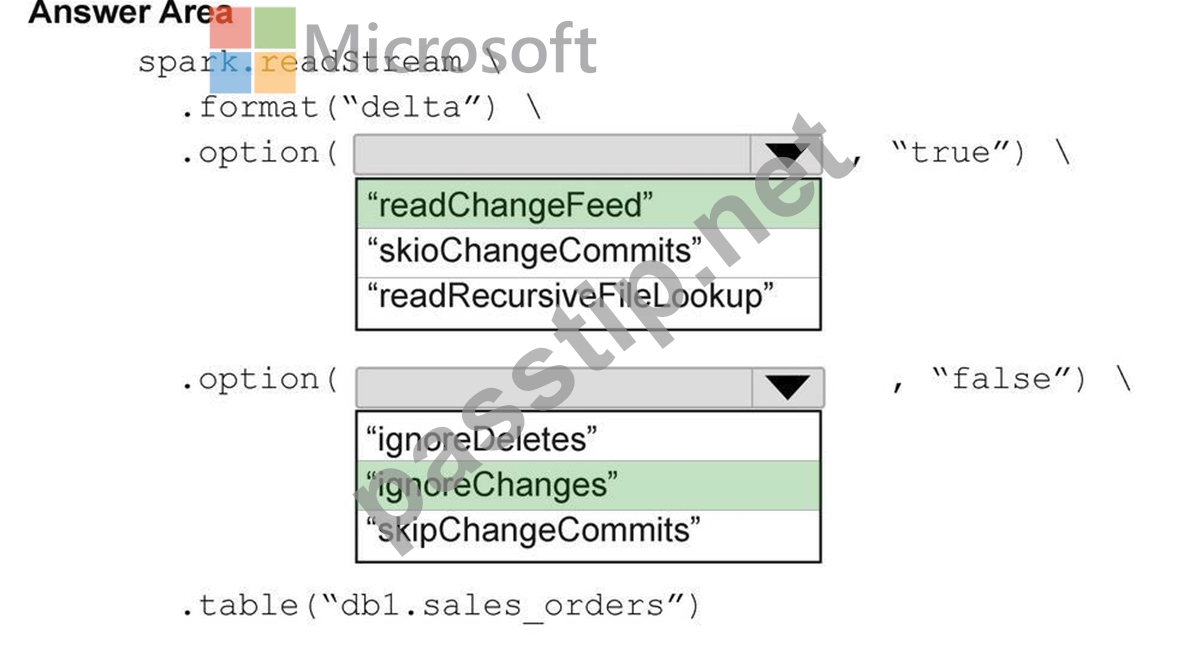
질문 # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
정답:D
설명:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
질문 # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements
* Transaction logs and deleted data files that are older than 90 days must be removed from Delta tables to reclaim storage.
* All the tables must remain available for querying during the cleanup process.
* Administrative effort must be minimized
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.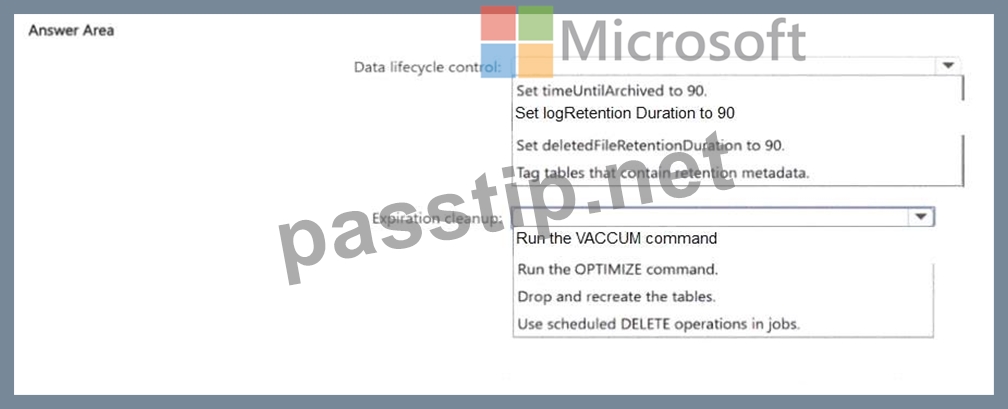
정답:
설명: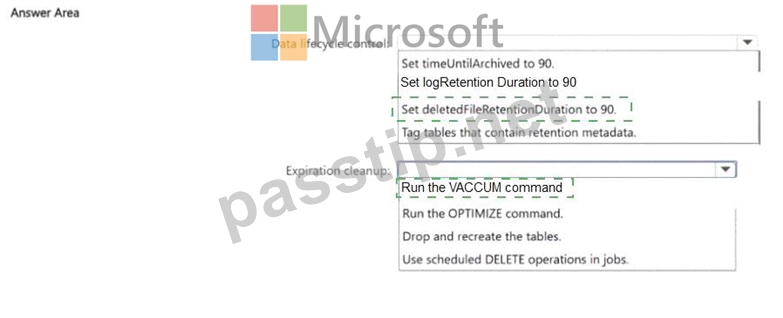
Explanation:
Two actions are needed to reclaim storage while keeping tables queryable:
Set delta.deletedFileRetentionDuration and delta.logRetentionDuration to 90 days on each table. These properties define the retention floor - VACUUM will not touch anything newer than this threshold, so no data needed for time travel within 90 days can be accidentally removed.
Run VACUUM on each table. VACUUM is the Delta Lake command that physically removes data files and transaction log entries older than the retention duration. Importantly, VACUUM runs as a background operation - it uses Delta Lake's MVCC (multi-version concurrency control) to ensure that concurrent reads against the table continue uninterrupted while cleanup happens. Tables are fully available throughout.
OPTIMIZE compacts small files for query performance but doesn't delete anything. Manually deleting files outside the Delta protocol would corrupt the table.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
질문 # 43
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
정답:D
설명:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
질문 # 44
......
제일 빠른 시일내에 제일 간단한 방법으로Microsoft인증 DP-750시험을 패스하는 방법이 없냐구요? PassTIP의Microsoft인증 DP-750덤프를 공부하시면 가능합니다. PassTIP의Microsoft인증 DP-750덤프는 많은 분들이 검증한 가장 유력한Microsoft인증 DP-750시험공부자료입니다. 덤프의 문제만 기억하시면 패스는 문제없기에 제일 빠른 시일내에 시험을 패스하여 자격증 취득이 가능합니다.
DP-750시험대비 공부문제: https://www.passtip.net/DP-750-pass-exam.html