Do you often feel that your ability does not match your ambition?Are you dissatisfied with the ordinary and boring position? If your answer is yes, you can try to get the Databricks-Certified-Professional-Data-Engineer certification that you will find there are so many chances wait for you. You can get a better job; you can get more salary. But if you are trouble with the difficult of Databricks-Certified-Professional-Data-Engineer Exam, you can consider choose Databricks-Certified-Professional-Data-Engineer guide question to improve your knowledge to pass Databricks-Certified-Professional-Data-Engineer exam, which is your testimony of competence. We believe our latest Databricks-Certified-Professional-Data-Engineer exam torrent will be the best choice for you.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Pipeline observability and logging - Performance and health monitoring |
| Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
| Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
>> Databricks-Certified-Professional-Data-Engineer New Test Bootcamp <<
It is apparent that a majority of people who are preparing for the Databricks-Certified-Professional-Data-Engineer exam would unavoidably feel nervous as the exam approaching, If you are still worried about the coming exam, since you have clicked into this website, you can just take it easy now, I can assure you that our company will present the antidote for you--our Databricks-Certified-Professional-Data-Engineer Learning Materials. Our company has spent more than 10 years on compiling study materials for the exam in this field, and now we are delighted to be here to share our study materials with all of the candidates for the exam in this field.
NEW QUESTION # 120
The data engineering team maintains the following code: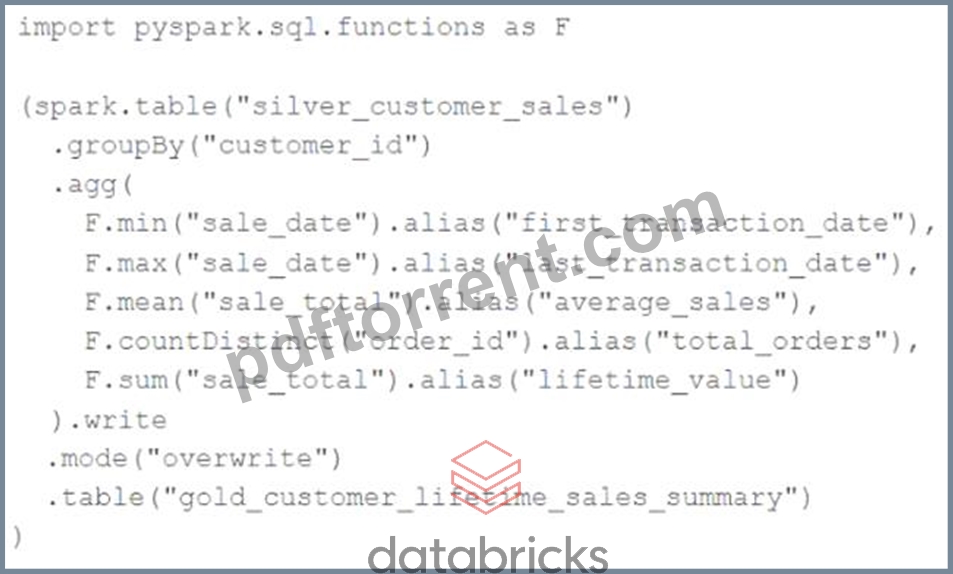
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: B
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 121
You are currently working on reloading customer_sales tables using the below query
1. INSERT OVERWRITE customer_sales
2. SELECT * FROM customers c
3. INNER JOIN sales_monthly s on s.customer_id = c.customer_id
After you ran the above command, the Marketing team quickly wanted to review the old data that was in the table. How does INSERT OVERWRITE impact the data in the customer_sales table if you want to see the previous version of the data prior to running the above statement?
Answer: D
Explanation:
Explanation
The answer is, INSERT OVERWRITE Overwrites the current version of the data but preserves all historical versions of the data, you can time travel to previous versions.
1.INSERT OVERWRITE customer_sales
2.SELECT * FROM customers c
3.INNER JOIN sales s on s.customer_id = c.customer_id
Let's just assume that this is the second time you are running the above statement, you can still query the prior version of the data using time travel, and any DML/DDL except DROP TABLE creates new PARQUET files so you can still access the previous versions of data.
SQL Syntax for Time travel
SELECT * FROM table_name as of [version number]
with customer_sales example
SELECT * FROM customer_sales as of 1 -- previous version
SELECT * FROM customer_sales as of 2 -- current version
You see all historical changes on the table using DESCRIBE HISTORY table_name Note: the main difference between INSERT OVERWRITE and CREATE OR REPLACE TABLE(CRAS) is that CRAS can modify the schema of the table, i.e it can add new columns or change data types of existing columns. By default INSERT OVERWRITE only overwrites the data.
INSERT OVERWRITE can also be used to update the schema when
spark.databricks.delta.schema.autoMerge.enabled is set true if this option is not enabled and if there is a schema mismatch command INSERT OVERWRITEwill fail.
Any DML/DDL operation(except DROP TABLE) on the Delta table preserves the historical ver-sion of the data.
NEW QUESTION # 122
The data engineering team maintains the following code:
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 123
A junior data engineer on your team has implemented the following code block.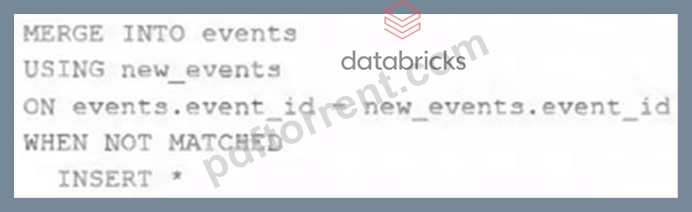
The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.
When this query is executed, what will happen with new records that have the same event_id as an existing record?
Answer: C
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
"If none of the WHEN MATCHED conditions evaluate to true for a source and target row pair that matches the merge_condition, then the target row is left unchanged." https://docs.databricks.com/en/sql/language-manual/delta-merge-into.html#:~:text=If%20none%20of%20the%20WHEN%20MATCHED%20conditions%20evaluate%20to%20true%20for%20a%20source%20and%20target%20row%20pair%20that%20matches%20the%20merge_condition%2C%20then%20the%20target%20row%20is%20left%20unchanged.
NEW QUESTION # 124
An external object storage container has been mounted to the location/mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team: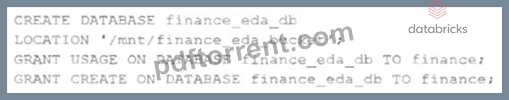
After the database was successfully created and permissions configured, a member of the finance team runs the following code: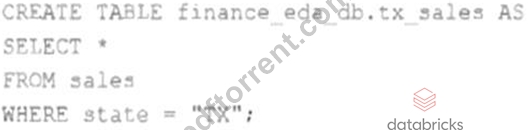
If all users on the finance team are members of thefinancegroup, which statement describes how thetx_sales table will be created?
Answer: B
Explanation:
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 125
......
Don't need a lot of time and money, only 30 hours of special training, and you can easily pass your first time to attend Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam. PDFTorrent are able to provide you with test exercises which are closely similar with real exam questions.
Real Databricks-Certified-Professional-Data-Engineer Braindumps: https://www.pdftorrent.com/Databricks-Certified-Professional-Data-Engineer-exam-prep-dumps.html