2026 Latest Real4Prep DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1MI65wUKObYtQBfq-OenOXJz8LAGZh-xm
When your life is filled with enriching yourself, you will feel satisfied with your good change. Our DP-100 exam questions are designed to stimulate your interest in learning so that you learn in happiness. And our DP-100 praparation materials are applied with the latest technologies so that you can learn with the IPAD, phone, laptop and so on. Try to believe in yourself. You also can become social elite under the guidance of our DP-100 Study Guide.
Officially, there is no prior work-experience or educational expertise related to DP-100 Exam. Anyone, willing to make it big in the world of data science, can go for it. However, industry pundits say that beginner-level expertise in concepts like running data experiments and machine learning will make the exam journey a lot more simplified and easy to accomplish.
The reality is often cruel. What do we take to compete with other people? More useful certifications like DP-100 certificate? In this era of surging talent, why should we stand out among the tens of thousands of graduates and be hired by the company? Only if you pass the exam can you get a better promotion. And if you want to pass it more efficiently, we must be the best partner for you. Because we are professional DP-100 question torrent provider, we are worth trusting; because we make great efforts, we do better. Here are many reasons to choose us.
Microsoft DP-100: Designing and Implementing a Data Science Solution on Azure is a certification exam designed for data professionals who want to demonstrate their skills in designing and implementing data science solutions on Azure. It is intended for individuals who work with data engineers, data scientists, and other stakeholders in the organization to create and deploy end-to-end data science solutions.
The Microsoft DP-100 Exam consists of various topics, including data exploration and preparation, modeling, deployment, and monitoring. The candidates need to have hands-on experience in these topics to pass the exam successfully. DP-100 exam also covers the use of Azure Machine Learning, Azure Databricks, and other Azure services that are used for implementing data science solutions.
NEW QUESTION # 26
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.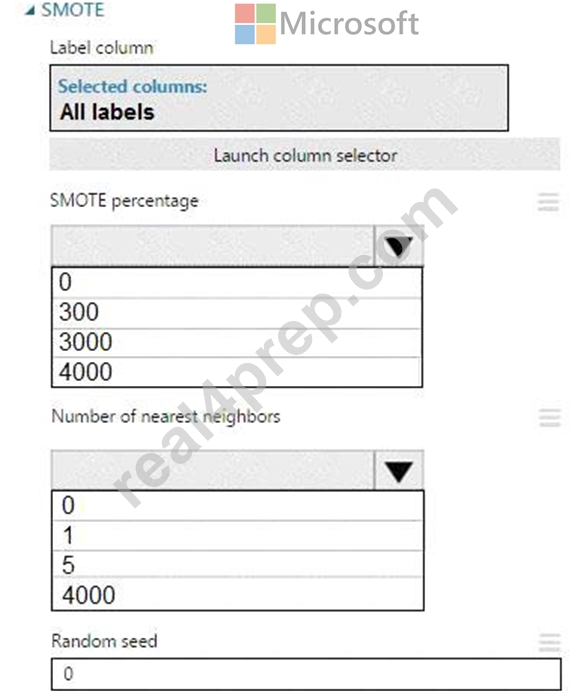
Answer:
Explanation: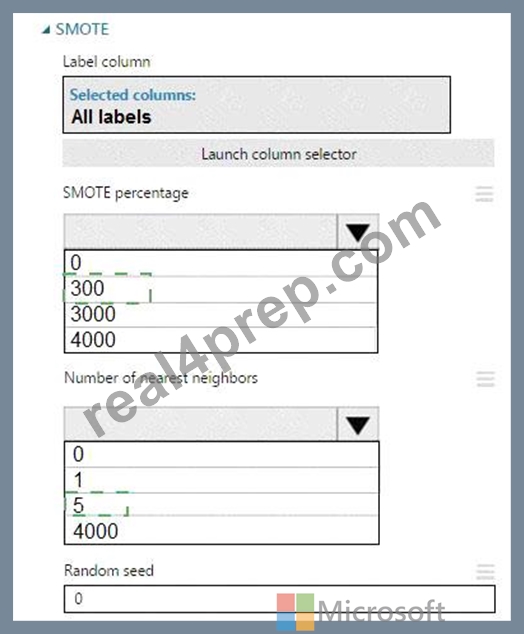
Explanation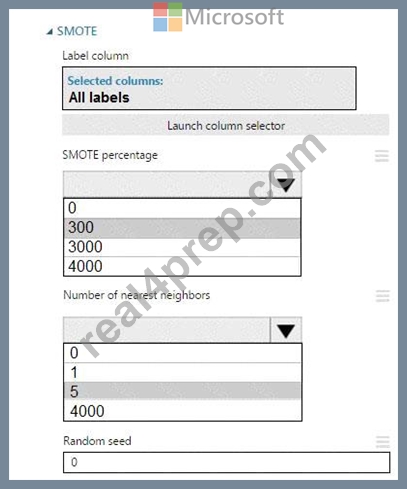
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 27
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code: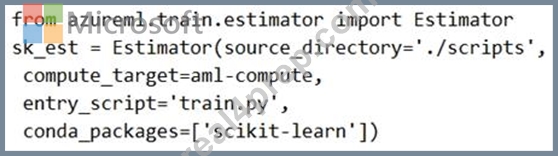
Does the solution meet the goal?
Answer: B
Explanation:
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 28
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: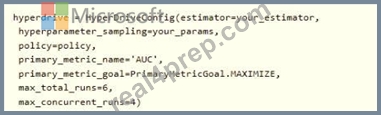
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
Solution: Run the following code: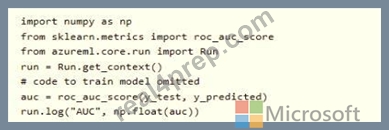
Does the solution meet the goal?
Answer: B
NEW QUESTION # 29
You are developing a linear regression model in Azure Machine Learning Studio. You run an experiment to compare different algorithms.
The following image displays the results dataset output: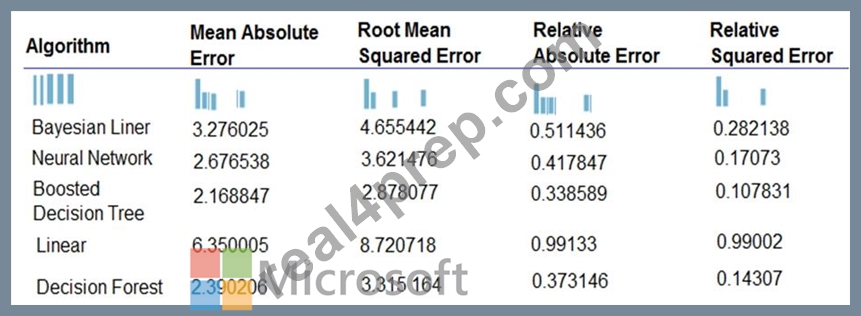
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the image.
NOTE: Each correct selection is worth one point.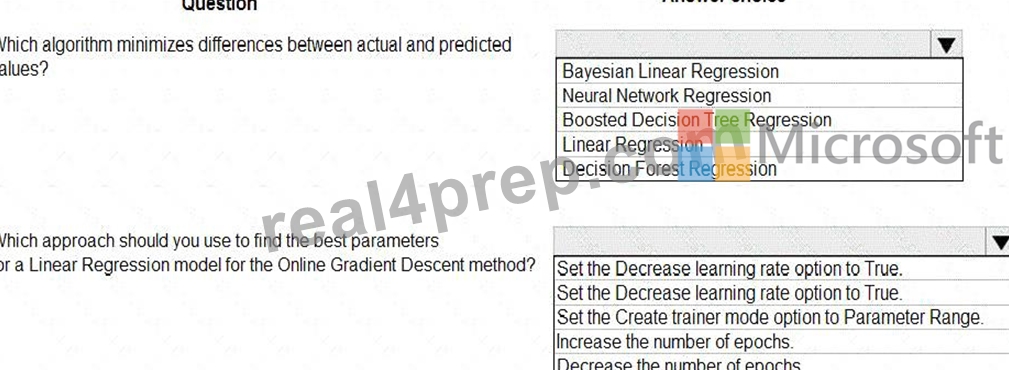
Answer:
Explanation: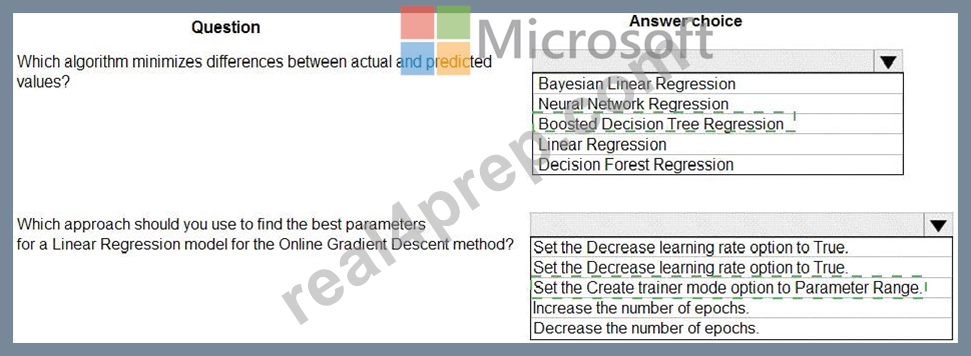
Explanation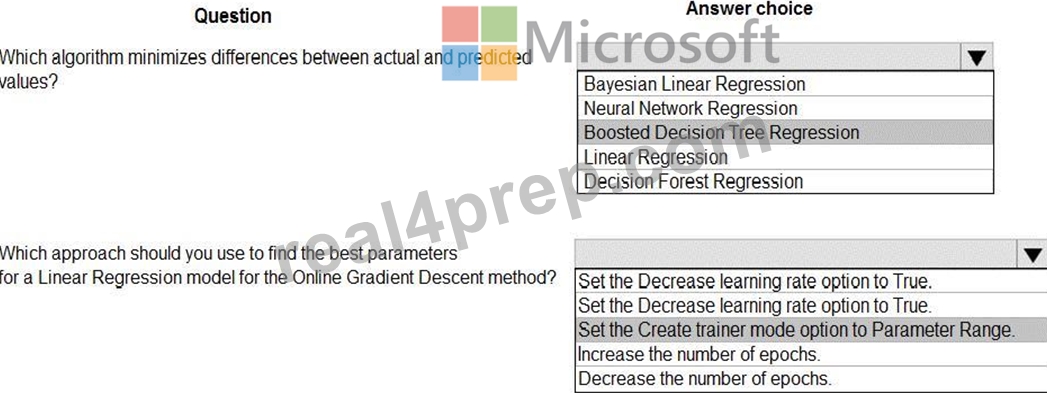
Box 1: Boosted Decision Tree Regression
Mean absolute error (MAE) measures how close the predictions are to the actual outcomes; thus, a lower score is better.
Box 2:
Online Gradient Descent: If you want the algorithm to find the best parameters for you, set Create trainer mode option to Parameter Range. You can then specify multiple values for the algorithm to try.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regression
NEW QUESTION # 30
You plan to use automated machine learning to train a regression model. You have data that has features which have missing values, and categorical features with few distinct values.
You need to configure automated machine learning to automatically impute missing values and encode categorical features as part of the training task.
Which parameter and value pair should you use in the AutoMLConfig class?
Answer: A
Explanation:
Featurization str or FeaturizationConfig
Values: 'auto' / 'off' / FeaturizationConfig
Indicator for whether featurization step should be done automatically or not, or whether customized featurization should be used.
Column type is automatically detected. Based on the detected column type preprocessing/featurization is done as follows:
Categorical: Target encoding, one hot encoding, drop high cardinality categories, impute missing values.
Numeric: Impute missing values, cluster distance, weight of evidence.
DateTime: Several features such as day, seconds, minutes, hours etc.
Text: Bag of words, pre-trained Word embedding, text target encoding.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-automl-client/azureml.train.automl.automlconfig.automlconfig
NEW QUESTION # 31
......
DP-100 Reliable Exam Syllabus: https://www.real4prep.com/DP-100-exam.html
DOWNLOAD the newest Real4Prep DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MI65wUKObYtQBfq-OenOXJz8LAGZh-xm