Implementing Data Engineering Solutions Using Azure Databricks DP-750 You can use Real Questions to guide your search for a Microsoft. DP-750 You can get ready for the Implementing Data Engineering Solutions Using Azure Databricks DP-750 test with the aid of Exam Dumps. the exam code Consider the inquiries. The Implementing Data Engineering Solutions Using Azure Databricks DP-750 practise test software is valid for Implementing Data Engineering Solutions Using Azure Databricks DP-750. the exam code Exam simulation practise tests, Implementing Data Engineering Solutions Using Azure Databricks DP-750 the exam code Final Implementing Data Engineering Solutions Using Azure Databricks DP-750 Dumps for Exam success requires familiarity with the most recent question types and effective time management.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
>> Practice DP-750 Exams Free <<
For the peace of your mind, you can also try a free demo of Microsoft DP-750 Dumps practice material. You will not find such affordable and latest material for Microsoft certification exam anywhere else. Don't miss these incredible offers. Order real Microsoft DP-750 Exam Questions today and start preparation for the certification exam.
NEW QUESTION # 65
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.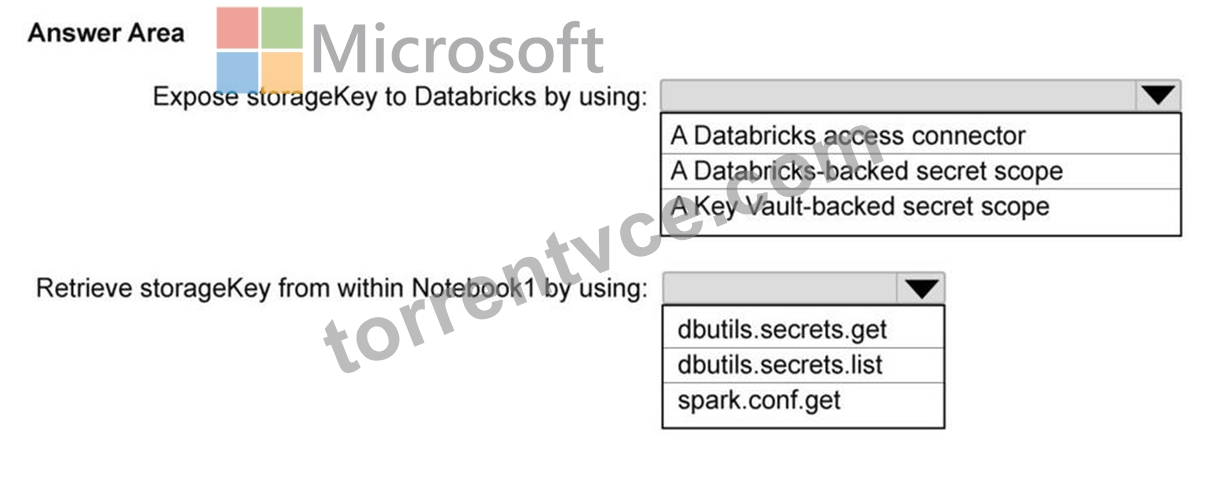
Answer:
Explanation: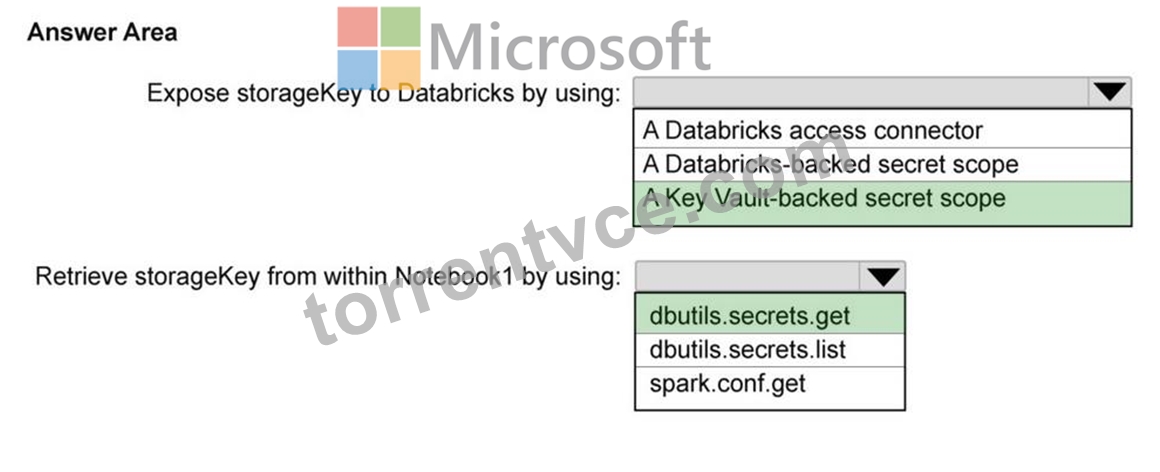
NEW QUESTION # 66
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.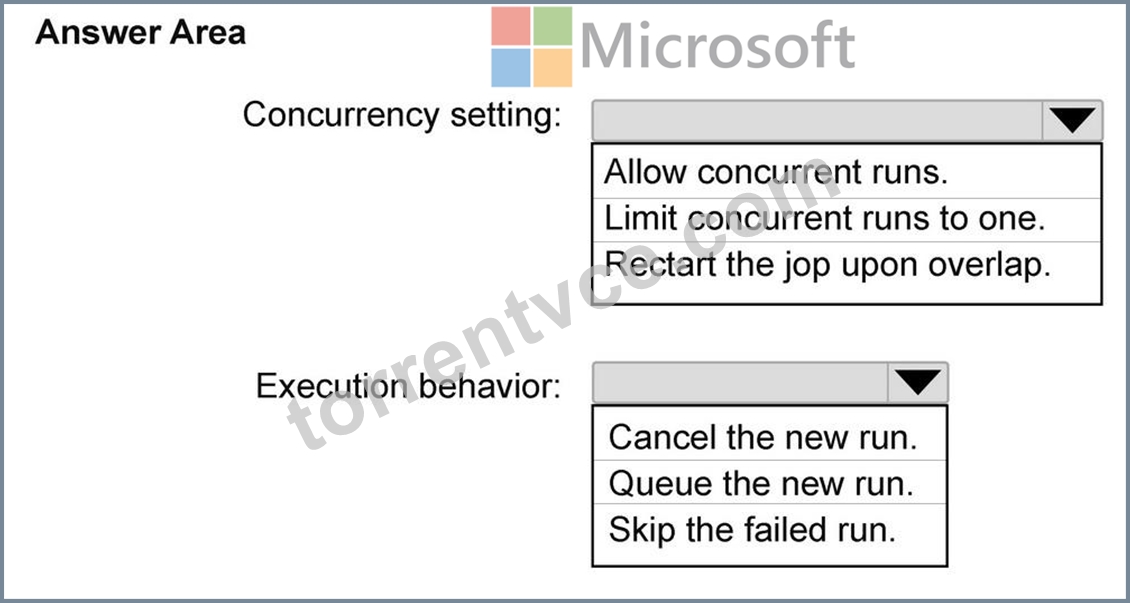
Answer:
Explanation: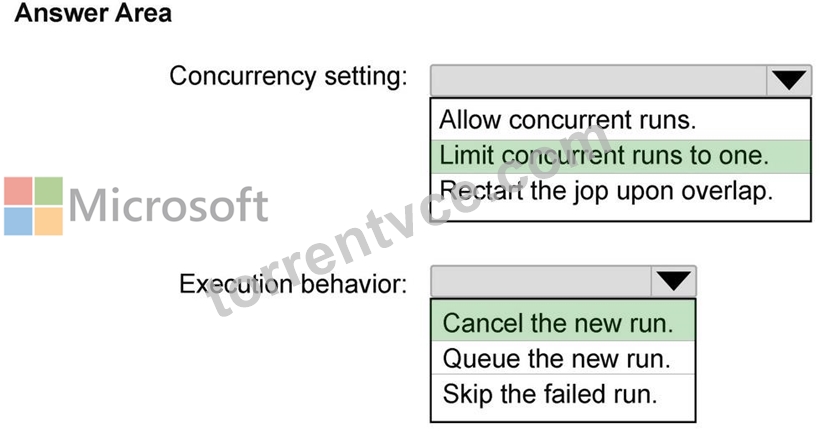
NEW QUESTION # 67
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark ' s filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn ' t rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=[ ' order_amount ' ]) produce identical results. The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 68
Which layer contains cleaned and conformed data in Databricks Lakehouse architecture?
Answer: C
Explanation:
Silver layer contains cleaned, validated, and enriched data ready for analytics. Bronze stores raw ingested data. Gold contains aggregated business-level data. Raw is not part of formal medallion architecture naming.
NEW QUESTION # 69
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark's filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn't rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=['order_amount']) produce identical results.
The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 70
......
For consolidation of your learning, our PDF,Software and APP online versions of the DP-750 exam questions also provide you with different sets of practice questions and answers. Doing all these sets of the DP-750 study materials again and again, you enrich your knowledge and maximize chances of an outstanding exam success. And the content of the three version is the same, but the displays are totally differnt. If you want to know them before the payment, you can free download the demos of our DP-750 leaning braindumps.
DP-750 Reliable Test Pdf: https://www.torrentvce.com/DP-750-valid-vce-collection.html