P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Pass4Leader: https://drive.google.com/open?id=1fIzU_cgZgaSFq8Ky1zZSbRVjvdhLH1EY
Pass4Leader offers the best self-assessment software for the Professional-Machine-Learning-Engineer exam. This desktop-based practice exam provides valid and up-to-date Professional-Machine-Learning-Engineer practice test questions. You can customize the software by adjusting the time and number of Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) questions to your preferences. Additionally, you can try a free demo of the Professional-Machine-Learning-Engineer Practice Test. This software keeps track of all your Professional-Machine-Learning-Engineer practice exam attempts, allowing you to monitor your progress and improve your Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam preparation.
The Google Professional Machine Learning Engineer certification exam has no formal prerequisites. However, it is pretty hard to pass this test without having solid practical background. The candidates are recommended to have at least three years of industry experience, involving about one year of experience in designing and managing solutions with the help of Google Cloud. The target individuals can take advantage of Google Cloud Free Tier to use the selected products free of charge and gain the real-world expertise.
>> Passing Google Professional-Machine-Learning-Engineer Score Feedback <<
Do you worry about not having a long-term fixed study time? Do you worry about not having a reasonable plan for yourself? Professional-Machine-Learning-Engineer exam dumps will solve this problem for you. Based on your situation, including the available time, your current level of knowledge, our study materials will develop appropriate plans and learning materials. Whatever you want to choose, you want to learn from which stage. In our study materials, you can find the right one for you. At the same time, the Professional-Machine-Learning-Engineer Exam Prep is constantly updated. After you have finished learning a part, you can choose a new method according to your own situation. Our study materials are so easy to understand that no matter who you are, you can find what you want here.
Google Professional Machine Learning Engineer Certification Exam consists of multiple-choice questions and performance-based scenarios that test your ability to design and implement machine learning models on the Google Cloud Platform. Professional-Machine-Learning-Engineer Exam covers a wide range of topics, including data preparation, model training and evaluation, and deployment of machine learning models in a production environment.
NEW QUESTION # 224
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: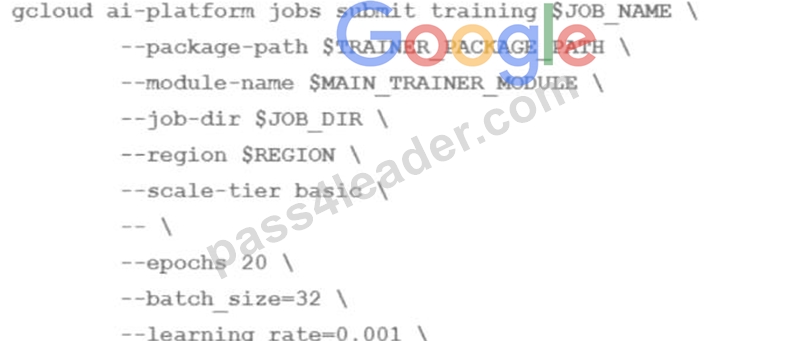
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
Answer: B
Explanation:
The training time of a machine learning model depends on several factors, such as the complexity of the model, the size of the data, the hardware resources, and the hyperparameters. To minimize the training time without significantly compromising the accuracy of the model, one should optimize these factors as much as possible.
One of the factors that can have a significant impact on the training time is the scale-tier parameter, which specifies the type and number of machines to use for the training job on AI Platform. The scale-tier parameter can be one of the predefined values, such as BASIC, STANDARD_1, PREMIUM_1, or BASIC_GPU, or a custom value that allows you to configure the machine type, the number of workers, and the number of parameter servers1 To speed up the training of an LSTM-based model on AI Platform, one should modify the scale-tier parameter to use a higher tier or a custom configuration that provides more computational resources, such as more CPUs, GPUs, or TPUs. This can reduce the training time by increasing the parallelism and throughput of the model training. However, one should also consider the trade-off between the training time and the cost, as higher tiers or custom configurations may incur higher charges2 The other options are not as effective or may have adverse effects on the model accuracy. Modifying the epochs parameter, which specifies the number of times the model sees the entire dataset, may reduce the training time, but also affect the model's convergence and performance. Modifying the batch size parameter, which specifies the number of examples per batch, may affect the model's stability and generalization ability, as well as the memory usage and the gradient update frequency. Modifying the learning rate parameter, which specifies the step size of the gradient descent optimization, may affect the model's convergence and performance, as well as the risk of overshooting or getting stuck in local minima3 References: 1: Using predefined machine types 2: Distributed training 3: Hyperparameter tuning overview
NEW QUESTION # 225
You work for an organization that operates a streaming music service. You have a custom production model that is serving a "next song" recommendation based on a user's recent listening history. Your model is deployed on a Vertex Al endpoint. You recently retrained the same model by using fresh data. The model received positive test results offline. You now want to test the new model in production while minimizing complexity. What should you do?
Answer: B
Explanation:
Traffic splitting is a feature of Vertex AI that allows you to distribute the prediction requests among multiple models or model versions within the same endpoint. You can specify the percentage of traffic that each model or model version receives, and change it at any time. Traffic splitting can help you test the new model in production without creating a new endpoint or a separate service. You can deploy the new model to the existing Vertex AI endpoint, and use traffic splitting to send 5% of production traffic to the new model. You can monitor the end-user metrics, such as listening time, to compare the performance of the new model and the previous model. If the end-user metrics improve between models over time, you can gradually increase the percentage of production traffic sent to the new model. This solution can help you test the new model in production while minimizing complexity and cost. References:
* Traffic splitting | Vertex AI
* Deploying models to endpoints | Vertex AI
NEW QUESTION # 226
You work on the data science team for a multinational beverage company. You need to develop an ML model to predict the company's profitability for a new line of naturally flavored bottled waters in different locations. You are provided with historical data that includes product types, product sales volumes, expenses, and profits for all regions. What should you use as the input and output for your model?
Answer: A
NEW QUESTION # 227
You have developed an application that uses a chain of multiple scikit-learn models to predict the optimal price for your company's products. The workflow logic is shown in the diagram Members of your team use the individual models in other solution workflows. You want to deploy this workflow while ensuring version control for each individual model and the overall workflow Your application needs to be able to scale down to zero. You want to minimize the compute resource utilization and the manual effort required to manage this solution. What should you do?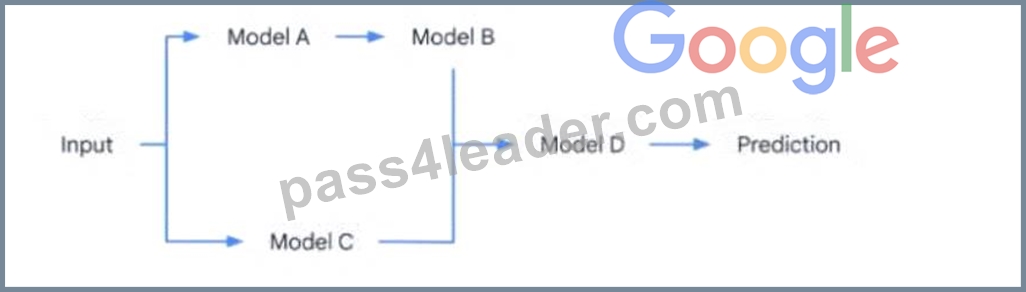
Answer: D
Explanation:
The option C is the most efficient and scalable solution for deploying a machine learning workflow with multiple models while ensuring version control and minimizing compute resource utilization. By exposing each model as an endpoint in Vertex AI Endpoints, it allows for easy versioning and management of individual models. Using Cloud Run to orchestrate the workflow ensures that the application can scale down to zero, thus minimizing resource utilization when not in use. Cloud Run is a service that allows you to run stateless containers on a fully managed environment or on Google Kubernetes Engine. You can use Cloud Run to invoke the endpoints of each model in the workflow and pass the data between them. You can also use Cloud Run to handle the input and output of the workflow and provide an HTTP interface for the application.
References:
* Vertex AI Endpoints documentation
* Cloud Run documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 228
You work for a retail company. You have been asked to develop a model to predict whether a customer will purchase a product on a given day. Your team has processed the company's sales data, and created a table with the following rows:
- Customer_id
- Product_id
- Date
- Days_since_last_purchase (measured in days)
- Average_purchase_frequency (measured in 1/days)
- Purchase (binary class, if customer purchased product on the Date)
You need to interpret your model's results for each individual prediction.
What should you do?
Answer: B
NEW QUESTION # 229
......
Professional-Machine-Learning-Engineer Latest Exam Cost: https://www.pass4leader.com/Google/Professional-Machine-Learning-Engineer-exam.html
BTW, DOWNLOAD part of Pass4Leader Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1fIzU_cgZgaSFq8Ky1zZSbRVjvdhLH1EY