DOWNLOAD the newest ValidDumps MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ZrgjWvQbyaVSWWqjmlyIMUOjJF4Pp-Ae
The content system of MLA-C01 exam simulation is constructed by experts. After-sales service of our study materials is also provided by professionals. If you encounter some problems when using our MLA-C01 study materials, you can also get them at any time. After you choose MLA-C01 Preparation questions, professional services will enable you to use it in the way that suits you best, truly making the best use of it, and bringing you the best learning results.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deployment and Orchestration of ML Workflows | 22% | - Choose deployment infrastructure and pattern
|
| Topic 2: Data Preparation for Machine Learning | 28% | - Ingest and store data
|
| Topic 3: ML Solution Monitoring, Maintenance, and Security | 24% | - Optimize and maintain workloads
|
| Topic 4: ML Model Development | 26% | - Select appropriate modeling approach
|
>> MLA-C01 Exam Dumps Provider <<
In order to cater to meet different needs of our customers, three versions of MLA-C01 exam bootcamp are available. Each version has its own advantages, and you can choose the most suitable one in accordance with your needs. Furthermore, MLA-C01 exam bootcamp is compiled by outstanding experts, therefore the quality and the accuracy can be guaranteed. Besides, we have the professional technicians to examine the website on a regular basis, hence a clean and safe shopping environment will be provided to you. You just need to buy the MLA-C01 Exam Dumps with ease.
NEW QUESTION # 105
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.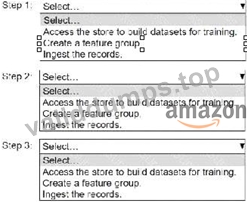
Answer:
Explanation: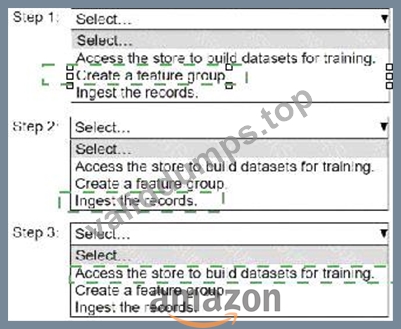
Explanation: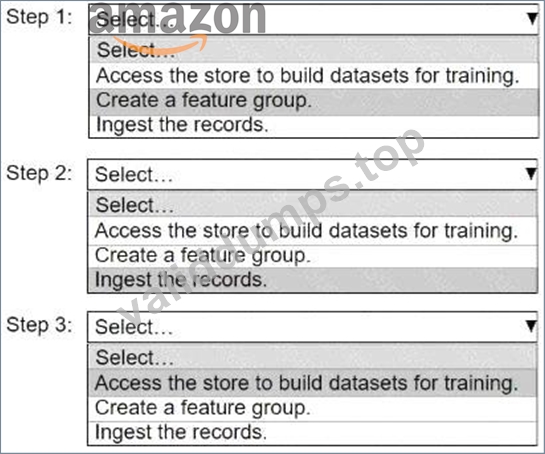
Step 1: Create a feature group.Step 2: Ingest the records.Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why?A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How?Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why?After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How?Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why?Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How?Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 106
A company is creating an ML model to identify defects in a product. The company has gathered a dataset and has stored the dataset in TIFF format in Amazon S3. The dataset contains 200 images in which the most common defects are visible. The dataset also contains 1,800 images in which there is no defect visible.
An ML engineer trains the model and notices poor performance in some classes. The ML engineer identifies a class imbalance problem in the dataset.
What should the ML engineer do to solve this problem?
Answer: B
Explanation:
Class imbalance occurs when one class significantly outnumbers another, causing models to bias predictions toward the majority class. In this case, images without defects (1,800) vastly outnumber images with defects (200). AWS ML best practices recommend oversampling the minority class to improve class representation without discarding valuable data.
Oversampling techniques-such as duplicating minority samples or applying data augmentation-help the model better learn defect-related features. This approach preserves all available data and improves recall and precision for underrepresented defect classes.
Option B is incorrect because undersampling the minority class would further worsen imbalance. Option A unnecessarily reduces dataset size. Option D does not address the imbalance problem.
Thus, oversampling defect images is the correct solution.
NEW QUESTION # 107
An ML engineer needs to use data with Amazon SageMaker Canvas to train an ML model. The data is stored in Amazon S3 and is complex in structure. The ML engineer must use a file format that minimizes processing time for the data.
Which file format will meet these requirements?
Answer: B
NEW QUESTION # 108
A company needs to combine data from multiple sources. The company must use Amazon Redshift Serverless to query an AWS Glue Data Catalog database and underlying data that is stored in an Amazon S3 bucket.
Select and order the correct steps from the following list to meet these requirements. Select each step one time or not at all. (Select and order three.)
* Attach the IAM role to the Redshift cluster.
* Attach the IAM role to the Redshift namespace.
* Create an external database in Amazon Redshift to point to the Data Catalog schema.
* Create an external schema in Amazon Redshift to point to the Data Catalog database.
* Create an IAM role for Amazon Redshift to use to access only the S3 bucket that contains underlying data.
* Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.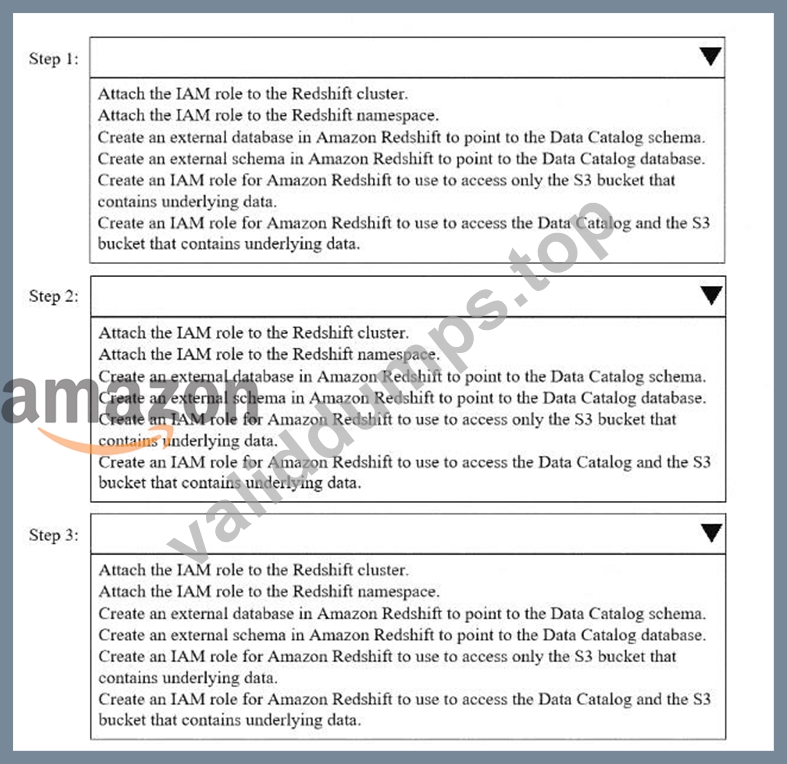
Answer:
Explanation: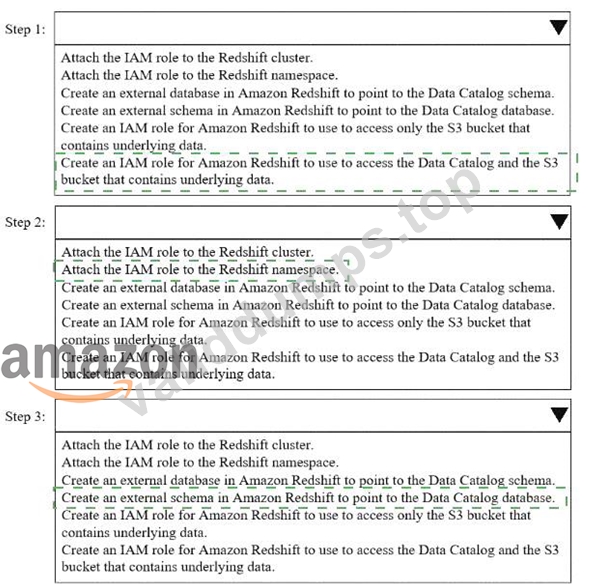
Explanation:
Step 1
Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.
This role must include:
Permissions for AWS Glue Data Catalog (e.g., glue:GetDatabase, glue:GetTables) Permissions for the Amazon S3 bucket that stores the underlying data Step 2 Attach the IAM role to the Redshift namespace.
Redshift Serverless uses a namespace, not a cluster, so the role must be associated with the namespace to allow Redshift to assume it when querying external data.
Step 3
Create an external schema in Amazon Redshift to point to the Data Catalog database.
The external schema maps Redshift to the Glue Data Catalog database so Redshift can query the tables stored in S3.
NEW QUESTION # 109
A company regularly receives new training data from a vendor of an ML model. The vendor delivers cleaned and prepared data to the company's Amazon S3 bucket every 3-4 days.
The company has an Amazon SageMaker AI pipeline to retrain the model. An ML engineer needs to run the pipeline automatically when new data is uploaded to the S3 bucket.
Which solution will meet these requirements with the LEAST operational effort?
Answer: D
Explanation:
AWS best practices recommend event-driven architectures to automate ML workflows with minimal operational overhead. Amazon EventBridge natively integrates with Amazon S3 and Amazon SageMaker Pipelines, making it the most efficient solution for triggering retraining when new data arrives.
Amazon S3 automatically emits object creation events. By creating an EventBridge rule that listens for these events and targets a SageMaker Pipeline execution, the pipeline can start immediately when new training data is uploaded. This solution requires no custom code, no polling, and no infrastructure management.
Option A is incorrect because S3 lifecycle rules manage storage transitions, not workflow execution. Option B introduces custom code and periodic scanning, which increases operational complexity and cost. Option D (MWAA) is powerful but requires maintaining an Airflow environment and is unnecessary for a simple event- based trigger.
AWS documentation explicitly highlights EventBridge + SageMaker Pipelines as the recommended pattern for automated retraining workflows triggered by data arrival.
Therefore, Option C is the correct and AWS-verified answer.
NEW QUESTION # 110
......
Our Amazon MLA-C01 exam questions are designed to provide you with the most realistic MLA-C01 experience possible. Each question is accompanied by an accurate answer, prepared by our team of experts. We also offer free Amazon MLA-C01 Exam Questions updates for 1 year after purchase, as well as a free MLA-C01 practice exam questions demo before purchase.
MLA-C01 Reliable Dumps Ebook: https://www.validdumps.top/MLA-C01-exam-torrent.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by ValidDumps: https://drive.google.com/open?id=1ZrgjWvQbyaVSWWqjmlyIMUOjJF4Pp-Ae