BTW, DOWNLOAD part of EduDump AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=10OtXdk0dk-BDXohTacKMnorO8x5abBDJ
Are you aware of the importance of the AI-300 certification? If your answer is not, you may place yourself at the risk of be eliminated by the labor market. As we know, the AI-300 certification is the main reflection of your ability. If you want to maintain your job or get a better job for making a living for your family, it is urgent for you to try your best to get the AI-300 Certification. We are glad to help you get the certification with our best AI-300 study materials successfully.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 3: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 4: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 5: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
Our AI-300 practice questions are specialized in providing our customers with the most reliable and accurate exam guide and help them pass their exams by achieve their satisfied scores. With our AI-300 study materials, your exam will be a piece of cake. We have a lasting and sustainable cooperation with customers who are willing to purchase our actual exam. We try our best to renovate and update our AI-300 learning guide in order to help you fill the knowledge gap during your learning process, thus increasing your confidence and success rate.
NEW QUESTION # 129
A company ' s platform engineers manage the resource settings and governance of Microsoft Foundry.
Developers must be able to create and update project assets but must not be able to change resource-level configurations.
You need to enforce least privilege access for the engineers and developers.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: C,D
Explanation:
Microsoft ' s Azure AI Foundry documentation defines built-in roles scoped to the resource hierarchy. The Azure AI Administrator role grants permissions to manage the Azure AI Hub resource itself - including network settings, shared connections, quota, and governance configuration - which is appropriate for platform engineers who configure resource-level settings. The Azure AI Developer role grants permissions to create, update, and manage project-level assets such as deployments, prompt flows, fine-tuning jobs, and evaluations, without access to resource-level configuration. This precisely matches the developer requirement and enforces least privilege. Disabling Entra ID authentication (option B) violates security policy and removes the identity-based access control that makes RBAC possible. Sharing a single API key (option D) violates the least-privilege principle - all users would have identical, undifferentiated access with no audit trail.
Microsoft Learn Reference Topic: Manage access to Azure AI Foundry - Built-in roles: Azure AI Administrator and Azure AI Developer
NEW QUESTION # 130
Drag and Drop Question
You develop a flow for a Microsoft Foundry project.
You plan to use outputs generated by running the flow to determine the following information:
- the number of tokens used by each large language model (LLM) node of
the flow
- the accuracy of the model used by the flow
You need to examine the output that provides the required information.
Which output type should you examine? To answer, move the appropriate output types to the correct evaluations. You may use each output type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.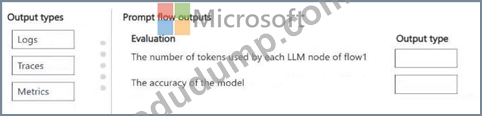
Answer:
Explanation: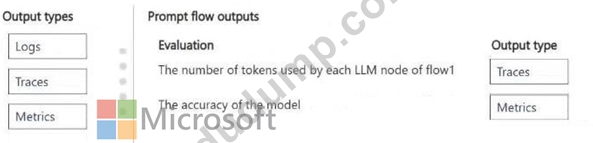
Explanation:
Box 1: Traces
The appropriate output flow type to determine the number of tokens used by each Large Language Model (LLM) node is Traces.
While Metrics provide a macro-level, aggregated overview of total token usage across an entire application or resource, Traces capture detailed, node-by-node execution details.
When a prompt flow runs in Microsoft Foundry, Traces track:
The precise execution path of individual items
Inputs and outputs for each specific LLM node
Detailed telemetry records-such as input_tokens, output_tokens, and total_tokens-bound to that exact step Box 2: Metrics The most appropriate output flow type to determine the accuracy of the model is Metrics.
Metrics are quantitative measurements (such as accuracy, F1-score, precision, recall, or mean squared error) specifically calculated by evaluating model predictions against ground truth data.
Reference:
https://huggingface.co/docs/evaluate/a_quick_tour
NEW QUESTION # 131
You are a data scientist working for a hotel booking website company. You use the Azure Machine Learning service to train a model that identifies fraudulent transactions.
You must deploy the model to an Azure Machine Learning online endpoint by using the Azure Machine Learning Python SDK v2. The deployed model must return real-time predictions of fraud based on transaction data input.
You need to create the script that is specified as the scoring_script parameter for the CodeConfiguration class used to deploy the model.
What should the entry script do?
Answer: B
Explanation:
The entry script (scoring script) for an Azure Machine Learning online endpoint must initialize the model when the container starts and process incoming transaction data to return real-time fraud predictions.
init() function: Runs once when the container is initialized. It must locate and load the trained model into memory (typically using a global variable) from the path specified by the AZUREML_MODEL_DIR environment variable.
run(data) function: Executes every time the endpoint receives a real-time HTTP request. It accepts the raw transaction payload, deserializes it, processes the features, passes them to the loaded model for prediction, and returns a JSON-serializable response.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-deploy-online-endpoints?view=azureml-api-2
NEW QUESTION # 132
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.'s issues, constraints, and technical requirements. What should you implement?
Answer: A
Explanation:
Scenario: Issues and Constraints: Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Managed compute targets with autoscaling are the best choice for Azure Machine Learning training workloads when serverless or managed options are preferred and cost predictability is critical.
Best Implementation: Managed Compute with Autoscaling
This option, specifically using Azure Machine Learning compute clusters (AmlCompute), aligns with all your requirements:
Managed Infrastructure: Azure handles the creation, patching, and lifecycle of the virtual machines, reducing management overhead.
Cost Predictability & Efficiency: Autoscaling allows you to set a minimum of zero nodes. This ensures you only pay for compute while a job is running, preventing costs from idle resources.
Scalability: It can automatically scale up to a multi-node cluster to handle large datasets or distributed training jobs.
Enterprise Governance: Administrators can enforce cost control by setting quotas at the subscription or workspace level.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-serverless-compute
NEW QUESTION # 133
You create an Azure Machine Learning workspace. You use the Azure Machine Learning Python SDK v2 to create a compute cluster.
The compute cluster must run a training script. Costs associated with running the training script must be minimized.
You need to complete the Python script to create the compute cluster.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.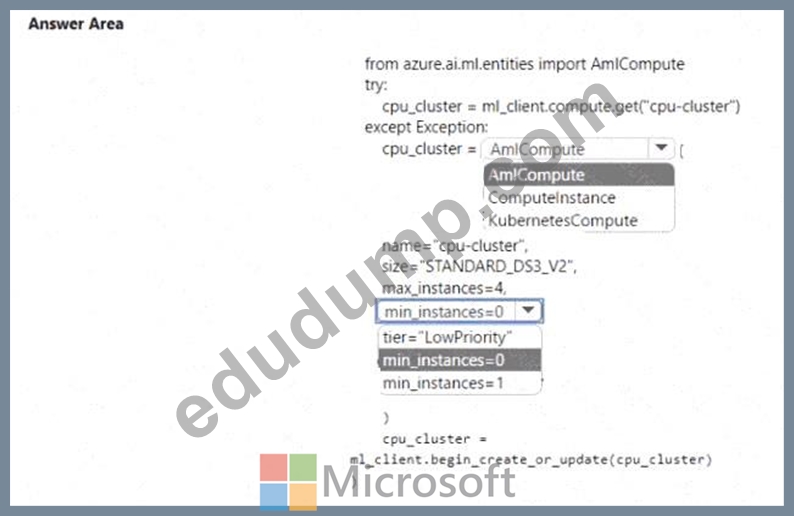
Answer:
Explanation: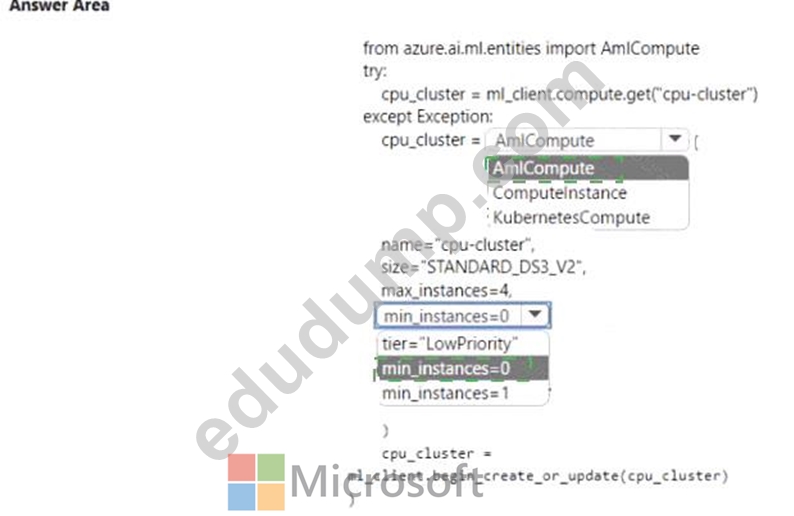
Explanation: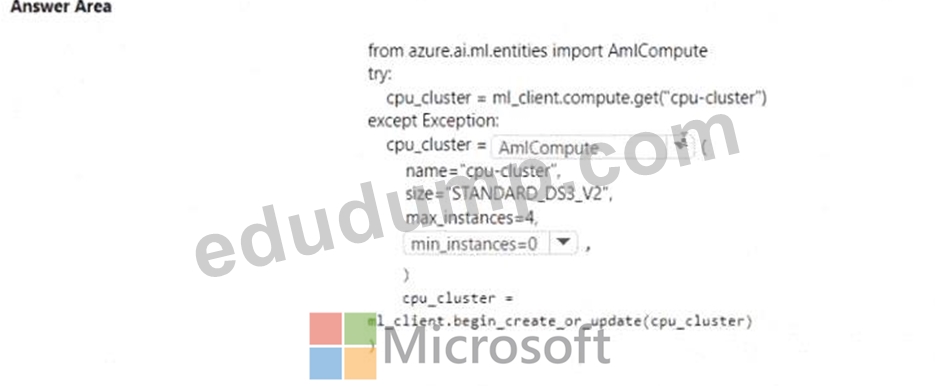
NEW QUESTION # 134
......
The dream of IT in front of the reality is always tiny. But the dream to pass AI-300 certification exam, with the help of EduDump, can be absolutely realized. The service of our EduDump is high-quality, the accuracy of AI-300 Certification Exam training materials is very high, the passing rate of AI-300 exam is as high as 100%. As long as you choose EduDump, we guarantee that you can pass the AI-300 certification exam!
AI-300 Exam Lab Questions: https://www.edudump.com/exams/Microsoft/AI-300/
DOWNLOAD the newest EduDump AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10OtXdk0dk-BDXohTacKMnorO8x5abBDJ