P.S. CertJukenがGoogle Driveで共有している無料かつ新しいMLA-C01ダンプ:https://drive.google.com/open?id=1qF4nhWmxHzL-n5430BWefE1JIvriXcxf
ご存知のように、私たちは今、非常に大きな競争圧力に直面しています。欲しいものを手に入れるにはもっと力が必要です。MLA-C01無料の試験ガイドがこれらを提供するかもしれません。教材を使用すると、AWS Certified Associate認定資格を取得できます。これにより、多くの競合他社の中で、あなたの能力がより明確になります。 MLA-C01練習ファイルを使用することは、ソフトパワーを向上させるための重要なステップです。業界の他の製品と比較して、MLA-C01学習教材が顧客を引き付けるために必要なものを理解するのに少し時間を割いていただければ幸いです。
| Section | Weight | Objectives |
|---|---|---|
| MLOps and Monitoring | 28% | - Incident response and remediation - Model monitoring and drift detection - CI/CD pipelines for ML - Cost optimization for ML workloads - Security and access management for ML - Model lineage and reproducibility |
| Model Development | 30% | - Algorithm selection and model architecture - ML frameworks (SageMaker, built-in algorithms) - Hyperparameter optimization - Training and validation strategies - Transfer learning and fine-tuning - Distributed training |
| Model Deployment and Inference | 20% | - SageMaker endpoints configuration - Model versioning and rollback - Inference optimization (latency, throughput) - Model deployment strategies (real-time, batch) - A/B testing and shadow mode deployment |
| Data Processing | 22% | - Data validation and quality assessment - Data pipelining with AWS services ( Glue, Data Brew, etc.) - Data preprocessing and feature engineering - Handling imbalanced data - Data ingestion and transformation |
MLA-C01 prepトレントは、PDF、ソフト、およびAPPバージョンの3つのバージョンをお客様に提供します。それぞれに独自の利点があります。次に、MLA-C01テストブレインダンプのPDFバージョンを紹介します。 PDFバージョンが非常に便利で実用的であることはよく知られています。 MLA-C01テストブレインダンプのPDFバージョンは、お客様にデモを提供します。同時に、PDFバージョンを使用している場合は、PDFバージョンごとにMLA-C01試験トレントを印刷できます。メモを取るのはとても簡単です。私たちのMLA-C01テストブレインダンプはあなたに大きな利便性をもたらすと信じています。
質問 # 113
A company has a team of data scientists who use Amazon SageMaker notebook instances to test ML models.
When the data scientists need new permissions, the company attaches the permissions to each individual role that was created during the creation of the SageMaker notebook instance.
The company needs to centralize management of the team's permissions.
Which solution will meet this requirement?
正解:B
解説:
Managing permissions for multiple Amazon SageMaker notebook instances can become complex when handled individually. To centralize and streamline permission management, AWS recommends creating a single IAM role with the necessary permissions and attaching this role to each notebook instance used by the data science team.
Steps to Implement the Solution:
* Create a Single IAM Role with Necessary Permissions:
* Define an IAM role that encompasses all permissions required by the data scientists for their tasks. This includes permissions for SageMaker operations and any other AWS services they interact with.
* AWS provides managed policies like AmazonSageMakerFullAccess that can be attached to the role to grant comprehensive SageMaker permissions.(IAM Policies for SageMaker)
* Attach the IAM Role to Each Notebook Instance:
* When creating or updating a SageMaker notebook instance, specify the IAM role created in the previous step. This ensures that all notebook instances operate under a consistent set of permissions.
* In the SageMaker console, during the notebook instance setup, you can choose an existing IAM role to associate with the instance.(Creating SageMaker Workspaces) Benefits of This Approach:
* Centralized Permission Management:By using a single IAM role, you simplify the process of updating permissions. Changes to the role's policies automatically propagate to all associated notebook instances, ensuring consistent access control.
* Adherence to Best Practices:AWS recommends using IAM roles to manage permissions for applications running on services like SageMaker. This approach avoids the need to manage individual user permissions separately.(IAM Best Practices for SageMaker) Alternative Options and Their Drawbacks:
* Option B:Creating a single IAM group and adding data scientists to it does not directly associate the group with notebook instances. IAM groups are used to manage user permissions, not to assign roles to AWS resources like notebook instances.
* Option C:Using a single IAM user with the AdministratorAccess policy is not recommended due to security risks associated with granting broad permissions and the challenges in managing shared user credentials.
* Option D:Associating an IAM group with a role and then with notebook instances is not a valid approach, as IAM groups cannot be directly associated with AWS resources.
Conclusion:Option A is the most effective solution to centralize and manage permissions for SageMaker notebook instances, aligning with AWS best practices for IAM role management.
References:
* AWS Documentation: IAM Policies for SageMaker
* AWS Documentation: Creating SageMaker Workspaces
* AWS Documentation: IAM Best Practices for SageMaker
質問 # 114
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company is experimenting with consecutive training jobs.
How can the company MINIMIZE infrastructure startup times for these jobs?
正解:D
解説:
When running consecutive training jobs in Amazon SageMaker, infrastructure provisioning can introduce latency, as each job typically requires the allocation and setup of compute resources. To minimize this startup time and enhance efficiency, Amazon SageMaker offers Managed Warm Pools.
Key Features of Managed Warm Pools:
* Reduced Latency: Reusing existing infrastructure significantly reduces startup time for training jobs.
* Configurable Retention Period: Allows retention of resources after training jobs complete, defined by the KeepAlivePeriodInSeconds parameter.
* Automatic Matching: Subsequent jobs with matching configurations (e.g., instance type) can reuse retained infrastructure.
Implementation Steps:
* Request Warm Pool Quota Increase: Increase the default resource quota for warm pools through AWS Service Quotas.
* Configure Training Jobs:
* Set KeepAlivePeriodInSeconds for the first training job to retain resources.
* Ensure subsequent jobs match the retained pool's configuration to enable reuse.
* Monitor Warm Pool Usage: Track warm pool status through the SageMaker console or API to confirm resource reuse.
Considerations:
* Billing: Resources in warm pools are billable during the retention period.
* Matching Requirements: Jobs must have consistent configurations to use warm pools effectively.
Alternative Options:
* Managed Spot Training: Reduces costs by using spare capacity but doesn't address startup latency.
* SageMaker Training Compiler: Optimizes training time but not infrastructure setup.
* SageMaker Distributed Data Parallelism Library: Enhances training efficiency but doesn't reduce setup time.
By using Managed Warm Pools, the company can significantly reduce startup latency for consecutive training jobs, ensuring faster experimentation cycles with minimal operational overhead.
AWS Documentation: Managed Warm Pools
AWS Blog: Reduce ML Model Training Job Startup Time
質問 # 115
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.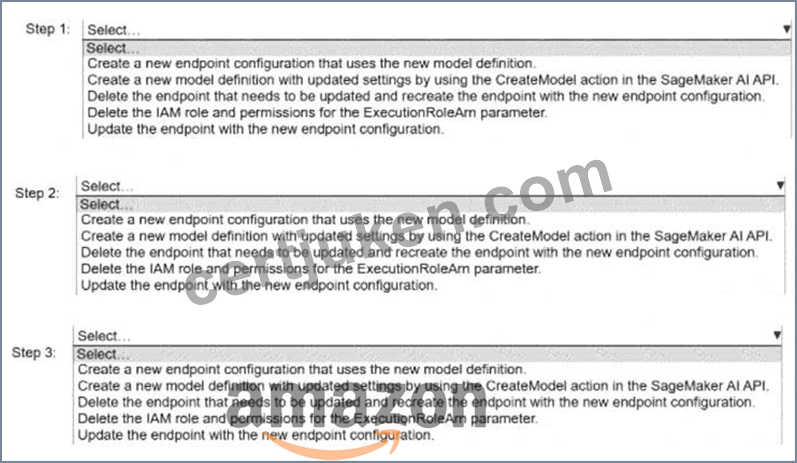
正解:
解説: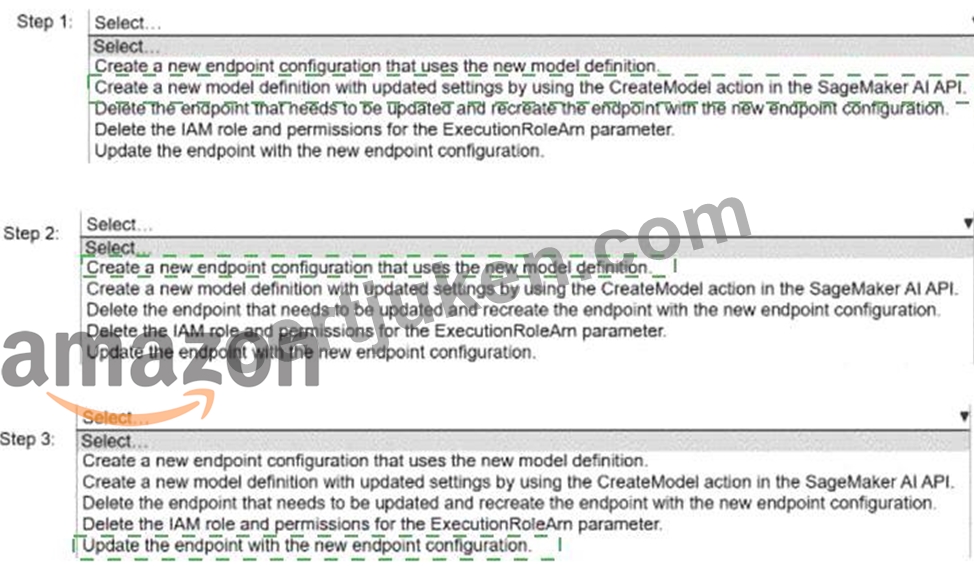
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
質問 # 116
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records every second.
The company needs to implement a scalable solution on AWS to identify anomalous data points.
Which solution will meet these requirements with the LEAST operational overhead?
正解:C
解説:
This solution is the most efficient and involves the least operational overhead:
Amazon Kinesis data streams efficiently handle real-time ingestion of high-volume streaming data.
Amazon Managed Service for Apache Flink provides a fully managed environment for stream processing with built-in support for RANDOM_CUT_FOREST, an algorithm designed for anomaly detection in real- time streaming data.
This approach eliminates the need for deploying and managing additional infrastructure like SageMaker endpoints, Lambda functions, or external tools, making it the most scalable and operationally simple solution.
質問 # 117
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
正解:A
解説:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such as SageMaker Pipelines and the SageMaker Model Registry.
SageMaker Pipelines is a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with the SageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
Define the Pipeline:
Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
Incorporate a Condition Step to assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
Register the Model:
Utilize the RegisterModel step to add the trained model to the Model Registry.
Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
Manual Approval Process:
Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
The approver reviews the model ' s performance and, if satisfactory, updates the model ' s status to Approved using the AWS SDK or through the SageMaker Studio interface.
Deploy the Approved Model:
Configure the pipeline to automatically deploy models with an Approved status to the production endpoint.
This can be managed by adding deployment steps conditioned on the model ' s approval status.
Advantages of This Approach:
Automated Workflow: SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
Governance and Compliance: The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
Scalability: The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines Update the Approval Status of a Model - Amazon SageMaker
質問 # 118
......
学習効率をテストする時間を設定して、実際のMLA-C01試験に参加しているときに指定された時間内にテストを完了することができます。さらに、試験の速度に合わせて調整し、MLA-C01トレーニング資料で設定したタイムキーパーに従ってアラートを維持することができます。したがって、この効果的なシミュレーション機能に関するMLA-C01スタディガイドを信頼することで、最終的に効率が向上し、MLA-C01試験の成功を支援できます。 MLA-C01試験問題の無料デモをお試しください!
MLA-C01合格資料: https://www.certjuken.com/MLA-C01-exam.html
さらに、CertJuken MLA-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1qF4nhWmxHzL-n5430BWefE1JIvriXcxf