BTW, DOWNLOAD part of itPass4sure Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1CbtcNPcTLw0QjV-vF1u-f8akL5uuHQib
These Professional-Machine-Learning-Engineer exam questions are designed and verified by experienced professionals. These professionals have years of experience and they constantly work with us to ensure the top standard of Professional-Machine-Learning-Engineer Exam Questions time. So you do not need to go anywhere. Just visit the itPass4sure and explore the top features of Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Work with foundation models and generative AI techniques - Select appropriate model architectures and frameworks - Optimize model performance and generalization - Design and run experiments |
| Topic 2: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs |
| Topic 3: Automate and orchestrate ML pipelines | 18% | - Implement CI/CD for ML systems - Use Vertex AI Pipelines, TFX, and other orchestration tools - Automate retraining and model updates - Design end-to-end ML workflows |
| Topic 4: Collaborate to manage data and models | 16% | - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Topic 5: Train and deploy models | 20% | - Deploy models for online, batch, and streaming prediction - Use Vertex AI deployment features and infrastructure - Configure training jobs and environments - Implement generative AI deployment patterns |
| Topic 6: Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Monitor data quality and pipeline health - Monitor model performance, fairness, and drift - Optimize cost, latency, and resource usage |
>> Professional-Machine-Learning-Engineer Latest Mock Exam <<
The Google Professional-Machine-Learning-Engineer certification is one of the top-rated career advancement certifications in the market. This Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) certification exam has been inspiring candidates since its beginning. Over this long time period, thousands of Professional-Machine-Learning-Engineer Exam candidates have passed their Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) certification exam and now they are doing jobs in the world's top brands. You can also be a part of this wonderful community.
NEW QUESTION # 316
You recently deployed a scikit-learn model to a Vertex Al endpoint You are now testing the model on live production traffic While monitoring the endpoint. you discover twice as many requests per hour than expected throughout the day You want the endpoint to efficiently scale when the demand increases in the future to prevent users from experiencing high latency What should you do?
Answer: B
Explanation:
The best option for scaling a Vertex AI endpoint efficiently when the demand increases in the future, using a scikit-learn model that is deployed to a Vertex AI endpoint and tested on live production traffic, is to configure an appropriate minReplicaCount value based on expected baseline traffic. This option allows you to leverage the power and simplicity of Vertex AI to automatically scale your endpoint resources according to the traffic patterns. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained model to an online prediction endpoint, which can provide low-latency predictions for individual instances. Vertex AI can also provide various tools and services for data analysis, model development, model deployment, model monitoring, and model governance. A minReplicaCount value is a parameter that specifies the minimum number of replicas that the endpoint must always have, regardless of the load. A minReplicaCount value can help you ensure that the endpoint has enough resources to handle the expected baseline traffic, and avoid high latency or errors. By configuring an appropriate minReplicaCount value based on expected baseline traffic, you can scale your endpoint efficiently when the demand increases in the future. You can set the minReplicaCount value when you deploy the model to the endpoint, or update it later. Vertex AI will automatically scale up or down the number of replicas within the range of the minReplicaCount and maxReplicaCount values, based on the target utilization percentage and the autoscaling metric1.
The other options are not as good as option B, for the following reasons:
* Option A: Deploying two models to the same endpoint and distributing requests among them evenly would not allow you to scale your endpoint efficiently when the demand increases in the future, and could increase the complexity and cost of the deployment process. A model is a resource that represents a machine learning model that you can use for prediction. A model can have one or more versions, which are different implementations of the same model. A model version can help you experiment and iterate on your model, and improve the model performance and accuracy. An endpoint is a resource that provides the service endpoint (URL) you use to request the prediction. An endpoint can have one or more deployed models, which are instances of model versions that are associated with physical resources. A deployed model can help you serve online predictions with low latency, and scale up or down based on the traffic. By deploying two models to the same endpoint and distributing requests among them evenly, you can create a load balancing mechanism that can distribute the traffic across the models, and reduce the load on each model. However, deploying two models to the same endpoint and distributing requests among them evenly would not allow you to scale your endpoint efficiently when the demand increases in the future, and could increase the complexity and cost of the deployment process. You would need to write code, create and configure the two models, deploy the models to the same endpoint, and distribute the requests among them evenly. Moreover, this option would not use the autoscaling feature of Vertex AI, which can automatically adjust the number of replicas based on the traffic patterns, and provide various benefits, such as optimal resource utilization, cost savings, and performance improvement2.
* Option C: Setting the target utilization percentage in the autoscalingMetricSpecs configuration to a higher value would not allow you to scale your endpoint efficiently when the demand increases in the future, and could cause errors or poor performance. A target utilization percentage is a parameter that specifies the desired utilization level of each replica. A target utilization percentage can affect the speed and accuracy of the autoscaling process. A higher target utilization percentage can help you reduce the number of replicas, but it can also cause high latency, low throughput, or resource exhaustion. By setting the target utilization percentage in the autoscalingMetricSpecs configuration to a higher value, you can increase the utilization level of each replica, and save some resources. However, setting the target utilization percentage in the autoscalingMetricSpecs configuration to a higher value would not allow you to scale your endpoint efficiently when the demand increases in the future, and could cause errors or poor performance. You would need to write code, create and configure the autoscalingMetricSpecs, and set the target utilization percentage to a higher value. Moreover, this option would not ensure that the endpoint has enough resources to handle the expected baseline traffic, which could cause high latency or errors1.
* Option D: Changing the model's machine type to one that utilizes GPUs would not allow you to scale your endpoint efficiently when the demand increases in the future, and could increase the complexity and cost of the deployment process. A machine type is a parameter that specifies the type of virtual machine that the prediction service uses for the deployed model. A machine type can affect the speed and accuracy of the prediction process. A machine type that utilizes GPUs can help you accelerate the computation and processing of the prediction, and handle more prediction requests at the same time. By
* changing the model's machine type to one that utilizes GPUs, you can improve the prediction performance and efficiency of your model. However, changing the model's machine type to one that utilizes GPUs would not allow you to scale your endpoint efficiently when the demand increases in the future, and could increase the complexity and cost of the deployment process. You would need to write code, create and configure the model, deploy the model to the endpoint, and change the machine type to one that utilizes GPUs. Moreover, this option would not use the autoscaling feature of Vertex AI, which can automatically adjust the number of replicas based on the traffic patterns, and provide various benefits, such as optimal resource utilization, cost savings, and performance improvement2.
References:
* Configure compute resources for prediction | Vertex AI | Google Cloud
* Deploy a model to an endpoint | Vertex AI | Google Cloud
NEW QUESTION # 317
You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model's accuracy dropped to 66%. How can you make your production model more accurate?
Answer: C
Explanation:
When building a model to predict daily temperatures, it is important to split the training and test data based on time rather than a random split. This is because temperature data is likely to have temporal dependencies and patterns, such as seasonality, trends, and cycles. If the data is split randomly, there is a risk of data leakage, which occurs when information from the future is used to train or validate the model. Data leakage can lead to overfitting and unrealistic performance estimates, as the model may learn from data that it should not have access to. By splitting the data based on time, such as using the most recent data as the test set and the older data as the training set, the model can be evaluated on how well it can forecast future temperatures based on past data, which is the realistic scenario in production. Therefore, splitting the data based on time rather than a random split is the best way to make the production model more accurate.
NEW QUESTION # 318
You are developing a model to predict whether a failure will occur in a critical machine part.
You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed.
You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook.
You want to log data and track artifacts from each run.
How should you set up your experiments?


Answer: D
Explanation:
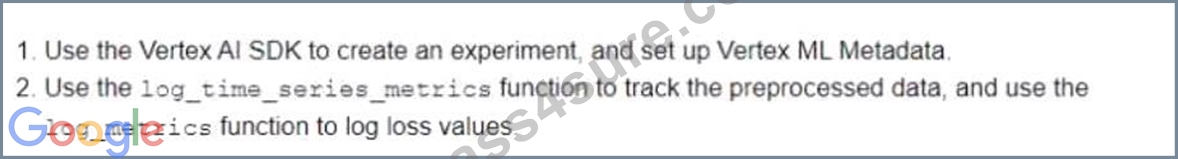
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 319
You built and manage a production system that is responsible for predicting sales numbers.
Model accuracy is crucial, because the production model is required to keep up with market changes. Since being deployed to production, the model hasn't changed; however the accuracy of the model has steadily deteriorated. What issue is most likely causing the steady decline in model accuracy?
Answer: D
Explanation:
Retraining is needed as the market is changing. Its how the Model keep updated and predictions accuracy.
NEW QUESTION # 320
You are responsible for building a unified analytics environment across a variety of on-premises data marts. Your company is experiencing data quality and security challenges when integrating data across the servers, caused by the use of a wide range of disconnected tools and temporary solutions. You need a fully managed, cloud-native data integration service that will lower the total cost of work and reduce repetitive work. Some members on your team prefer a codeless interface for building Extract, Transform, Load (ETL) process. Which service should you use?
Answer: A
Explanation:
https://cloud.google.com/data-fusion/docs/concepts/overview#using_the_code-free_web_ui
NEW QUESTION # 321
......
When candidates don't practice with the latest Professional-Machine-Learning-Engineer exam questions, they fail and lose their precious resources. For candidates who wish to clear the Professional-Machine-Learning-Engineer exam in a short time, itPass4sure offers the latest and actual Google Exam Questions. Our Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions are excellent and ensure that users succeed in one go. Authentic Professional-Machine-Learning-Engineer Exam Questions are available in these formats: web-based practice exam, desktop practice test software, and PDF format. Since every test taker has unique learning styles, itPass4sure has designed these formats to meet the practice needs of Professional-Machine-Learning-Engineer exam candidates.
Professional-Machine-Learning-Engineer Exam Exercise: https://www.itpass4sure.com/Professional-Machine-Learning-Engineer-practice-exam.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by itPass4sure: https://drive.google.com/open?id=1CbtcNPcTLw0QjV-vF1u-f8akL5uuHQib