DOWNLOAD the newest DumpStillValid AB-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1RiTydbe_-BYZ7qDD7GTxymAC2-Ul0-nJ
The Agentic AI Business Solutions Architect (AB-100) certification is one of the hottest career advancement credentials in the modern Microsoft world. The Agentic AI Business Solutions Architect (AB-100) certification can help you to demonstrate your expertise and knowledge level. With only one badge of Agentic AI Business Solutions Architect in AB-100 Certification, successful candidates can advance their careers and increase their earning potential.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
As the saying goes, to develop study interest requires to giving learner a good key for study, this is promoting learner active development of internal factors. The most function of our AB-100 question torrent is to help our customers develop a good study habits, cultivate interest in learning and make them pass their exam easily and get their AB-100 Certification. All workers of our company are working together, in order to produce a high-quality product for candidates. I believe that our AB-100 exam torrent will be very useful for your future.
NEW QUESTION # 105
A company has a Microsoft Copilot Studio agent that provides answers based on a knowledge base for customer support.
Users report that, occasionally, the agent provides inaccurate answers.
You need to use metrics from the Analytics tab in Copilot Studio to identify the cause of the inaccuracies.
Which two options should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
[C]
You can use the Analytics dashboard to identify and fix inaccurate responses by focusing on specific performance signals:
*-> Topics with Low Resolution: This metric identifies individual topics where sessions frequently end without a successful outcome. A low resolution rate often indicates that the topic's logic is flawed, the content is outdated, or it fails to address the user's specific intent.
*-> Topic Usage: High usage of certain topics combined with low resolution or high escalation rates points to critical knowledge gaps. Use this to prioritize which parts of your knowledge base need immediate refinement.
Unrecognized Utterances: Review these to find user phrases that didn't trigger any custom topic, indicating missing content or the need for new trigger phrases.
Analyze User Questions by Theme: Copilot Studio uses AI to group generative responses into themes. You can review these clusters to see which themes have poor response quality and need better grounding or data hygiene.
User Feedback (Thumbs Up/Down): Review specific messages with negative feedback in the Analytics tab to understand exactly where the AI is hallucinating or providing incomplete data.
[D]
In Microsoft Copilot Studio, you can use analytics to pinpoint why your agent is providing inaccurate answers by following a structured improvement checklist.
Using Metrics to Locate Problems
*-> Engagement Rate: A low engagement rate often indicates that your triggers are misconfigured or too broad, causing the agent to initiate the wrong topic or fail to recognize user intent entirely.
*-> Resolution Rate: Identify specific topics with low resolution. If a topic has a high volume of sessions but fails to reach a "Resolved" state, it usually means the knowledge source is outdated, mismatched, or the generative answers are not grounded properly.
*-> Escalation Rate: High escalation rates for particular topics are "red flag" drivers. Use the Escalation Rate Drivers chart to see which topics most frequently force a hand-off to a human agent, indicating where the AI's knowledge or logic is insufficient.
Reference:
https://learn.microsoft.com/en-au/microsoft-copilot-studio/guidance/analytics
https://support.accelevents.com/en/articles/5456691-session-analytics
NEW QUESTION # 106
You are designing a low-code Al business solution by using Microsoft Copilot Studio.
The solution must include an agent that automates tasks by simulating user interactions across third-party apps and websites, such as clicking buttons, entering text, and extracting information from screens.
You need to recommend what to include in the agent.
What should you recommend?
Answer: A
Explanation:
This requirement is very specific: the agent must automate tasks by simulating user interactions across third-party apps and websites , including:
* clicking buttons
* entering text
* extracting information from screens
That is exactly what Computer Use in Copilot Studio is designed for.
Why C is correct:
* Computer Use enables agents to interact with user interfaces in a human-like way.
* It is intended for scenarios where the agent must work across apps and websites that may not expose direct APIs.
* It supports low-code business automation where the AI performs on-screen actions rather than just answering questions.
Why the other options are not correct:
* A. a natural language understanding+ (NLU+) model in Copilot Studio NLU+ helps with understanding user intent, not with UI interaction automation.
* B. Copilot skills Skills extend capabilities, but the question is specifically about simulating on-screen actions across apps and websites.
* D. Model Context Protocol (MCP) MCP is for standardized tool and context integration between models and external systems. It is not the primary feature for direct UI simulation.
NEW QUESTION # 107
You are designing a testing solution for a Microsoft Copilot Studio agent that integrates with Microsoft Dynamics 365 Customer Service and Dynamics 365 Sales.
You need to design end-to-end scenarios to test the agent ' s ability to perform the following actions:
Coordinate tasks and data interactions across both Dynamics 365 apps.
Interpret user input and provide contextually relevant outputs.
Which test scenario and metric should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.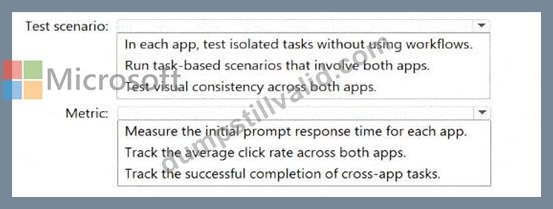
Answer:
Explanation: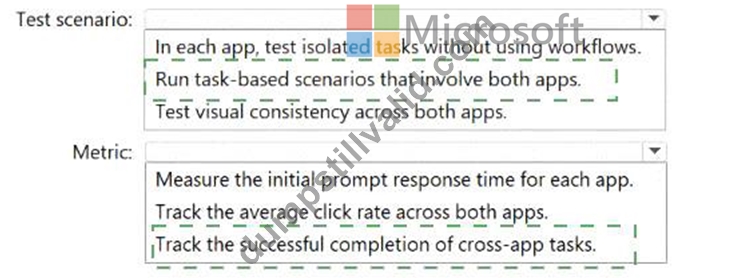
Explanation:
Test scenario # Run task-based scenarios that involve both apps; Metric # Track the successful completion of cross-app tasks Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is D:
Test scenario # Run task-based scenarios that involve both apps
Metric # Track the successful completion of cross-app tasks
Why this test scenario is correct
The question explicitly asks for an end-to-end testing design for a Copilot Studio agent that integrates with both:
Dynamics 365 Customer Service
Dynamics 365 Sales
The required capabilities are:
coordinating tasks and data interactions across both apps
interpreting user input and returning contextually relevant outputs
That means the testing approach cannot be isolated to one app at a time. It must validate the agent's behavior across the full multi-application business workflow.
That is why the correct test scenario is:
Run task-based scenarios that involve both apps
This kind of test validates whether the agent can successfully move through realistic business processes such as:
reading customer context from one app
updating or retrieving related sales information in the other
maintaining context through the workflow
responding appropriately based on user intent across systems
From an agentic AI business solutions perspective, this is the right design because true enterprise agent validation must focus on workflow execution, not just component-level checks.
Why this metric is correct
The best metric is:
Track the successful completion of cross-app tasks
This is the most direct way to measure whether the agent is actually achieving the intended business outcome across both Dynamics 365 applications.
Why this matters:
The requirement is about coordination across apps
The test is end-to-end
The goal is not just speed or UI consistency
The agent must complete business tasks successfully across systems
A cross-app completion metric shows whether the agent can:
understand the user's request
maintain context
retrieve or update the right information
finish the workflow correctly across app boundaries
This is much more meaningful than measuring clicks or simple response time.
Why the other options are incorrect
A). In each app, test isolated tasks without using workflows / Measure initial prompt response time This fails the end-to-end requirement. Isolated tasks do not validate cross-app orchestration, and response time does not prove successful workflow execution.
B). Run task-based scenarios that involve both apps / Track average click rate across both apps The scenario part is good, but average click rate is not the right success metric for Copilot task orchestration.
Clicks do not reliably measure whether the business process was completed correctly.
C). Test visual consistency across both apps / Track successful completion of cross-app tasks The metric is good, but the test scenario is wrong. Visual consistency is a UI concern, not an end-to-end functional validation of cross-app agent behavior.
Expert reasoning
For exam questions like this:
If the requirement says end-to-end across multiple apps, choose task-based scenarios involving both apps If the goal is business workflow success, choose a metric tied to task completion, not visual design, click rate, or raw response speed
NEW QUESTION # 108
A company has a cloud-based Al solution that uses Azure OpenAI models.
You need to design a monitoring solution that meets the following requirements:
* Monitors performance metrics and operational health for the models
* Monitors Al apps and agents for compliance
* Uses Azure-native capabilities
* Minimizes development effort
What should you use for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.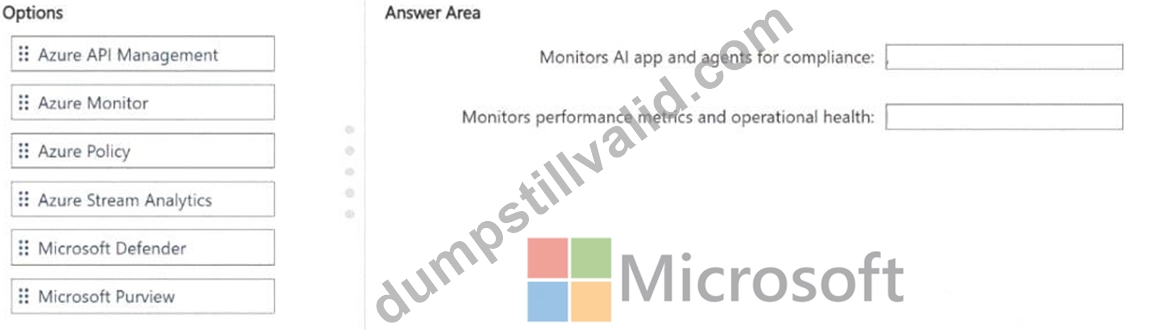
Answer:
Explanation: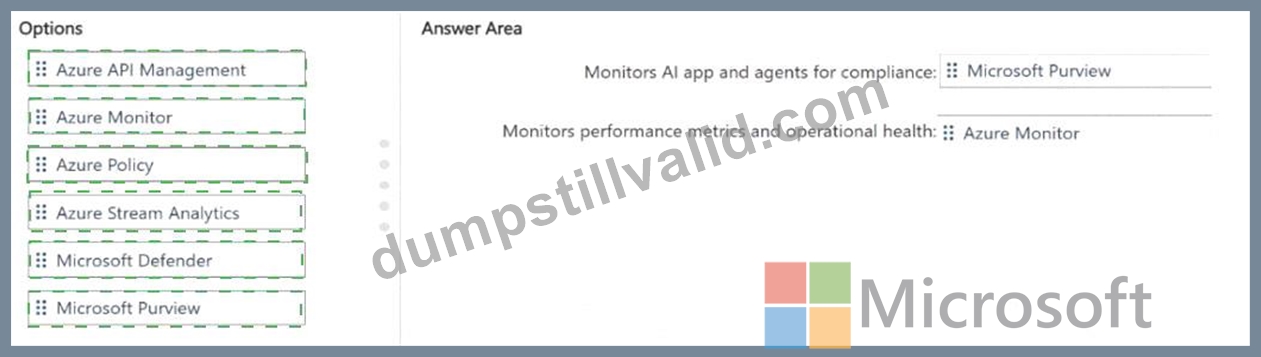
Explanation:
Verified Answer : =
* Monitors AI app and agents for compliance # Microsoft Purview
* Monitors performance metrics and operational health # Azure Monitor
For an Azure-based AI solution using Azure OpenAI models , the best Azure-native monitoring design is to separate:
* operational and performance monitoring
* compliance and governance monitoring
For performance metrics and operational health , the correct choice is Azure Monitor . It is the standard Azure-native service for collecting telemetry, tracking service health, monitoring metrics, analyzing logs, and alerting on runtime issues. This is the best fit for model and application operational monitoring with minimal development effort.
For monitoring AI apps and agents for compliance , the correct choice is Microsoft Purview . Purview is designed for compliance, governance, data protection, and policy-based oversight across data and AI-related assets. It aligns best with the requirement to monitor AI applications and agents from a compliance perspective.
Why the other options are not the best fit:
* Azure API Management is for API exposure, management, and security, not primary compliance or operational monitoring.
* Azure Policy is used to enforce and assess Azure resource compliance, but it is not the main tool for monitoring AI apps and agents in the broader compliance/governance sense asked here.
* Azure Stream Analytics is for streaming data processing, not this monitoring scenario.
* Microsoft Defender is focused on security threat detection and posture, not overall AI compliance monitoring.
NEW QUESTION # 109
Your company is deploying customer support agents in Microsoft Foundry for a claims business group that uses sensitive grounding data The group has a production project that connects to a data source by using a project-scoped connection that uses Microsoft Entra pass through authentication.
The solution has the following requirements:
* For grounding data changes, the company must log data ingestion events, sensitivity label changes, and data movement across geographical regions. Audit records must preserve traceability for investigations, and only capture metadata.
* The solution must use a DataZone deployment in a Foundry resource located in the United States for the Azure Direct.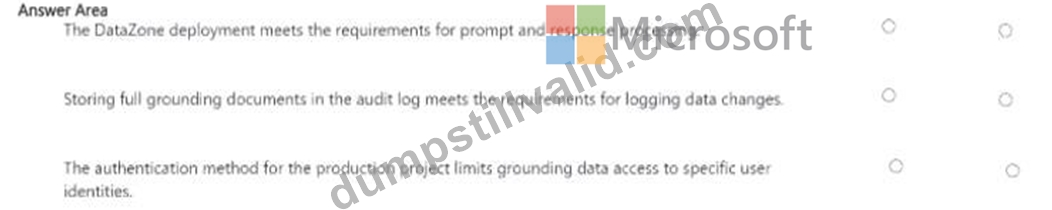
Answer:
Explanation: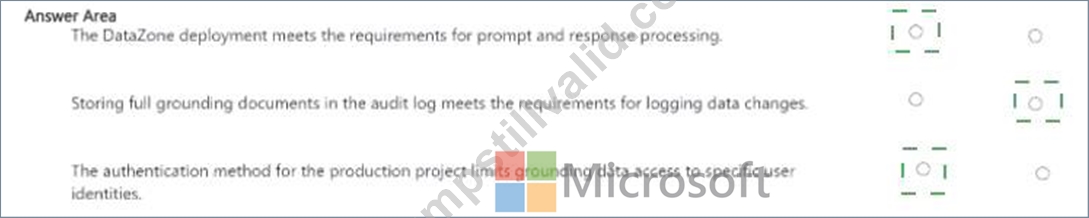
Explanation:
* DataZone deployment # Yes
* Full grounding documents in audit log # No
* Microsoft Entra passthrough authentication # Yes
A DataZone deployment created in a Microsoft Foundry resource located in the United States processes prompts and responses within the United States data zone . Microsoft states that DataZone deployments restrict inference processing to the specified data zone, unlike Global deployments, which can process requests across supported Azure geographies. Therefore, the described US DataZone deployment satisfies the prompt-and-response processing residency requirement.
The second statement is No . The requirement explicitly specifies that audit records must capture metadata only while preserving traceability of ingestion events, sensitivity-label changes, and geographical data movement. Storing the complete grounding documents would place actual sensitive content in the audit trail and directly violate that requirement. Audit information should therefore identify relevant events and contextual metadata without duplicating the grounding content itself.
The third statement is Yes . Microsoft Entra identity passthrough allows access to be evaluated using the individual user ' s identity and permissions , rather than a common project credential. Microsoft recommends user-token/Entra passthrough specifically when sensitive data sources require greater per-user access control.
NEW QUESTION # 110
......
Annual test syllabus is essential to predicate the real AB-100 questions. So you must have a whole understanding of the test syllabus. After all, you do not know the AB-100 exam clearly. It must be difficult for you to prepare the AB-100 exam. Then our study materials can give you some guidance. All questions on our AB-100 study materials are strictly in accordance with the knowledge points on newest test syllabus. Also, our experts are capable of predicating the difficult knowledge parts of the AB-100 Exam according to the test syllabus. We have tried our best to simply the difficult questions. In order to help you memorize the AB-100 study materials better, we have detailed explanations of the difficult questions such as illustration, charts and referring website. Every year some knowledge is reoccurring over and over. You must ensure that you master them completely.
Valid Test AB-100 Format: https://www.dumpstillvalid.com/AB-100-prep4sure-review.html
What's more, part of that DumpStillValid AB-100 dumps now are free: https://drive.google.com/open?id=1RiTydbe_-BYZ7qDD7GTxymAC2-Ul0-nJ