The Dumpcollection is a trusted and reliable platform that has been helping the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam candidates for many years. Over this long time period, the Databricks-Certified-Professional-Data-Engineer Exam Practice questions have helped the Databricks-Certified-Professional-Data-Engineer exam candidates in their preparation and enabled them to pass the challenging exam on the first attempt.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Available Languages: | English |
| Real Exam Qty: | 60 |
| Exam Format: | Multiple Select, Multiple Choice |
| Passing Score: | 70% |
| Exam Price: | $200 USD |
| Related Certifications: | Databricks Certified Data Analyst Associate Databricks Certified Associate Developer |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Latest Databricks-Certified-Professional-Data-Engineer Exam Format <<
Our Databricks-Certified-Professional-Data-Engineer study materials include all the qualification tests in recent years, as well as corresponding supporting materials. Such a huge amount of database can greatly satisfy users' learning needs. Not enough valid Databricks-Certified-Professional-Data-Engineer learning materials, will bring many inconvenience to the user, such as delay learning progress, reduce the learning efficiency eventually lead to the user's study achievement was not significant, these are not conducive to the user pass exam, therefore, in order to solve these problems, our Databricks-Certified-Professional-Data-Engineer Study Materials will do a complete summarize and precision of summary analysis.
The Databricks Certified Professional Data Engineer Exam certification verifies that the candidate has significant experience in implementing big data solutions that operate on the Databricks Delta Architecture. To earn the certification, a candidate must pass a 90-minute exam consisting of up to 50 multiple-choice and multiple-select questions. The Databricks-Certified-Professional-Data-Engineer Certification is valid for two years from the date of passing the exam.
NEW QUESTION # 133
The following code has been migrated to a Databricks notebook from a legacy workload: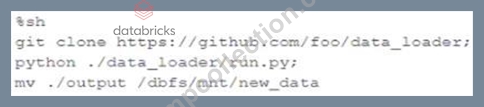
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
Answer: C
Explanation:
Explanation
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 134
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
Answer: A
Explanation:
In Databricks, catalogs, schemas (or databases), and tables are managed through the Unity Catalog or Hive Metastore, depending on the environment. Permissions and ownership within these structures are governed by access control lists (ACLs).
* Catalog and Schema Ownership: When a platform engineer creates a catalog (such as catalog_A) and schema (such as schema_A), they automatically become the owner of those entities. This ownership gives them control over granting permissions for those entities (i.e., granting the USE CATALOG and USE SCHEMA privileges to others). However, ownership of the catalog or schema does not automatically extend to ownership or permission of individual tables within that schema.
* Table Permissions: For tables within a schema, the permission model is more granular. The table creator (i.e., whoever creates the table) is automatically assigned as the owner of that table. In this case, the platform engineer owns the schema but does not automatically inherit permissions to any table created within the schema unless explicitly granted by the table's owner or unless they grant permissions to themselves.
* Why the Engineer Lacks Access: The platform engineer notices that they do not have access to the underlying tables in schema_A despite being the owner of the schema. This occurs because the schema's ownership does not cascade to the tables. The engineer must either:
* Grant permissions to themselves for the tables in schema_A, or
* Be granted permissions by whoever created the tables within the schema.
* Resolution: As the owner of the schema, the platform engineer can easily grant themselves the required permissions (such as SELECT, INSERT, etc.) for the tables in the schema. This explains why the owner of a schema may not automatically have access to the tables and must take explicit steps to acquire those permissions.
References
* Databricks Unity Catalog Documentation: Manage Permissions
* [Databricks Permissions and Ownership (https://docs.databricks.com/security/access-control/workspace-acl.html#permissions
NEW QUESTION # 135
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: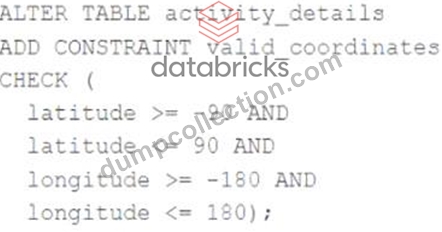
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
Answer: B
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints: https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions: https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 136
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
Answer: E
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph.
If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. References:
* transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes
* Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
NEW QUESTION # 137
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources.
Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table.
Given the current implementation, which method can be used?
Answer: B
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
References:
* Delta Lake Documentation on Time Travel: Delta Time Travel
* Delta Lake Versioning: Delta Lake Versioning Guide
NEW QUESTION # 138
......
Training Databricks-Certified-Professional-Data-Engineer Material: https://www.dumpcollection.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html