BTW, DOWNLOAD part of Actual4Exams AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1G9MRKiL9NxRLaJKQ3O3upGeg3F2RuQop
First and foremost, the pass rate of our AI-300 training guide among our customers has reached as high as 98% to 100%, which marks the highest pass rate in the field, we are waiting for you to be the next beneficiary. Second, you can get our AI-300 practice test only in 5 to 10 minutes after payment, which enables you to devote yourself to study with our AI-300 Exam Questions as soon as possible. Last but not least, you will get the privilege to enjoy free renewal of our AI-300 preparation materials during the whole year. All of the staffs in our company wish you early success.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 5: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
>> Exam AI-300 Cram Questions <<
The trick to the success is simply to be organized, efficient, and to stay positive about it. If you are remain an optimistic mind all the time when you are preparing for the AI-300 exam, we deeply believe that it will be very easy for you to successfully pass the exam, and get the related certification in the near future. Of course, we also know that how to keep an optimistic mind is a question that is very difficult for a lot of people to answer. Because the AI-300 Exam is so difficult for a lot of people that many people have a failure to pass the exam.
NEW QUESTION # 75
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
An organization provisions Azure Machine Learning workspaces for development, test, and production environments.
Each environment must be deployed consistently and updated through source control. The deployment process must be automated, repeatable, and auditable.
You need to deploy Azure Machine Learning resources in a consistent and controlled manner.
Solution: Clone an existing Azure Machine Learning workspace to create additional environments.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
This action is best because it fulfills all of your operational requirements:
Consistency & Controlled Manner:
Infrastructure as Code (IaC) via Bicep ensures that dev, test, and prod environments are configured identically, eliminating configuration drift.
Source Control: Storing the Bicep template in a Git repository satisfies the requirement that each environment must be updated through source control.
Automated & Repeatable: Orchestrating the deployment using GitHub Actions fully automates the workflow, allowing it to be executed reliably every time a change is merged.
Auditable: Git commit histories combined with GitHub deployment logs provide a comprehensive, compliant audit trail of exactly who modified the infrastructure and when.
Incorrect:
* Clone an existing Azure Machine Learning workspace to create additional environments.
* Create Azure Machine Learning workspaces manually in the Azure portal for each environment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-github-actions-machine-learning
NEW QUESTION # 76
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
Answer: A
Explanation:
To ensure that older Azure Machine Learning model versions are no longer deployable but remain available for reference or historical tracking, you should archive those specific versions.
How to Archive Model Versions
Archiving a model version effectively hides it from standard list queries and management interfaces, preventing accidental deployment while maintaining its metadata and files in the workspace.
Behavior of Archived Models:
Hidden by Default: They will no longer appear in the Azure Machine Learning Studio model list unless you explicitly filter for archived assets.
Referenceable: You can still reference and use an archived model version in existing workflows if you have its specific version number.
Restoreable: If you need to redeploy the model in the future, you can use the restore command to make it active again.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-manage-models
NEW QUESTION # 77
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
- Queries that include exact policy identifiers must return matching
documents even when semantic similarity is low.
- Natural-language questions must prioritize semantically relevant
documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.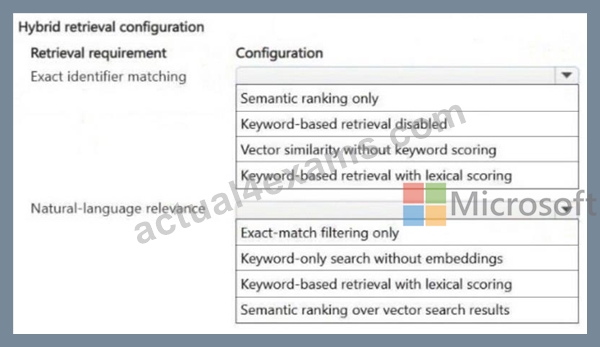
Answer:
Explanation: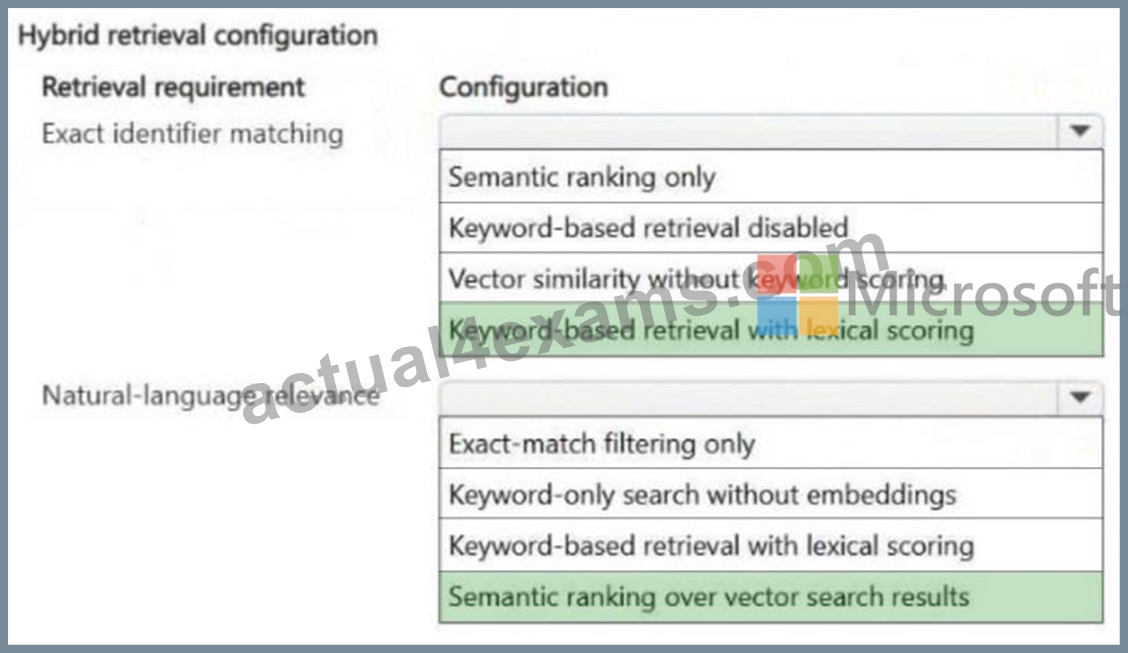
NEW QUESTION # 78
A data science team trains a classification model that predicts loan approval outcomes.
Before registering the model, the team must ensure the following:
- Predictions must not disproportionately impact protected groups.
- Prediction errors can be evaluated across different data segments.
You need to assess whether the model meets Responsible AI expectations.
Which two approaches should you use? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,E
Explanation:
[D]
To evaluate a trained loan classification model for Responsible AI expectations--ensuring no disproportionate impact on protected groups, evaluating error across segments, and verifying prediction transparency--you can employ SHAP (SHapley Additive exPlanations) values to assess feature importance.
This approach allows you to identify which variables (e.g., credit history, debt levels) drive the model's predictions, fostering trust and fairness.
Feature Importance for Transparency: Use SHAP (model-agnostic) or LIME (local approximations) to explain why the model approved or denied a loan. These techniques identify how each feature contributes to individual predictions.
[E]
To ensure a trained loan approval classification model meets responsible AI expectations-- specifically, that it does not disproportionately impact protected groups and that errors can be evaluated across segments--you should analyze error rates across defined demographic cohorts using Fairness-Aware Machine Learning metrics.
Reference:
https://urfpublishers.com/journal/artificial-intelligence/article/view/explainable-aiml-testing- ensuring-transparency-accountability-and-compliance
https://timvero.com/blog/ethics-in-automated-lending-can-ai-make-fair-credit-decisions
NEW QUESTION # 79
A team is experimenting with traditional models for a classification workflow in Azure Machine Learning.
The team requires a consistent way to manage assets that are created during experimentation.
You need to ensure that artifacts can be reused and governed across projects.
Which asset should you register?
Answer: D
Explanation:
In an Azure Machine Learning classification workflow, you should register Models.
Registration creates a versioned asset in your workspace or a centralized registry, which is essential for ensuring that artifacts are reusable, governed, and trackable across different projects and environments.
Key Assets for Reuse and Governance
To maintain a consistent and governed workflow, you should focus on registering these specific assets:
Models: The primary artifact. Registering a model allows you to track its lineage (which experiment created it), version it, and deploy it consistently across environments.
Components: These are self-contained pieces of code that perform specific steps in a pipeline (e.g., data cleaning, training). Registering them allows different teams to reuse the same
"traditional" classification logic without rewriting code.
Environments: Encapsulates the software dependencies (Python packages, Docker images) required for your model to run. Registering these ensures reproducibility across different compute targets.
Data Assets: Registering your training and testing datasets as versioned assets ensures that you can always audit exactly what data was used to train a specific model version.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-azure-machine-learning-v2
NEW QUESTION # 80
......
Desktop and web-based AI-300 practice exams are available at Actual4Exams for thorough preparation. Going through these Microsoft AI-300 mock exams boosts your learning and reduces mistakes in the Microsoft AI-300 Test Preparation. Customization features of Microsoft AI-300 practice tests allow you to change the settings of the AI-300 test sessions.
AI-300 Test Questions Answers: https://www.actual4exams.com/AI-300-valid-dump.html
P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by Actual4Exams: https://drive.google.com/open?id=1G9MRKiL9NxRLaJKQ3O3upGeg3F2RuQop