2026 Latest itPass4sure SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1MuQyz8-4cdJCJAthL3yY4Bl1JGG9Ij3l
Opportunities are very important in this society. With the opportunity you can go further. However, it is difficult to seize the opportunity. Is your strength worthy of the opportunity before you? In any case, you really need to make yourself better by using our SPS-C01 training engine. With our SPS-C01 Exam Questions, you can equip yourself with the most specialized knowledage of the subject. What is more, our SPS-C01 study materials can help you get the certification. Imagine you're coming good future maybe you will make a better choice!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API for Python | 30% | - Reading and writing data - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management |
| Topic 2: Performance Optimization and Best Practices | 20% | - Caching strategies - Debugging and explain plans - Minimizing data transfer - Query pushdown and optimization - Warehouse sizing for Snowpark - Vectorized UDFs |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Persisting transformed data |
| Topic 4: Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Transformations vs. Actions - Snowpark architecture and core concepts - Client-side vs. Server-side execution - Stored procedures and conditional logic |
>> Prep Snowflake SPS-C01 Guide <<
Firstly, we can give you 100% pass rate guarantee on the SPS-C01 exam. Our SPS-C01 practice quiz is equipped with a simulated examination system with timing function, allowing you to examine your learning results at any time, keep checking for defects, and improve your strength. Secondly, during the period of using SPS-C01 learning guide, we also provide you with 24 hours of free online services, which help to solve any problem for you on the SPS-C01 exam questions at any time and sometimes mean a lot to our customers.
NEW QUESTION # 356
Given a Snowpark DataFrame 'employees_df with columns 'employee_id' , 'department' , and 'salary' , and a second Snowpark DataFrame 'departments_df with columns 'department_id' and which of the following Snowpark code snippets correctly performs a join to retrieve employee information along with their department name, filtering for employees with salaries greater than $60,000, and then orders the result by department name?

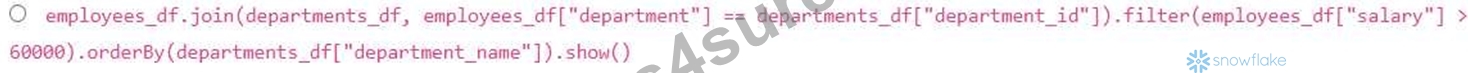



Answer: E
Explanation:
Explanation:Option E first filters the 'employees_df for salaries greater than $60,000, then joins with 'departments_df using the appropriate join condition (employee.department = department.department_id), and finally orders the result by department name. Using instead of and instead of also acceptable syntax. It's more efficient to filter before joining, so E is better than D, and more importantly E and D work correctly. The other options will throw an error.
NEW QUESTION # 357
You are tasked with optimizing a Snowpark Python application that performs complex data transformations on a large dataset. The application's performance is currently bottlenecked by the data transfer between Snowflake and the client machine running the Python code. Which of the following strategies can effectively minimize data transfer and improve performance?
Answer: C
Explanation:
Snowpark's lazy evaluation, data filtering/aggregation within Snowflake, and vectorized UDFs are crucial for minimizing data transfer. Lazy evaluation ensures that data is only transferred when needed. Pushing down operations like filtering and aggregation to Snowflake reduces the amount of data transferred. Vectorized UDFs allow UDFs to operate on batches of data, improving performance. Fetching the entire dataset into a Pandas DataFrame (C) exacerbates the data transfer bottleneck. Disabling lazy evaluation (D) is counterproductive.
NEW QUESTION # 358
A Snowpark Python application is experiencing significant performance degradation when processing a large dataset (100GB+) stored in Snowflake. The application performs a complex series of transformations, including window functions and joins with smaller lookup tables. You suspect data skew is contributing to the issue. Which of the following strategies would be MOST effective in mitigating the impact of data skew and improving performance?
Answer: D
Explanation:
Salting or pre-partitioning addresses data skew directly by distributing the skewed values more evenly across partitions. Increasing warehouse size (A) might help to some extent but doesn't solve the underlying skew issue. Broadcasting small tables (C) is a good optimization, but it's less effective if the larger dataset is skewed. Disabling query result caching (D) is irrelevant to data skew. Converting to Pandas (E) will likely make performance worse for large datasets due to data transfer overhead and limitations of single-node processing.
NEW QUESTION # 359
A UDTF (User-Defined Table Function) named 'split_sentences" takes a text string as input and returns a table with each row containing a single sentence from the input. You need to grant SELECT privilege on this UDTF to a specific role, 'DATA ANALYST'. Which of the following SQL statements will achieve this?
Answer: A
Explanation:
Since UDTFs return a table, you need to grant the 'SELECT privilege on the table function to allow the role to query the results produced by the UDTF. The syntax is 'GRANT SELECT ON TABLE FUNCTION'. option A is wrong it's for UDE Options C and E provide too many privileges, potentially allowing unintended modifications. Option D is not the correct Privilege.
NEW QUESTION # 360
You have a Snowpark DataFrame named containing order data that needs to be inserted into the 'ORDERS table. However, due to a recent data ingestion issue, some records in might already exist in the 'ORDERS table based on the 'ORDER ID' column. Your goal is to insert only the new orders into the 'ORDERS table while avoiding duplicates. Which of the following approaches, combining efficiency and correctness, is most suitable for this task? Assume 'session' and required libraries are already imported.
Answer: B,C
Explanation:
Options A and C are both suitable and efficient. Option A uses a 'left_anti' join to identify records in 'staged_orders' that do not exist in the 'ORDERS' table based on 'ORDER ID. This is a standard and efficient way to filter out existing records using Snowpark's DataFrame operations. Option C suggests a stored procedure with a MERGE statement, which is highly efficient for upsert operations directly within Snowflake. Option B is inefficient because it collects all the order IDs from the 'ORDERS table into the driver's memory, which could cause memory issues with large datasets. Option D is incorrect as 'on_duplicate_key' is not a valid parameter for insert_into method. Option E is using pandas dataframe to insert, which might not perform well in terms of scale.
NEW QUESTION # 361
......
According to the survey, the candidates most want to take Snowflake SPS-C01 test in the current IT certification exams. Of course, the Snowflake SPS-C01 certification is a very important exam which has been certified. In addition, the exam qualification can prove that you have high skills. However, like all the exams, Snowflake SPS-C01 test is also very difficult. To pass the exam is difficult but itPass4sure can help you to get Snowflake SPS-C01 certification.
SPS-C01 Free Exam: https://www.itpass4sure.com/SPS-C01-practice-exam.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by itPass4sure: https://drive.google.com/open?id=1MuQyz8-4cdJCJAthL3yY4Bl1JGG9Ij3l