Databricks Databricks-Certified-Data-Analyst-Associate認定デベロッパー: Databricks Certified Data Analyst Associate Exam - JPNTest確実に合格するのを助ける

BONUS!!! JPNTest Databricks-Certified-Data-Analyst-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1Hq81fan0e526AU97xGX46HWlbeceFpKI
IT認定試験の中でどんな試験を受けても、JPNTestのDatabricks-Certified-Data-Analyst-Associate試験参考資料はあなたに大きなヘルプを与えることができます。それは JPNTestのDatabricks-Certified-Data-Analyst-Associate問題集には実際の試験に出題される可能性がある問題をすべて含んでいて、しかもあなたをよりよく問題を理解させるように詳しい解析を与えますから。真剣にJPNTestのDatabricks Databricks-Certified-Data-Analyst-Associate問題集を勉強する限り、受験したい試験に楽に合格することができるということです。
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
|---|
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
|---|
| Exam Duration: | 90 minutes |
|---|
| Related Certifications: | Databricks Certified Data Engineer Associate
Databricks Certified Machine Learning Associate |
|---|
| Real Exam Qty: | 45 |
|---|
| Available Languages: | English |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | $200 USD |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Exam Format: | Multiple Choice |
|---|
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
|---|
| Exam Way: | Online proctored or test center proctored |
|---|
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
|---|
>> Databricks-Certified-Data-Analyst-Associate認定デベロッパー <<
Databricks Databricks-Certified-Data-Analyst-Associate難易度 & Databricks-Certified-Data-Analyst-Associate受験記対策
IT業種が新しい業種で、経済発展を促進するチェーンですから、極めて重要な存在ということを我々は良く知っています。IT認証はIT業種での競争な手段の一つです。認証に受かったらあなたは各方面でよく向上させます。でも、受かることが難しいですから、トレーニングツールを利用するのを勧めます。トレーニング資料を選びたいのなら、JPNTestのDatabricksのDatabricks-Certified-Data-Analyst-Associate試験トレーニング資料は最高の選択です。この資料の成功率が100パーセントに達して、あなたが試験に合格することを保証します。
Databricks Databricks-Certified-Data-Analyst-Associate 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| トピック 2 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| トピック 3 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| トピック 4 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| トピック 5 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
Databricks Certified Data Analyst Associate Exam 認定 Databricks-Certified-Data-Analyst-Associate 試験問題 (Q15-Q20):
質問 # 15
A data analyst has written and saved a series of queries that reveal trends that need to be monitored by several stakeholders.
Which tool should the data analyst use to share the results of all of the queries to be viewed at once?
- A. A Query History page
- B. A data visualization tab on a Query page
- C. A dashboard
- D. A SQL warehouse
正解:C
解説:
The correct answer is C because a dashboard is designed to collect multiple visualizations and query outputs in one shared reporting interface. A SQL warehouse provides compute for running SQL queries, but it is not a sharing/reporting interface. Query History only shows past query executions. A visualization tab belongs to one query result, while a dashboard can display multiple results together for stakeholders.
Official documentation extract used: Databricks states that dashboards are used to "build data visualizations and share reports with your team."
質問 # 16
Which of the following layers of the medallion architecture is most commonly used by data analysts?
- A. Silver
- B. Gold
- C. None of these layers are used by data analysts
- D. All of these layers are used equally by data analysts
- E. Bronze
正解:B
解説:
The gold layer of the medallion architecture contains data that is highly refined and aggregated, and powers analytics, machine learning, and production applications. Data analysts typically use the gold layer to access data that has been transformed into knowledge, rather than just information. The gold layer represents the final stage of data quality and optimization in the lakehouse. Reference: What is the medallion lakehouse architecture?
質問 # 17
Which of the following describes how Databricks SQL should be used in relation to other business intelligence (BI) tools like Tableau, Power BI, and looker?
- A. As a complementary tool for quick in-platform Bl work
- B. As a substitute with less functionality
- C. As a complementary tool for professional-grade presentations
- D. As a complete replacement with additional functionality
- E. As an exact substitute with the same level of functionality
正解:A
解説:
Databricks SQL is not meant to replace or substitute other BI tools, but rather to complement them by providing a fast and easy way to query, explore, and visualize data on the lakehouse using the built-in SQL editor, visualizations, and dashboards. Databricks SQL also integrates seamlessly with popular BI tools like Tableau, Power BI, and Looker, allowing analysts to use their preferred tools to access data through Databricks clusters and SQL warehouses. Databricks SQL offers low-code and no-code experiences, as well as optimized connectors and serverless compute, to enhance the productivity and performance of BI workloads on the lakehouse. References: Databricks SQL, Connecting Applications and BI Tools to Databricks SQL, Databricks integrations overview, Databricks SQL: Delivering a Production SQL Development Experience on the Lakehouse
質問 # 18
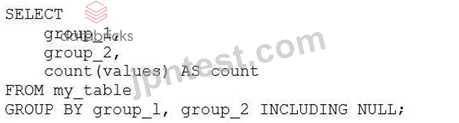
A data analyst is processing a complex aggregation on a table with zero null values and their query returns the following result:
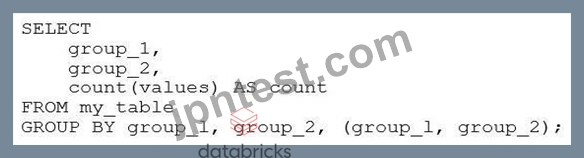
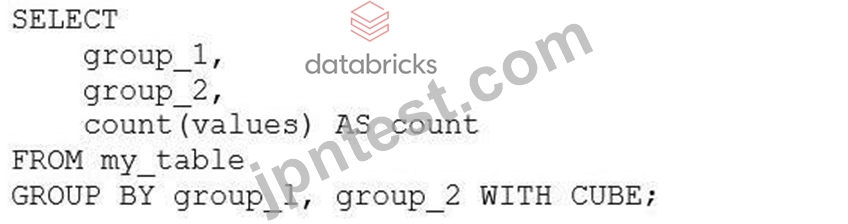
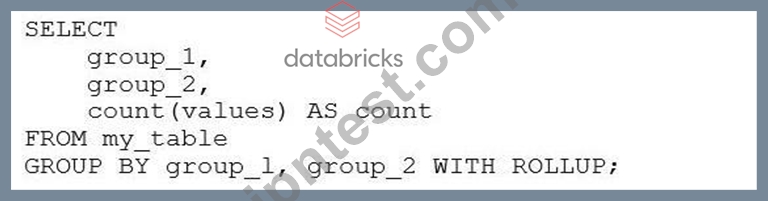
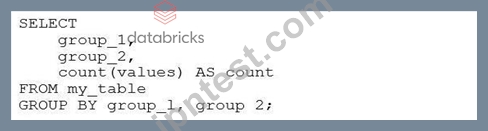
Which of the following queries did the analyst run to obtain the above result?
正解:C
解説:
The result set provided shows a combination of grouping by two columns (group_1 and group_2) with subtotals for each level of grouping and a grand total. This pattern is typical of a GROUP BY ... WITH ROLLUP operation in SQL, which provides subtotal rows and a grand total row in the result set.
Considering the query options:
A) Option A: GROUP BY group_1, group_2 INCLUDING NULL - This is not a standard SQL clause and would not result in subtotals and a grand total.
B) Option B: GROUP BY group_1, group_2 WITH ROLLUP - This would create subtotals for each unique group_1, each combination of group_1 and group_2, and a grand total, which matches the result set provided.
C) Option C: GROUP BY group_1, group 2 - This is a simple GROUP BY and would not include subtotals or a grand total.
D) Option D: GROUP BY group_1, group_2, (group_1, group_2) - This syntax is not standard and would likely result in an error or be interpreted as a simple GROUP BY, not providing the subtotals and grand total.
E) Option E: GROUP BY group_1, group_2 WITH CUBE - The WITH CUBE operation produces subtotals for all combinations of the selected columns and a grand total, which is more than what is shown in the result set.
The correct answer is Option B, which uses WITH ROLLUP to generate the subtotals for each level of grouping as well as a grand total. This matches the result set where we have subtotals for each group_1, each combination of group_1 and group_2, and the grand total where both group_1 and group_2 are NULL.
質問 # 19
Which of the following is an advantage of using a Delta Lake-based data lakehouse over common data lake solutions?
- A. Flexible schemas
- B. ACID transactions
- C. Data deletion
- D. Scalable storage
- E. Open-source formats
正解:B
解説:
A Delta Lake-based data lakehouse is a data platform architecture that combines the scalability and flexibility of a data lake with the reliability and performance of a data warehouse. One of the key advantages of using a Delta Lake-based data lakehouse over common data lake solutions is that it supports ACID transactions, which ensure data integrity and consistency. ACID transactions enable concurrent reads and writes, schema enforcement and evolution, data versioning and rollback, and data quality checks. These features are not available in traditional data lakes, which rely on file-based storage systems that do not support transactions. Reference:
Delta Lake: Lakehouse, warehouse, advantages | Definition
Synapse - Data Lake vs. Delta Lake vs. Data Lakehouse
Data Lake vs. Delta Lake - A Detailed Comparison
Building a Data Lakehouse with Delta Lake Architecture: A Comprehensive Guide
質問 # 20
......
Databricks-Certified-Data-Analyst-Associate難易度: https://www.jpntest.com/shiken/Databricks-Certified-Data-Analyst-Associate-mondaishu
- Databricks-Certified-Data-Analyst-Associate対応資料 ⏳ Databricks-Certified-Data-Analyst-Associate最新受験攻略 🃏 Databricks-Certified-Data-Analyst-Associate最新受験攻略 🦼 ➡ jp.fast2test.com ️⬅️で( Databricks-Certified-Data-Analyst-Associate )を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associate問題集
- Databricks-Certified-Data-Analyst-Associate問題無料 🌴 Databricks-Certified-Data-Analyst-Associate問題無料 🧆 Databricks-Certified-Data-Analyst-Associateテスト問題集 🍊 ✔ www.goshiken.com ️✔️で使える無料オンライン版[ Databricks-Certified-Data-Analyst-Associate ] の試験問題Databricks-Certified-Data-Analyst-Associate練習問題
- Databricks-Certified-Data-Analyst-Associate問題無料 🔡 Databricks-Certified-Data-Analyst-Associate問題集無料 🍇 Databricks-Certified-Data-Analyst-Associate資格復習テキスト 🚤 ✔ www.mogiexam.com ️✔️は、✔ Databricks-Certified-Data-Analyst-Associate ️✔️を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Analyst-Associateテスト問題集
- Databricks-Certified-Data-Analyst-Associate資格復習テキスト 🧫 Databricks-Certified-Data-Analyst-Associate資格取得講座 🥣 Databricks-Certified-Data-Analyst-Associate問題無料 👭 ⏩ www.goshiken.com ⏪サイトで⇛ Databricks-Certified-Data-Analyst-Associate ⇚の最新問題が使えるDatabricks-Certified-Data-Analyst-Associate資格認定
- 更新するDatabricks-Certified-Data-Analyst-Associate認定デベロッパー - 合格スムーズDatabricks-Certified-Data-Analyst-Associate難易度 | ユニークなDatabricks-Certified-Data-Analyst-Associate受験記対策 🎾 ➤ www.xhs1991.com ⮘サイトにて▛ Databricks-Certified-Data-Analyst-Associate ▟問題集を無料で使おうDatabricks-Certified-Data-Analyst-Associate出題内容
- 試験の準備方法-100%合格率のDatabricks-Certified-Data-Analyst-Associate認定デベロッパー試験-有難いDatabricks-Certified-Data-Analyst-Associate難易度 🏁 ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️を無料でダウンロード✔ www.goshiken.com ️✔️ウェブサイトを入力するだけDatabricks-Certified-Data-Analyst-Associate資格取得講座
- Databricks-Certified-Data-Analyst-Associate問題集 👍 Databricks-Certified-Data-Analyst-Associate問題無料 👽 Databricks-Certified-Data-Analyst-Associate資格取得講座 🐜 ▶ Databricks-Certified-Data-Analyst-Associate ◀を無料でダウンロード( www.xhs1991.com )ウェブサイトを入力するだけDatabricks-Certified-Data-Analyst-Associate資格取得講座
- 試験の準備方法-100%合格率のDatabricks-Certified-Data-Analyst-Associate認定デベロッパー試験-有難いDatabricks-Certified-Data-Analyst-Associate難易度 🤠 サイト➠ www.goshiken.com 🠰で[ Databricks-Certified-Data-Analyst-Associate ]問題集をダウンロードDatabricks-Certified-Data-Analyst-Associate日本語問題集
- Databricks-Certified-Data-Analyst-Associate復習時間 🤬 Databricks-Certified-Data-Analyst-Associate試験概要 🚰 Databricks-Certified-Data-Analyst-Associateテスト問題集 📃 { www.passtest.jp }を開き、⏩ Databricks-Certified-Data-Analyst-Associate ⏪を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associate復習時間
- Databricks-Certified-Data-Analyst-Associate出題内容 🚪 Databricks-Certified-Data-Analyst-Associate練習問題 ↩ Databricks-Certified-Data-Analyst-Associate関連日本語版問題集 😤 [ www.goshiken.com ]サイトにて最新⇛ Databricks-Certified-Data-Analyst-Associate ⇚問題集をダウンロードDatabricks-Certified-Data-Analyst-Associate問題無料
- 完璧なDatabricks-Certified-Data-Analyst-Associate認定デベロッパー - 資格試験におけるリーダーオファー - 有用なDatabricks-Certified-Data-Analyst-Associate難易度 🍛 ▛ www.passtest.jp ▟に移動し、⇛ Databricks-Certified-Data-Analyst-Associate ⇚を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associateテスト問題集
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, me.muz.li, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. JPNTestがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Data-Analyst-Associateダンプ:https://drive.google.com/open?id=1Hq81fan0e526AU97xGX46HWlbeceFpKI