BTW, DOWNLOAD part of Exam-Killer DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1jdlpFvoOVXmAsUq2CcwFrE20GXJMdQK6
We aim to provide the best service for our customers, and we demand our after sale service staffs to the highest ethical standard, and our DP-100 study guide and compiling processes will be of the highest quality. We play an active role in making every country and community in which we selling our DP-100 practice test a better place to live and work. Therefore, our responsible after sale service staffs are available in twenty four hours a day, seven days a week. That is to say, if you have any problem after DP-100 Exam Materials purchasing, you can contact our after sale service staffs anywhere at any time.
| Section | Weight | Objectives |
|---|---|---|
| Explore data and run experiments | 20-25% | - Implement pipelines
|
| Design and prepare a machine learning solution | 20-25% | - Manage data assets
|
| Train and deploy models | 25-30% | - Monitor and maintain models
|
| Optimize language models for AI applications | 25-30% | - Implement generative AI solutions
|
Many people prefer to buy our DP-100 valid study guide materials because they deeply believe that if only they buy them can definitely pass the test. The reason why they like our DP-100 guide questions is that our study materials' quality is very high. For years we always devote ourselves to perfecting our DP-100 Study Materials. We boost the leading research team and the top-ranking sale service. We boost the expert team to specialize in the research and production of the DP-100 guide questions and professional personnel to be responsible for the update of the DP-100 study materials.
NEW QUESTION # 226
Hotspot Question
You are tuning a hyperparameter for an algorithm.
The following table shows a data set with different hyperparameter, training error, and validation errors.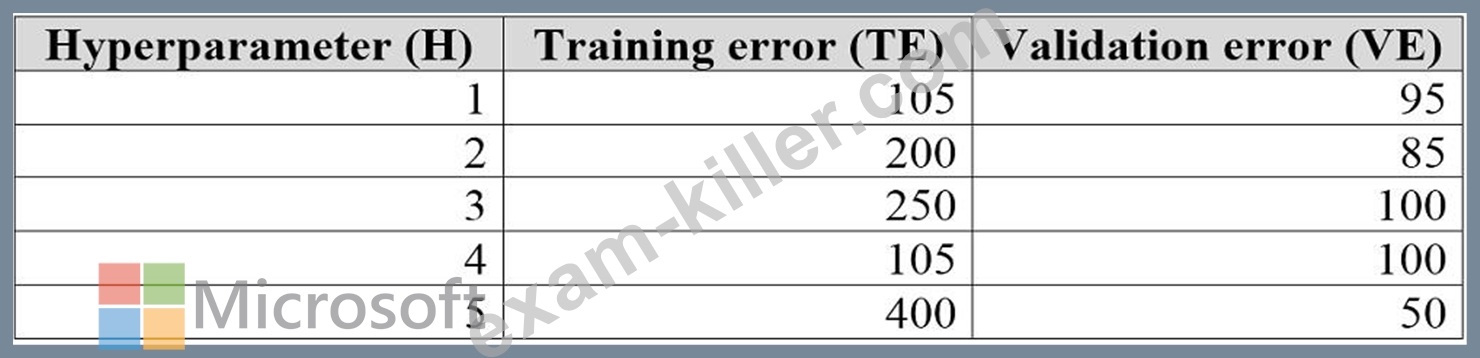
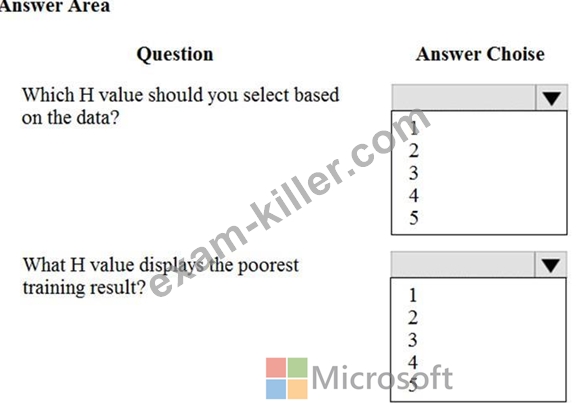
Answer:
Explanation: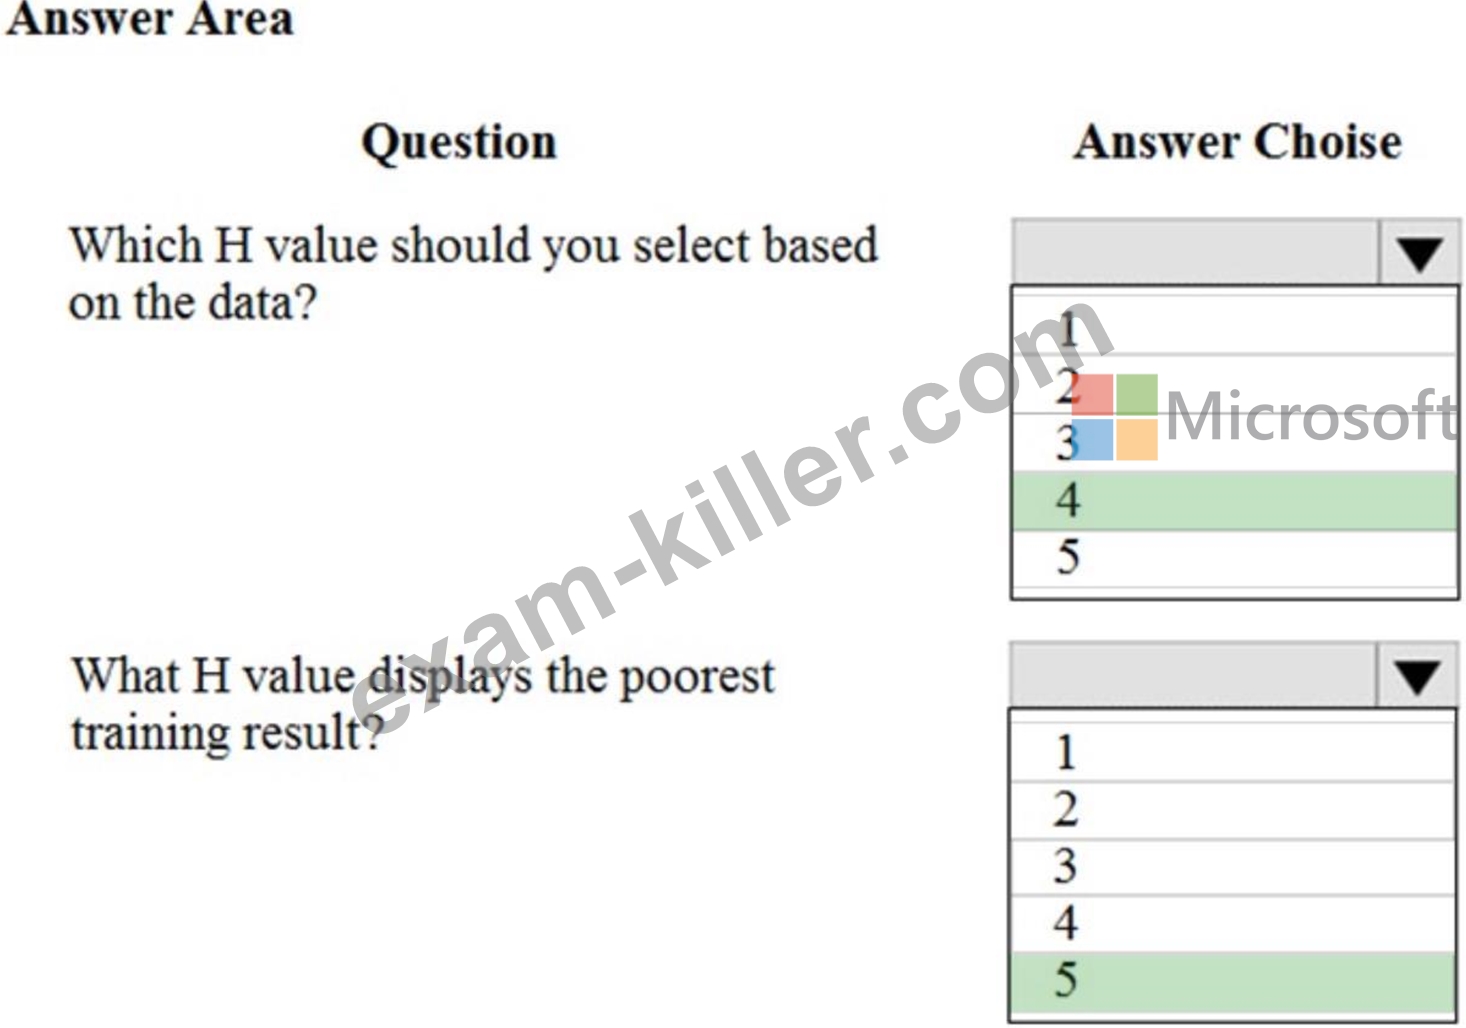
Explanation:
Box 1: 4
Choose the one which has lower training and validation error and also the closest match.
Minimize variance (difference between validation error and train error).
Box 2: 5
Minimize variance (difference between validation error and train error).
Reference:
https://medium.com/comet-ml/organizing-machine-learning-projects-project-management- guidelines-2d2b85651bbd
NEW QUESTION # 227
You use the Azure Machine Learning SDK to run a training experiment that trains a classification model and calculates its accuracy metric.
The model will be retrained each month as new data is available.
You must register the model for use in a batch inference pipeline.
You need to register the model and ensure that the models created by subsequent retraining experiments are registered only if their accuracy is higher than the currently registered model.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
NEW QUESTION # 228
You need to select an environment that will meet the business and data requirements.
Which environment should you use?
Answer: D
Explanation:
Topic 1, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1
+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: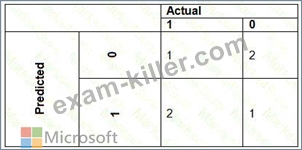
The ad propensity model uses proposed cost factors shown in the following diagram: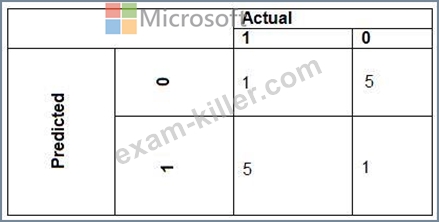
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: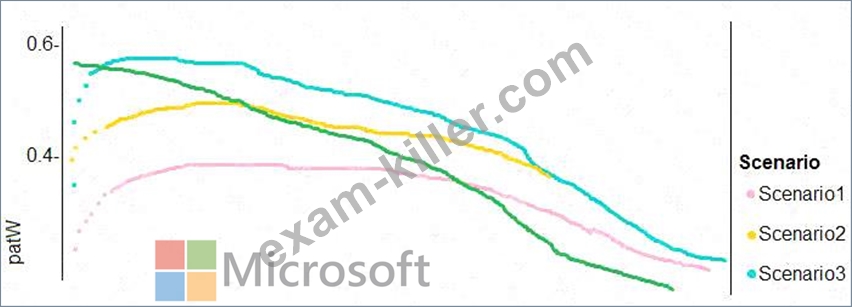
Penalty detection and sentiment
Findings
*Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
*Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
*Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
*Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
*Global penalty detection models must be trained by using dynamic runtime graph computation during training.
*Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
*Ad response rates declined.
*Drops were not consistent across ad styles.
*The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
*Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
*All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
*Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
*The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
NEW QUESTION # 229
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create a model to forecast weather conditions based on historical data.
You need to create a pipeline that runs a processing script to load data from a datastore and pass the processed data to a machine learning model training script.
Solution: Run the following code: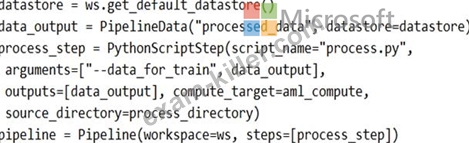
Does the solution meet the goal?
Answer: B
Explanation:
Explanation
train_step is missing.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.pipelinedata?view=azu
NEW QUESTION # 230
You need to implement a scaling strategy for the local penalty detection data.
Which normalization type should you use?
Answer: D
Explanation:
Post batch normalization statistics (PBN) is the Microsoft Cognitive Toolkit (CNTK) version of how to evaluate the population mean and variance of Batch Normalization which could be used in inference Original Paper.
In CNTK, custom networks are defined using the BrainScriptNetworkBuilder and described in the CNTK network description language "BrainScript." Scenario:
Local penalty detection models must be written by using BrainScript.
Reference:
https://docs.microsoft.com/en-us/cognitive-toolkit/post-batch-normalization-statistics
NEW QUESTION # 231
......
The pass rate for DP-100 training materials is 98.95%, and you can pass and get the certificate successfully if you buy DP-100 training materials from us. Besides, we have experienced experts to compile and verify DP-100 training materials, therefore quality and accuracy can be guaranteed. We are pass guarantee and money back guarantee if you buy DP-100 Exam Dumps from us. We provide you with free update for one year for the DP-100 training materials, so that you can know the latest information about the exam.
DP-100 Test Dates: https://www.exam-killer.com/DP-100-valid-questions.html
What's more, part of that Exam-Killer DP-100 dumps now are free: https://drive.google.com/open?id=1jdlpFvoOVXmAsUq2CcwFrE20GXJMdQK6