Reliable Certified-Data-Engineer-Professional Practice Questions | Certified-Data-Engineer-Professional New Study Plan

The very reason for this selection of DumpsQuestion Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions is that they are real and updated. DumpsQuestion guarantees you that you will pass your Databricks Certified-Data-Engineer-Professional exam of Databricks certification on the very first try. DumpsQuestion provides its valuable users a free Certified-Data-Engineer-Professional Pdf Dumps demo test before buying the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification preparation material so they may be fully familiar with the quality of the product.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Compare streaming tables and materialized views
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Configure environments, dependencies, memory, and retry behavior
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 8. Use control flow operators in pipeline components
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
>> Reliable Certified-Data-Engineer-Professional Practice Questions <<
Reliable Certified-Data-Engineer-Professional Practice Questions|Legal for Databricks Certified Data Engineer Professional
DumpsQuestion is a website to achieve dreams of many IT people. DumpsQuestion provide candidates participating in the IT certification exams the information they want to help them pass the exam. Do you still worry about passing Databricks certification Certified-Data-Engineer-Professional exam? Have you thought about purchasing an Databricks certification Certified-Data-Engineer-Professional exam counseling sessions to assist you? DumpsQuestion can provide you with this convenience. DumpsQuestion's training materials can help you pass the certification exam. DumpsQuestion's exercises are almost similar to real exams. With DumpsQuestion's accurate Databricks Certification Certified-Data-Engineer-Professional Exam practice questions and answers, you can pass Databricks certification Certified-Data-Engineer-Professional exam with a high score.
Databricks Certified Data Engineer Professional Sample Questions (Q86-Q91):
NEW QUESTION # 86
A view is registered with the following code:
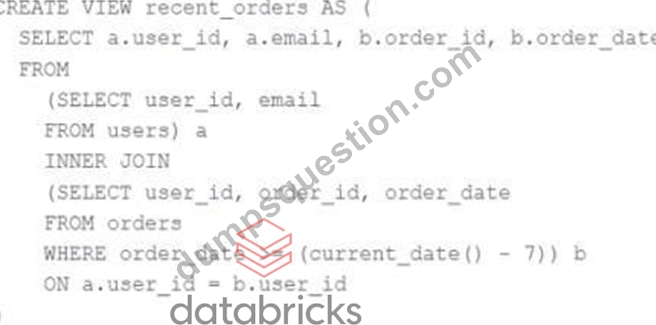
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- C. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- D. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
Answer: B
NEW QUESTION # 87
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
- B. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
- C. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- D. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
Answer: B
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
NEW QUESTION # 88
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
- A. Load batch data with notebooks and ingest streaming data with SQL Warehouses; use Unity Catalog column masks on Silver tables to redact fields after storage.
- B. Allow PII to be stored unmasked in Bronze for lineage tracking, then apply masking logic in Gold tables used for reporting.
- C. Use Lakeflow Declarative Pipelines for batch and streaming ingestion, define a PII masking function, and apply it during Bronze ingestion before writing to Delta Lake.
- D. Ingest both batch and streaming data using Lakeflow Declarative Pipelines, and apply masking via Unity Catalog column masks at read time to avoid modifying the data during ingestion.
Answer: C
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 89
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
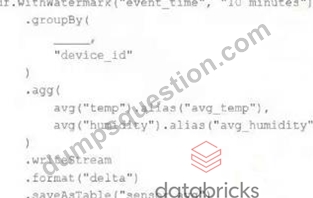
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. to_interval("event_time", "5 minutes").alias("time")
- B. lag("event_time", "10 minutes").alias("time")
- C. window("event_time", "5 minutes").alias("time")
- D. "event_time"
- E. window("event_time", "10 minutes").alias("time")
Answer: C
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 90
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- B. Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
- C. Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
- D. Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
Answer: B
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 91
......
These Databricks Certified-Data-Engineer-Professional exam questions have a high chance of coming in the actual Certified-Data-Engineer-Professional test. You have to memorize these Certified-Data-Engineer-Professional questions and you will pass the Databricks Certified-Data-Engineer-Professional test with brilliant results. The price of Databricks Certified-Data-Engineer-Professional updated exam dumps is affordable.
Certified-Data-Engineer-Professional New Study Plan: https://www.dumpsquestion.com/Certified-Data-Engineer-Professional-exam-dumps-collection.html
- Quiz Databricks - Certified-Data-Engineer-Professional - Perfect Reliable Databricks Certified Data Engineer Professional Practice Questions 📐 Search for ▷ Certified-Data-Engineer-Professional ◁ and download it for free on 【 www.exam4labs.com 】 website 🕊Certified-Data-Engineer-Professional Reliable Exam Review
- Real Certified-Data-Engineer-Professional Questions 🌕 Study Certified-Data-Engineer-Professional Tool 💺 Certified-Data-Engineer-Professional Exam Dumps Demo 📎 Go to website ➤ www.pdfvce.com ⮘ open and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 👄Certified-Data-Engineer-Professional Sample Questions
- Latest Certified-Data-Engineer-Professional Practice Exam Guide Materials: Databricks Certified Data Engineer Professional - www.practicevce.com 🦩 Search on ⏩ www.practicevce.com ⏪ for 「 Certified-Data-Engineer-Professional 」 to obtain exam materials for free download ➖Valid Certified-Data-Engineer-Professional Exam Duration
- Latest Certified-Data-Engineer-Professional Test Cram ◀ Certified-Data-Engineer-Professional Exam Questions Answers 💏 Certified-Data-Engineer-Professional Test Preparation 😸 Easily obtain free download of 【 Certified-Data-Engineer-Professional 】 by searching on ☀ www.pdfvce.com ️☀️ 🔵Certified-Data-Engineer-Professional Sample Questions
- Databricks Certified-Data-Engineer-Professional Exam Questions Updates Are Free For one year 🛸 Easily obtain free download of ⏩ Certified-Data-Engineer-Professional ⏪ by searching on [ www.pdfdumps.com ] 🖼Certified-Data-Engineer-Professional Questions Answers
- Valid Certified-Data-Engineer-Professional Exam Duration ⬇ Certified-Data-Engineer-Professional Exam Questions Answers 👇 Certified-Data-Engineer-Professional Questions Answers 💻 Search on ✔ www.pdfvce.com ️✔️ for ( Certified-Data-Engineer-Professional ) to obtain exam materials for free download 🍢Certified-Data-Engineer-Professional Valid Exam Preparation
- Free Download Reliable Certified-Data-Engineer-Professional Practice Questions - Pass Certified-Data-Engineer-Professional in One Time - Perfect Certified-Data-Engineer-Professional New Study Plan ♣ Open ▛ www.verifieddumps.com ▟ and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free 💌Latest Certified-Data-Engineer-Professional Braindumps Questions
- Databricks Reliable Certified-Data-Engineer-Professional Practice Questions: Databricks Certified Data Engineer Professional - Pdfvce High Pass Rate 🏵 Immediately open “ www.pdfvce.com ” and search for ➥ Certified-Data-Engineer-Professional 🡄 to obtain a free download 🥟Certified-Data-Engineer-Professional Reliable Exam Review
- Databricks Reliable Certified-Data-Engineer-Professional Practice Questions: Databricks Certified Data Engineer Professional - www.examcollectionpass.com High Pass Rate 🔒 Easily obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download through ➽ www.examcollectionpass.com 🢪 🧪Dumps Certified-Data-Engineer-Professional Torrent
- Valid Certified-Data-Engineer-Professional Exam Duration 🍭 Certified-Data-Engineer-Professional Exam Dumps Demo 🛒 Certified-Data-Engineer-Professional Latest Guide Files 🧵 Enter ☀ www.pdfvce.com ️☀️ and search for 「 Certified-Data-Engineer-Professional 」 to download for free 👆Certified-Data-Engineer-Professional Exam Dumps Demo
- Certified-Data-Engineer-Professional Reliable Exam Review 🧖 Certified-Data-Engineer-Professional Practical Information 😂 Dumps Certified-Data-Engineer-Professional Torrent 👍 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply entering ( www.testkingpass.com ) website 🧮Valid Certified-Data-Engineer-Professional Exam Duration
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.4shared.com, Disposable vapes