P.S.JPTestKingがGoogle Driveで共有している無料の2026 Appian ACD-301ダンプ:https://drive.google.com/open?id=19lkypeDlo5QcrwRRT0ggq7Do0Um7_kQ5
JPTestKingを通じて最新のAppianのACD-301試験の問題と解答早めにを持てて、弊社の問題集があればきっと君の強い力になります。
| Section | Objectives |
|---|---|
| Process Modeling | - Exception handling and optimization - Advanced process model design |
| Security and Deployment | - Security roles and group management - Deployment pipelines and environment management |
| Application Design and Architecture | - Solution structuring and application layering - Reusable components and design patterns |
| Expression Language and Logic | - Rule design and optimization - Advanced Appian expression functions |
| User Interface Design | - User experience best practices - Interface design and dynamic layouts |
| Data Management | - Data types and CDT structures - Record types and data stores |
目の前の本当の困難に挑戦するために、君のもっと質の良いAppianのACD-301問題集を提供するために、私たちはJPTestKingのITエリートチームの変動からAppianのACD-301問題集の更新まで、完璧になるまでにずっと頑張ります。私たちはあなたが簡単にAppianのACD-301認定試験に合格するができるという目標のために努力しています。あなたはうちのAppianのACD-301問題集を購入する前に、一部分のフリーな試験問題と解答をダンロードして、試用してみることができます。
質問 # 11
You are required to create an integration from your Appian Cloud instance to an application hosted within a customer's self-managed environment.
The customer's IT team has provided you with a REST API endpoint to test with: https://internal.network/api/api/ping.
Which recommendation should you make to progress this integration?
正解:A
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, integrating an Appian Cloud instance with a customer's self-managed (on-premises) environment requires addressing network connectivity, security, and Appian's cloud architecture constraints. The provided endpoint (https://internal.network/api/api/ping) is a REST API on an internal network, inaccessible directly from Appian Cloud due to firewall restrictions and lack of public exposure. Let's evaluate each option:
A . Expose the API as a SOAP-based web service:
Converting the REST API to SOAP isn't a practical recommendation. The customer has provided a REST endpoint, and Appian fully supports REST integrations via Connected Systems and Integration objects. Changing the API to SOAP adds unnecessary complexity, development effort, and risks for the customer, with no benefit to Appian's integration capabilities. Appian's documentation emphasizes using the API's native format (REST here), making this irrelevant.
B . Deploy the API/service into Appian Cloud:
Deploying the customer's API into Appian Cloud is infeasible. Appian Cloud is a managed PaaS environment, not designed to host customer applications or APIs. The API resides in the customer's self-managed environment, and moving it would require significant architectural changes, violating security and operational boundaries. Appian's integration strategy focuses on connecting to external systems, not hosting them, ruling this out.
C . Add Appian Cloud's IP address ranges to the customer network's allowed IP listing:
This approach involves whitelisting Appian Cloud's IP ranges (available in Appian documentation) in the customer's firewall to allow direct HTTP/HTTPS requests. However, Appian Cloud's IPs are dynamic and shared across tenants, making this unreliable for long-term integrations-changes in IP ranges could break connectivity. Appian's best practices discourage relying on IP whitelisting for cloud-to-on-premises integrations due to this limitation, favoring secure tunnels instead.
D . Set up a VPN tunnel:
This is the correct recommendation. A Virtual Private Network (VPN) tunnel establishes a secure, encrypted connection between Appian Cloud and the customer's self-managed network, allowing Appian to access the internal REST API (https://internal.network/api/api/ping). Appian supports VPNs for cloud-to-on-premises integrations, and this approach ensures reliability, security, and compliance with network policies. The customer's IT team can configure the VPN, and Appian's documentation recommends this for such scenarios, especially when dealing with internal endpoints.
Conclusion: Setting up a VPN tunnel (D) is the best recommendation. It enables secure, reliable connectivity from Appian Cloud to the customer's internal API, aligning with Appian's integration best practices for cloud-to-on-premises scenarios.
Appian Documentation: "Integrating Appian Cloud with On-Premises Systems" (VPN and Network Configuration).
Appian Lead Developer Certification: Integration Module (Cloud-to-On-Premises Connectivity).
Appian Best Practices: "Securing Integrations with Legacy Systems" (VPN Recommendations).
質問 # 12
An existing integration is implemented in Appian. Its role is to send data for the main case and its related objects in a complex JSON to a REST API, to insert new information into an existing application. This integration was working well for a while. However, the customer highlighted one specific scenario where the integration failed in Production, and the API responded with a 500 Internal Error code. The project is in Post-Production Maintenance, and the customer needs your assistance. Which three steps should you take to troubleshoot the issue?
正解:A、C、E
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer in a Post-Production Maintenance phase, troubleshooting a failed integration (HTTP 500 Internal Server Error) requires a systematic approach to isolate the root cause-whether it's Appian-side, API-side, or environmental. A 500 error typically indicates an issue on the server (API) side, but the developer must confirm Appian's contribution and collaborate with the customer. The goal is to select three steps that efficiently diagnose the specific scenario while adhering to Appian's best practices. Let's evaluate each option:
A . Send the same payload to the test API to ensure the issue is not related to the API environment:
This is a critical step. Replicating the failure by sending the exact payload (from the failed Production call) to a test API environment helps determine if the issue is environment-specific (e.g., Production-only configuration) or inherent to the payload/API logic. Appian's Integration troubleshooting guidelines recommend testing in a non-Production environment first to isolate variables. If the test API succeeds, the Production environment or API state is implicated; if it fails, the payload or API logic is suspect. This step leverages Appian's Integration object logging (e.g., request/response capture) and is a standard diagnostic practice.
B . Send a test case to the Production API to ensure the service is still up and running:
While verifying Production API availability is useful, sending an arbitrary test case risks further Production disruption during maintenance and may not replicate the specific scenario. A generic test might succeed (e.g., with simpler data), masking the issue tied to the complex JSON. Appian's Post-Production guidelines discourage unnecessary Production interactions unless replicating the exact failure is controlled and justified. This step is less precise than analyzing existing behavior (C) and is not among the top three priorities.
C . Analyze the behavior of subsequent calls to the Production API to ensure there is no global issue, and ask the customer to analyze the API logs to understand the nature of the issue:
This is essential. Reviewing subsequent Production calls (via Appian's Integration logs or monitoring tools) checks if the 500 error is isolated or systemic (e.g., API outage). Since Appian can't access API server logs, collaborating with the customer to review their logs is critical for a 500 error, which often stems from server-side exceptions (e.g., unhandled data). Appian Lead Developer training emphasizes partnership with API owners and using Appian's Process History or Application Monitoring to correlate failures-making this a key troubleshooting step.
D . Obtain the JSON sent to the API and validate that there is no difference between the expected JSON format and the sent one:
This is a foundational step. The complex JSON payload is central to the integration, and a 500 error could result from malformed data (e.g., missing fields, invalid types) that the API can't process. In Appian, you can retrieve the sent JSON from the Integration object's execution logs (if enabled) or Process Instance details. Comparing it against the API's documented schema (e.g., via Postman or API specs) ensures Appian's output aligns with expectations. Appian's documentation stresses validating payloads as a first-line check for integration failures, especially in specific scenarios.
E . Ensure there were no network issues when the integration was sent:
While network issues (e.g., timeouts, DNS failures) can cause integration errors, a 500 Internal Server Error indicates the request reached the API and triggered a server-side failure-not a network issue (which typically yields 503 or timeout errors). Appian's Connected System logs can confirm HTTP status codes, and network checks (e.g., via IT teams) are secondary unless connectivity is suspected. This step is less relevant to the 500 error and lower priority than A, C, and D.
Conclusion: The three best steps are A (test API with same payload), C (analyze subsequent calls and customer logs), and D (validate JSON payload). These steps systematically isolate the issue-testing Appian's output (D), ruling out environment-specific problems (A), and leveraging customer insights into the API failure (C). This aligns with Appian's Post-Production Maintenance strategies: replicate safely, analyze logs, and validate data.
Appian Documentation: "Troubleshooting Integrations" (Integration Object Logging and Debugging).
Appian Lead Developer Certification: Integration Module (Post-Production Troubleshooting).
Appian Best Practices: "Handling REST API Errors in Appian" (500 Error Diagnostics).
質問 # 13
You are required to configure a connection so that Jira can inform Appian when specific tickets change (using a webhook). Which three required steps will allow you to connect both systems?
正解:A、B、C
解説:
Comprehensive and Detailed In-Depth Explanation:
Configuring a webhook connection from Jira to Appian requires setting up a mechanism for Jira to push ticket change notifications to Appian in real-time. This involves creating an endpoint in Appian to receive the webhook and configuring Jira to send the data. Appian's Integration Best Practices and Web API documentation provide the framework for this process.
Option A (Create a Web API object and set up the correct security):
This is a required step. In Appian, a Web API object serves as the endpoint to receive incoming webhook requests from Jira. You must define the API structure (e.g., HTTP method, input parameters) and configure security (e.g., basic authentication, API key, or OAuth) to validate incoming requests. Appian recommends using a service account with appropriate permissions to ensure secure access, aligning with the need for a controlled webhook receiver.
Option B (Configure the connection in Jira specifying the URL and credentials):
This is essential. In Jira, you need to set up a webhook by providing the Appian Web API's URL (e.g., https://<appian-site>/suite/webapi/<web-api-name>) and the credentials or authentication method (e.g., API key or basic auth) that match the security setup in Appian. This ensures Jira can successfully send ticket change events to Appian.
Option C (Create a new API Key and associate a service account):
This is necessary for secure authentication. Appian recommends using an API key tied to a service account for webhook integrations. The service account should have permissions to process the incoming data (e.g., write to a process or data store) but not excessive privileges. This step complements the Web API security setup and Jira configuration.
Option D (Give the service account system administrator privileges):
This is unnecessary and insecure. System administrator privileges grant broad access, which is overkill for a webhook integration. Appian's security best practices advocate for least-privilege principles, limiting the service account to the specific objects or actions needed (e.g., executing the Web API).
Option E (Create an integration object from Appian to Jira to periodically check the ticket status):
This is incorrect for a webhook scenario. Webhooks are push-based, where Jira notifies Appian of changes. Creating an integration object for periodic polling (pull-based) is a different approach and not required for the stated requirement of Jira informing Appian via webhook.
These three steps (A, B, C) establish a secure, functional webhook connection without introducing unnecessary complexity or security risks.
The three required steps that will allow you to connect both systems are:
A . Create a Web API object and set up the correct security. This will allow you to define an endpoint in Appian that can receive requests from Jira via webhook. You will also need to configure the security settings for the Web API object, such as authentication method, allowed origins, and access control.
B . Configure the connection in Jira specifying the URL and credentials. This will allow you to set up a webhook in Jira that can send requests to Appian when specific tickets change. You will need to specify the URL of the Web API object in Appian, as well as any credentials required for authentication.
C . Create a new API Key and associate a service account. This will allow you to generate a unique token that can be used for authentication between Jira and Appian. You will also need to create a service account in Appian that has permissions to access or update data related to Jira tickets.
The other options are incorrect for the following reasons:
D . Give the service account system administrator privileges. This is not required and could pose a security risk, as giving system administrator privileges to a service account could allow it to perform actions that are not related to Jira tickets, such as modifying system settings or accessing sensitive data.
E . Create an integration object from Appian to Jira to periodically check the ticket status. This is not required and could cause unnecessary overhead, as creating an integration object from Appian to Jira would involve polling Jira for ticket status changes, which could consume more resources than using webhook notifications. Verified Appian Documentation, section "Web API" and "API Keys".
質問 # 14
As part of your implementation workflow, users need to retrieve data stored in a third-party Oracle database on an interface. You need to design a way to query this information.
How should you set up this connection and query the data?
正解:A
解説:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a solution to query data from a third-party Oracle database for display on an interface requires secure, efficient, and maintainable integration. The scenario focuses on real-time retrieval for users, so the design must leverage Appian's data connectivity features. Let's evaluate each option:
A . Configure a Query Database node within the process model. Then, type in the connection information, as well as a SQL query to execute and return the data in process variables:
The Query Database node (part of the Smart Services) allows direct SQL execution against a database, but it requires manual connection details (e.g., JDBC URL, credentials), which isn't scalable or secure for Production. Appian's documentation discourages using Query Database for ongoing integrations due to maintenance overhead, security risks (e.g., hardcoding credentials), and lack of governance. This is better for one-off tasks, not real-time interface queries, making it unsuitable.
B . Configure a timed utility process that queries data from the third-party database daily, and stores it in the Appian business database. Then use a!queryEntity using the Appian data source to retrieve the data:
This approach syncs data daily into Appian's business database (e.g., via a timer event and Query Database node), then queries it with a!queryEntity. While it works for stale data, it introduces latency (up to 24 hours) for users, which doesn't meet real-time needs on an interface. Appian's best practices recommend direct data source connections for up-to-date data, not periodic caching, unless latency is acceptable-making this inefficient here.
C . Configure an expression-backed record type, calling an API to retrieve the data from the third-party database. Then, use a!queryRecordType to retrieve the data:
Expression-backed record types use expressions (e.g., a!httpQuery()) to fetch data, but they're designed for external APIs, not direct database queries. The scenario specifies an Oracle database, not an API, so this requires building a custom REST service on the Oracle side, adding complexity and latency. Appian's documentation favors Data Sources for database queries over API calls when direct access is available, making this less optimal and over-engineered.
D . In the Administration Console, configure the third-party database as a "New Data Source." Then, use a!queryEntity to retrieve the data:
This is the best choice. In the Appian Administration Console, you can configure a JDBC Data Source for the Oracle database, providing connection details (e.g., URL, driver, credentials). This creates a secure, managed connection for querying via a!queryEntity, which is Appian's standard function for Data Store Entities. Users can then retrieve data on interfaces using expression-backed records or queries, ensuring real-time access with minimal latency. Appian's documentation recommends Data Sources for database integrations, offering scalability, security, and governance-perfect for this requirement.
Conclusion: Configuring the third-party database as a New Data Source and using a!queryEntity (D) is the recommended approach. It provides direct, real-time access to Oracle data for interface display, leveraging Appian's native data connectivity features and aligning with Lead Developer best practices for third-party database integration.
Appian Documentation: "Configuring Data Sources" (JDBC Connections and a!queryEntity).
Appian Lead Developer Certification: Data Integration Module (Database Query Design).
Appian Best Practices: "Retrieving External Data in Interfaces" (Data Source vs. API Approaches).
質問 # 15
You are on a protect with an application that has been deployed to Production and is live with users. The client wishes to increase the number of active users.
You need to conduct load testing to ensure Production can handle the increased usage Review the specs for four environments in the following image.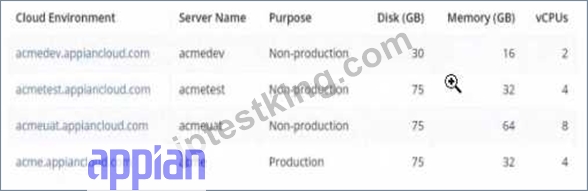
Which environment should you use for load testing7
正解:D
解説:
The image provides the specifications for four environments in the Appian Cloud:
acmedev.appiancloud.com (acmedev): Non-production, Disk: 30 GB, Memory: 16 GB, vCPUs: 2 acmetest.appiancloud.com (acmetest): Non-production, Disk: 75 GB, Memory: 32 GB, vCPUs: 4 acmeuat.appiancloud.com (acmeuat): Non-production, Disk: 75 GB, Memory: 64 GB, vCPUs: 8 acme.appiancloud.com (acme): Production, Disk: 75 GB, Memory: 32 GB, vCPUs: 4 Load testing assesses an application's performance under increased user load to ensure scalability and stability. Appian's Performance Testing Guidelines emphasize using an environment that mirrors Production as closely as possible to obtain accurate results, while avoiding direct impact on live systems.
Option A (acmeuat):This is the best choice. The UAT (User Acceptance Testing) environment (acmeuat) has the highest resources (64 GB memory, 8 vCPUs) among the non-production environments, closely aligning with Production's capabilities (32 GB memory, 4 vCPUs) but with greater capacity to handle simulated loads. UAT environments are designed to validate the application with real-world usage scenarios, making them ideal for load testing. The higher resources also allow testing beyond current Production limits to predict future scalability, meeting the client's goal of increasing active users without risking live data.
Option B (acmedev):The development environment (acmedev) has the lowest resources (16 GB memory, 2 vCPUs), which is insufficient for load testing. It's optimized for development, not performance simulation, and results would not reflect Production behavior accurately.
Option C (acme):The Production environment (acme) is live with users, and load testing here would disrupt service, violate Appian's Production Safety Guidelines, and risk data integrity. It should never be used for testing.
Option D (acmetest):The test environment (acmetest) has moderate resources (32 GB memory, 4 vCPUs), matching Production's memory and vCPUs. However, it's typically used for SIT (System Integration Testing) and has less capacity than acmeuat. While viable, it's less ideal than acmeuat for simulating higher user loads due to its resource constraints.
Appian recommends using a UAT environment for load testing when it closely mirrors Production and can handle simulated traffic, making acmeuat the optimal choice given its superior resources and non-production status.
質問 # 16
......
ACD-301 Appian Certified Lead Developerは、技術的な精度の最高水準を高め、認定された主題と専門家のみを使用します。最新の正確なACD-301試験トレントをクライアントに提供し、提供する質問と回答は実際の試験に基づいています。合格率が高く、約98%-100%であることをお約束します。また、ACD-301テストブレインダンプは高いヒット率を高め、試験を刺激してACD-301試験の準備を整えることができます。あなたの成功は、ACD-301試験問題に縛られています。
ACD-301日本語対策問題集: https://www.jptestking.com/ACD-301-exam.html
P.S. JPTestKingがGoogle Driveで共有している無料かつ新しいACD-301ダンプ:https://drive.google.com/open?id=19lkypeDlo5QcrwRRT0ggq7Do0Um7_kQ5