What's more, part of that VCEPrep DP-600 dumps now are free: https://drive.google.com/open?id=1GtxyjCo4xdZDjnD2LNQl-SSnoHP5oVpL
Everyone has their own life planning. Different selects will have different acquisition. So the choice is important. VCEPrep's Microsoft DP-600 Exam Training materials are the best things to help each IT worker to achieve the ambitious goal of his life. It includes questions and answers, and issimilar with the real exam questions. This really can be called the best training materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-600 Positive Feedback <<
We provide you with two kinds of consulting channels if you are confused about some questions on our DP-600 study materials. You can email us or contact our online customer service. We will reply you as soon as possible. You are free to ask questions about DP-600 training prep at any time since that we are working 24/7 online. Our staff is really very patient and friendly. They are waiting to give you the most professional suggestions on our DP-600 exam questions.
NEW QUESTION # 210
What should you use to implement calculation groups for the Research division semantic models?
Answer: D
Explanation:
Topic 1, Contoso, ltd.
Overview
Contoso, ltd. is a US-based health supplements company, Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroupi and ReseachReviewefsGfoup2.
Data Environment
Contoso has the following data environment
* The Sales division uses a Microsoft Power B1 Premium capacity.
* The semantic model of the Online Sales department includes a fact table named Orders that uses import mode. In the system of origin, the OrderlD value represents the sequence in which orders are created.
* The Research department uses an on-premises. third-party data warehousing product.
* Fabric is enabled for contoso.com.
* An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Producthne1. The data is in the delta format.
* A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Planned Changes
Contoso plans to make the following changes:
* Enable support for Fabric in the Power Bl Premium capacity used by the Sales division.
* Make all the data for the Sales division and the Research division available in Fabric.
* For the Research division, create two Fabric workspaces named Producttmelws and Productline2ws.
* in Productlinelws. create a lakehouse named LakehouseV
* In Lakehouse1. create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
* All the workspaces for the Sales division and the Research division must support all Fabric experiences.
* The Research division workspaces must use a dedicated, on-demand capacity that has per-minute billing.
* The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
* For the Research division workspaces, the members of ResearchRevtewersGroupl must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
* For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
* All the semantic models and reports for the Research division must use version control that supports branching Data Preparation Requirements Contoso identifies the following data preparation requirements:
* The Research division data for Producthne2 must be retrieved from Lakehouset by using Fabric notebooks.
* All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models;
* The number of rows added to the Orders table during refreshes must be minimized.
* The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
* Follow the principle of least privilege when applicable
* Minimize implementation and maintenance effort when possible.
NEW QUESTION # 211
Drag and Drop Question
You are creating a data flow in Fabric to ingest data from an Azure SQL database by using a T- SQL statement.
You need to ensure that any foldable Power Query transformation steps are processed by the Microsoft SQL Server engine.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.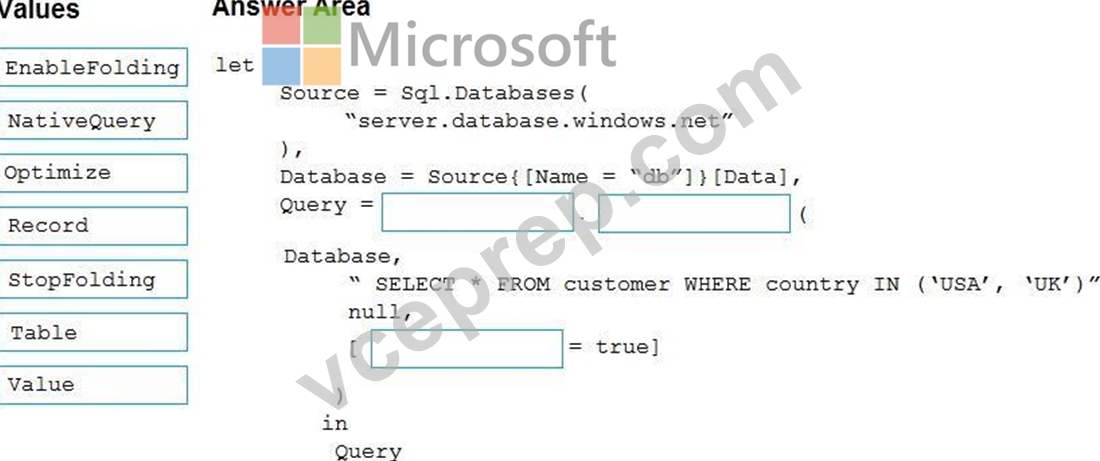
Answer:
Explanation: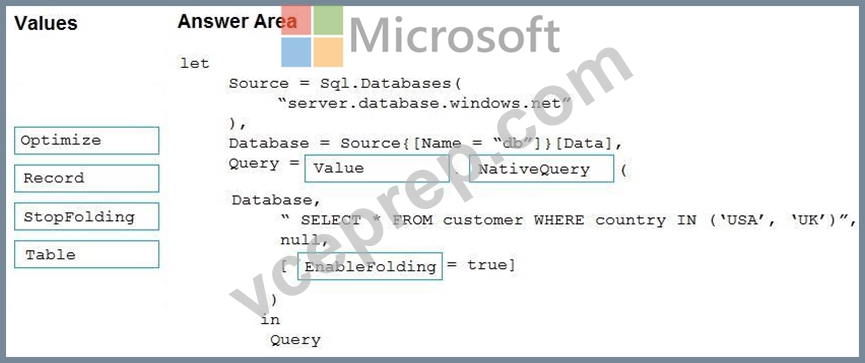
Explanation:
https://learn.microsoft.com/en-us/power-query/native-query-folding
NEW QUESTION # 212
You have a Fabric tenant that contains the workspaces shown in the following table.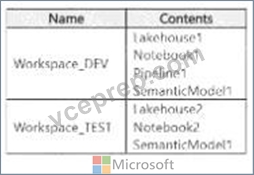
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
Answer: C
NEW QUESTION # 213
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals.
More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
Your network contains an on-premises Active Directory Domain Services (AD DS) domain named contoso.
com that syncs with a Microsoft Entra tenant by using Microsoft Entra Connect.
You have a Fabric tenant that contains a semantic model.
You enable dynamic row-level security (RLS) for the model and deploy the model to the Fabric service.
You query a measure that includes the username () function, and the query returns a blank result.
You need to ensure that the measure returns the user principal name (UPN) of a user.
Solution: You update the measure to use the USEROBJECT () function.
Does this meet the goal?
Answer: B
Explanation:
There is no USEROBJECT() function in DAX. The correct functions available are USERNAME() and USERPRINCIPALNAME().
USERPRINCIPALNAME() is the one that returns the UPN directly.
Since the solution refers to a non-existent function (USEROBJECT()), it cannot solve the problem.
Correct approach: Update the measure to use USERPRINCIPALNAME(), not USEROBJECT().
NEW QUESTION # 214
You have a Microsoft Power B1 report and a semantic model that uses Direct Lake mode. From Power Si Desktop, you open Performance analyzer as shown in the following exhibit.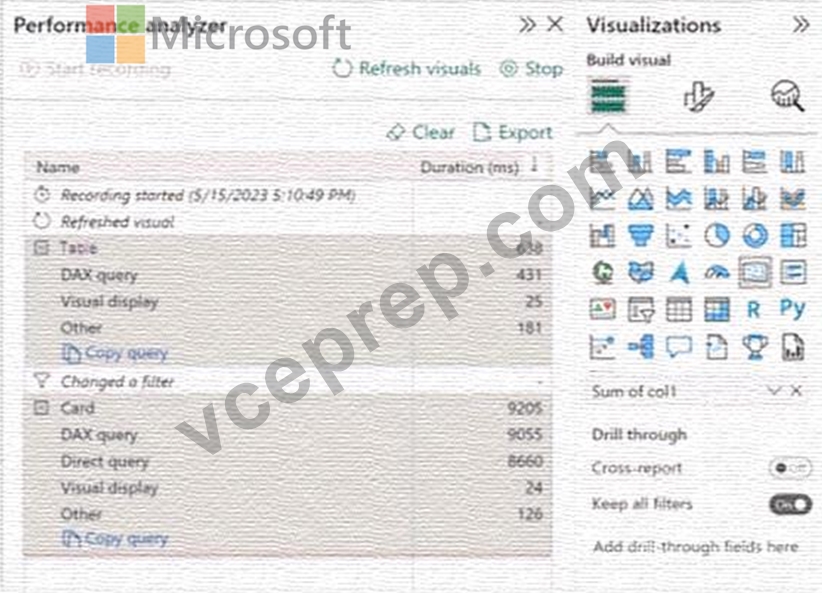
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.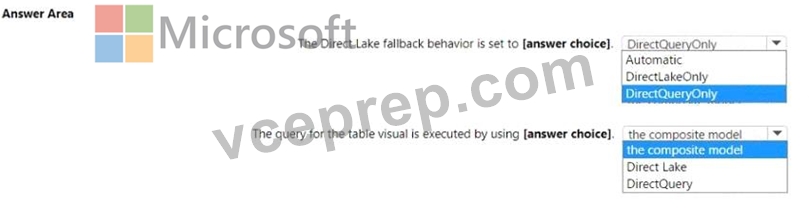
Answer:
Explanation: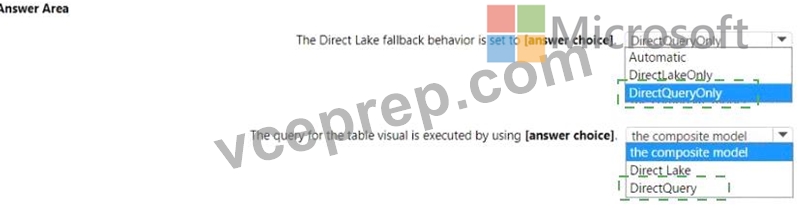
Explanation:
* The Direct Lake fallback behavior is set to: DirectQueryOnly
* The query for the table visual is executed by using: DirectQuery
In the context of Microsoft Power BI, when using DirectQuery in Direct Lake mode, there is no caching of data and all queries are sent directly to the underlying data source. The Performance Analyzer tool shows the time taken for different operations, and from the options provided, it indicates that DirectQuery mode is being used for the visuals, which is consistent with the Direct Lake setting. DirectQueryOnly as the fallback behavior ensures that only DirectQuery will be used without reverting to import mode.
NEW QUESTION # 215
......
We apply international recognition third party for the payment of DP-600 exam dumps, and your money and account will be safe if you choose us. And the third party will protest the interests of you. What’s more, free demo is available for DP-600 training materials, and you can have a try before buying, so that you can know what the complete version is like. We also pass guarantee and money back guarantee. You just need to send us the failure scanned, and we will give you full refund. We have online chat service, and if you have any questions for DP-600 Training Materials, you can consult us.
Reliable DP-600 Exam Papers: https://www.vceprep.com/DP-600-latest-vce-prep.html
DOWNLOAD the newest VCEPrep DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1GtxyjCo4xdZDjnD2LNQl-SSnoHP5oVpL