Pass4Test의 도움을 받겠다고 하면 우리는 무조건 최선을 다하여 한번에 패스하도록 도와드릴 것입니다. 또한 일년무료 업뎃서비스를 제공합니다. 중요한 건 덤프가 갱신이 되면 또 갱신버전도 여러분 메일로 보내드립니다. 망설이지 마십시오. 우리를 선택하는 동시에 여러분은AI-103시험고민을 하시지 않으셔도 됩니다.빨리 우리덤프를 장바구니에 넣으시죠.
| Section | Objectives |
|---|---|
| Topic 1: Develop Generative AI Applications and Agents | - AI agents architecture
|
| Topic 2: Implement Natural Language Processing Solutions | - Language understanding and intent recognition - Text analytics and summarization - Translation and multilingual support |
| Topic 3: Knowledge Mining and Information Retrieval | - RAG (Retrieval Augmented Generation) patterns - Indexing and semantic search - Azure AI Search configuration |
| Topic 4: Plan and Manage Azure AI Solutions | - Model selection and lifecycle management - Azure AI resource provisioning and configuration - Responsible AI principles and governance |
| Topic 5: Implement Computer Vision Solutions | - OCR and document intelligence - Image classification and object detection |
일반적으로AI-103인증시험은 IT업계전문가들이 끊임없는 노력과 지금까지의 경험으로 연구하여 만들어낸 제일 정확한 시험문제와 답들이니. 마침 우리Pass4Test 의 문제와 답들은 모두 이러한 과정을 걸쳐서 만들어진 아주 완벽한 시험대비문제집들입니다. 우리의 문제집으로 여러분은 충분히 안전이 시험을 패스하실 수 있습니다. 우리 Pass4Test 의 문제집들은 모두 100%보장 도를 자랑하며 만약 우리Pass4Test의 제품을 구매하였다면Microsoft AI-103관련 시험패스와 자격증취득은 근심하지 않으셔도 됩니다. 여러분은 IT업계에서 또 한층 업그레이드 될것입니다.
질문 # 65
You have a Microsoft Foundry project that contains a deployed chat model.
You have a Python service that sends API requests to the model. The service is integrated with an automated validation system that compares generated outputs against approved response patterns.
Stakeholders report that small wording differences are causing validation mismatches.
You need to update the request parameters to improve output stability. The solution must maximize reasoning quality.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.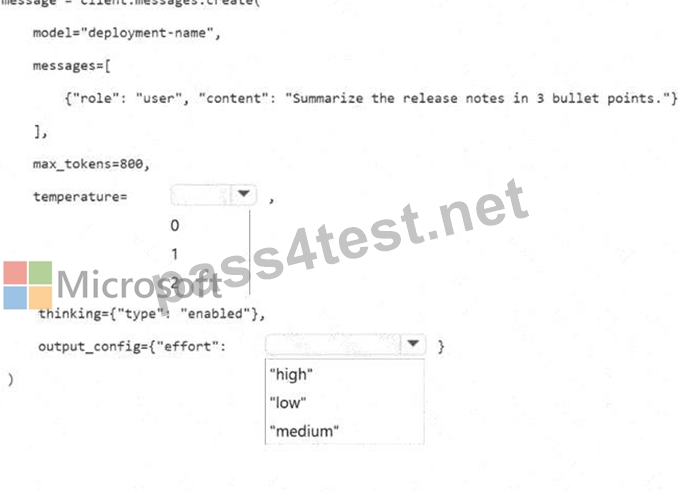
정답:
설명: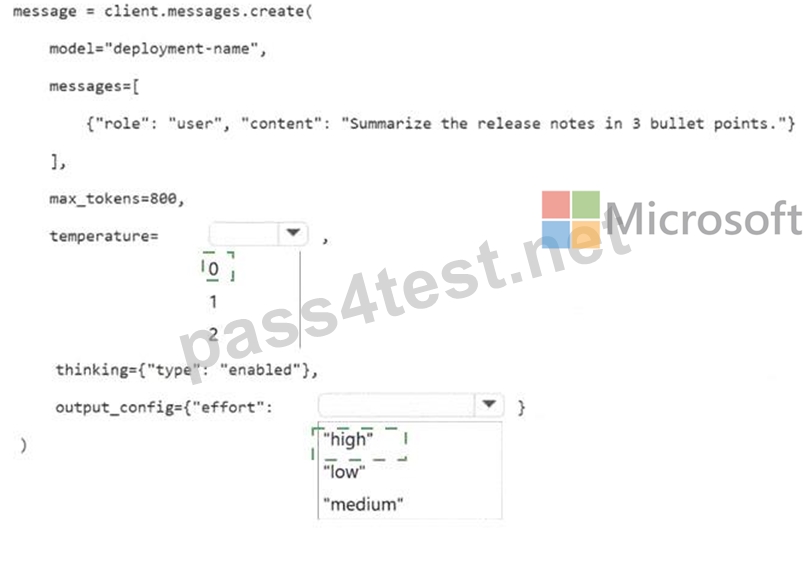
Explanation:
temperature = 0
output_config = { " effort " : " high " }
The correct configuration is temperature = 0 and output_config = { " effort " : " high " }. The requirement is to reduce small wording variations that are breaking automated validation. In chat completion requests, temperature controls sampling randomness. Microsoft's Azure OpenAI reference states that temperature ranges between 0 and 2, and that higher values make output more random while lower values make output more focused and deterministic. Therefore, the most stable setting from the available choices is 0, because it minimizes randomness and improves repeatability for validation-sensitive response patterns.
The solution must also maximize reasoning quality. The code already enables thinking with thinking={ " type
" : " enabled " }, so the remaining reasoning-quality control is the effort setting. Microsoft Foundry model guidance states that the effort parameter controls the quality/cost tradeoff and supports low, medium, and high effort levels. Selecting " high " maximizes reasoning quality among the available options.
Using temperature values of 1 or 2 would increase variability and make validation mismatches more likely.
Selecting low or medium effort would not meet the requirement to maximize reasoning quality. Reference topics: Microsoft Foundry model inference, chat model parameters, temperature, thinking, effort, and output stability.
질문 # 66
Hotspot Question
You are creating an enrichment pipeline that will use Azure AI Search. The knowledge store contains unstructured JSON data and the text from scanned PDF documents.
Which projection type should you use for each data type? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.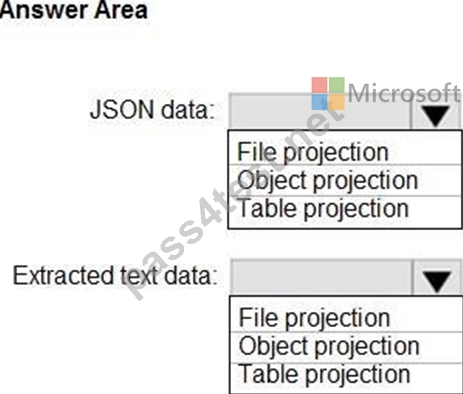
정답:
설명: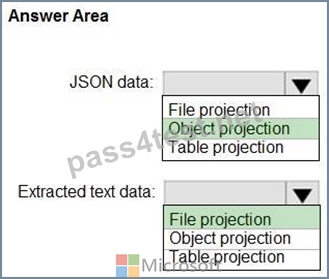
Explanation:
Box 1: Object projection
For the unstructured JSON data, you must use object projection, and for the extracted text data from the scanned PDF documents, you must use file projection.
Object Projection: Projects your data as a full JSON representation. It is ideal for maintaining the original structure alongside any applied AI enrichments within a single JSON document inside Azure Blob Storage.
Box 2: File projection
File Projection: Captures the binary or image extraction layer required during Optical Character Recognition (OCR) processing. It isolates and outputs raw text and graphic details directly from unstructured physical binary files into a designated container Reference:
https://learn.microsoft.com/en-us/azure/search/cognitive-search-concept-image-scenarios
질문 # 67
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
- Provide accurate, context-aware responses grounded in internal
product documentation stored in Azure AI Search.
- Require deep, multi-step reasoning across long contexts.
- Generate detailed natural language responses.
Which type of model should you use to power the agent?
정답:D
설명:
For a support agent requiring deep multi-step reasoning, long context processing, and strict grounding in internal documents, the GPT-5.5 (or GPT-5.5-Pro) model from the Azure AI Foundry model catalog is the best choice.
Here is how GPT-5.5 directly addresses the requirements:
Deep Multi-Step Reasoning: These frontier models use deliberate reasoning and iterative planning before generating a response. This allows the agent to decompose complex support queries, analyze alternatives, and prevent hallucinations without requiring heavy custom prompt engineering.
Grounded, Accurate Responses:
Rather than doing this alone, pair the model with Foundry IQ connected to your Azure AI Search indices. Foundry IQ's agentic retrieval engine will pull exactly the right context, allowing GPT-5.5 to synthesize the answer and cite the original documentation.
Long Context Handling:
GPT-5.5 models support massive context windows, allowing them to ingest extensive previous conversational turns alongside detailed internal documentation in a single pass without losing track of important rules.
Note:
GPT-5.5 is a large language model (LLM).While it is a flagship LLM built on OpenAI's advanced transformer architecture, it also features natively omnimodal capabilities that allow it to process both text and images seamlessly within a single unified framework. However, when choosing between the specific categories provided, its primary core classification is a Large Language Model (LLM).
Key Details About GPT-5.5
Core Architecture: Large Language Model (LLM) built by OpenAI.
Primary Focus: Highly optimized for complex reasoning, multi-step problem solving, coding, and autonomous agentic workflows.
Input/Output Capabilities: Supports text and image inputs with text-based outputs.
Reference:
https://developers.openai.com/api/docs/guides/reasoning
질문 # 68
You are planning a Microsoft Foundry project named Project1 that will contain multiple agents.
Each agent will access the same Azure AI Search resource.
You need to recommend a solution to centrally manage the Azure AI Search credentials within Project1. The solution must be implemented across all the agents.
What should you recommend?
정답:A
설명:
To best manage security and centrally handle credentials across multiple agents, you should add a connection to the Azure AI Search resource at the Azure AI Foundry project level.
Why This Works
Central Hub: The project acts as the single security perimeter for all your agents.
Credential Masking: Agents inherit access without hardcoding secrets, API keys, or connection strings in their code.
Identity Management: It allows you to leverage Microsoft Entra ID (formerly Azure AD) for role- based access control (RBAC).
How to Implement It
1. Navigate to your Azure AI Foundry portal.
2. Select your specific project from the dashboard.
3. Open the "Management Center" or "Project settings" tab.
4. Click on "Connected resources" or "Connections".
5. Add the Azure AI Search resource.
6. Choose Entra ID (managed identity) over API keys for maximum security.
Reference:
https://partner.microsoft.com/en-us/blog/article/azure-updates-december-2025
질문 # 69
You have a web app named App1 that processes user prompts by integrating with a Microsoft Foundry project named Project1. App1 performs the following actions:
- Sends prompts directly to a model by using the Azure OpenAI Responses API
- Invokes the Azure AI Content Safety tool by using a Foundry
connection within the same request
You need to configure end-to-end visibility into each step of the request workflow.
What should you do?
정답:C
설명:
To configure end-to-end visibility into each step of the request workflow, you should Enable application tracing in the project.
Project-Level Observability: Enabling application tracing allows Microsoft Foundry to natively track, trace, and monitor every component of the workflow-including calls to the Azure OpenAI Responses API and associated tools like Azure AI Content Safety-within the same request without requiring complex, separate SDK configurations.
Centralized Tracking: Tracing captures the exact execution path across the project endpoints, allowing you to see metrics, latency, and inputs/outputs sequentially for both the model invocation and the content safety check.
Reference:
https://learn.microsoft.com/en-us/azure/foundry-classic/how-to/develop/trace-production-sdk
질문 # 70
......
다른 방식으로 같은 목적을 이룰 수 있다는 점 아세요? 여러분께서는 어떤 방식, 어느 길을 선택하시겠습니까? 많은 분들은Microsoft인증AI-103시험패스로 자기 일에서 생활에서 한층 업그레이드 되기를 바랍니다. 하지만 모두 다 알고계시는그대로Microsoft인증AI-103시험은 간단하게 패스할 수 있는 시험이 아닙니다. 많은 분들이Microsoft인증AI-103시험을 위하여 많은 시간과 정신력을 투자하고 있습니다. 하지만 성공하는 분들은 적습니다.
AI-103적중율 높은 덤프: https://www.pass4test.net/AI-103.html