What's more, part of that DumpsReview DP-800 dumps now are free: https://drive.google.com/open?id=16UjS4-A3pmA5NzTAoQeS34TmljJN9Aus
DumpsReview DP-800 practice test has real DP-800 exam questions. You can change the difficulty of these questions, which will help you determine what areas appertain to more study before taking your Developing AI-Enabled Database Solutions (DP-800) exam dumps. Here we listed some of the most important benefits you can get from using our Developing AI-Enabled Database Solutions (DP-800) practice questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Every question from our DP-800 study materials is carefully elaborated and the content of our DP-800 exam questions involves the professional qualification certificate examination. We believe under the assistance of our DP-800 practice quiz, passing the exam and obtain related certificate are not out of reach. As long as you study our DP-800 training engine and followe it step by step, we believe you will achieve your dream easily.
NEW QUESTION # 73
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.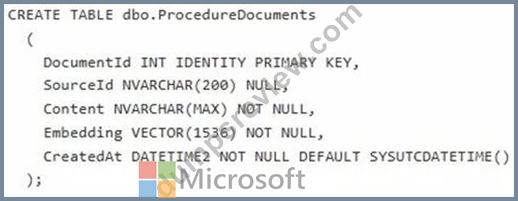
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.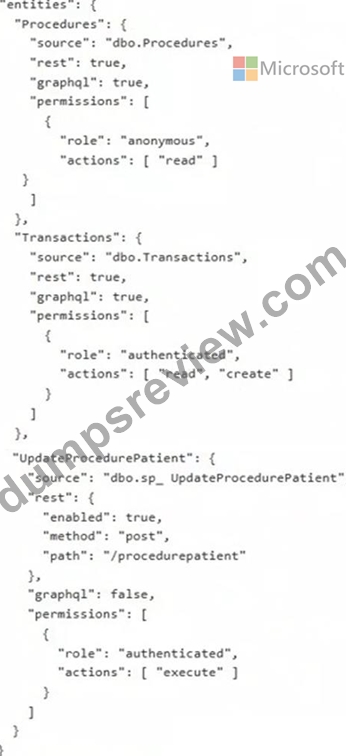
You need to use the UsefulPrompts table as defined in the AI requirements. Which stored procedure should you use?
Answer: B
Explanation:
Scenario:
The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
The system stored procedure sp_invoke_external_rest_endpoint is used to connect an Azure SQL Database to an Azure OpenAI endpoint.This procedure allows you to call HTTPS REST endpoints directly from your database, enabling the integration of generative AI or embedding models into your SQL workflows without an intermediate application layer.
Reference:
https://blog.fabric.microsoft.com/en-gb/blog/ai-ready-apps-from-rag-to-chat-interacting-with-sql- database-in-microsoft-fabric-using-graphql-and-mcp
NEW QUESTION # 74
Hotspot Question
You have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL item named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.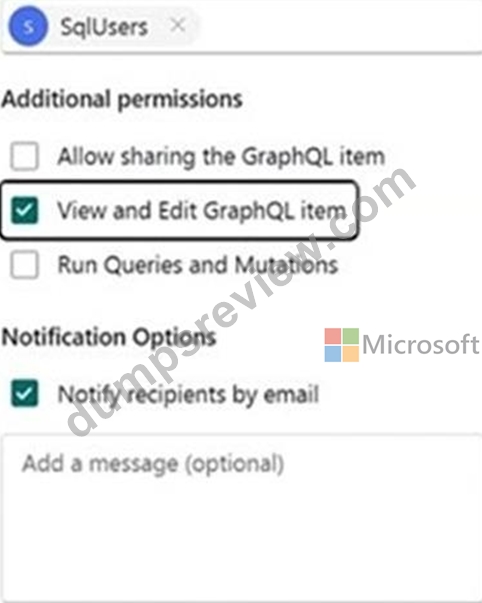
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.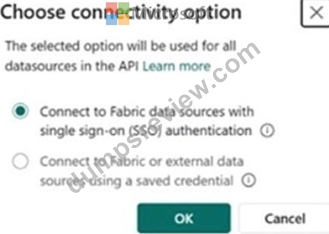
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: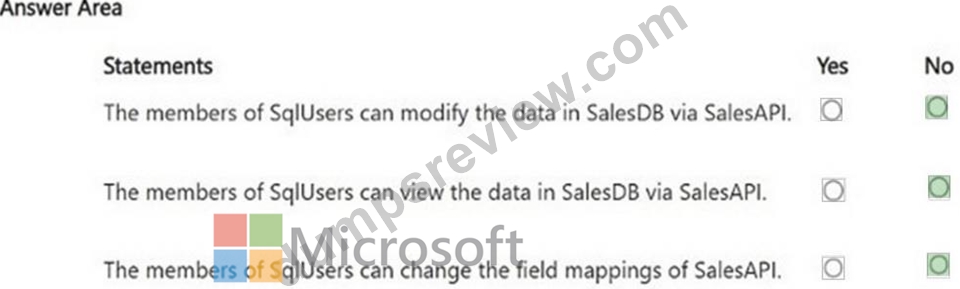
NEW QUESTION # 75
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.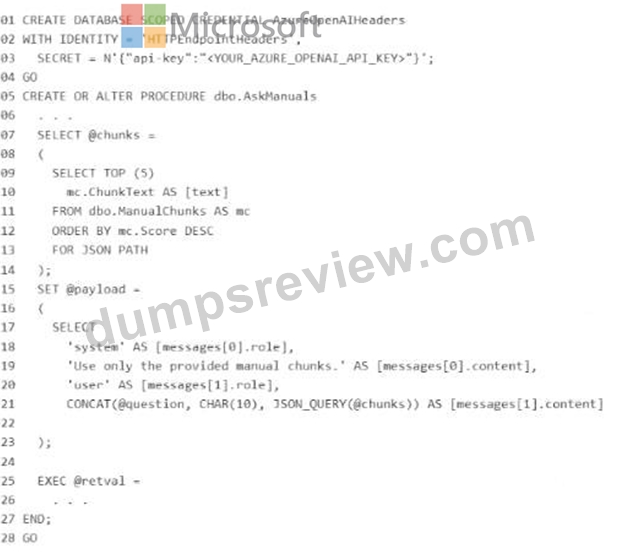
What should you insert at line 22?
Answer: B
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 76
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.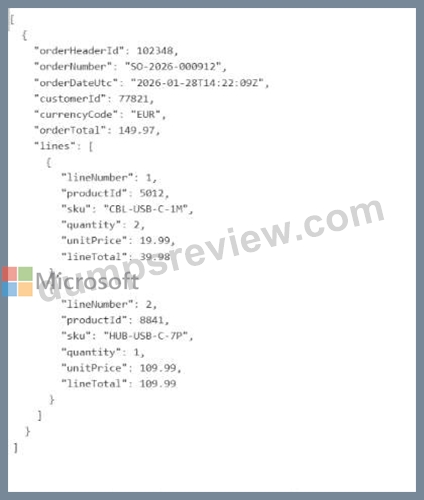
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.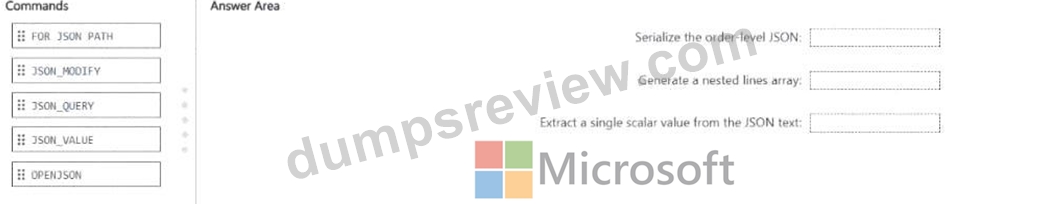
Answer:
Explanation: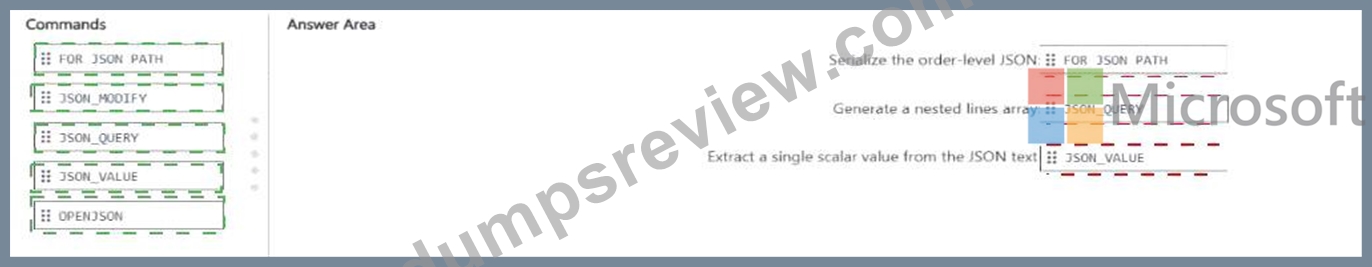
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 77
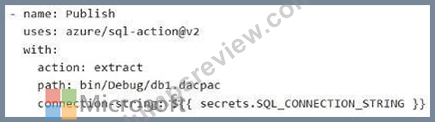
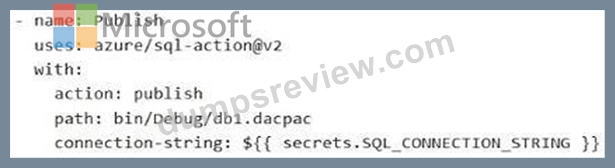
You have a database named DB1. The schema is stored in a Git repository as an SDK-style SQL database project.
You have a GitHub Actions workflow that already runs dotnet build and produces a database artifact.
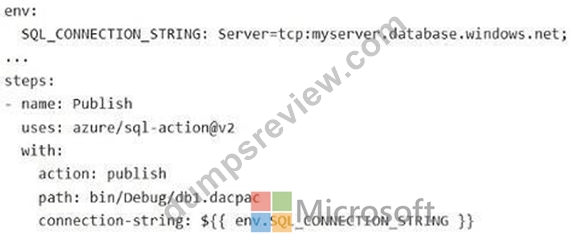
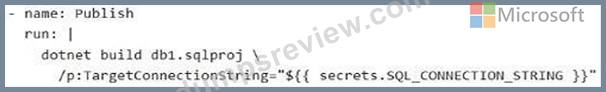
You need to add a deployment step that publishes the .dacpac file to an Azure SQL database by using the secrets stored in GitHub repository secrets.
What should you include in the workflow?
Answer: D
Explanation:
To deploy your .dacpac to Azure SQL using GitHub Actions, you should use the official azure/sql- action@v2. This action is designed specifically to take the output of your dotnet build and publish it.
Assuming your build step is already working, here is how you structure the deployment job.
GitHub Actions Workflow Snippet
Add this job to your .yml file. It depends on your build job (usually named build) and runs on a runner with the Azure CLI installed (like ubuntu-latest).
- name: Deploy SQL Schema
uses: azure/sql-action@v2
with:
connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
path: './bin/Release/netstandard2.1/YourDatabase.dacpac' # Path to your .dacpac action: 'publish' Incorrect:
[Not A]
Use connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
[Not B]
Action set to publish, not to extract.
[Not D]
Use azure/sql-action@v2.
Reference:
https://stackoverflow.com/questions/75490960/github-actions-dotnet-publish-specify-a-project- with-a-dot-in-the-name
NEW QUESTION # 78
......
Studying from an updated practice material is necessary to get success in the Microsoft DP-800 certification test on the first try. If you don't adopt this strategy, you will not be able to clear the Developing AI-Enabled Database Solutions (DP-800) examination. Failure in the Developing AI-Enabled Database Solutions (DP-800) test will lead to loss of confidence, time, and money.
DP-800 Latest Examprep: https://www.dumpsreview.com/DP-800-exam-dumps-review.html
2026 Latest DumpsReview DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=16UjS4-A3pmA5NzTAoQeS34TmljJN9Aus