2026 Latest ValidExam SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1Ni63-HDSGS6wtk-m6hVwiUG8Ezsz-WlQ
Valid Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 test dumps demo and latest test preparation for customer's success. Snowflake offers latest Snowflake Certified SnowPro Specialty - Snowpark exam and valid practice questions book to help you pass the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Exam in your field. The Snowflake Certified SnowPro Specialty - Snowpark exam is 365 days updates and true. New SPS-C01 study questions pdf in less time. And Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 price is benefit!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 2: Snowpark API and Development | 30% | - Python API fundamentals
|
| Topic 3: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 4: Performance and Best Practices | 10% | - Security and governance
|
If you want to be familiar with the real test and grasp the rhythm in the real test, you can choose our SPS-C01 exam test engine to practice. Both our soft test engine and app test engine provide the exam scene simulation functions. You set timed SPS-C01 test and practice again and again. Besides, SPS-C01 exam test engine cover most valid test questions so that it can guide you and help you have a proficient & valid preparation process.
NEW QUESTION # 257
You're using Snowpark in Python and need to execute a complex SQL query. The query involves several joins and aggregations, and you want to optimize its performance. You are using "session.sql(query)' to execute the query. Which of the following strategies, applied before executing 'session.sql(query)' , would likely lead to the most significant performance improvement for a very large dataset?
Answer: D
Explanation:
Option A provides the most significant improvement because Snowpark DataFrame operations allow Snowflake's query optimizer to leverage pushdown optimizations. When you express your logic as DataFrame operations, Snowpark translates these into SQL that is specifically tailored for Snowflake's engine. This gives Snowflake more control over the execution plan compared to simply passing in a pre-written SQL query via 'session.sql(queryy. DataFrame operations allow the query optimizer to push down operations such as filters and aggregations to the data source, significantly reducing the amount of data transferred and processed. Option B is incorrect because comments only improve readability, not performance. Option C, , can help if the DataFrame is used multiple times, but it doesn't address the initial optimization of the query itself. Option D could help, but converting to DataFrame operations provides more comprehensive optimization. Option E can assist, but often DataFrame creation and optimal query plan generation can be better using Option A.
NEW QUESTION # 258
You have JSON files stored in an internal stage named 'json_stage' within your Snowflake account. Each JSON file contains an array of product objects, with potentially nested structures. You need to create a Snowpark DataFrame to analyze this data, but the schema is complex and you want to avoid explicitly defining it in your Python code. Which of the following Snowpark code snippets will MOST effectively achieve this, assuming you have a Snowpark session object named 'session'?





Answer: A
Explanation:
Option A is the most straightforward. By default, Snowpark automatically infers the schema when reading JSON files directly from a stage without requiring additional options. Other options are useful for specific cases, like handling missing fields, but are not necessary for the basic requirement of reading JSON with schema inference. Note that E would require looping through and UNIONing results, and is far less efficient than the built in stage reader.
NEW QUESTION # 259
A data engineering team is building a Snowpark pipeline to process IoT sensor data'. They want to create a UDF that uses a 3rd-party Python library (not available in Snowflake's Anaconda channel) to analyze the sensor readings. The UDF needs to be efficiently deployed and managed within Snowflake. Which of the following approaches represents the MOST robust and scalable way to register and deploy this UDF using Snowpark?
Answer: E
Explanation:
Option B is the correct answer. It describes the best practice for deploying UDFs with external Python libraries in Snowflake. Creating a virtual environment, zipping it, uploading it to a stage, and referencing it during UDF registration ensures proper dependency management and avoids conflicts. Option A is problematic because embedding the library directly makes the UDF definition very large and unmanageable. Option C will not work if the required version isn't available. Option D is incorrect because functions.udf relies on packages available in the Snowflake Anaconda channel and doesn't manage custom packages. While Option E could work, its overly complex for this specific scenario compared to utilizing Snowpark virtual enviornment and stage management. Option B is more efficient and streamlined.
NEW QUESTION # 260
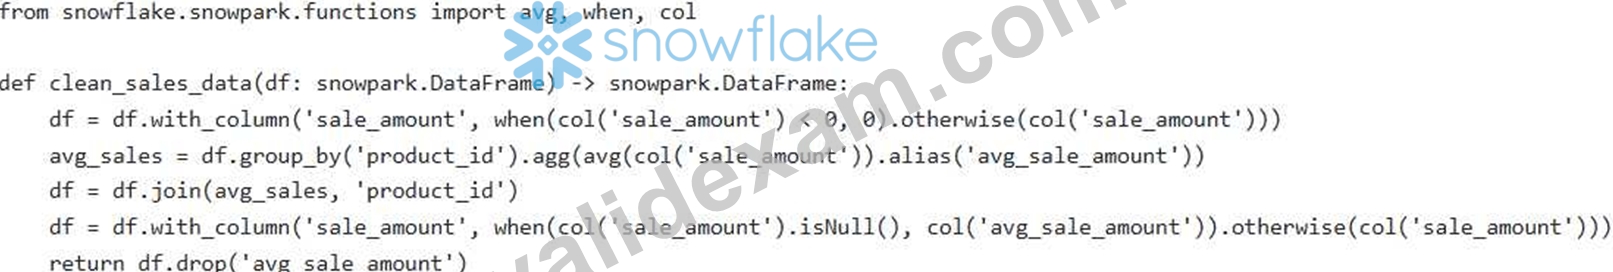
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
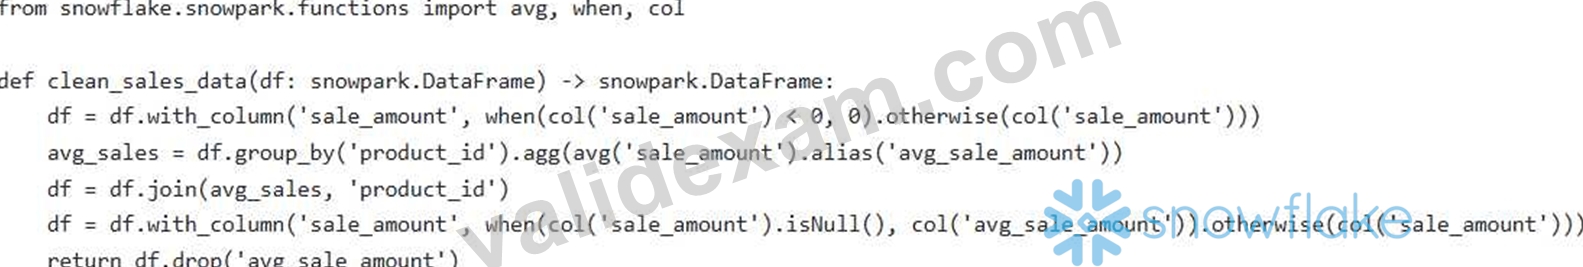
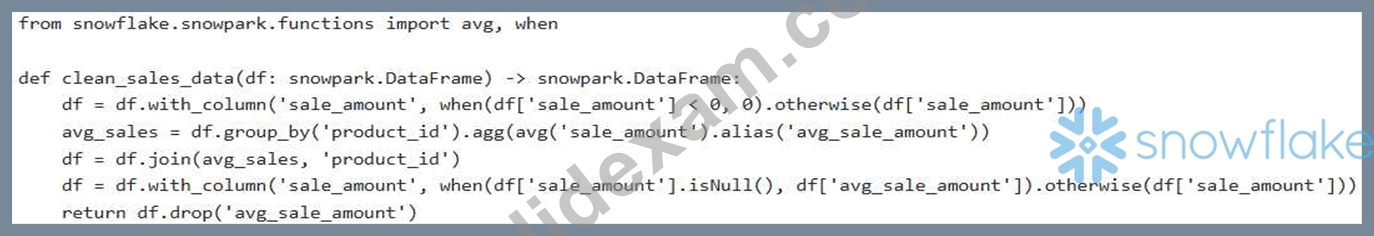
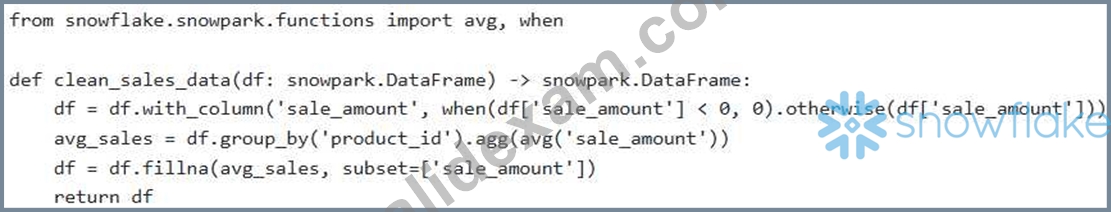
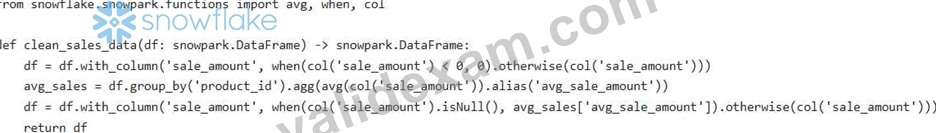
Answer: E
Explanation:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
NEW QUESTION # 261
You have a Snowpark application processing streaming data from an event table. You observe that the application frequently fails with transient errors related to network connectivity or Snowflake service unavailability. You want to implement a robust error handling strategy to ensure the application can recover from these transient failures without losing data'. Which of the following approaches would be MOST appropriate and effective in this scenario, ensuring idempotent processing?
Answer: A,C
Explanation:
Implementing a message queue provides a buffer that isolates the Snowpark application from transient data source failures. E is correct because adding an exponential backoff mechanism with jitter is crucial to prevent overwhelming the system with retries and helps to ensure idempotent processing. Option B can address some internal Snowflake errors, but not connectivity issues. The other approaches do not address data loss or idempotent operation.
NEW QUESTION # 262
......
Our SPS-C01 exam questions are so popular among the candidates not only because that the qulity of the SPS-C01 study braidumps is the best in the market. But also because that our after-sales service can be the most attractive project in our SPS-C01 Preparation questions. We have free online service which means that if you have any trouble, we can provide help for you remotely in the shortest time. And we will give you the best advices on the SPS-C01 practice engine.
Exam SPS-C01 Questions Pdf: https://www.validexam.com/SPS-C01-latest-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by ValidExam: https://drive.google.com/open?id=1Ni63-HDSGS6wtk-m6hVwiUG8Ezsz-WlQ