P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by ExamcollectionPass: https://drive.google.com/open?id=1DUagSEM5E5bil-7xQUuGxUAj3ES_fX2o
As the old saying goes, "Everything starts from reality, seeking truth from facts." This means that when we learn the theory, we end up returning to the actual application. Therefore, the effect of the user using the latest AI-300 exam dump is the only standard for proving the effectiveness and usefulness of our products. I believe that users have a certain understanding of the advantages of our AI-300 Study Guide, but now I want to show you the best of our AI-300 training Materials - Amazing pass rate. Based on the statistics, prepare the exams under the guidance of our AI-300 practice materials, the user's pass rate is up to 98% to 100%, And they only need to practice latest AI-300 exam dump to hours.
| Section | Objectives |
|---|---|
| Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Design and implement generative AI solutions | - Large language model integration
|
Our AI-300 practice braindumps not only apply to students, but also apply to office workers; not only apply to veterans in the workplace, but also apply to newly recruited newcomers. And our AI-300 study materials use a very simple and understandable language, to ensure that all people can learn and understand. Besides, our AI-300 Real Exam also allows you to avoid the boring of textbook reading, but let you master all the important knowledge in the process of doing exercises.
NEW QUESTION # 85
Hotspot Question
You create an Azure Machine Learning workspace and install the MLflow library.
You need to log different types of data by using the MLflow library.
Which method should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.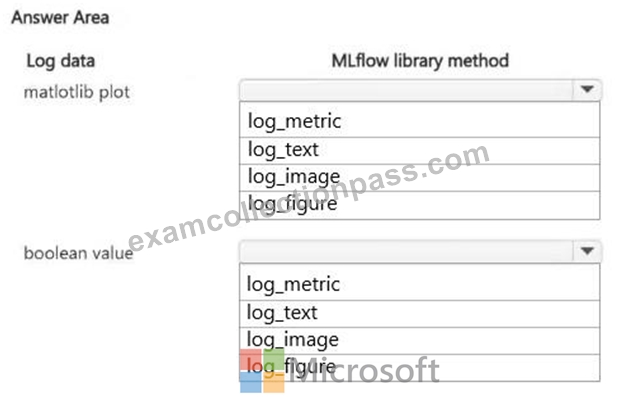
Answer:
Explanation: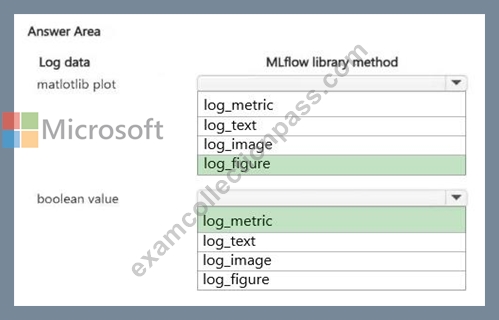
Explanation:
Box 1: log_figure
matlotlib plot
To log a Matplotlib plot data using the MLflow library, you should use the mlflow.log_figure() method.
Alternatively, if you save the Matplotlib plot as an image object (such as a PIL image) or a local image file first, you can use mlflow.log_image() or mlflow.log_artifact(). However, mlflow.log_figure() is specifically built to accept a Matplotlib figure object directly.
Box 2: log_metric
Boolean value
To log a boolean value data using the MLflow library in an Azure Machine Learning workspace, you should use the mlflow.log_param() method.
Alternatively, if you want to track it as a numerical metric over time, you can map the boolean to an integer (1 for True, 0 for False) and log it using mlflow.log_metric().
Depending on your precise objective for tracking the boolean data, choose from the two main use cases:
mlflow.log_param(key, value): Best for static configuration data, flags, or hyperparameter switches (e.g., is_training=True). Parameters accept string representations of boolean values.
mlflow.log_metric(key, value): Best if the boolean represents a status or binary occurrence that shifts or updates throughout execution. MLflow metrics exclusively accept numeric values, meaning you must cast the boolean into a 1 or 0.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-log-view-metrics
NEW QUESTION # 86
Drag and Drop Question
A team maintains Infrastructure as Code (IaC) templates to provision Azure Machine Learning resources.
Provisioning must be triggered by changes in the templates and executed without manual intervention.
You need to automate resource provisioning.
Which action should you take for each requirement? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.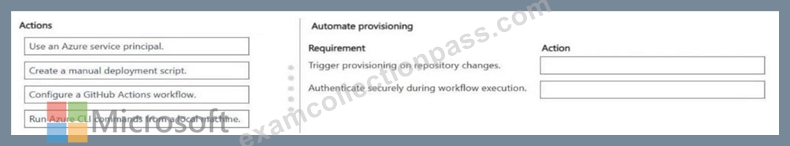
Answer:
Explanation: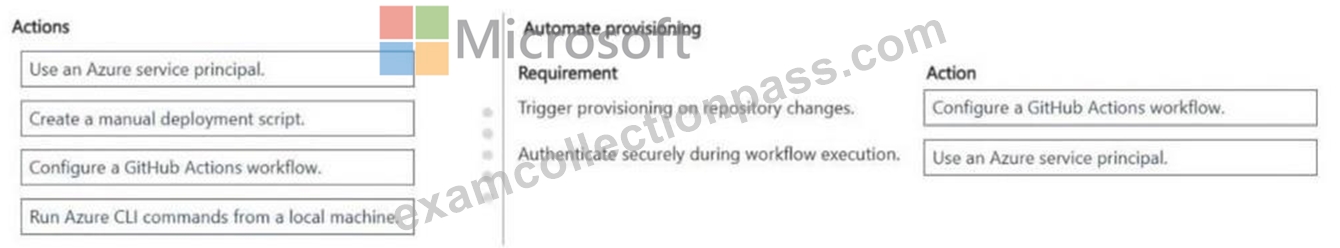
NEW QUESTION # 87
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team requires generative AI to automatically evaluate every pull request of an agentic application and fail the build if safety thresholds are exceeded.
You need to automate evaluations as part of CI.
What should you configure?
Answer: C
Explanation:
The correct solution is a GitHub Actions workflow that executes Microsoft Foundry evaluations as part of the CI process . Microsoft provides an AI agent evaluation GitHub Action specifically for incorporating Foundry agent evaluations into CI/CD workflows. The action can invoke the agent against an evaluation dataset, execute configured evaluators-including safety evaluators-and publish evaluation results before a change reaches production.
For pull-request gating, the workflow can be configured to run whenever relevant application files change.
Evaluation commands can also enforce explicit thresholds and return a non-zero exit code when those thresholds are not satisfied. Microsoft documents evaluation gating through options such as --fail-on pass- rate= < threshold > or --fail-on any-failure; a non-zero result causes the CI job to fail, preventing unsafe changes from being promoted.
A blocklist or content filter provides runtime content protection but does not automate pull-request evaluation.
A retrieval chunking strategy affects RAG retrieval quality, not CI safety gates.
Therefore, the required mechanism is GitHub Actions integrated with Foundry evaluation runs and safety thresholds .
Study Guide Reference: Implement generative AI quality assurance and observability - automated evaluations, CI/CD quality gates, safety evaluators, GitHub Actions, and pre-production validation.
NEW QUESTION # 88
-
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.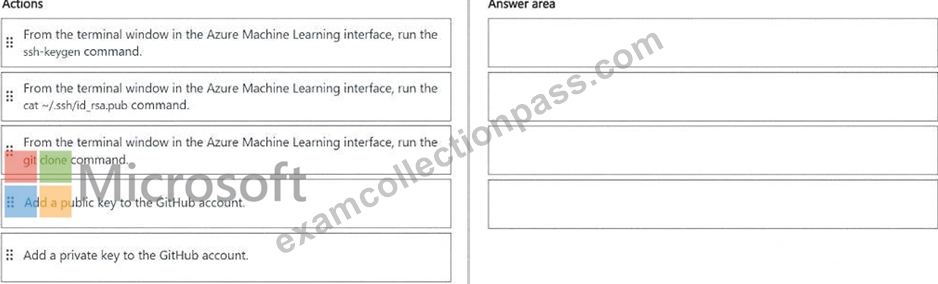
Answer:
Explanation: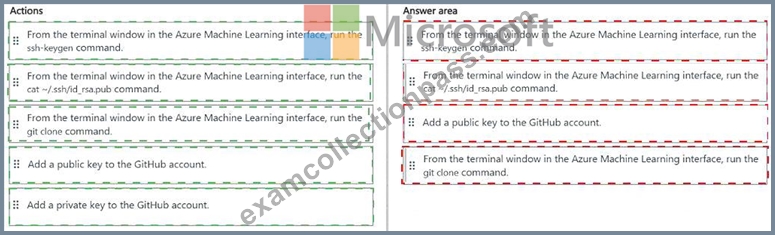
Explanation:
Correct sequence:
* From the terminal window in the Azure Machine Learning interface, run the ssh-keygen command.
* From the terminal window in the Azure Machine Learning interface, run the cat ~/.ssh/id_rsa.
pub command.
* Add a public key to the GitHub account.
* From the terminal window in the Azure Machine Learning interface, run the git clone command.
Azure Machine Learning supports cloning Git repositories directly into the workspace file system from a compute instance terminal . For an SSH-based GitHub connection, the required workflow is to generate an SSH key pair, obtain the public-key value, associate that public key with the Git account, and then clone the repository using its SSH URL. Microsoft documents this exact logical sequence for Git integration with Azure Machine Learning.
First, ssh-keygen creates the private/public SSH key pair on the Azure Machine Learning compute instance.
Next, the cat ~/.ssh/id_rsa.pub command displays the public-key contents so they can be copied. The public key is then added to the GitHub account, enabling GitHub to authenticate connections originating from the compute instance. The private key must remain on the compute instance and must never be uploaded to GitHub.
Finally, execute git clone with the repository ' s SSH clone URL. Azure Machine Learning documentation confirms that repositories can be cloned directly into its shared workspace file system and recommends performing Git operations from the compute-instance terminal.
Add a private key to the GitHub account is therefore the unused and incorrect action.
Study Guide Reference: Design and implement an MLOps infrastructure - source control integration, Azure Machine Learning workspace files, SSH authentication, Git repositories, and secure development workflows.
NEW QUESTION # 89
Hotspot Question
A team retrains a machine learning model on a weekly basis by using updated training data.
The team must be able to rerun any previous experiment by using the exact data that was available at the time it was originally run. The solution must preserve historical versions of the data without duplicating training scripts.
You need to manage the data so that experiments can be reproduced reliably.
Which workspace actions should you perform? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.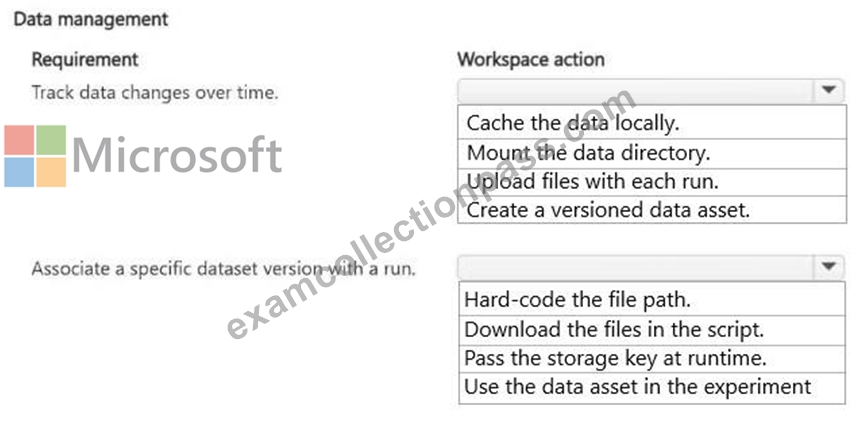
Answer:
Explanation:
Explanation:
Box 1: Create a versioned dataset
Track data changes over time.
Creating a versioned dataset in your machine learning workspace configuration is the correct and industry-standard way to solve this.
Versioned datasets allow you to decouple your training scripts from your data state. This approach satisfies all your constraints without duplicating code or creating messy infrastructure.
Enables Reproducibility: Every time you run a training job, you log the specific dataset version used (e.g., v1, v2, v3). To rerun a historical experiment, you simply call that specific version identifier.
Prevents Code Duplication: Your training scripts remain identical. They accept a dataset version as an input parameter rather than pointing to hardcoded file paths.
Tracks Weekly Updates: When the weekly data refresh occurs, you register the new data as v+1 in the workspace registry, keeping a clean chronological ledger.
Box 2: Use the data asset in the experiment
Associate a specific dataset version with a run.
To best associate a specific dataset version with a run in the workspace, you should use the data asset in the experiment.
Automatic Lineage: Registering data as a versioned data asset automatically tracks which exact version was used in which specific run.
Exact Reproducibility: You can look back at any historical run and instantly identify or retrieve the precise data state used at that moment.
No Script Duplication: Your training scripts remain decoupled from the data, satisfying your requirement to preserve history without changing code.
Incorrect:
[Pass the storage key at runtime]
Passing a storage key at runtime only connects the run to a storage location, not a specific, immutable version of the data at a frozen point in time.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-version-track-datasets
NEW QUESTION # 90
......
The name of these formats are Microsoft AI-300 PDF dumps file, desktop practice test software, and web-based practice test software. All these three Microsoft Cloud AI-300 practice test formats are easy to use and perfectly work with all devices, operating systems, and web browsers. The AI-300 Pdf Dumps file is a simple collection of Real and Updated Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions in PDF format and it is easy to install and use.
Latest AI-300 Exam Questions Vce: https://www.examcollectionpass.com/Microsoft/AI-300-practice-exam-dumps.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by ExamcollectionPass: https://drive.google.com/open?id=1DUagSEM5E5bil-7xQUuGxUAj3ES_fX2o