Pass Guaranteed Quiz 2026 Databricks Databricks-Machine-Learning-Professional–High-quality Exam Vce Format

BTW, DOWNLOAD part of ExamDiscuss Databricks-Machine-Learning-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1ioxY1tYz5xAaVusKXTNrMhTdnQQz9U76
Free demos of ExamDiscuss Databricks-Machine-Learning-Professional exam questions are available which you can download easily. Just choose the right ExamDiscuss Databricks-Machine-Learning-Professional exam questions format and download the Databricks-Machine-Learning-Professional exam product demo free of cost. Check the top features of Databricks-Machine-Learning-Professional Exam Questions and if you feel that the ExamDiscuss Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) certification exam practice material can work with you then take your buying decision and download it accordingly. Best of luck!!!
Databricks Databricks-Machine-Learning-Professional Exam Overview:
>> Databricks-Machine-Learning-Professional Exam Vce Format <<
Databricks Databricks-Machine-Learning-Professional Examcollection Dumps | Test Databricks-Machine-Learning-Professional Questions Vce
The Databricks world has become so competitive and challenging. To say updated and meet the challenges of the market you have to learn new in-demand skills and upgrade your knowledge. With the Databricks Databricks-Machine-Learning-Professional Certification Exam everyone can do this job nicely and quickly. The Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) certification exam offers a great opportunity to validate the skills and knowledge.
| Topic | Details |
|---|
| Topic 1 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 2 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 3 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 4 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 5 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 6 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 7 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 8 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 9 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 10 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 11 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
Databricks Certified Machine Learning Professional Sample Questions (Q142-Q147):
NEW QUESTION # 142
A Machine Learning Engineer has previously built a feature table for model training and inference using a batch mode approach:
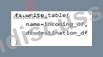
They have been informed that they now require these features to be available in "real-time", with latency on the order of a minute. Their manager has informed them there is now a Kafka stream from which they can stream live data, and they need to have this ingested and available for low- latency feature lookups.
Which change to their existing code will achieve this?
- A. Change the incoming_df to be a dataframe based on a readStream() from the kafka source, the write_table() method will provide a low-latency lookup on this data.
- B. Run a triggered workflow to ingest the Kafka data to a dataframe that they can use with their existing write_table() command.
- C. Create a custom pyfunc MLflow model which processes results of the Kafka stream for on demand feature calculation.
- D. Change the incoming_df to be a dataframe based on a readStream() from the Kafka source and publish the table as an online table with the streaming option set to True.
Answer: D
Explanation:
To achieve real-time availability with minute-level latency, the feature data must be continuously ingested from Kafka and published to an online table. Using a streaming DataFrame created with readStream from the Kafka source and enabling the online table with streaming allows incremental updates to be synchronized to the online store, supporting low-latency feature lookups for real-time inference.
NEW QUESTION # 143
A Machine Learning Engineer is building an application that requires low latency data lookups in response to a user's question following a RAG based search. They want to ensure their users can receive as recent data as possible for urgent requests, so data should not be more than a few minutes late. The underlying data is a large table that may contain hundreds of gigabytes of data. Which data serving approach will suit their use case?
- A. Online tables with snapshot sync mode
- B. Online tables with continuous sync mode
- C. A fast database hosted in MLflow model serving
- D. Online tables with triggered mode and a time series key
Answer: B
Explanation:
Online tables with continuous sync mode are designed for low-latency serving while keeping data fresh within minutes. Continuous sync incrementally propagates updates from the large underlying table to the online store, ensuring near-real-time availability for RAG-based lookups without requiring full refreshes, which is ideal for urgent, freshness-sensitive queries on large datasets.
NEW QUESTION # 144
A Data Scientist has created a sales forecasting model, named sales-forecasting. The model is deployed to a model serving endpoint with a schema. They need to invoke this model using Python and would prefer to use a SDK function to make the request. Which method suits these requirements?
- A. Import the MLflow Deployments class and use the ai_query method and provide the endpoints and request parameters.
- B. Make an API request to the MODEL_VERSION_URI and provide the dataframe_split as the request parameter.
- C. Import the MLflow Deployments class and use the predict method and provide the endpoint and input parameters.
- D. Use the built in ai_query function and provide the endpoints and request parameters.
Answer: C
Explanation:
The MLflow Deployments SDK provides a predict method specifically designed to invoke Databricks model serving endpoints from Python. This method abstracts the HTTP request details, allows specifying the endpoint name directly, and cleanly passes input parameters that conform to the model's serving schema, making it the preferred SDK-based approach.
NEW QUESTION # 145
A machine learning engineer has created a webhook with the following code block:
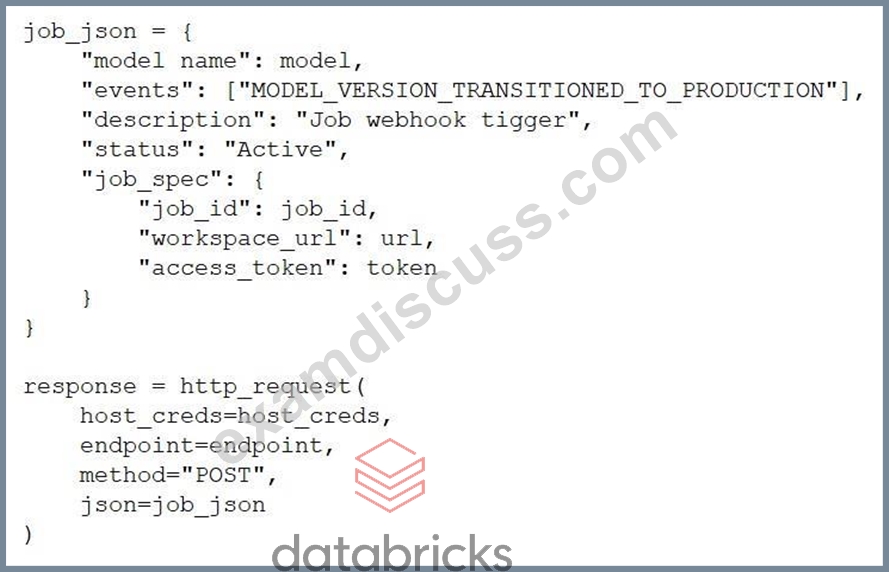
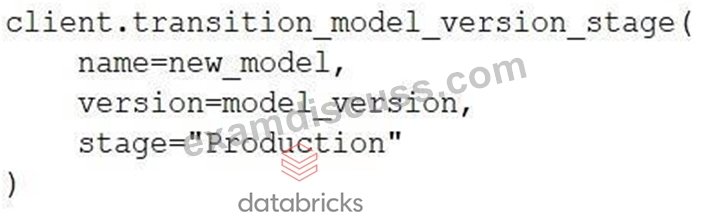
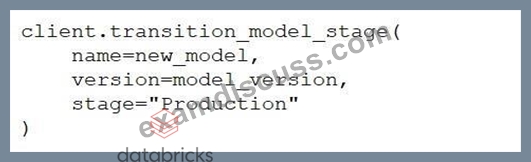
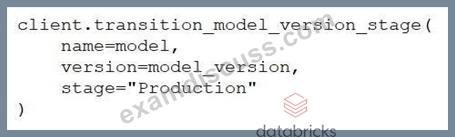
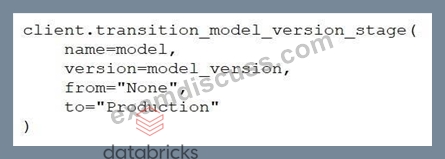
Which code block will trigger this webhook to run the associate job?
Answer: C
Explanation:
The webhook in the first image is configured to trigger on the
MODEL_VERSION_TRANSITIONED_TO_PRODUCTION event. The chosen code uses
client.transition_model_version_stage(...) to move the model version to "Production", which matches the event type in the webhook and will correctly trigger the associated job.
NEW QUESTION # 146
A Data Scientist at an online gaming company is creating a model to predict player churn. The company currently collects terabytes of player activity logs daily, which are stored in Databricks and processed for daily reporting. The Data Scientist has completed feature engineering and the resulting data is saved as a Delta Table with a size of 500GB. They need to next build the model for the most performant and cost-effective performance for Databricks. Which approach will do this?
- A. Load the feature data as a pandas DataFrame and train the model using scikit-learn's RandomForestClassifier on a multi-node Databricks cluster.
- B. Load the feature data as a pandas DataFrame and train the model using scikit-learn's RandomForestClassifier on a single-node Databricks cluster.
- C. Load the feature data as a Spark DataFrame and train the model using Spark's DeepspeedTorchDistributor on a multi-node Databricks cluster.
- D. Load the feature data as a Spark DataFrame and train the model using SparkML's RandomForestClassifier on a multi-node Databricks cluster.
Answer: D
Explanation:
A 500GB Delta Table is far beyond what is practical to load into a single pandas DataFrame, and scaling pandas-based scikit-learn training across nodes is not the right fit for this workload. Using a Spark DataFrame with Spark ML's RandomForestClassifier leverages distributed data processing and distributed model training on a multi-node cluster, which is the most performant and cost-effective approach for large tabular datasets in Databricks.
NEW QUESTION # 147
......
Databricks-Machine-Learning-Professional Examcollection Dumps: https://www.examdiscuss.com/Databricks/exam/Databricks-Machine-Learning-Professional/
- Newest Databricks-Machine-Learning-Professional Exam Vce Format - Leading Offer in Qualification Exams - Unparalleled Databricks Databricks Certified Machine Learning Professional ↕ Go to website ⇛ www.pdfdumps.com ⇚ open and search for ➡ Databricks-Machine-Learning-Professional ️⬅️ to download for free 🤺Databricks-Machine-Learning-Professional Latest Exam Review
- Vce Databricks-Machine-Learning-Professional File 🧬 Guaranteed Databricks-Machine-Learning-Professional Passing 🎮 Databricks-Machine-Learning-Professional Practice Exam Fee 🌾 Search on ➤ www.pdfvce.com ⮘ for ⏩ Databricks-Machine-Learning-Professional ⏪ to obtain exam materials for free download 🌖New Databricks-Machine-Learning-Professional Test Discount
- Guaranteed Databricks-Machine-Learning-Professional Passing 💲 Databricks-Machine-Learning-Professional 100% Correct Answers 🏘 Databricks-Machine-Learning-Professional Practice Exam Fee 🐻 Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and download it for free on 《 www.torrentvce.com 》 website 🍜New Databricks-Machine-Learning-Professional Test Discount
- Databricks-Machine-Learning-Professional New Exam Bootcamp 🎅 Practice Test Databricks-Machine-Learning-Professional Pdf 🍣 Databricks-Machine-Learning-Professional Latest Test Experience 📊 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ and obtain a free download on 「 www.pdfvce.com 」 ⚗Databricks-Machine-Learning-Professional 100% Correct Answers
- Databricks-Machine-Learning-Professional Exam Vce Format Offer You The Best Examcollection Dumps to pass Databricks Databricks Certified Machine Learning Professional exam 🥓 The page for free download of ➽ Databricks-Machine-Learning-Professional 🢪 on ⮆ www.exam4labs.com ⮄ will open immediately 👺Latest Databricks-Machine-Learning-Professional Test Testking
- 100% Pass Quiz Perfect Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Exam Vce Format 🔎 Search for 「 Databricks-Machine-Learning-Professional 」 and download exam materials for free through ⮆ www.pdfvce.com ⮄ 🚻Databricks-Machine-Learning-Professional Latest Questions
- www.exam4labs.com Databricks Databricks-Machine-Learning-Professional Real Exam Questions PDF Format 🔤 Open website ➽ www.exam4labs.com 🢪 and search for [ Databricks-Machine-Learning-Professional ] for free download 🍈Databricks-Machine-Learning-Professional Latest Exam Review
- Databricks-Machine-Learning-Professional Valid Test Book 📐 Databricks-Machine-Learning-Professional Latest Exam Materials 👋 Databricks-Machine-Learning-Professional Latest Exam Review ✳ The page for free download of ⮆ Databricks-Machine-Learning-Professional ⮄ on ➠ www.pdfvce.com 🠰 will open immediately 🌀Databricks-Machine-Learning-Professional Latest Exam Materials
- Guaranteed Databricks-Machine-Learning-Professional Passing 👑 Databricks-Machine-Learning-Professional Latest Questions 🎊 New Databricks-Machine-Learning-Professional Test Discount 🌷 Download ▷ Databricks-Machine-Learning-Professional ◁ for free by simply searching on “ www.vce4dumps.com ” 🍣New Databricks-Machine-Learning-Professional Test Syllabus
- Updated Databricks-Machine-Learning-Professional Exam Vce Format | Amazing Pass Rate For Databricks-Machine-Learning-Professional Exam | Marvelous Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 🎡 Search for ➡ Databricks-Machine-Learning-Professional ️⬅️ and download it for free on ➽ www.pdfvce.com 🢪 website 🤘Guaranteed Databricks-Machine-Learning-Professional Passing
- Accurate Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Exam Vce Format 🧬 Go to website ➡ www.troytecdumps.com ️⬅️ open and search for ➥ Databricks-Machine-Learning-Professional 🡄 to download for free 🤐Databricks-Machine-Learning-Professional Practice Exam Fee
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.intensedebate.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.qualitydigest.com, Disposable vapes
What's more, part of that ExamDiscuss Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1ioxY1tYz5xAaVusKXTNrMhTdnQQz9U76