DOWNLOAD the newest EduDump Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=15KIcKRPDl6WreLEsh0bOJWwHHtnwnf_V
The Professional-Machine-Learning-Engineer torrent prep contains the real questions and simulation questions of various qualifying examinations. It is very worthy of study efficiently. Time is constant development, and proposition experts will set questions of real Professional-Machine-Learning-Engineer exam continuously according to the progress of the society change tendency of proposition, and consciously highlight the hot issues and policy changes. In order to be able to better grasp the proposition thesis direction, the Professional-Machine-Learning-Engineer study question focus on the latest content to help you pass the Professional-Machine-Learning-Engineer exam.
| Section | Weight | Objectives |
|---|---|---|
| Train and deploy models | 20% | - Deploy models for online, batch, and streaming prediction - Use Vertex AI deployment features and infrastructure - Configure training jobs and environments - Implement generative AI deployment patterns |
| Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Automate and orchestrate ML pipelines | 18% | - Implement CI/CD for ML systems - Automate retraining and model updates - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows |
| Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Identify use cases for low-code/no-code AI tools |
| Monitor and optimize AI solutions | 16% | - Optimize cost, latency, and resource usage - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift - Monitor data quality and pipeline health |
| Scale prototypes into AI models | 18% | - Design and run experiments - Work with foundation models and generative AI techniques - Optimize model performance and generalization - Select appropriate model architectures and frameworks |
>> Test Professional-Machine-Learning-Engineer Questions Pdf <<
To improve our products’ quality we employ first-tier experts and professional staff and to ensure that all the clients can pass the test we devote a lot of efforts to compile the Professional-Machine-Learning-Engineer study materials. Even if you unfortunately fail in the test we won’t let you suffer the loss of the money and energy and we will return your money back at the first moment. After you pass the Professional-Machine-Learning-Engineer test you will enjoy the benefits the certificate brings to you such as you will be promoted by your boss in a short time and your wage will surpass your colleagues.
NEW QUESTION # 240
You developed a custom model by using Vertex Al to forecast the sales of your company s products based on historical transactional data You anticipate changes in the feature distributions and the correlations between the features in the near future You also expect to receive a large volume of prediction requests You plan to use Vertex Al Model Monitoring for drift detection and you want to minimize the cost. What should you do?
Answer: B
Explanation:
The best option for using Vertex AI Model Monitoring for drift detection and minimizing the cost is to use the features and the feature attributions for monitoring, and set a prediction-sampling-rate value that is closer to 0 than 1. This option allows you to leverage the power and flexibility of Google Cloud to detect feature drift in the input predict requests for custom models, and reduce the storage and computation costs of the model monitoring job. Vertex AI Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Vertex AI Model Monitoring can monitor the model's prediction input data for feature skew and drift. Feature drift occurs when the feature data distribution in production changes over time. If the original training data is not available, you can enable drift detection to monitor your models for feature drift.
Vertex AI Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the training data is not available, the baseline distribution is calculated from the first 1000 prediction requests that the model receives. If the distance score for a feature exceeds an alerting threshold that you set, Vertex AI Model Monitoring sends you an email alert. However, if you use a custom model, you can also enable feature attribution monitoring, which can provide more insights into the feature drift. Feature attribution monitoring analyzes the feature attributions, which are the contributions of each feature to the prediction output. Feature attribution monitoring can help you identify the features that have the most impact on the model performance, and the features that have the most significant drift over time. Feature attribution monitoring can also help you understand the relationship between the features and the prediction output, and the correlation between the features1. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower prediction-sampling-rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower prediction-sampling-rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. However, using a higher prediction-sampling-rate can increase the storage and computation costs of the model monitoring job, and also the amount of data that needs to be processed and analyzed. Therefore, there is a trade-off between the prediction-sampling-rate and the cost and accuracy of the model monitoring job, and the optimal prediction-sampling-rate depends on the business objective and the data characteristics2. By using the features and the feature attributions for monitoring, and setting a prediction-sampling-rate value that is closer to 0 than 1, you can use Vertex AI Model Monitoring for drift detection and minimize the cost.
The other options are not as good as option D, for the following reasons:
* Option A: Using the features for monitoring and setting a monitoring-frequency value that is higher than the default would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a higher monitoring-frequency can increase the frequency and timeliness of the model monitoring job, but also the computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance1.
* Option B: Using the features for monitoring and setting a prediction-sampling-rate value that is closer to
1 than 0 would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a higher prediction-sampling-rate can increase the quality and validity of the data, but also the storage and computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance12.
* Option C: Using the features and the feature attributions for monitoring and setting a monitoring-frequency value that is lower than the default would enable feature attribution monitoring, but could reduce the frequency and timeliness of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a lower
* monitoring-frequency can reduce the computation costs of the model monitoring job, but also the frequency and timeliness of the model monitoring job. This can make the model monitoring job less responsive and effective in detecting and alerting the feature drift1.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Using Model Monitoring
* Understanding the score threshold slider
NEW QUESTION # 241
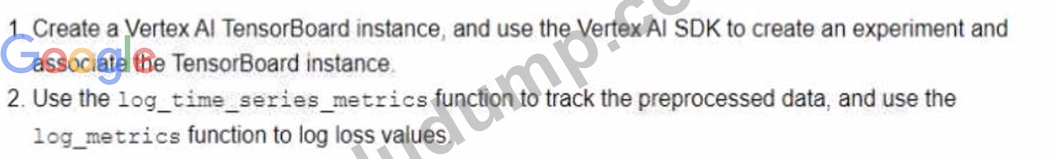
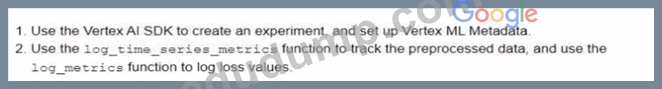
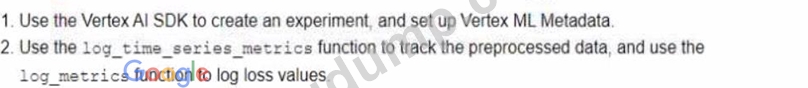
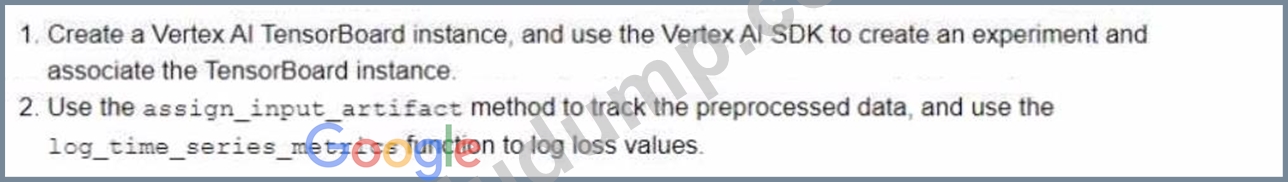
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
Answer: B
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem. You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run. The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. Reference:
Vertex AI Workbench documentation
Vertex AI TensorBoard documentation
Vertex AI SDK documentation
log_time_series_metrics function documentation
log_metrics function documentation
[Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 242
You are an ML engineer at a manufacturing company. You need to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. You want your model to preprocess the images with lower computation to quickly extract features of defects in products. Which approach should you use to build the model?
Answer: C
Explanation:
* Option A is incorrect because reinforcement learning is not a suitable approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. Reinforcement learning is a type of machine learning that learns from its own actions and rewards, rather than from labeled data or explicit feedback1. Reinforcement learning is more suitable for problems that involve sequential decision making, such as games, robotics, or control systems1.
However, defect detection is a problem that involves image classification or segmentation, which requires supervised learning, not reinforcement learning.
* Option B is incorrect because a recommender system is not a relevant approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. A recommender system is a system that suggests items or actions to users based on their preferences, behavior, or context2. A recommender system is more suitable for problems that involve personalization, such as e-commerce, entertainment, or social media2. However, defect detection is a problem that involves image classification or segmentation, which requires supervised learning, not recommender system.
* Option C is incorrect because recurrent neural networks (RNN) are not the most efficient approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. RNNs are a type of neural networks that can process sequential data, such as text, speech, or video, by maintaining a hidden state that captures the temporal dependencies3. RNNs are more suitable for problems that involve natural language processing, speech recognition, or video analysis3. However, defect detection is a problem that involves image classification or segmentation, which does not require temporal dependencies, but rather spatial dependencies. Moreover, RNNs are computationally expensive and prone to vanishing or exploding gradients4.
* Option D is correct because convolutional neural networks (CNN) are the best approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. CNNs are a type of neural networks that can process image data, by applying convolutional filters that extract local features and reduce the dimensionality of the data5. CNNs are more suitable for problems that involve image classification, object detection, or segmentation5. CNNs can preprocess the images with lower computation to quickly extract features of defects in products, by using techniques such as pooling, dropout, or batch normalization6.
References:
* Reinforcement learning
* Recommender system
* Recurrent neural network
* Vanishing and exploding gradients
* Convolutional neural network
* CNN techniques
* [Defect detection]
* [Image classification]
* [Image segmentation]
NEW QUESTION # 243
You work for a financial company that has a large custom dataset with one trillion tokens. The dataset contains financial news, reports, and other related data as well as acquired large public datasets similar to Common Crawl. You need to train a custom LLM from scratch using the open- source open language model (OLMo) framework. You want to maximize throughput. What should you do?
Answer: B
Explanation:
A reserved cluster of a4-highgpu-8g machines provides reliable access to NVIDIA B200 GPUs for sustained, large-scale distributed training. Managed Lustre delivers the high-throughput parallel storage needed to feed a trillion-token dataset efficiently, while Cluster Toolkit and Slurm provide an optimized architecture for coordinating multi-node PyTorch workloads and maximizing accelerator utilization.
Reference:
https://docs.cloud.google.com/architecture/optimize-ai-ml-workloads-managed-lustre
https://docs.cloud.google.com/cluster-toolkit/docs
NEW QUESTION # 244
You work for a bank and are building a random forest model for fraud detection. You have a dataset that includes transactions, of which 1% are identified as fraudulent. Which data transformation strategy would likely improve the performance of your classifier?
Answer: C
Explanation:
Oversampling is a technique for dealing with imbalanced datasets, where the majority class dominates the minority class. It balances the distribution of classes by increasing the number of samples in the minority class. Oversampling can improve the performance of a classifier by reducing the bias towards the majority class and increasing the sensitivity to the minority class.
In this case, the dataset includes transactions, of which 1% are identified as fraudulent. This means that the fraudulent transactions are the minority class and the non-fraudulent transactions are the majority class. A random forest model trained on this dataset might have a low recall for the fraudulent transactions, meaning that it might miss many of them and fail to detect fraud. This could have a high cost for the bank and its customers.
One way to overcome this problem is to oversample the fraudulent transactions 10 times, meaning that each fraudulent transaction is duplicated 10 times in the training dataset. This would increase the proportion of fraudulent transactions from 1% to about 10%, making the dataset more balanced. This would also make the random forest model more aware of the patterns and features that distinguish fraudulent transactions from non- fraudulent ones, and thus improve its accuracy and recall for the minority class.
For more information about oversampling and other techniques for imbalanced data, see the following references:
* Random Oversampling and Undersampling for Imbalanced Classification
* Exploring Oversampling Techniques for Imbalanced Datasets
NEW QUESTION # 245
......
We promise you will pass the exam and obtain the Google Professional Machine Learning Engineer certificate successfully with our help of Professional-Machine-Learning-Engineer exam questions. According to recent survey of our previous customers, 99% of them can achieve their goals, so believe that we can be the helping hand to help you achieve your ultimate goal. Bedsides we have high-quality Professional-Machine-Learning-Engineer test guide for managing the development of new knowledge, thus ensuring you will grasp every study points in a well-rounded way. On the other hand, if you fail to pass the exam with our Professional-Machine-Learning-Engineer Exam Questions unfortunately, you can receive a full refund only by presenting your transcript. At the same time, if you want to continue learning, our Professional-Machine-Learning-Engineer test guide will still provide free updates to you and you can have a discount more than one year. Finally our refund process is very simple. If you have any question about Google Professional Machine Learning Engineer study question, please contact us immediately.
Professional-Machine-Learning-Engineer Latest Test Guide: https://www.edudump.com/exams/Google/Professional-Machine-Learning-Engineer/
BTW, DOWNLOAD part of EduDump Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=15KIcKRPDl6WreLEsh0bOJWwHHtnwnf_V