2026 Latest ExamTorrent DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1NktSFP4hDGZxgQynWC4JgPnsDqAg4Huf
These Microsoft DP-800 exam questions have a high chance of coming in the actual DP-800 test. You have to memorize these DP-800 questions and you will pass the Microsoft DP-800 test with brilliant results. The price of Microsoft DP-800 updated exam dumps is affordable.
| Section | Objectives |
|---|---|
| Topic 1: Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
| Topic 2: Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Topic 3: Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Topic 4: Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
>> DP-800 Valid Exam Review <<
Although it is not an easy thing for somebody to pass the exam, ExamTorrent can help aggressive people to achieve their goals. More qualified certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition. So the DP-800 Certification has also become more and more important for all people. Because a lot of people long to improve themselves and get the decent job. In this circumstance, more and more people will ponder the question how to get the DP-800 certification successfully in a short time.
NEW QUESTION # 80
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements.
What should you include in the recommendation?
Answer: D
Explanation:
The best recommendation is to use an MCP server . In the official DP-800 study guide , Microsoft explicitly lists skills such as configuring Model Context Protocol (MCP) tool options in a GitHub Copilot session and connecting to MCP server endpoints, including Microsoft SQL Server and Fabric Lakehouse . That makes MCP the exam-aligned mechanism for enabling AI-assisted tools to work with live database context rather than static snapshots.
This also matches the stated development requirement: the team will use Visual Studio Code and GitHub Copilot and needs to retrieve live metadata from the databases . Microsoft's documentation for GitHub Copilot with the MSSQL extension explains that Copilot works with an active database connection , provides schema-aware suggestions , supports chatting with a connected database, and adapts responses based on the current database context . Microsoft also documents MCP as the standard way for AI tools to connect to external systems and data sources through discoverable tools and endpoints.
The other options do not satisfy the "live metadata" requirement as well:
* A .dacpac is a point-in-time schema artifact, not live metadata.
* A Copilot instruction file provides guidance, not live database discovery.
* Including the database project in the repository helps source control and deployment, but it still does not provide live database metadata by itself.
NEW QUESTION # 81
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: D
Explanation:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
NEW QUESTION # 82
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.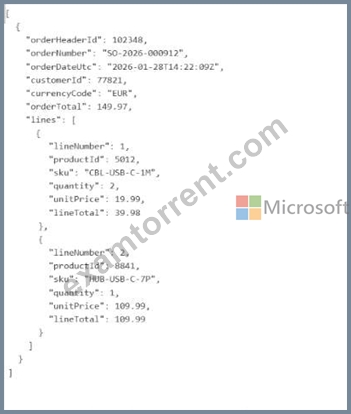
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.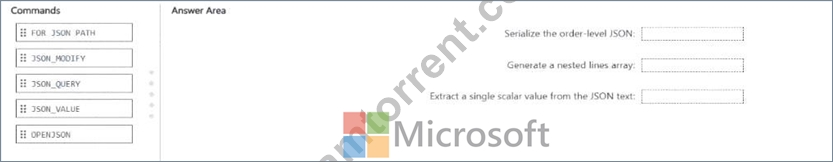
Answer:
Explanation: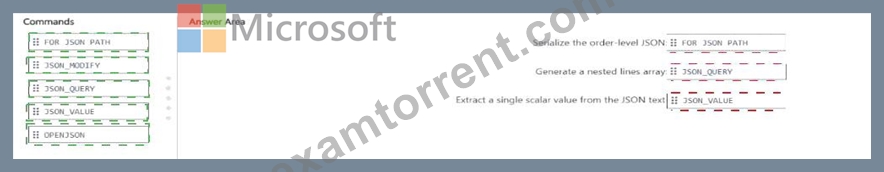
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 83
Hotspot Question
You have an Azure SQL database that contains a table named knowledge_base.
knowledge_base stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_profiles and benefits_enrollment that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.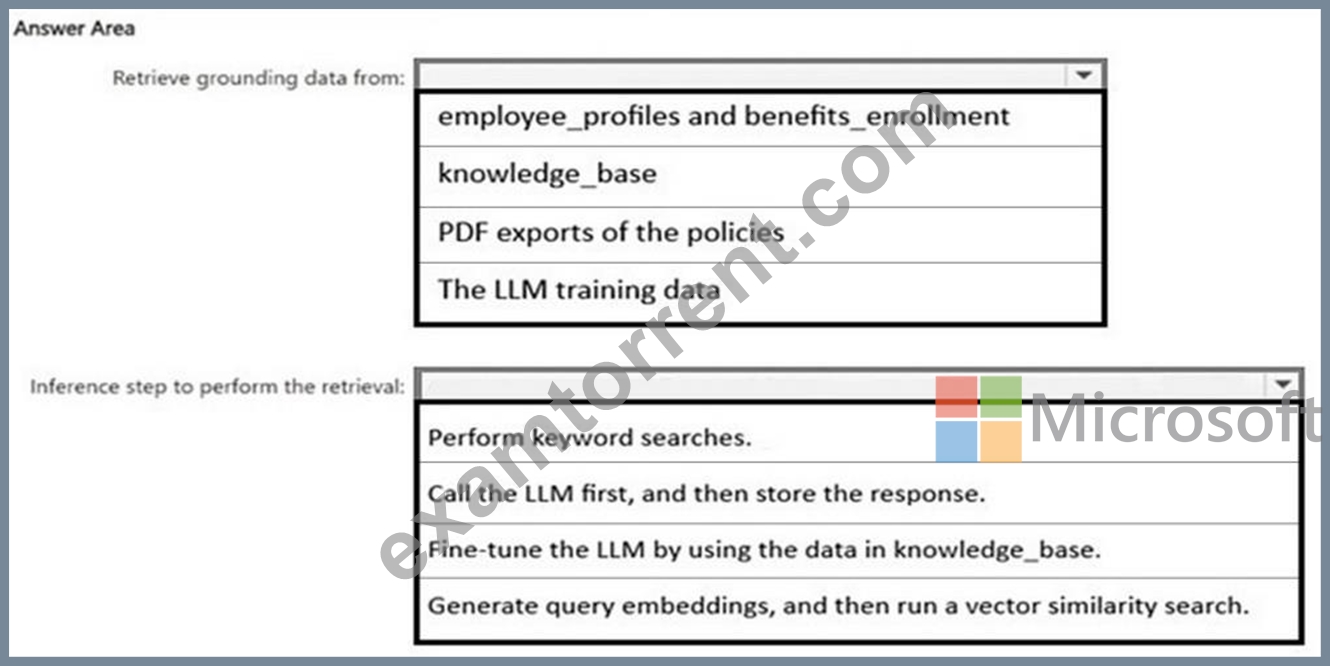
Answer:
Explanation: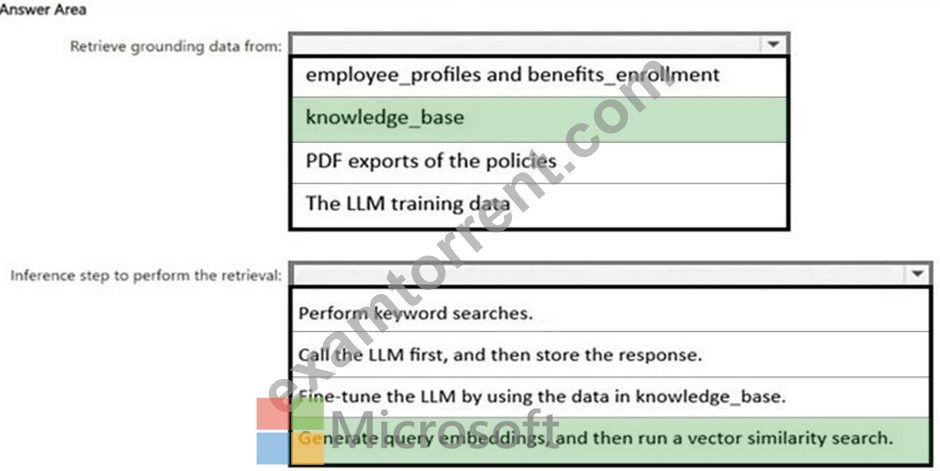
NEW QUESTION # 84
You have an Azure SQL database that contains a table named dbo.orders, dbo.orders contains a column named createDate that stores order creation dates.
You need to create a stored procedure that filters Orders by CreateDate for a single calendar day. The solution must be SARGable.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.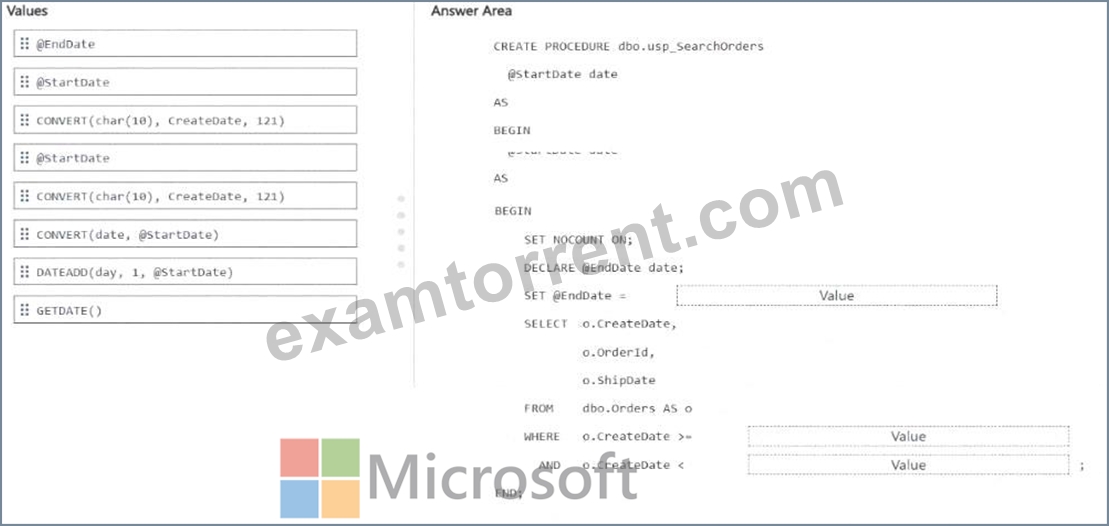
Answer:
Explanation: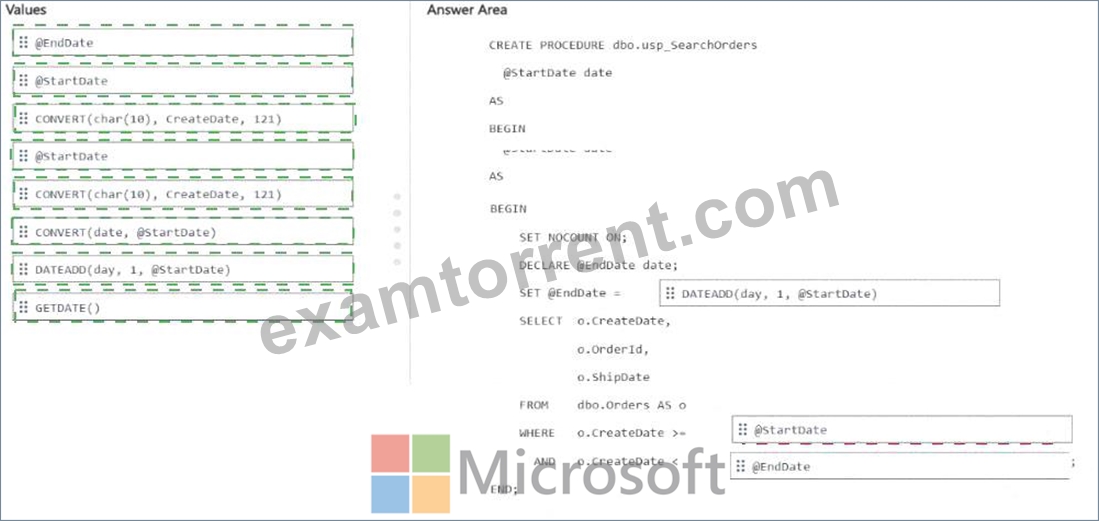
Explanation: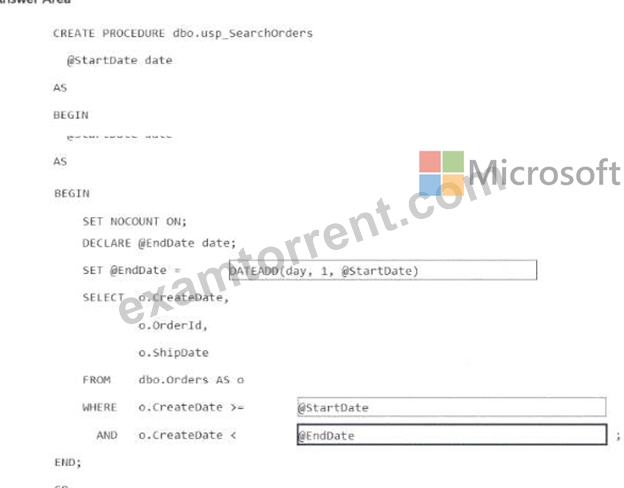
The correct SARGable pattern for filtering a single calendar day is to use a half-open date range :
o.CreateDate > = @StartDate
AND o.CreateDate < @EndDate
with:
SET @EndDate = DATEADD(day, 1, @StartDate)
This is the correct design because it keeps the function off the column and applies it only to the parameter.
That allows SQL Server and Azure SQL to use an index on CreateDate efficiently, which is the key requirement for a SARGable predicate. Microsoft documents DATEADD as the standard function for adding one day to a date value, which makes it the right way to derive the exclusive upper boundary for the next day.
The incorrect choices are the ones that wrap CreateDate in CONVERT(...), because expressions like:
CONVERT(char(10), CreateDate, 121) = ...
make the predicate non-SARGable and typically prevent efficient seeks on an index over CreateDate.
So the completed procedure is:
CREATE PROCEDURE dbo.usp_SearchOrders
@StartDate date
AS
BEGIN
SET NOCOUNT ON;
DECLARE @EndDate date;
SET @EndDate = DATEADD(day, 1, @StartDate);
SELECT o.CreateDate,
o.OrderId,
o.ShipDate
FROM dbo.Orders AS o
WHERE o.CreateDate > = @StartDate
AND o.CreateDate < @EndDate;
END;
NEW QUESTION # 85
......
Today, the prevailing belief is that knowledge is stepping-stone to success. By discarding outmoded beliefs, our DP-800 exam materials are update with the requirements of the authentic exam. To embrace your expectations and improve your value during your review, you can take joy and challenge theDP-800 Exam may bring you by the help of our DP-800 guide braindumps. You will be surprised by the high-effective of our DP-800 study guide!
Reliable Study DP-800 Questions: https://www.examtorrent.com/DP-800-valid-vce-dumps.html
2026 Latest ExamTorrent DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1NktSFP4hDGZxgQynWC4JgPnsDqAg4Huf