2026 Latest Free4Torrent Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1tvxND5-Z_PEb3G6IGhGjVN7TFac8O48M
Using Professional-Machine-Learning-Engineer exam guide allows you to learn without any obstacles anytime and anywhere. All Professional-Machine-Learning-Engineer exam materials in the platform include PDF, PC test engine, and APP test engine three modes. Among them, the PDF version of learning materials is easy to download and print into a paper version for practice and easy to take notes; PC version of Professional-Machine-Learning-Engineer training torrent can imitate real test environment and conduct time-limited testing, and the system will automatically score for you after the test; and APP version of Professional-Machine-Learning-Engineer exam guide supports any electronic device.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Certificate Validity Period: | 2 years |
| Exam Price: | $200 USD |
| Real Exam Qty: | Approximately 50–60 questions |
| Exam Duration: | 120 minutes |
| Available Languages: | Japanese, English |
| Related Certifications: | Google Cloud Professional Cloud Architect Google Cloud Professional Data Engineer Google Cloud Associate Cloud Engineer |
| Exam Format: | Multiple choice, Multiple select, Case study |
| Recommended Training: | Google Cloud Skills Boost - Machine Learning Engineer Path Vertex AI Documentation |
| Exam Registration: | Kryterion Webassessor Google Cloud Certification Portal |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online proctored exam or in-person testing via Kryterion test centers. |
| Pre Condition: | No formal prerequisites required, but 3+ years of industry experience in ML/AI and familiarity with Google Cloud Platform are strongly recommended. |
| Official Syllabus URL: | https://cloud.google.com/certification/machine-learning-engineer |
>> Exam Professional-Machine-Learning-Engineer Answers <<
Our clients come from all around the world and our company sends the products to them quickly. The clients only need to choose the version of the product, fill in the correct mails and pay for our Google Professional Machine Learning Engineer guide dump. Then they will receive our mails in 5-10 minutes. Once the clients click on the links they can use our Professional-Machine-Learning-Engineer Study Materials immediately. If the clients can’t receive the mails they can contact our online customer service and they will help them solve the problem. Finally the clients will receive the mails successfully. The purchase procedures are simple and the delivery of our Professional-Machine-Learning-Engineer study tool is fast.
The following will be discussed in Google Professional-Machine-Learning-Engineer Exam Dumps:
NEW QUESTION # 358
You deployed an ML model into production a year ago. Every month, you collect all raw requests that were sent to your model prediction service during the previous month. You send a subset of these requests to a human labeling service to evaluate your model's performance. After a year, you notice that your model's performance sometimes degrades significantly after a month, while other times it takes several months to notice any decrease in performance. The labeling service is costly, but you also need to avoid large performance degradations. You want to determine how often you should retrain your model to maintain a high level of performance while minimizing cost. What should you do?
Answer: B
Explanation:
The best option for determining how often to retrain your model to maintain a high level of performance while minimizing cost is to run training-serving skew detection batch jobs every few days. Training-serving skew refers to the discrepancy between the distributions of the features in the training dataset and the serving data. This can cause the model to perform poorly on the new data, as it is not representative of the data that the model was trained on. By running training-serving skew detection batch jobs, you can monitor the changes in the feature distributions over time, and identify when the skew becomes significant enough to affect the model performance. If skew is detected, you can send the most recent serving data to the labeling service, and use the labeled data to retrain your model. This option has the following benefits:
* It allows you to retrain your model only when necessary, based on the actual data changes, rather than on a fixed schedule or a heuristic. This can save you the cost of the labeling service and the retraining process, and also avoid overfitting or underfitting your model.
* It leverages the existing tools and frameworks for training-serving skew detection, such as TensorFlow Data Validation (TFDV) and Vertex Data Labeling. TFDV is a library that can compute and visualize descriptive statistics for your datasets, and compare the statistics across different datasets. Vertex Data Labeling is a service that can label your data with high quality and low latency, using either human labelers or automated labelers.
* It integrates well with the MLOps practices, such as continuous integration and continuous delivery (CI
/CD), which can automate the workflow of running the skew detection jobs, sending the data to the labeling service, retraining the model, and deploying the new model version.
The other options are less optimal for the following reasons:
* Option A: Training an anomaly detection model on the training dataset, and running all incoming requests through this model, introduces additional complexity and overhead. This option requires building and maintaining a separate model for anomaly detection, which can be challenging and time- consuming. Moreover, this option requires running the anomaly detection model on every request, which can increase the latency and resource consumption of the prediction service. Additionally, this option may not capture the subtle changes in the feature distributions that can affect the model performance, as anomalies are usually defined as rare or extreme events.
* Option B: Identifying temporal patterns in your model's performance over the previous year, and creating a schedule for sending serving data to the labeling service for the next year, introduces additional assumptions and risks. This option requires analyzing the historical data and model performance, and finding the patterns that can explain the variations in the model performance over time. However, this can be difficult and unreliable, as the patterns may not be consistent or predictable, and may depend on various factors that are not captured by the data. Moreover, this option requires creating a schedule based on the past patterns, which may not reflect the future changes in the data or the environment. This can lead to either sending too much or too little data to the labeling service, resulting in either wasted cost or degraded performance.
* Option C: Comparing the cost of the labeling service with the lost revenue due to model performance degradation over the past year, and adjusting the frequency of model retraining accordingly, introduces additional challenges and trade-offs. This option requires estimating the cost of the labeling service and the lost revenue due to model performance degradation, which can be difficult and inaccurate, as they may depend on various factors that are not easily quantifiable or measurable. Moreover, this option requires finding the optimal balance between the cost and the performance, which can be subjective and variable, as different stakeholders may have different preferences and expectations. Furthermore, this option may not account for the potential impact of the model performance degradation on other aspects of the business, such as customer satisfaction, retention, or loyalty.
NEW QUESTION # 359
Your company manages a video sharing website where users can watch and upload videos. You need to create an ML model to predict which newly uploaded videos will be the most popular so that those videos can be prioritized on your company's website. Which result should you use to determine whether the model is successful?
Answer: B
Explanation:
In this scenario, the goal is to create an ML model to predict which newly uploaded videos will be the most popular on a video sharing website. The result that should be used to determine whether the model is successful is the one that best aligns with the business objective and the evaluation metric. Option C is the correct answer because it defines the most popular videos as the ones that have the highest watch time within
30 days of being uploaded, and it sets a high accuracy threshold of 95% for the model prediction.
Option C: The model predicts 95% of the most popular videos measured by watch time within 30 days of being uploaded. This option is the best result for the scenario because it reflects the business objective and the evaluation metric. The business objective is to prioritize the videos that will attract and retain the most viewers on the website. The watch time is a good indicator of the viewer engagement and satisfaction, as it measures how long the viewers watch the videos. The 30-day window is a reasonable time frame to capture the popularity trend of the videos, as it accounts for the initial interest and the viral potential of the videos.
The 95% accuracy threshold is a high standard for the model prediction, as it means that the model can correctly identify 95 out of 100 of the most popular videos based on the watch time metric.
Option A: The model predicts videos as popular if the user who uploads them has over 10,000 likes. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the users who upload them. The number of likes that a user has is not a good indicator of the popularity of their videos, as it does not measure the viewer engagement or satisfaction with the videos. Moreover, this option does not specify a time frame or an accuracy threshold for the model prediction, making it vague and unreliable.
Option B: The model predicts 97.5% of the most popular clickbait videos measured by number of clicks. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the videos that have the most misleading or sensational titles or thumbnails. The number of clicks that a video has is not a good indicator of the popularity of the video, as it does not measure the viewer engagement or satisfaction with the video content. Moreover, this option only focuses on the clickbait videos, which may not represent the majority or the diversity of the videos on the website.
Option D: The Pearson correlation coefficient between the log-transformed number of views after 7 days and
30 days after publication is equal to 0. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the videos that have the most consistent or inconsistent number of views over time. The Pearson correlation coefficient is a metric that measures the linear relationship between two variables, not the popularity of the videos. A correlation coefficient of 0 means that there is no linear relationship between the log-transformed number of views after 7 days and 30 days, which does not indicate whether the videos are popular or not. Moreover, this option does not specify a threshold or a target value for the correlation coefficient, making it meaningless and irrelevant.
NEW QUESTION # 360
You are building an ML model to detect anomalies in real-time sensor dat a. You will use Pub/Sub to handle incoming requests. You want to store the results for analytics and visualization. How should you configure the pipeline?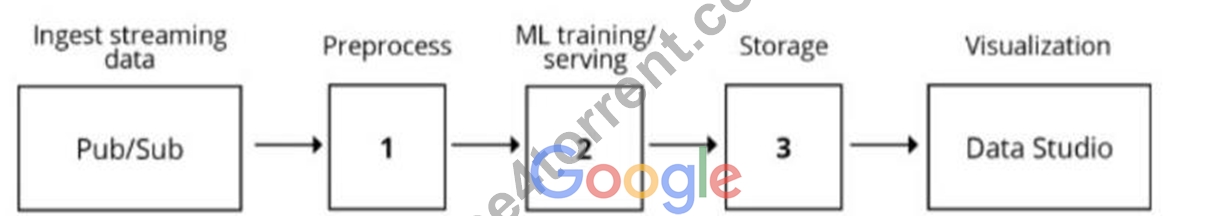
Answer: D
NEW QUESTION # 361
Your company stores a large number of audio files of phone calls made to your customer call center in an on- premises database. Each audio file is in wav format and is approximately 5 minutes long. You need to analyze these audio files for customer sentiment. You plan to use the Speech-to-Text API. You want to use the most efficient approach. What should you do?
Answer: C
Explanation:
According to the official exam guide 1 , one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". The Speech-to- Text API 2 allows you to convert audio to text by applying powerful neural network models. The Natural Language API 3 enables you to analyze text and extract information about the sentiment, entities, and syntax. The Cloud Functions 4 service lets you write and deploy code that runs in response to events, such as a Pub/Sub message or an HTTP request. Therefore, option B is the most efficient approach to analyze the audio files for customer sentiment, as it leverages the existing Google Cloud services and avoids unnecessary data processing and model training. The other options are not relevant or optimal for this scenario.
References :
* Professional ML Engineer Exam Guide
* Speech-to-Text API
* Natural Language API
* Cloud Functions
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 362
You are an ML engineer at a manufacturing company. You need to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. You want your model to preprocess the images with lower computation to quickly extract features of defects in products. Which approach should you use to build the model?
Answer: C
Explanation:
* Option A is incorrect because reinforcement learning is not a suitable approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. Reinforcement learning is a type of machine learning that learns from its own actions and rewards, rather than from labeled data or explicit feedback1. Reinforcement learning is more suitable for problems that involve sequential decision making, such as games, robotics, or control systems1.
However, defect detection is a problem that involves image classification or segmentation, which requires supervised learning, not reinforcement learning.
* Option B is incorrect because a recommender system is not a relevant approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. A recommender system is a system that suggests items or actions to users based on their preferences, behavior, or context2. A recommender system is more suitable for problems that involve personalization, such as e-commerce, entertainment, or social media2. However, defect detection is a problem that involves image classification or segmentation, which requires supervised learning, not recommender system.
* Option C is incorrect because recurrent neural networks (RNN) are not the most efficient approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. RNNs are a type of neural networks that can process sequential data, such as text, speech, or video, by maintaining a hidden state that captures the temporal dependencies3. RNNs are more suitable for problems that involve natural language processing, speech recognition, or video analysis3.
However, defect detection is a problem that involves image classification or segmentation, which does not require temporal dependencies, but rather spatial dependencies. Moreover, RNNs are computationally expensive and prone to vanishing or exploding gradients4.
* Option D is correct because convolutional neural networks (CNN) are the best approach to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. CNNs are a type of neural networks that can process image data, by applying convolutional filters that extract local features and reduce the dimensionality of the data5. CNNs are more suitable for problems that involve image classification, object detection, or segmentation5. CNNs can preprocess the images with lower computation to quickly extract features of defects in products, by using techniques such as pooling, dropout, or batch normalization6.
References:
* Reinforcement learning
* Recommender system
* Recurrent neural network
* Vanishing and exploding gradients
* Convolutional neural network
* CNN techniques
* [Defect detection]
* [Image classification]
* [Image segmentation]
NEW QUESTION # 363
......
Reliable Professional-Machine-Learning-Engineer Dumps Pdf: https://www.free4torrent.com/Professional-Machine-Learning-Engineer-braindumps-torrent.html
What's more, part of that Free4Torrent Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1tvxND5-Z_PEb3G6IGhGjVN7TFac8O48M