Once you purchase the AI-200 exam dumps from TroytecDumps you can use it in three forms Microsoft PDF Questions format, web-based software, and desktop Microsoft AI-200 practice test. Candidates can use Developing AI Cloud Solutions on Azure pdf questions file on their mobiles, laptop tablets, or any other device. Candidates can install the AI-200 Practice Exam software on their desktops to attempt the Microsoft AI-200 practice test even when they are offline.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
Whereas the AI-200 PDF file is concerned this file is the collection of real, valid, and updated Microsoft AI-200 exam questions. You can use the Microsoft AI-200 PDF format on your desktop computer, laptop, tabs, or even on your smartphone and start Developing AI Cloud Solutions on Azure (AI-200) exam questions preparation anytime and anywhere.
NEW QUESTION # 67
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: C
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 68
You maintain multiple versions of a container image in Azure Container Registry.
The production deployment must always run the exact same image build even if tags are changed later.
You need to ensure predictable and immutable image selection during deployment.
What should you do?
Answer: D
Explanation:
Use the image ' s SHA-256 manifest digest when defining the production deployment. Azure Container Registry assigns every pushed image manifest a unique digest, and Microsoft explicitly states that pulling an image by digest guarantees the image version being retrieved , even if an identically named tag is later pushed to a different image. A digest reference has the form myregistry.azurecr.io/repository@sha256: < digest > .
Tags such as production or latest are mutable references . By default, a user or pipeline with sufficient permissions can push a different image under the same tag. Microsoft therefore warns against relying on reusable stable tags for production deployments when exact image reproducibility is required.
A scheduled rebuild also creates a new image artifact and therefore cannot guarantee that production executes the original build. In contrast, the manifest digest is content-addressed and resolves to the precise image manifest selected at deployment time.
Thus, for deterministic and immutable production image selection, reference the container image by its SHA digest rather than by a mutable tag .
Study Guide references: Azure Container Registry # image manifests and digests; image addressing; tagging
/versioning recommendations; immutable deployment references.
NEW QUESTION # 69
Drag and Drop Question
You are building a back-end pipeline that receives AI inference requests.
The pipeline must perform the following actions:
- Publish a message so that multiple independent consumers receive it.
- Process messages in first-in, first-out (FIFO) order.
- Isolate any failed messages.
You need to configure the appropriate Service Bus entities.
How should you configure the Service Bus entities? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.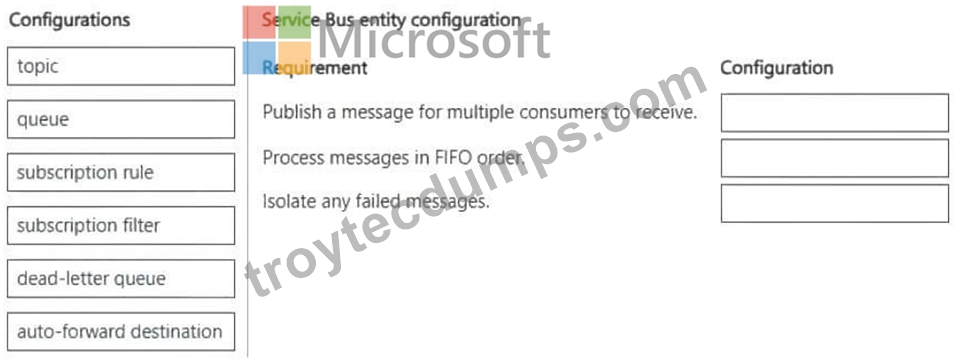
Answer:
Explanation: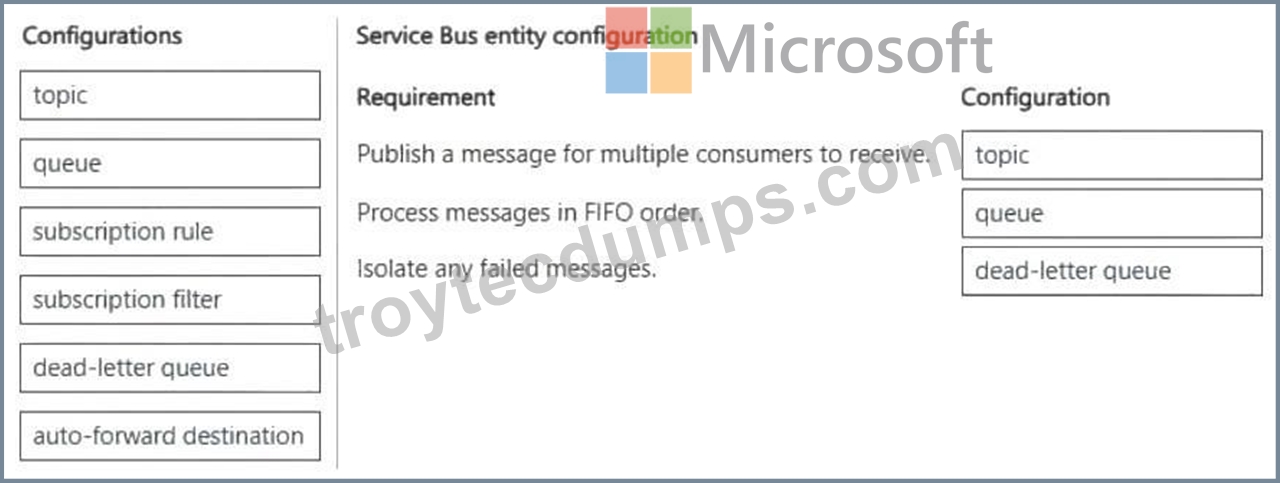
Explanation:
Box 1: topic
You should use an Azure Service Bus Topic to publish the message.
In a pub/sub architecture, the topic acts as the single destination where the sender publishes the message.
Box 2: queue
You should use a dedicated FIFO queue for this purpose.
While a standard queue allows parallel processing that can disrupt the arrival order, a strict FIFO (First-In, First-Out) queue guarantees that your AI inference requests are processed in the exact order they are received.
Order Preservation: Standard message queues only guarantee "best-effort" ordering. FIFO queues ensure strict sequential processing.
Exactly-Once Processing: FIFO queues inherently prevent duplicate message delivery. This prevents running the same costly AI inference twice.
Concurrency Control: You can limit or throttle consumers. This prevents overwhelming your AI models or GPUs.
Box 3: dead-letter queue
A dead-letter queue (DLQ) is the exact industry-standard pattern and correct architectural choice to isolate failed messages in an AI inference pipeline. It captures messages that fail processing repeatedly due to errors like model timeouts, malformed input payloads, or downstream GPU memory crashes.
Prevents Blockages: Stops bad requests from clogging the main queue and halting pipeline throughput.
Enables Debugging: Preserves the exact failed payload and error metadata for post-mortem analysis.
Protects Resources: Keeps infrastructure from getting stuck in endless retry loops on broken data.
Reference:
https://wearenotch.com/blog/azure-service-bus-tips-to-optimize-functions/
NEW QUESTION # 70
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by using a parameterized query. You must minimize the possibility of SQL injection.
How should you update the implementation to execute the SQL statement safely? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. you may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.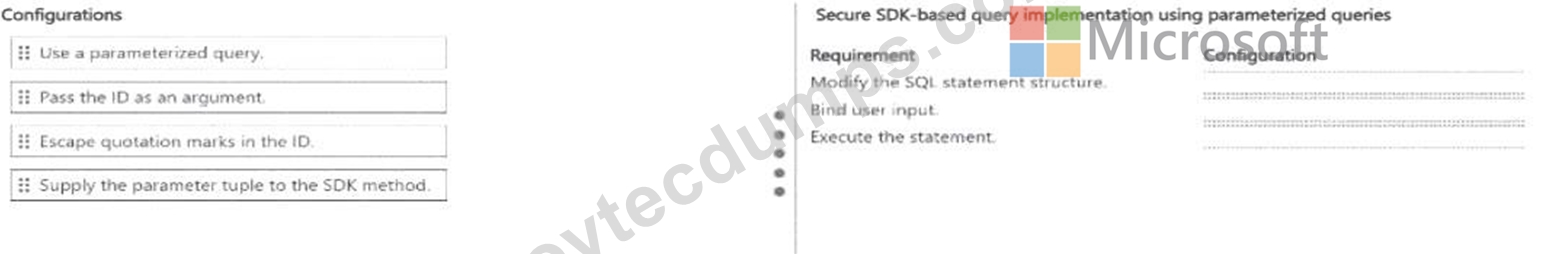
Answer:
Explanation: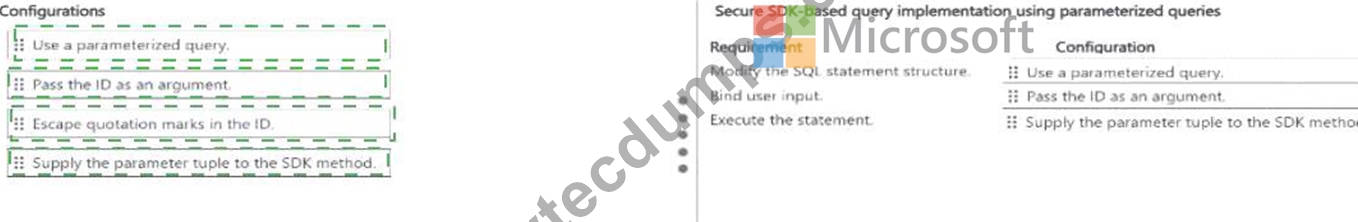
Explanation: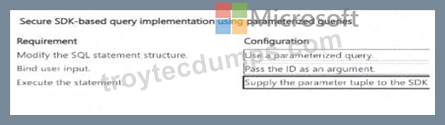
Verified Answer: Modify SQL: use a parameterized query. Bind input: pass the ID as an argument. Execute:
supply the parameter tuple to the SDK/driver method.
Detailed Explanation: The security boundary is created by separating SQL syntax from user-supplied values.
The statement should contain a parameter placeholder rather than concatenated input, and the document ID should be supplied separately through the database driver's parameter mechanism. The driver then performs the correct protocol-level binding and escaping. Manually escaping quotation marks is error-prone and does not provide the same injection resistance as true parameterization.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 71
You are using Azure Monitor Application Insights to collect dependency data.
You must be able to:
* Correlate failed requests with dependency calls during the last hour.
* Calculate the average dependency duration per operation.
You need to construct the KQL query by using the minimum number of statements.
Which three operators should you use? Each correct answer presents part of the solution.
Answer: A,B,C
Explanation:
Use where , join , and summarize .
The where operator filters telemetry to the required scope, including records from the last hour and failed requests. For example, a predicate can restrict timestamp > ago(1h) and request success status in the same filtering expression.
Next, use join to correlate request telemetry with dependency telemetry. Application Insights assigns related telemetry a common operation_Id , and Microsoft specifically demonstrates joining the dependencies and requests tables on operation_Id to identify dependency calls associated with requests.
Finally, use summarize with avg(duration) grouped by the appropriate operation identifier or operation name.
summarize performs aggregation over groups and is therefore the required operator for calculating average dependency duration. Microsoft documents dependency duration as supporting an Avg aggregation.
extend is unnecessary because no derived column is required, while distinct merely removes duplicate rows and cannot calculate averages or correlate two telemetry tables.
A representative structure is:
requests
| where timestamp > ago(1h) and success == false
| join (dependencies | where timestamp > ago(1h)) on operation_Id
| summarize avg_dependency_duration = avg(duration1) by operation_Name
Study Guide references: Azure Monitor Application Insights; KQL where; telemetry correlation using operation_Id; join; summarize; dependency duration analysis.
NEW QUESTION # 72
......
If you are still worried about your exam, our exam dumps may be your good choice. Our Microsoft AI-200 training dumps cover many real test materials so that if you master our dumps questions and answers you can clear exams successfully. Don't worry over trifles. If you purchase our Microsoft AI-200 training dumps you can spend your time on more significative work.
Latest AI-200 Dumps Free: https://www.troytecdumps.com/AI-200-troytec-exam-dumps.html