您可以先在網上下載VCESoft為你免費提供的關於Microsoft AI-103認證考試的練習題及答案作為嘗試,之後你會覺得VCESoft給你通過考試提供了一顆定心丸。選擇VCESoft為你提供的針對性培訓,你可以很輕鬆通過Microsoft AI-103 認證考試。
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Implement agentic solutions | 20-25% | - Build AI agents
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
AI-103考古題被大多數考生證明是有效的,通過很多IT認證考試的考生使用之后得出,能使考生在短時間內掌握最新的Microsoft AI-103考試相關知識。由高級認證專家不斷完善出最新版的AI-103考古題資料,他們的研究結果可以100%保證您成功通過AI-103考試,獲得認證,這是非常有效的題庫資料。一些通過AI-103考試的考生成為了我們的回頭客,他們說選擇VCESoft就意味著選擇成功。
問題 #87
You have an Azure subscription that contains an Azure Language in Foundry Tools service resource. You need to identify the URL of the REST interface for the Language service. Which blade should you use in the Azure portal?
答案:C
解題說明:
The Keys and Endpoint blade displays the resource-specific endpoint URL used to construct REST API requests to Azure Language in Foundry Tools. It also provides the resource access keys when local key-based authentication is enabled. Microsoft's Azure Language documentation directs administrators to open the resource in the Azure portal and select Keys and Endpoint from the left menu to obtain the endpoint and credentials required for API calls.
The endpoint normally forms the base URI for the service. The application appends the operation-specific route and API version required by features such as sentiment analysis, named entity recognition, entity linking, or conversational language understanding. The key may then be supplied in the request's authentication header, although Microsoft Entra ID and managed identities are recommended for supported production workloads because they avoid embedding secrets in application code.
The Networking blade controls public access, firewalls, virtual networks, and private endpoints. Identity manages the resource's managed identity. Properties presents general resource metadata but is not the designated location for retrieving the REST API endpoint and access keys.
Study Guide alignment: plan and manage Azure AI resources, configure service access, and integrate Foundry Tools through their APIs and authentication mechanisms .
問題 #88
You have a Microsoft Foundry project that contains an agent.
The agent ingests scanned PDF vendor invoices that contain tables and embedded QR codes.
The agent must preserve the PDF layout in the extracted output to ensure that downstream processing can reference sections and tables.
You plan to call Azure Content Understanding in Foundry Tools.
You need to extract content and layout elements and detect QR codes without requiring a language model deployment.
Which built-in analyzer should you use?
答案:C
解題說明:
To extract content, preserve tables and document layout, and detect embedded QR codes without deploying a large language model (LLM), you should use the built-in prebuilt-layout analyzer.
Note:
Unlike schema-driven extraction models in Content Understanding that utilize generative AI orchestration, the Layout analyzer is a highly efficient machine-learning-based model. It natively outputs structural geometry and decodes barcodes without requiring an active LLM deployment or provisioned throughput.
Structural Preservation: It extracts headers, paragraphs, and nested sections, returning precise spatial bounding boxes for every single element. Downstream agents can utilize this geometric metadata to anchor or cross-reference sections accurately.
Advanced Table Mapping: It maps intricate, multi-page invoice tables, capturing text alongside row and column indices. You can configure the output structure format natively into Markdown or HTML tables to maintain formatting cleanliness.
Built-in QR and Barcode Decoding: By default, the configuration parameter enableBarcode is set to true. The analyzer scans the scanned PDF image, isolates 2D code regions, and appends the decoded string payload into the output JSON alongside text blocks.
Zero LLM Dependency: It does not route text to foundational models like GPT-4o for its extraction, keeping processing latency low and lowering operational costs significantly.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/quickstart/content-understanding-studio
問題 #89
You have a Microsoft Foundry project that contains a deployed chat model.
You have a Python service that sends API requests to the model. The service is integrated with an automated validation system that compares generated outputs against approved response patterns.
Stakeholders report that small wording differences are causing validation mismatches.
You need to update the request parameters to improve output stability. The solution must maximize reasoning quality.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.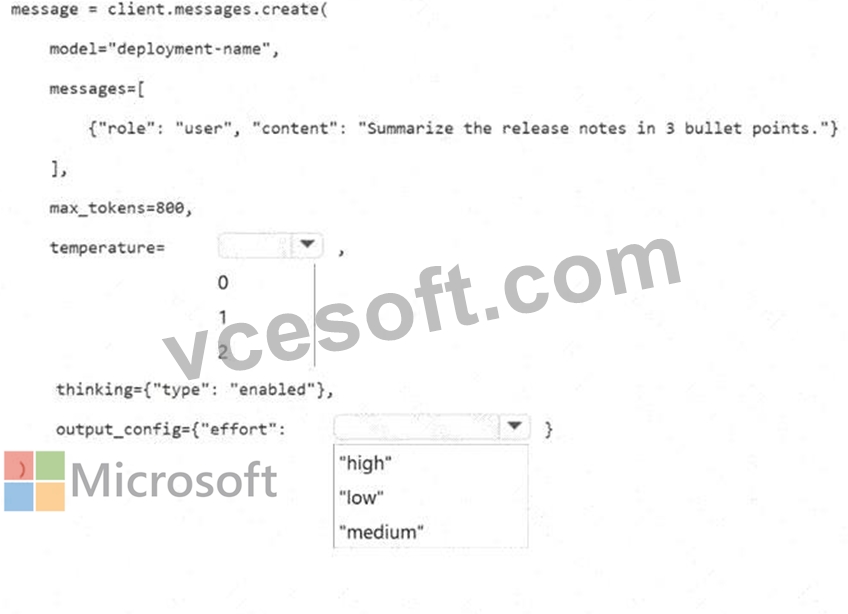
答案:
解題說明: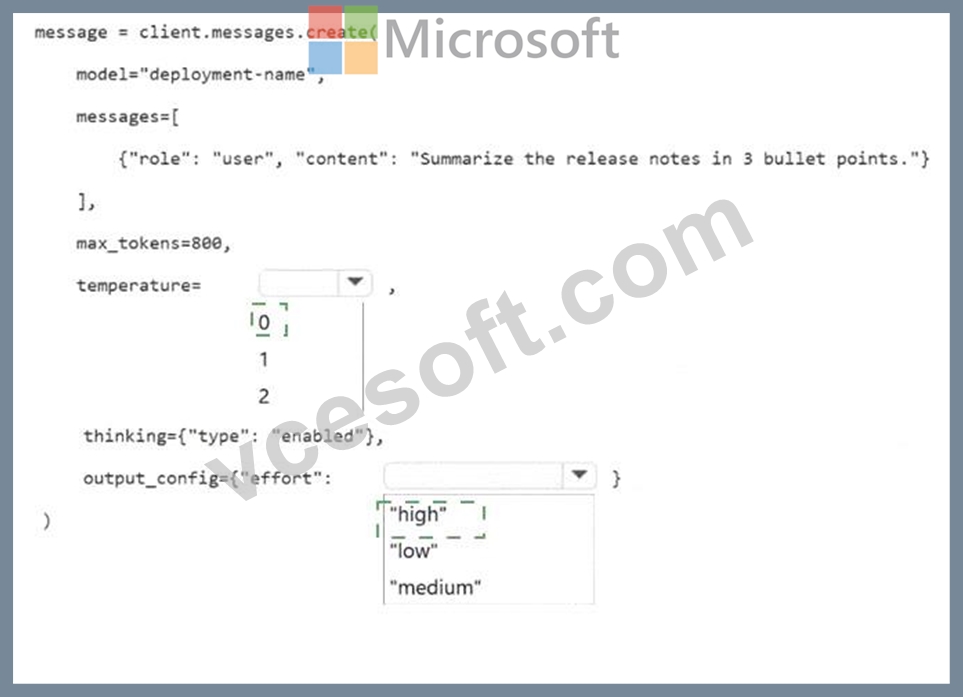
Explanation:
temperature = 0
output_config = { " effort " : " high " }
The correct configuration is temperature = 0 and output_config = { " effort " : " high " }. The requirement is to reduce small wording variations that are breaking automated validation. In chat completion requests, temperature controls sampling randomness. Microsoft's Azure OpenAI reference states that temperature ranges between 0 and 2, and that higher values make output more random while lower values make output more focused and deterministic. Therefore, the most stable setting from the available choices is 0, because it minimizes randomness and improves repeatability for validation-sensitive response patterns.
The solution must also maximize reasoning quality. The code already enables thinking with thinking={ " type
" : " enabled " }, so the remaining reasoning-quality control is the effort setting. Microsoft Foundry model guidance states that the effort parameter controls the quality/cost tradeoff and supports low, medium, and high effort levels. Selecting " high " maximizes reasoning quality among the available options.
Using temperature values of 1 or 2 would increase variability and make validation mismatches more likely.
Selecting low or medium effort would not meet the requirement to maximize reasoning quality. Reference topics: Microsoft Foundry model inference, chat model parameters, temperature, thinking, effort, and output stability.
問題 #90
A copilot must answer multi-part questions that depend on earlier turns in the conversation. You want the system to break each complex question into focused subqueries, run them in parallel, and semantically rerank the results before composing an answer. Which Azure AI Search capability provides this?
答案:A
解題說明:
Agentic retrieval in Azure AI Search uses a large language model to decompose a complex query into focused subqueries, runs them in parallel, semantically reranks each set of results, and merges them into a unified response, while taking conversation history into account. That is precisely the behaviour the scenario describes.
問題 #91
You have a custom agent named Agent1.
You need to control access to and monitor activity for Agent1 by using Microsoft Foundry.
What should you do first?
答案:D
問題 #92
......
你現在十分需要與AI-103認證考試相關的歷年考試問題集和考試參考書吧?每天忙於工作,你肯定沒有足夠的時間準備考試吧。所以,你很有必要選擇一個高效率的考試參考資料。當然,最重要的是要選一個適合自己的工具來更好地準備考試,這是一個與你是否可以順利通過考試相關的問題。所以,VCESoft的AI-103考古題吧。
最新AI-103考證: https://www.vcesoft.com/AI-103-pdf.html