100% Pass Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Newest Updated Demo

Do you eager to find the ideal job? Do you eager to pass the Certified-Data-Engineer-Professional exam easily? If you want to, then you have arrived right place now. We provide authentic exam materials for Certified-Data-Engineer-Professional exam, and we can make your exam preparation easy with our study material various quality features. With the guidance of no less than seasoned professionals, we have formulated updated actual questions for exams, over the years. By practicing our Certified-Data-Engineer-Professional study materials, you are reducing your chances for failure exam. What’s more, we will give all candidates who purchased our material a guarantee that they will pass the Certified-Data-Engineer-Professional Exam on their very first try. If we fail to deliver our promise, we will give candidates full refund. There are thousands of candidates choose to trusted us and got paid. So, if you really eager to pass the exam, our Certified-Data-Engineer-Professional study materials must be your best choice.
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 2: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Use APPLY CHANGES APIs for change data capture
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare streaming tables and materialized views
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 8. Develop unit and integration tests for data processing code
|
| Topic 4: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 5: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 6: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 7: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 8: Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
>> Updated Certified-Data-Engineer-Professional Demo <<
One of the Best Ways to Prepare For the Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Exam
If you buy Dumpkiller exam dumps, you will obtain free update for a year. Once the dumps update, Dumpkiller will immediately send the latest Certified-Data-Engineer-Professional Certification Certified-Data-Engineer-Professional training materials to your mailbox. You can also request we provide you with the latest dumps at any time. If you want to know the latest exam questions, even if you have passed the certification test, Dumpkiller will also free update exam dumps for you.
Databricks Certified Data Engineer Professional Sample Questions (Q179-Q184):
NEW QUESTION # 179
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Use a foreach task with a list of report types as its inputs.
- B. Define ten Notebook tasks to clearly track which report download failed.
- C. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- D. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
Answer: A
Explanation:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
NEW QUESTION # 180
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. Delta Lake statistics are not optimized for free text fields with high cardinality.
- B. Delta Lake statistics are only collected on the first 4 columns in a table.
- C. Text data cannot be stored with Delta Lake.
- D. ZORDER ON review will need to be run to see performance gains.
- E. The Delta log creates a term matrix for free text fields to support selective filtering.
Answer: A
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 181
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- B. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- D. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- E. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
Answer: C
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 182
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
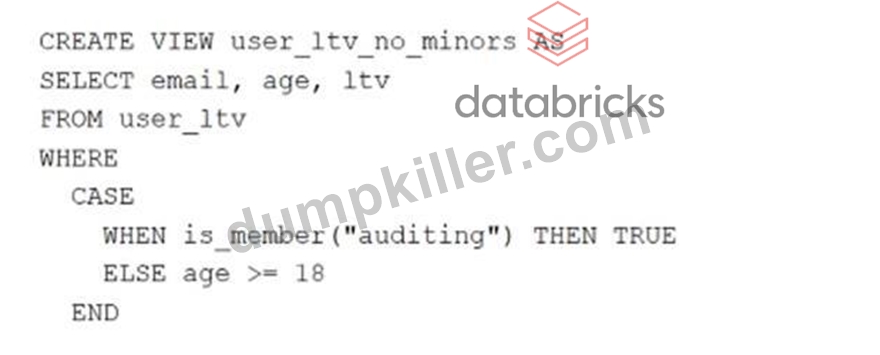
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All records from all columns will be displayed with the values in user_ltv.
- B. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- C. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
- D. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- E. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
Answer: D
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 183
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
- A. Tasks B and C will be skipped; task A will not commit any changes because of stage failure.
- B. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until all tasks have successfully been completed.
- C. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task A failed, all commits will be rolled back automatically.
- D. Tasks B and C will attempt to run as configured; any changes made in task A will be rolled back due to task failure.
- E. Tasks B and C will be skipped; some logic expressed in task A may have been committed before task failure.
Answer: E
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running.
NEW QUESTION # 184
......
Our Certified-Data-Engineer-Professional study materials have a high quality which is mainly reflected in the pass rate. Our product can promise a higher pass rate than other study materials. 99% people who have used our Certified-Data-Engineer-Professional study materials passed their exam and got their certificate successfully, it is no doubt that it means our Certified-Data-Engineer-Professional study materials have a 99% pass rate. So our product will be a very good choice for you. If you are anxious about whether you can pass your exam and get the certificate, we think you need to buy our Certified-Data-Engineer-Professional Study Materials as your study tool, our product will lend you a good helping hand. If you are willing to take our Certified-Data-Engineer-Professional study materials into more consideration, it must be very easy for you to pass your exam in a short time.
Pass4sure Certified-Data-Engineer-Professional Pass Guide: https://www.dumpkiller.com/Certified-Data-Engineer-Professional_braindumps.html
- Certified-Data-Engineer-Professional Dumps PDF Format Practice Test 🤘 Open 《 www.prepawayete.com 》 and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free ❣Certified-Data-Engineer-Professional Latest Test Testking
- Certified-Data-Engineer-Professional Dumps PDF Format Practice Test 👔 Open ➥ www.pdfvce.com 🡄 enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 🏨Certified-Data-Engineer-Professional Reliable Test Book
- Experience The Real Databricks Certified-Data-Engineer-Professional Exam With Web-Based Practice Exam Software 🤜 The page for free download of ➠ Certified-Data-Engineer-Professional 🠰 on ▛ www.practicevce.com ▟ will open immediately 🙈Certified-Data-Engineer-Professional Latest Test Testking
- Certified-Data-Engineer-Professional Reliable Braindumps Ebook 🍰 Certified-Data-Engineer-Professional Simulated Test 🔕 Certified-Data-Engineer-Professional Clear Exam 🚛 Search for 《 Certified-Data-Engineer-Professional 》 and download exam materials for free through ▷ www.pdfvce.com ◁ 🦡Certified-Data-Engineer-Professional Valid Exam Question
- Certified-Data-Engineer-Professional Pass Leader Dumps 😟 Certified-Data-Engineer-Professional Answers Free 🏄 Certified-Data-Engineer-Professional Valid Exam Sample 👳 Immediately open ▛ www.examcollectionpass.com ▟ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to obtain a free download 🦋Certified-Data-Engineer-Professional Latest Exam Questions
- Experience The Real Databricks Certified-Data-Engineer-Professional Exam With Web-Based Practice Exam Software 💷 ⇛ www.pdfvce.com ⇚ is best website to obtain 《 Certified-Data-Engineer-Professional 》 for free download 🍭Reliable Certified-Data-Engineer-Professional Cram Materials
- Certified-Data-Engineer-Professional Valid Exam Sample 🏓 Real Certified-Data-Engineer-Professional Braindumps 🦓 Certified-Data-Engineer-Professional Reliable Test Book 🌋 Search for ▶ Certified-Data-Engineer-Professional ◀ and easily obtain a free download on ⏩ www.examcollectionpass.com ⏪ 🗣High Certified-Data-Engineer-Professional Passing Score
- Certified-Data-Engineer-Professional Latest Test Testking 🍑 Certified-Data-Engineer-Professional Valid Exam Question 👸 Certified-Data-Engineer-Professional Test Review 🦅 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free immediately on ▷ www.pdfvce.com ◁ 🔔Certified-Data-Engineer-Professional Dumps Download
- Valid Certified-Data-Engineer-Professional exam dumps ensure you a high Certified-Data-Engineer-Professional passing rate 🟢 Download ▛ Certified-Data-Engineer-Professional ▟ for free by simply searching on ➠ www.troytecdumps.com 🠰 👈Certified-Data-Engineer-Professional Latest Exam Questions
- Certified-Data-Engineer-Professional Dumps PDF Format Practice Test 🚰 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ☀ www.pdfvce.com ️☀️ 🔃Reliable Certified-Data-Engineer-Professional Cram Materials
- Pass Guaranteed 2026 Reliable Certified-Data-Engineer-Professional: Updated Databricks Certified Data Engineer Professional Demo 📞 Easily obtain { Certified-Data-Engineer-Professional } for free download through 【 www.vceengine.com 】 🐥Certified-Data-Engineer-Professional Test Review
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, poi-australia.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes