Databricks-Machine-Learning-Professional指南 & Databricks-Machine-Learning-Professional認證資料

2026 Fast2test最新的Databricks-Machine-Learning-Professional PDF版考試題庫和Databricks-Machine-Learning-Professional考試問題和答案免費分享:https://drive.google.com/open?id=1r4_AaGuBqzxGgGHiGEMX6wCfWVWVnEBV
獲得Databricks-Machine-Learning-Professional認證是IT職業發展有利保证,而Fast2test公司提供最新最準確的Databricks-Machine-Learning-Professional題庫資料,幾乎包含真實考試的所有知識點,借助我們的學習資料,您不必浪費時間去閱讀過多的參考書籍,只需要花費一定的時間去學習我們的Databricks Databricks-Machine-Learning-Professional題庫資料。本站提供PDF版本和軟件本版的Databricks-Machine-Learning-Professional題庫,PDF版本的方便打印,而對于軟件版本的Databricks Databricks-Machine-Learning-Professional題庫可以模擬真實的考試環境,方便考生選擇。
Databricks Databricks-Machine-Learning-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Model Deployment | 10% | - Deployment Strategies
- 1. Batch Deployment
- 2. Real-time Deployment
- 3. Streaming Deployment
- Model Serving
- 1. Databricks Model Serving
- 2. Custom serving solutions
|
| Model Development | 47% | - SparkML and Scaling
- 1. Ray/Optuna distributed tuning
- 2. Building scalable ML pipelines with SparkML
- 3. Distributed training and hyperparameter tuning
- MLflow Advanced Features
- 1. Experiment tracking and model management
- 2. Model registry and versioning
- Feature Store
- 1. Automated feature pipelines
- 2. Feature Store concepts and usage
|
| Model Lifecycle Management (MLOps) | 43% | - Testing Strategies
- 1. Model testing and validation
- 2. Data quality testing
- Automated Workflows
- 1. Automated retraining workflows
- 2. CI/CD pipelines for ML
- Monitoring
- 1. Lakehouse Monitoring for drift detection
- 2. Model performance monitoring
- Environment Management
- 1. Environment configuration and reproducibility
- 2. Databricks Asset Bundles (DABs)
|
>> Databricks-Machine-Learning-Professional指南 <<
Databricks-Machine-Learning-Professional認證資料,Databricks-Machine-Learning-Professional真題
Fast2test提供高品質的最佳學習資料,讓通過Databricks Databricks-Machine-Learning-Professional考試從未如此快速、便宜、和簡單。有了最新詳細的題庫和答案,為您的Databricks-Machine-Learning-Professional考試做好充分的準備,我們將保證您在考試中取得成功。在購買前,您還可以下載我們提供的Databricks-Machine-Learning-Professional免費DEMO來試用,這是非常有效的學習資料。通過客戶的完全信任,我們為考生提供真實有效的訓練,幫助大家在第一次Databricks Databricks-Machine-Learning-Professional考試中順利通過。
最新的 ML Data Scientist Databricks-Machine-Learning-Professional 免費考試真題 (Q175-Q180):
問題 #175
Which of the following is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov-Smirnov (KS) test for numeric feature drift detection?
- A. JS is not normalized or smoothed
- B. JS is more robust when working with large datasets
- C. JS does not require any manual threshold or cutoff determinations
- D. All of these reasons
- E. None of these reasons
答案:B
問題 #176
A data scientist would like to switch from manually using MLflow logging to MLflow Autologging for all machine learning libraries used in a notebook.
They begin by adding mlflow.autolog()to the top of the below code block:
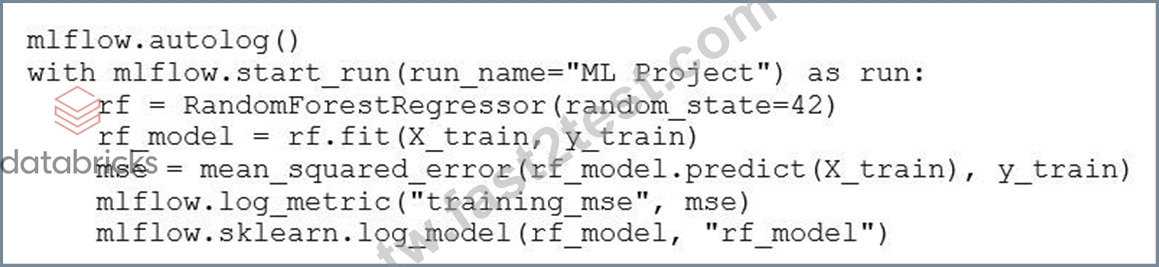
The data scientist is now trying to determine which line of code will kick off the MLflow Autologging process.
Which line of code within the above code block will start the MLflow Autologging process?
- A. rf_model = rf.fit(X_train, y_train)
- B. mlflow.sklearn.log_model(rf_model, "rf_model")
- C. with mlflow.start_run(run_name="ML Project") as run:
- D. mlflow.log_metric("training_mse", mse)
答案:A
解題說明:
The MLflow Autologging process is triggered when a model's training function is called. In this case, rf.fit(X_train, y_train) starts the autologging process because mlflow.autolog() automatically tracks parameters, metrics, and the model when a supported estimator (like RandomForestRegressor) is fitted. The context manager mlflow.start_run() only initiates an MLflow run, but the actual autologging begins during the .fit() execution.
問題 #177
A Machine Learning Engineer wants to monitor the quality and stability of their machine learning model's predictions over time. They have a Delta table, retail_inference_log, which records each model prediction along with input features, a timestamp, and (when available) the true label. They need to detect data drift and monitor model performance trends using Databricks Lakehouse Monitoring, ensuring that alerts are triggered if the distribution of predictions or input features changes significantly. Which approach will set up monitoring for this use case?
- A. Create a monitor with the Inference profile on the retail_inference_log table, and specify a recent batch of production data as the baseline table for drift detection. Use this recent production data to compare against new data for drift and performance monitoring.
- B. Create a monitor with the Time Series profile on the retail_inference_log table, specifying the timestamp column and including model input, prediction columns and the true label column. This will track drift in features and predictions over time, and model performance could also be tracked using a custom metric.
- C. Create a monitor with the Inference profile on the retail_inference_log table, specifying the timestamp column and the columns for model inputs, predictions, and labels. Configure the monitor to compute drift and performance metrics over time windows.
- D. Create a monitor with the Snapshot profile on the retail_inference_log table, so that metrics are calculated over the entire table each time the monitor runs and therefore is able to compare new values with previous ones to compute data drift.
答案:C
解題說明:
The Inference profile is specifically designed for monitoring production inference logs. By configuring it on the inference table with the timestamp, input feature columns, prediction column, and label column, Databricks Lakehouse Monitoring can automatically compute prediction drift, input feature drift, and model performance metrics over rolling time windows, and trigger alerts when significant distribution changes or performance degradation are detected.
問題 #178
A Machine Learning Engineer is implementing integration tests for an ML pipeline in Databricks.
The current integration test runs the complete workflow but takes four hours to execute due to large dataset processing and extensive model training. They need to select an approach that will be the most effective for optimizing integration test execution while maintaining test reliability. The approach should also be based on MLOps best practices. Which approach will do this?
- A. Use small subsets of production-like data and reduce training iterations while maintaining the same pipeline structure and validation checkpoints in a staging environment that closely matches production.
- B. Skip the model training phase entirely and only test data transformations and API endpoints using mock model predictions.
- C. Replace integration tests with unit tests for each pipeline component to reduce execution time and focus on individual component validation in a staging environment that closely matches production.
- D. Run integration tests only in the production environment using full datasets to ensure complete accuracy of the testing process.
答案:A
解題說明:
Using smaller, production-like datasets and reduced training iterations preserves the full pipeline structure while significantly reducing execution time. This aligns with MLOps best practices by maintaining high-fidelity integration testing in a staging environment that mirrors production behavior, without the cost and delay of running full-scale training workloads.
問題 #179
A retail company wants to better forecast their sales of each SKU in every store in order to more accurately distribute their products. To achieve this, a Data Scientist proposes scaling their existing forecasting model to forecast individually for each combination of SKU and Store ID.
They have a cluster with 12 executors available in order to execute this. The current model is written using Pandas and the Prophet library for forecasting, with a Python function that receives a Pandas Data Frame with historic sales data as a parameter to train the forecasting model. For their next iteration, they want to improve the efficiency of this approach while using the least amount of effort and leveraging all available resources. Which approach will do this?
- A. 1. Use a Spark query to identify all combinations of SKU and Store ID;
2. Run a loop through every combination calling the existing Python function using Spark repartition(12) function so it distributes across all available executors. - B. 1. Decorate the existing training function with the @pandas_udf;
2. On the Spark DataFrame with all training data perform a GROUP BY by Store and SKU;
3. Apply the decorated function to the grouped DataFrame with the apply function. - C. 1. Rewrite the function using the Generalized Linear Regression models available in Spark MLlib, which allows parameterizing to reflect a similar behavior to that of Prophet;
2. Perform a GROUP BY on the Spark DataFrame with the training data to group by Store and SKU;
3. Apply the Spark UDF to the grouped DataFrame with the apply function. - D. 1. Use Spark repartition(12) to scale across all executors;
2. Run to Pandas to convert the repartitioned DataFrame to Pandas so it can run on the original existing function;
3. Add the Store ID and SKU to the Prophet model as exogenous variables.
答案:B
解題說明:
A grouped Pandas UDF lets you keep the existing Prophet-based pandas training function while distributing execution across the cluster. Grouping the Spark DataFrame by SKU and Store ID and applying the function runs one model per group in parallel on the executors, improving efficiency and leveraging all available resources with minimal refactoring.
問題 #180
......
你對自己現在的工作滿意嗎?對自己正在做的事情滿意嗎?想不想提升自己的水準呢?多掌握一些對工作有用的技能吧。那麼,在IT領域工作的你,當然是應該選擇參加IT認定考試獲得認證資格了。因為這樣可以更好地提升你自己。而且,最重要的是,你也可以向別人證明你掌握了更多的工作技能。那麼,快來參加Databricks的Databricks-Machine-Learning-Professional考試吧。這個考試可以幫助你實現你自己的願望。對通過這個考試沒有信心也沒關係。因為你可以來Fast2test找到你想要的幫手和準備考試的工具。Fast2test的考考试资料一定能帮助你获得Databricks-Machine-Learning-Professional考试的认证资格。
Databricks-Machine-Learning-Professional認證資料: https://tw.fast2test.com/Databricks-Machine-Learning-Professional-premium-file.html
- Databricks-Machine-Learning-Professional考古题推薦 👇 Databricks-Machine-Learning-Professional證照指南 🎑 Databricks-Machine-Learning-Professional考題資訊 🦡 透過▛ www.pdfexamdumps.com ▟搜索⏩ Databricks-Machine-Learning-Professional ⏪免費下載考試資料Databricks-Machine-Learning-Professional最新試題
- Databricks-Machine-Learning-Professional權威考題 👣 Databricks-Machine-Learning-Professional考題資訊 🤬 Databricks-Machine-Learning-Professional考試證照綜述 🎧 立即打開➤ www.newdumpspdf.com ⮘並搜索《 Databricks-Machine-Learning-Professional 》以獲取免費下載Databricks-Machine-Learning-Professional考試資料
- 最真實的Databricks-Machine-Learning-Professional認證考試的真實考古題匯總 🧰 立即到「 www.pdfexamdumps.com 」上搜索▶ Databricks-Machine-Learning-Professional ◀以獲取免費下載Databricks-Machine-Learning-Professional試題
- Databricks-Machine-Learning-Professional最新試題 🕚 Databricks-Machine-Learning-Professional學習指南 🥈 Databricks-Machine-Learning-Professional題庫分享 🙆 免費下載⏩ Databricks-Machine-Learning-Professional ⏪只需在“ www.newdumpspdf.com ”上搜索Databricks-Machine-Learning-Professional考試資料
- 最真實的Databricks-Machine-Learning-Professional認證考試的真實考古題匯總 💌 在《 www.newdumpspdf.com 》網站下載免費{ Databricks-Machine-Learning-Professional }題庫收集Databricks-Machine-Learning-Professional考題資訊
- 最新Databricks-Machine-Learning-Professional考題 🥻 Databricks-Machine-Learning-Professional PDF題庫 👑 Databricks-Machine-Learning-Professional考試 🤖 ☀ www.newdumpspdf.com ️☀️上的➽ Databricks-Machine-Learning-Professional 🢪免費下載只需搜尋Databricks-Machine-Learning-Professional最新考古題
- Databricks-Machine-Learning-Professional考試 🥰 Databricks-Machine-Learning-Professional考試題庫 🥀 Databricks-Machine-Learning-Professional最新考古題 😳 在⇛ www.newdumpspdf.com ⇚上搜索⮆ Databricks-Machine-Learning-Professional ⮄並獲取免費下載最新Databricks-Machine-Learning-Professional考古題
- Databricks-Machine-Learning-Professional熱門考古題 🐰 Databricks-Machine-Learning-Professional最新考古題 👇 Databricks-Machine-Learning-Professional考試 🛕 開啟{ www.newdumpspdf.com }輸入➠ Databricks-Machine-Learning-Professional 🠰並獲取免費下載Databricks-Machine-Learning-Professional考試證照綜述
- 權威Databricks-Machine-Learning-Professional指南和資格考試中的領先材料供應者&可信的Databricks Databricks Certified Machine Learning Professional 🐃 打開網站{ www.vcesoft.com }搜索⮆ Databricks-Machine-Learning-Professional ⮄免費下載Databricks-Machine-Learning-Professional考題資訊
- Databricks-Machine-Learning-Professional考試 🏺 Databricks-Machine-Learning-Professional權威考題 🔻 Databricks-Machine-Learning-Professional熱門考古題 🍬 免費下載( Databricks-Machine-Learning-Professional )只需在「 www.newdumpspdf.com 」上搜索Databricks-Machine-Learning-Professional熱門考古題
- 全面包括的Databricks-Machine-Learning-Professional指南和資格考試中的領導者和無與倫比的Databricks-Machine-Learning-Professional認證資料 🧜 打開網站⏩ www.newdumpspdf.com ⏪搜索▛ Databricks-Machine-Learning-Professional ▟免費下載Databricks-Machine-Learning-Professional試題
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.fotor.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Fast2test在Google Drive上分享了免費的2026 Databricks Databricks-Machine-Learning-Professional考試題庫:https://drive.google.com/open?id=1r4_AaGuBqzxGgGHiGEMX6wCfWVWVnEBV