
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Easy4Engine: https://drive.google.com/open?id=18Wc0NpCkHLGTUGW1XIHsG9taHurDdQq2
Easy4Engine's Amazon MLA-C01 exam training material is the best training materials on the Internet. It is the leader in all training materials. It not only can help you to pass the exam, you can also improve your knowledge and skills. Help you in your career in your advantage successfully. As long as you have the Amazon MLA-C01 Certification, you will be treated equally by all countries.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
As the most famous and popular MLA-C01 exam questions on the market, we have built a strict quality control system. The whole compilation process of the MLA-C01 study materials is normative. We have proof-readers to check all the contents. Usually, the MLA-C01 Actual Exam will go through many times’ careful proofreading. Please trust us. We always attach great importance to quality of the MLA-C01practice braindumps.
NEW QUESTION # 69
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to use the central model registry to manage different versions of models in the application.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
Explanation:
Amazon SageMaker Model Registry is a feature designed to manage machine learning (ML) models throughout their lifecycle. It allows users to catalog, version, and deploy models systematically, ensuring efficient model governance and management.
Key Features of SageMaker Model Registry:
* Centralized Cataloging: Organizes models intoModel Groups, each containing multiple versions.
* Version Control: Maintains a history of model iterations, making it easier to track changes.
* Metadata Association: Attach metadata such as training metrics and performance evaluations to models.
* Approval Status Management: Allows setting statuses like PendingManualApproval or Approved to ensure only vetted models are deployed.
* Seamless Deployment: Direct integration with SageMaker deployment capabilities for real-time inference or batch processing.
Implementation Steps:
* Create a Model Group: Organize related models into groups to simplify management and versioning.
* Register Model Versions: Each model iteration is registered as a version within a specific Model Group.
* Set Approval Status: Assign approval statuses to models before deploying them to ensure quality control.
* Deploy the Model: Use SageMaker endpoints for deployment once the model is approved.
Benefits:
* Centralized Management: Provides a unified platform to manage models efficiently.
* Streamlined Deployment: Facilitates smooth transitions from development to production.
* Governance and Compliance: Supports metadata association and approval processes.
By leveraging the SageMaker Model Registry, the company can ensure organized management of models, version control, and efficient deployment workflows with minimal operational overhead.
References:
* AWS Documentation: SageMaker Model Registry
* AWS Blog: Model Registry Features and Usage
NEW QUESTION # 70
An ML engineer needs to use an ML model to predict the price of apartments in a specific location.
Which metric should the ML engineer use to evaluate the model's performance?
Answer: D
Explanation:
When predicting continuous variables, such as apartment prices, it's essential to evaluate the model's performance using appropriate regression metrics. The Mean Absolute Error (MAE) is a widely used metric for this purpose.
Understanding Mean Absolute Error (MAE):
MAE measures the average magnitude of errors in a set of predictions, without considering their direction. It calculates the average absolute difference between predicted values and actual values, providing a straightforward interpretation of prediction accuracy.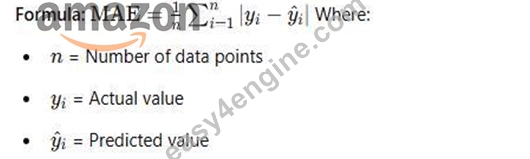
Advantages of MAE:
* Interpretability: MAE is expressed in the same units as the target variable, making it easy to understand.
* Robustness to Outliers: Unlike metrics that square the errors (e.g., Mean Squared Error), MAE does not disproportionately penalize larger errors, making it more robust to outliers.
Comparison with Other Metrics:
* Accuracy, AUC, F1 Score: These metrics are designed for classification tasks, where the goal is to predict discrete labels. They are not suitable for regression problems involving continuous target variables.
* Mean Squared Error (MSE): While MSE also measures prediction errors, it squares the differences, giving more weight to larger errors. This can be useful in certain contexts but may be sensitive to outliers.
Conclusion:
For evaluating the performance of a model predicting apartment prices-a continuous variable-MAE is an appropriate and effective metric. It provides a clear indication of the average prediction error in the same units as the target variable, facilitating straightforward interpretation and comparison.
References:
Regression Metrics - GeeksforGeeks
Evaluation Metrics for Your Regression Model - Analytics Vidhya
Regression Metrics for Machine Learning - Machine Learning Mastery
NEW QUESTION # 71
An ML engineer needs to deploy ML models to get inferences from large datasets in an asynchronous manner. The ML engineer also needs to implement scheduled monitoring of data quality for the models and must receive alerts when changes in data quality occur.
Which solution will meet these requirements?
Answer: B
Explanation:
This requirement combines asynchronous inference on large datasets with automated data quality monitoring and alerting. AWS documentation explicitly recommends Amazon SageMaker batch transform for large- scale, asynchronous inference workloads. Batch transform jobs process large datasets stored in Amazon S3 without requiring a persistent endpoint, making them cost-effective and scalable.
For data quality monitoring, Amazon SageMaker Model Monitor is the AWS-native solution. Model Monitor can be scheduled to analyze inference data, compare it against a baseline, and detect data quality issues such as missing values, schema changes, or statistical drift. When violations occur, Model Monitor emits metrics to Amazon CloudWatch, where alarms can trigger alerts.
Options A, B, and C lack ML-aware data quality monitoring capabilities. AWS Glue and Batch are not designed for model data quality analysis, and CloudTrail tracks API activity-not data quality.
AWS best practices clearly position Batch Transform + Model Monitor as the correct architecture for asynchronous inference with automated monitoring and alerting.
Therefore, Option D is the correct and AWS-verified solution.
NEW QUESTION # 72
A company uses a hybrid cloud environment. A model that is deployed on premises uses data in Amazon S3 to provide customers with a live conversational engine.
The model is using sensitive data. An ML engineer needs to implement a solution to identify and remove the sensitive data.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
The core requirement is to identify and remove sensitive data from content stored in Amazon S3 with minimal operational overhead. Amazon Macie is purpose-built to automatically discover, classify, and protect sensitive data (such as PII) in Amazon S3 using machine learning. Macie continuously scans S3 objects and produces findings that identify sensitive data types and locations without requiring custom ML pipelines or infrastructure.
Once Macie identifies sensitive data, AWS Lambda can be used to automate remediation-such as redacting, masking, or deleting sensitive fields-based on Macie findings. This event-driven approach is serverless, scales automatically, and minimizes operations.
Option A increases overhead by moving the model and building custom detection logic. Option B introduces unnecessary compute orchestration (ECS/Fargate and Batch). Option D uses Amazon Comprehend for entity detection, which is not optimized for broad S3 data discovery and requires EC2 management.
Therefore, using Amazon Macie for detection and Lambda for remediation is the most efficient and AWS- recommended solution.
NEW QUESTION # 73
An ML engineer needs to implement a solution to host a trained ML model. The rate of requests to the model will be inconsistent throughout the day.
The ML engineer needs a scalable solution that minimizes costs when the model is not in use.
The solution also must maintain the model's capacity to respond to requests during times of peak usage.
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 74
......
Easy4Engine is a wonderful study platform that contains our hearty wish for you to pass the exam by our MLA-C01 exam materials. So our responsible behaviors are our instinct aim and tenet. By devoting in this area so many years, we are omnipotent to solve the problems about the MLA-C01 learning questions with stalwart confidence. we can claim that only studing our MLA-C01 study guide for 20 to 30 hours, then you will pass the exam for sure.
Valid Test MLA-C01 Fee: https://www.easy4engine.com/MLA-C01-test-engine.html
What's more, part of that Easy4Engine MLA-C01 dumps now are free: https://drive.google.com/open?id=18Wc0NpCkHLGTUGW1XIHsG9taHurDdQq2