BTW, DOWNLOAD part of TestValid NCA-GENM dumps from Cloud Storage: https://drive.google.com/open?id=1qB_eTIJiRo5OTRl5n6KkcUEmVLU-XrsJ
The research and production of our NCA-GENM study materials are undertaken by our first-tier expert team. The clients can have a free download and tryout of our NCA-GENM study materials before they decide to buy our products. They can use our products immediately after they pay for the NCA-GENM study materials successfully. If the clients are unlucky to fail in the test we will refund them as quickly as we can. There are so many advantages of our products that we can’t summarize them with several simple words. You’d better look at the introduction of our NCA-GENM Study Materials in detail as follow by yourselves.
| Section | Objectives |
|---|---|
| Core AI and Machine Learning Fundamentals | - Machine learning basics
|
| NVIDIA AI Ecosystem | - NVIDIA tools and frameworks
|
| Generative AI Concepts | - Generative models
|
| Responsible and Trustworthy AI | - Bias and safety considerations - Ethical AI principles |
| Multimodal AI Systems | - Multimodal model design - Cross-modal learning
|
>> Study NVIDIA NCA-GENM Tool <<
There are many businesses in the market who boast about the high quality of their test materials. However, we can pat on the chest confidently to say that the passing rate of students who use our NCA-GENM test torrent is between 98% and 99%. If you unfortunately fail to pass the NCA-GENM exam, upload your exam certificate and screenshots of the failed scores, and we will immediately give a full refund. Using our NCA-GENM Test Questions will not bring you any loss. In addition, the refund process is very simple and will not bring you any trouble. If you have any questions, you can always contact us online or email us. We will reply as soon as possible.
NEW QUESTION # 38
You're building a multimodal model that processes both images and text. The image encoder outputs a feature vector of size 2048, and the text encoder outputs a feature vector of size 512. Which of the following strategies is MOST appropriate for combining these feature vectors before feeding them into a downstream classifier?
Answer: A
Explanation:
Projecting into a lower-dimensional common embedding space reduces dimensionality and potential overfitting, while concatenation after projection retains information from both modalities. Averaging might mask distinct features. Projecting to original vector sizes before averaging is possible, but concatenating smaller projected vectors is most memory efficient
NEW QUESTION # 39
In LLM evaluation, what does "zero-shot learning" refer to?
Answer: C
Explanation:
Zero-shot learning describes a model's capacity to correctly perform a task it was never explicitly trained or fine-tuned on, relying instead on knowledge and generalization ability acquired during broader pretraining.
For LLMs, this typically means the model is given only a natural-language instruction or prompt describing the task - with no task-specific labeled examples provided in the prompt at all - and is expected to produce a reasonable response by generalizing from its pretraining. This is directly analogous to CLIP's zero-shot image classification (covered elsewhere in this set): a model trained broadly can be applied to a new, specific task purely through how the task is described to it, without additional task-specific training.
Option A is a subtly incorrect paraphrase: zero-shot learning is not about the model "learning from zero examples" during a training process - it's about applying a model that was never trained for the specific task at all, at inference time. The model isn't learning in the zero-shot moment; it's generalizing from prior training. Option B misapplies "zero" to training time rather than to task-specific examples - an unrelated concept. Option C directly contradicts the definition; zero-shot specifically refers to performance *without* task-specific training, not performance *after* extensive training on that task.
Zero-shot is typically contrasted with few-shot learning, where a small number of task-specific examples are included in the prompt to guide the model's response without updating its weights.
Reference: Core Machine Learning and AI Knowledge domain - zero-shot vs. few-shot learning, generalization in LLMs.
NEW QUESTION # 40
Consider a scenario where you are building a multimodal model that combines image and text data for image captioning. You're using a transformer architecture with cross-attention. Which of the following best describes the role of cross-attention in this context?
Answer: B
Explanation:
Cross-attention in image captioning allows the decoder (generating text) to focus on specific parts of the image that are most relevant for generating the next word in the caption. The text 'attends' to the image.
NEW QUESTION # 41
You are developing a system to generate captions for videos. The video frames are processed using a pre-trained ResNet model, and the audio track is processed using a pre-trained Wav2Vec model. Which of the following techniques is MOST suitable for aligning the visual and audio features to generate accurate and coherent captions?
Answer: A
Explanation:
Cross-attention allows the model to learn the temporal relationships and dependencies between the visual and audio modalities. The audio features can attend to relevant visual features at each time step, and vice versa, leading to better alignment and more coherent captions. Simple concatenation and averaging are less effective at capturing these complex relationships. Ignoring the audio track loses valuable information.
NEW QUESTION # 42
Consider the following Python code snippet using PyTorch, intended to combine image and text embeddings: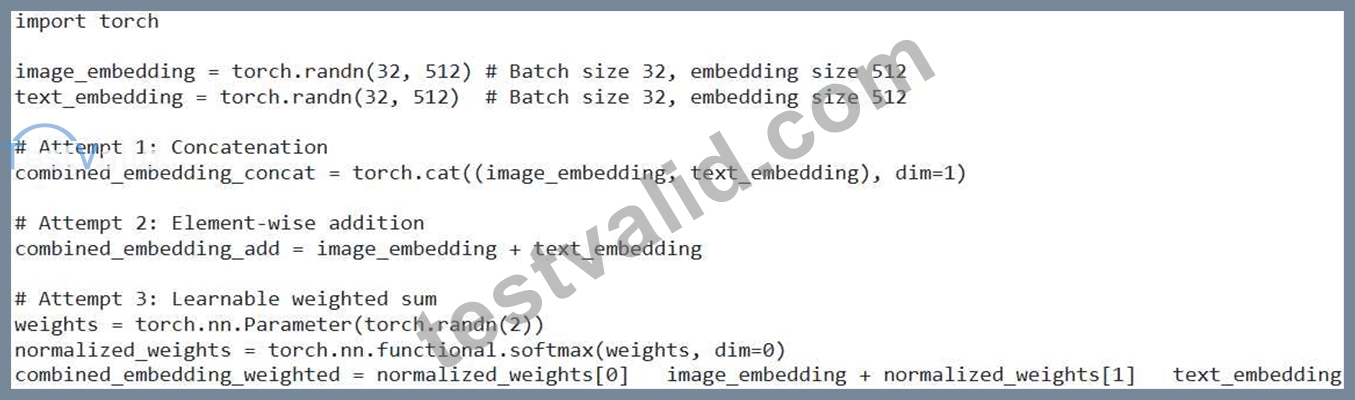
Which of the following statements regarding the output shapes of these combined embeddings are TRUE? (Select TWO)
Answer: B,D
Explanation:
torch.cat concatenates the embeddings along dimension 1, resulting in shape (32, 1024). Element-wise addition maintains the original shape (32, 512). The weighted sum is also element-wise, preserving the (32, 512) shape.
NEW QUESTION # 43
......
As we all know, the latest NCA-GENM quiz prep has been widely spread since we entered into a new computer era. The cruelty of the competition reflects that those who are ambitious to keep a foothold in the job market desire to get the NCA-GENM certification. As long as you spare one or two hours a day to study with our laTest NCA-GENM Quiz prep, we assure that you will have a good command of the relevant knowledge before taking the exam. What you need to do is to follow the NCA-GENM exam guide system at the pace you prefer as well as keep learning step by step.
Latest NCA-GENM Test Vce: https://www.testvalid.com/NCA-GENM-exam-collection.html
BONUS!!! Download part of TestValid NCA-GENM dumps for free: https://drive.google.com/open?id=1qB_eTIJiRo5OTRl5n6KkcUEmVLU-XrsJ