Our company employs the first-rate expert team which is superior to others both at home and abroad. Our experts team includes the experts who develop and research the DP-750 cram materials for many years and enjoy the great fame among the industry, the senior lecturers who boost plenty of experiences in the information about the exam and published authors who have done a deep research of the DP-750 latest exam file and whose articles are highly authorized. They provide strong backing to the compiling of the DP-750 Exam Questions and reliable exam materials resources. They compile each answer and question carefully. Each question presents the key information to the learners and each answer provides the detailed explanation and verification by the senior experts. The success of our DP-750 latest exam file cannot be separated from their painstaking efforts.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
>> DP-750 Valid Test Questions <<
We have confidence and ability to make you get large returns but just need input small investment. our DP-750 study materials provide a platform which help you gain knowledge in order to let you outstanding in the labor market and get satisfying job that you like. The content of our DP-750question torrent is easy to master and simplify the important information. It conveys more important information for DP-750 Exam with less answers and questions, thus the learning is easy and efficient. We believe our latest DP-750 exam torrent will be the best choice for you.
NEW QUESTION # 83
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Drag and Drop Question
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.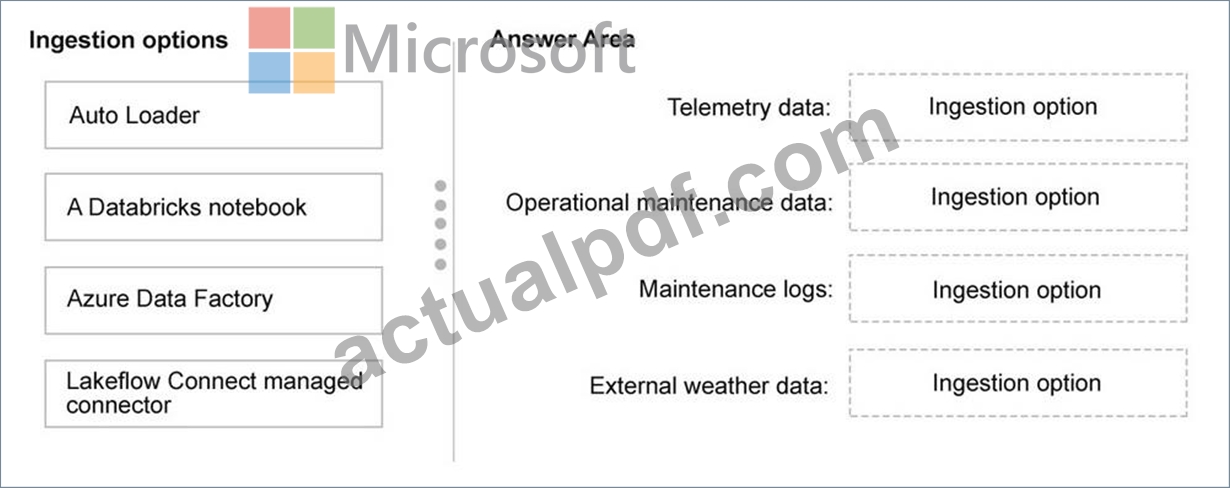
Answer:
Explanation: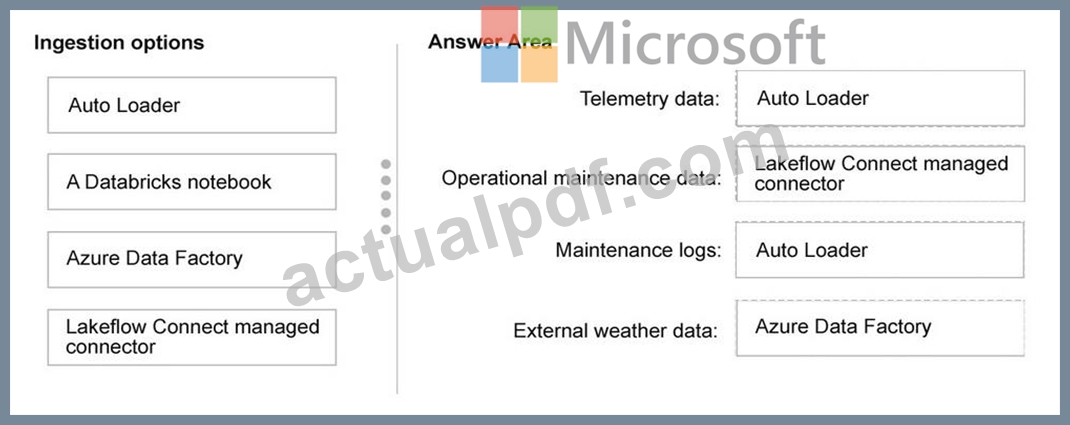
NEW QUESTION # 84
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Answer: C
Explanation:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
NEW QUESTION # 85
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: B
Explanation:
The correct answer is C - Enable schema evolution.
When new columns are added to the source data, a pipeline without schema evolution treats the unexpected columns as a schema mismatch and fails the write. Schema evolution, when enabled in an SDP pipeline, automatically adds those new columns to the target Delta table on the next pipeline run. The pipeline continues without intervention, and no historical data is lost.
Option A (disable schema enforcement) is the wrong lever - it removes all schema validation, which could allow corrupt or mistyped data into Table1. Schema evolution is a targeted, safer response.
Option B (row filters to exclude records with new columns) would silently discard valid records just because they carry extra fields - that's data loss. Option D (separate table per schema version) creates an explosion of tables as schemas evolve and makes downstream analytics significantly more complex. Schema evolution is the clean, built-in solution.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/schema-evolution
NEW QUESTION # 86
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.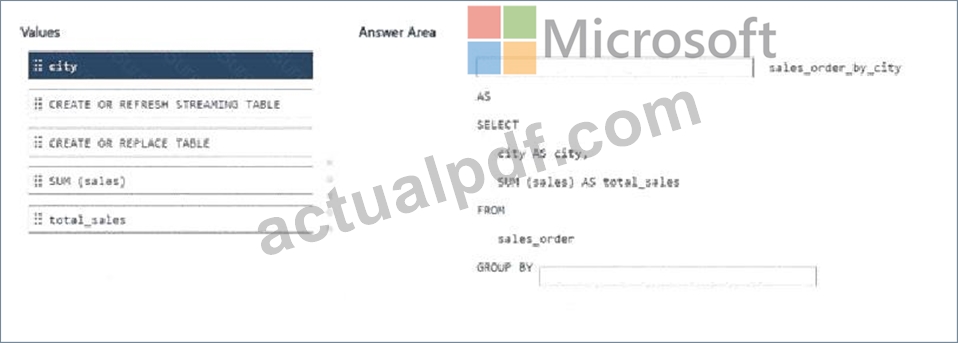
Answer:
Explanation: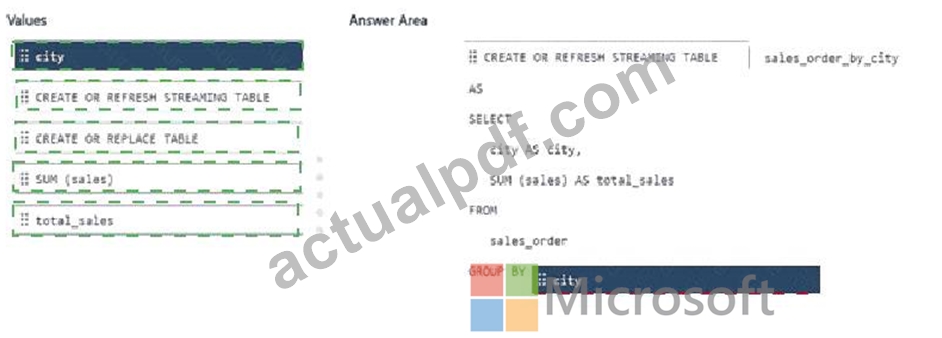
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
NEW QUESTION # 87
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: B
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 88
......
Grasping different consumers’ learning situation in a comprehensive way, the operation system of our DP-750 practice materials can adapt to different consumer groups. Facts speak louder than words. Through years’ efforts, our DP-750 exam preparation has received mass favorable reviews because the 99% pass rate of our DP-750 Study Guide is the powerful proof of trust of the public. No other vendor can do this like us, we are the unique and best DP-750 learning prep provider!
Test DP-750 Dump: https://www.actualpdf.com/DP-750_exam-dumps.html