There is a high demand for Designing and Implementing Multi-Agent AI Solutions certification, therefore there is an increase in the number of Microsoft AI-500 exam candidates. Many resources are available on the internet to prepare for the Designing and Implementing Multi-Agent AI Solutions exam. FreeDumps is one of the best certification exam preparation material providers where you can find newly released Microsoft AI-500 Dumps for your exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Topic 2: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
The software version is one of the three versions of our AI-500 actual exam, which is designed by the experts from our company. The functions of the software version are very special. For example, the software version can simulate the real exam environment. If you buy our AI-500 study questions, you can enjoy the similar real exam environment. So do not hesitate and buy our AI-500 preparation exam, you will benefit a lot from our products.
NEW QUESTION # 37
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: D
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 38
You have a Microsoft Foundry multi-agent solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. The retrieval agent uses a knowledge search tool.
Security testing reveals the following recurring issues:
* Some users submit jailbreak-style prompts at the start of a conversation.
* Some retrieved documents contain hidden instructions intended to manipulate the downstream agent The legal department at your company requires that final responses be flagged for review if they contain protected text. You need to configure guardrails to resolve the security issues and meet the legal requirements.
What should you configure?
Answer: B
Explanation:
The three risks occur at three different intervention points. Direct jailbreak attempts originate in the user prompt, so User input attacks should be evaluated at the User input boundary and blocked. Malicious instructions embedded in retrieved documents are indirect prompt-injection attacks and belong at the Tool response boundary before the retrieved content can influence downstream reasoning. Protected material in the final response must be flagged for legal review, not necessarily blocked, so an Output control using annotate- only behavior matches the requirement. Options A and B misplace at least one control or block content that the scenario says should only be flagged. Microsoft Foundry guardrails are explicitly designed around these intervention points, making C the configuration that aligns each risk with the stage where it can be detected and acted upon. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
NEW QUESTION # 39
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.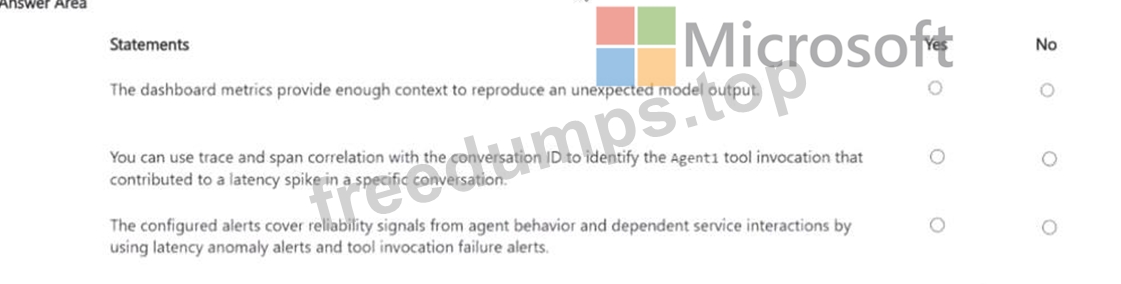
Answer:
Explanation: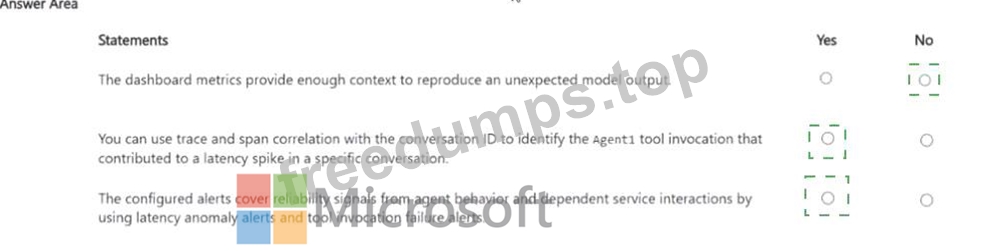
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts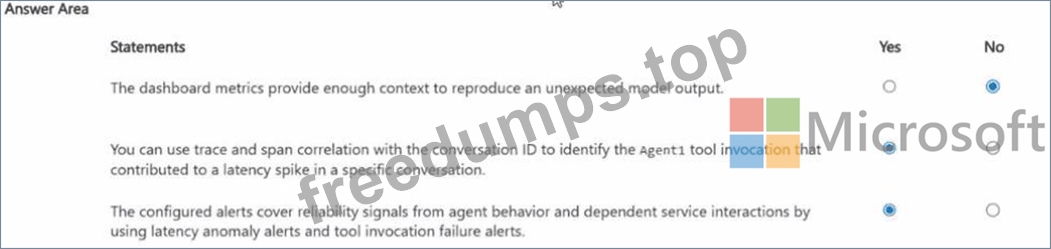
NEW QUESTION # 40
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.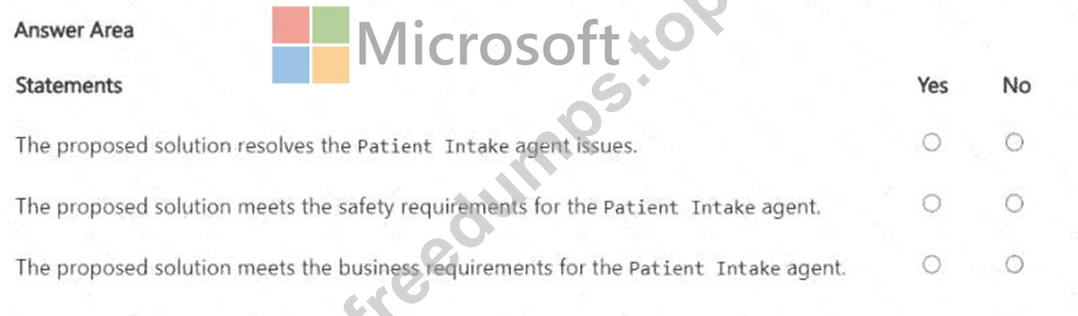
Answer:
Explanation: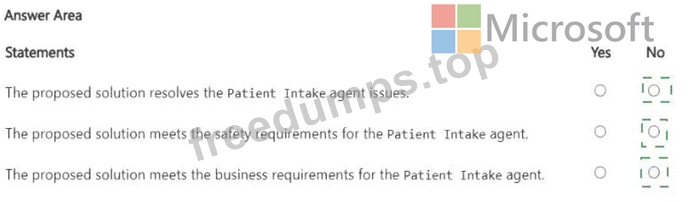
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
NEW QUESTION # 41
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.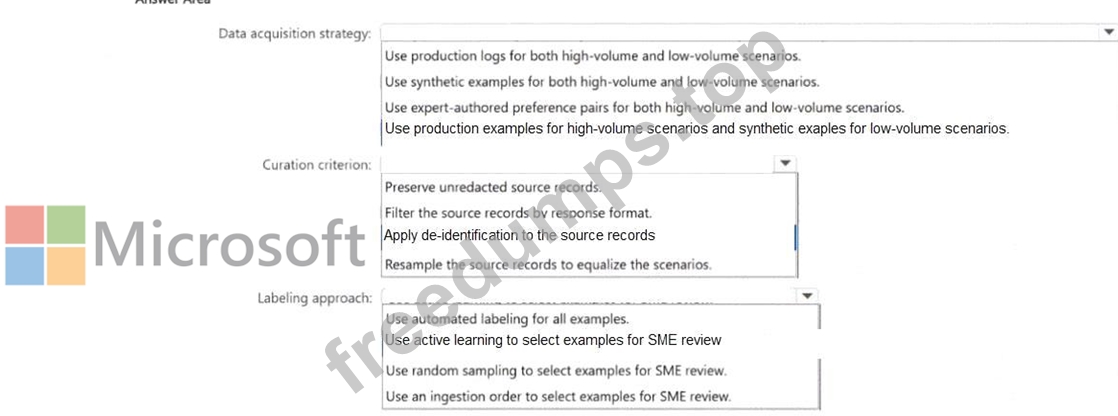
Answer:
Explanation: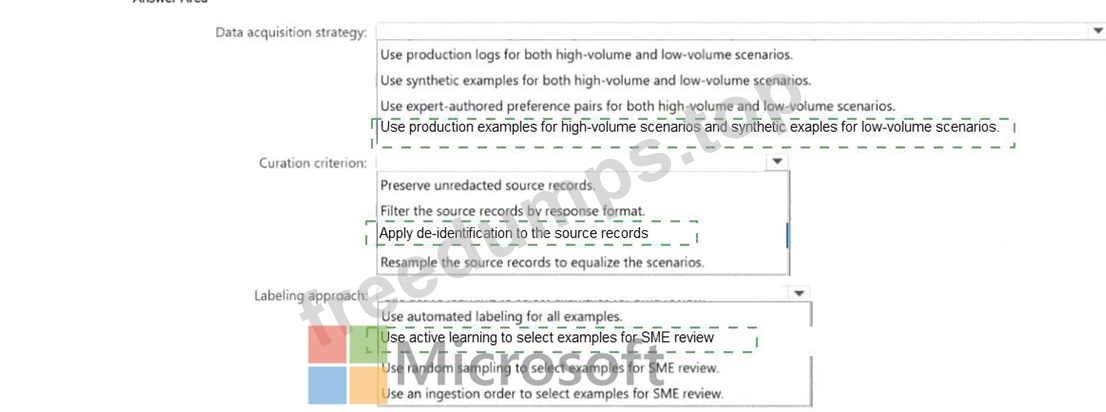
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation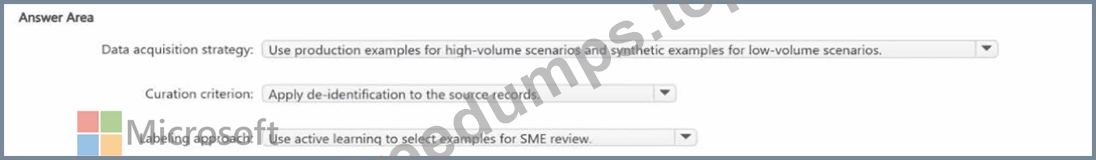
NEW QUESTION # 42
......
If you want to get a better job and relieve your employment pressure, it is essential for you to get the AI-500 certification. However, due to the severe employment situation, more and more people have been crazy for passing the AI-500 exam by taking examinations, the exam has also been more and more difficult to pass. Our AI-500 test guide has become more and more popular in the world. Of course, if you decide to buy our AI-500 latest question, we can make sure that it will be very easy for you to pass AI-500 exam torrent that you can learn and practice it. Then you just need 20-30 hours to practice our study materials that you can attend your exam. It is really spend your little time and energy.
New AI-500 Mock Test: https://www.freedumps.top/AI-500-real-exam.html