What's more, part of that Prep4SureReview SPS-C01 dumps now are free: https://drive.google.com/open?id=1lwEvmU_flj_F4JHQ6NW3TOp1_9As5GD4
Overall obtaining Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) certificate can be a valuable investment in your professional career. As it can help you to stand out in a competitive market, more career opportunities, and advancement of your career. To gain all these advantages you just need to enroll in the Snowflake SPS-C01 Certification Exam and put all your efforts to pass this challenging SPS-C01 exam with flying colors.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Persisting transformed data - Window functions - Filtering, Aggregating, and Joining DataFrames - Using built-in functions |
| Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Transformations vs. Actions - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark DataFrames and query plans |
| Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Reading and writing data - DataFrame creation and manipulation |
| Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Caching strategies - Debugging and explain plans - Minimizing data transfer - Warehouse sizing for Snowpark - Query pushdown and optimization |
>> Practice SPS-C01 Exam Pdf <<
In order to serve you better, we have a complete system for you if you choose us. We offer you free demo for SPS-C01 exam materials for you to have a try, so that you can have a better understanding of what you are going to buy. If you are quite satisfied with SPS-C01 exam materials and want the complete version, you just need to add them to cart and pay for it. You can receive the download link and password within ten minutes for SPS-C01 Training Materials, and if you don’t receive, you can contact with us, and we will solve the problem for you. We also have after-service stuff, if you have any questions about SPS-C01 exam materials, you can consult us.
NEW QUESTION # 67
You have a Snowpark DataFrame 'df representing sales data with columns 'product_id', 'region', and 'sales_amount'. You want to calculate the total sales amount for each region. Which of the following Snowpark code snippets is the MOST efficient and correct way to achieve this?





Answer: E
Explanation:
Option D is the most efficient and correct. 'df.groupBy('region')' groups the data by the 'region' column. agg(sum(col('sales_amount')).alias('total_sales'))' calculates the sum of the 'sales_amount' column for each region and aliases the result as 'total_sales'. Using explicitly is the recommended Snowpark practice. 'collect()' brings the entire result set to the client, which can be inefficient for large datasets. Using 'toPandas(Y works but defeats the purpose of Snowpark since it pulls all the data to the client before aggregation happens. Option C is syntactically incorrect as .alias(V is used incorrectly after and doesn't chain together. Options A and B are less performant because they transfer the data to the client side. Option E also works, but it's better to use string column name as it is recommended best practice.
NEW QUESTION # 68
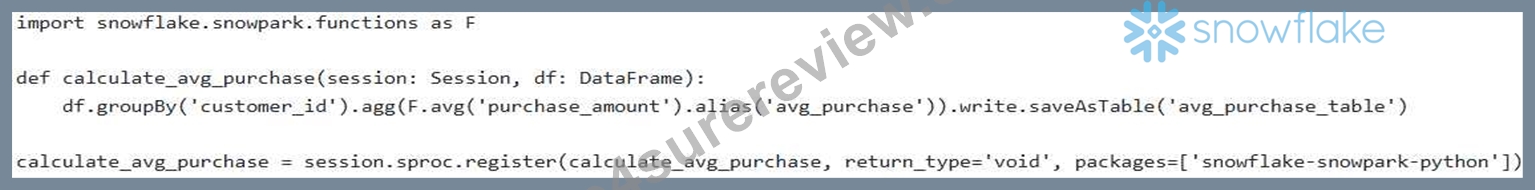
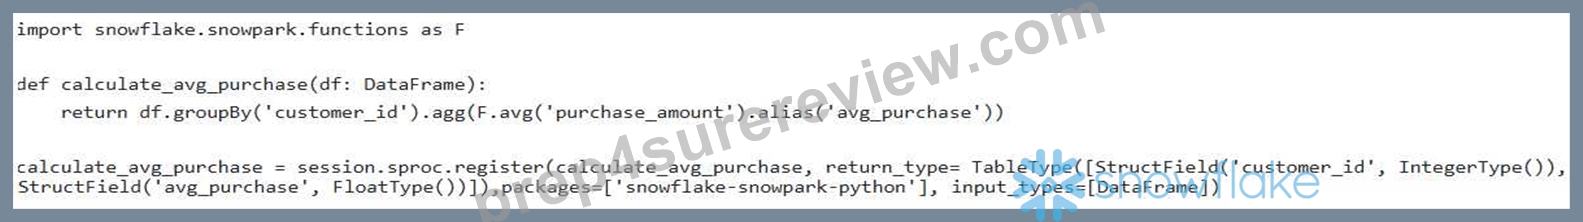
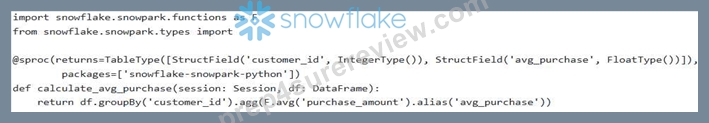
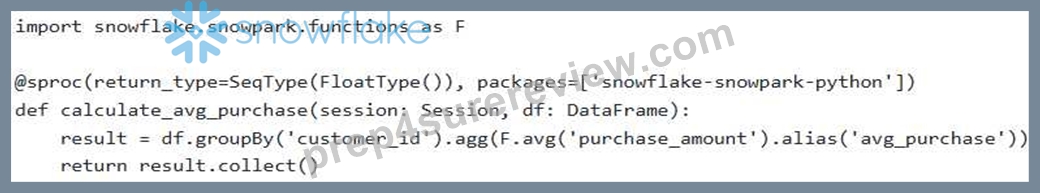
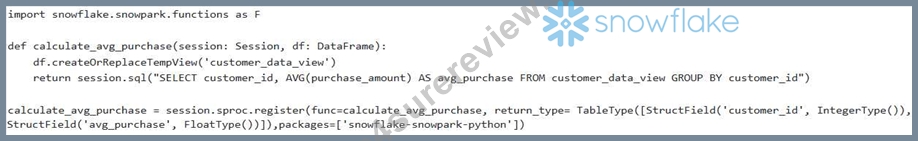
You have a Snowpark DataFrame named and want to create a stored procedure that calculates the average purchase amount for each customer. The stored procedure should accept the DataFrame as input, perform the aggregation, and return a new DataFrame with the results. Which of the following code snippets BEST demonstrates how to correctly define and deploy this stored procedure?
Answer: B
Explanation:
Option E is the most correct. It correctly registers the stored procedure using 'session.sproc.register' with the correct return type annotation for a DataFrame (using TableType and StructFields) and explicitly declares the input type to be DataFrame using 'input_types' parameter in registration. Option A uses the '@sproc' decorator which is the older API (still valid, but less explicit). Option B uses session.sql which is not appropriate for creating DataFrame based stored procedures. Option C is not correct because the return type SeqType(FloatType()) expects a sequence of float types instead of a DataFrame structure. Option D writes the result to a table, which is not the defined requirement to return a DataFrame.
NEW QUESTION # 69
You are developing a Snowpark Python application that reads data from a Snowflake table, performs several transformations including filtering, aggregation, and joining with another DataFrame, and then writes the results back to a new table. You want to optimize the execution plan to minimize data movement and processing time. Which of the following strategies would be MOST effective in leveraging Snowpark's lazy evaluation capabilities to achieve this optimization?
Answer: E
Explanation:
Chaining transformations and delaying execution until the final action allows Snowpark to optimize the entire query plan. Caching the initial DataFrame might improve performance in some cases, but it can also introduce unnecessary materialization. Defining transformations in a single SQL query string bypasses Snowpark's optimization capabilities. Calling 'collect()' after each transformation defeats the purpose of lazy evaluation. Python multiprocessing does not directly interact with Snowpark's query optimization.
NEW QUESTION # 70
Consider the following Snowpark Python code snippet for creating a stored procedure: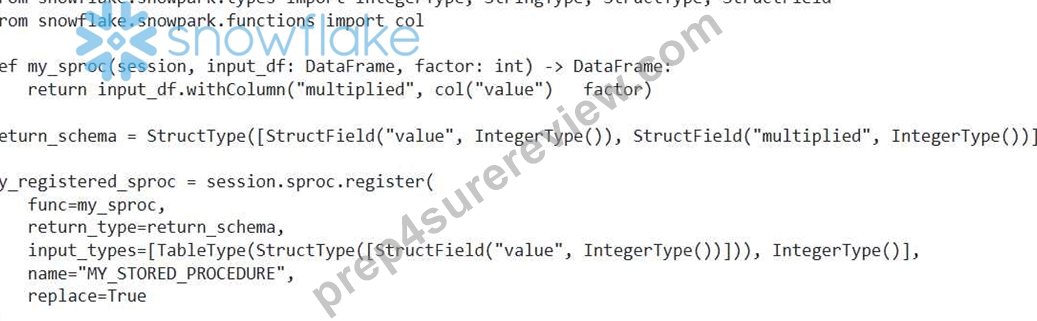
What is the PRIMARY reason for explicitly defining 'input_types' and during the stored procedure registration?
Answer: C
NEW QUESTION # 71
You are developing a Snowpark application that performs feature engineering on a dataset of customer transactions. This involves calculating several complex aggregate features such as rolling averages, medians, and custom ratios. You want to optimize the performance of this feature engineering process using a Snowpark-optimized warehouse. Which of the following strategies would be MOST effective in achieving optimal performance?
Answer: A,B
Explanation:
Using 'GROUP BY and window functions allows Snowflake to optimize the calculations within its engine. Leveraging UDTFs allows custom computations while still benefiting from Snowflake's optimization capabilities. Python UDFs are generally slower than equivalent SQL or Java/Scala UDTFs due to inter-process communication overhead. Materializing intermediate DataFrames can help in some scenarios but can also introduce overhead if not managed carefully. Java Stored procedures could be used, but UDTF would be more optimized way.
NEW QUESTION # 72
......
Prep4SureReview offers authentic and actual SPS-C01 dumps that every candidate can rely on for good preparation. Our top priority is to give you the most reliable prep material that helps you pass the SPS-C01 Exam on the first attempt. In addition, we offer up to three months of free Snowflake Certified SnowPro Specialty - Snowpark questions updates.
100% SPS-C01 Correct Answers: https://www.prep4surereview.com/SPS-C01-latest-braindumps.html
BTW, DOWNLOAD part of Prep4SureReview SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1lwEvmU_flj_F4JHQ6NW3TOp1_9As5GD4