DOWNLOAD the newest FreeCram Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MvpyzjFa5kV9oqXB_tnICFXLyfxQFa1r
As a brand in the field, our Professional-Machine-Learning-Engineer exam questions are famous for their different and effective advantages. Our professional experts have developed our Professional-Machine-Learning-Engineer study materials to the best. So if you buy them, you will find that our Professional-Machine-Learning-Engineer learning braindumps are simply unmatched in their utility and perfection. Our huge clientele is immensely satisfied with our product and the excellent passing rate of our Professional-Machine-Learning-Engineer simulating exam is the best evidence on it.
| Section | Objectives |
|---|---|
| Topic 1: Automating and orchestrating ML pipelines | - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems |
| Topic 2: Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Topic 3: Collaborating within and across teams to manage data and models | - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
| Topic 4: Serving and scaling models | - Model optimization (Quantization, Distillation) - Batch prediction - Hardware accelerators (GPU/TPU) in serving - Online prediction (Vertex AI Prediction) |
| Topic 5: Scaling prototypes into ML models | - Hyperparameter tuning - Training at scale (Distributed training, TPUs) - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Topic 6: Monitoring ML solutions | - Performance monitoring and drift detection - Model retraining strategies - Logging and alerting (Cloud Monitoring) |
>> Professional-Machine-Learning-Engineer Demo Test <<
These formats are Google PDF Questions and practice test software. The Google Professional Machine Learning Engineer Professional-Machine-Learning-Engineer practice exam software is further divided into two formats. The name of these two formats is Google Professional-Machine-Learning-Engineer desktop practice test software and web-based Google Professional-Machine-Learning-Engineer practice test software. Both Google Professional-Machine-Learning-Engineer practice test software is the Professional-Machine-Learning-Engineer Practice Exam that will give you a real-time Professional-Machine-Learning-Engineer exam preparation environment to solve all Google Professional Machine Learning Engineer Professional-Machine-Learning-Engineer questions. With the Google Professional-Machine-Learning-Engineer practice test software you can understand your weak topic areas. Later on, working on these Google Professional-Machine-Learning-Engineer weak topic areas you can make it perfect.
NEW QUESTION # 355
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: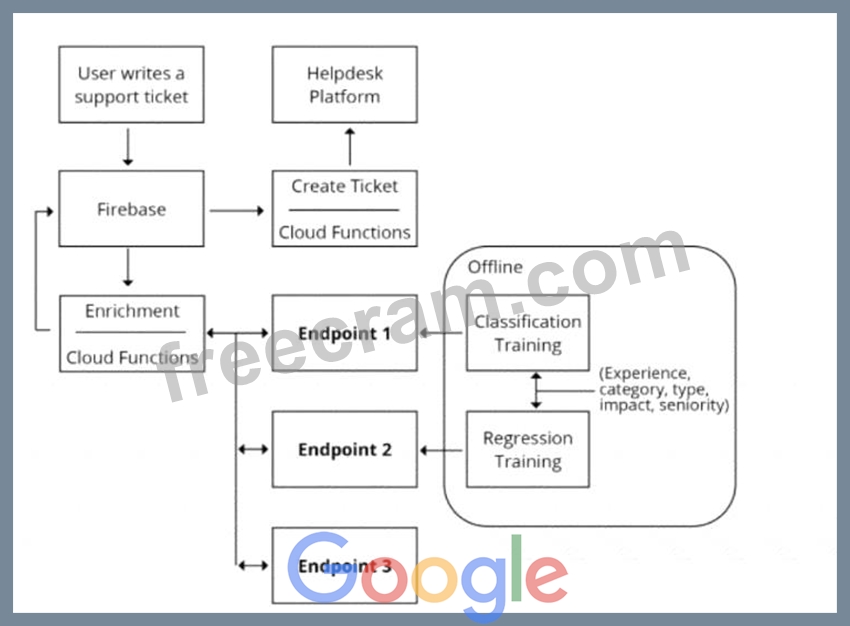
Which endpoints should the Enrichment Cloud Functions call?
Answer: B
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used toperform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels. They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 356
You are building a TensorFlow model for a financial institution that predicts the impact of consumer spending on inflation globally. Due to the size and nature of the data, your model is long-running across all types of hardware, and you have built frequent checkpointing into the training process. Your organization has asked you to minimize cost. What hardware should you choose?
Answer: D
Explanation:
The best hardware to choose for your model while minimizing cost is a Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a preemptible v3-8 TPU. This hardware configuration can provide you with high performance, scalability, and efficiency for your TensorFlow model, as well as low cost and flexibility for your long-running and checkpointing process. The v3-8 TPU is a cloud tensor processing unit (TPU) device, which is a custom ASIC chip designed by Google to accelerate ML workloads.
It can handle large and complex models and datasets, and offer fast and stable training and inference. The n1- standard-16 is a general-purpose VM that can support the CPU and memory requirements of your model, as well as the data preprocessing and postprocessing tasks. By choosing a preemptible v3-8 TPU, you can take advantage of the lower price and availability of the TPU devices, as long as you can tolerate the possibility of the device being reclaimed by Google at any time. However, since you have built frequent checkpointing into your training process, you can resume your model from the last saved state, and avoid losing any progress or data. Moreover, you can use the Vertex AI Workbench user-managed notebooks to create and manage your notebooks instances, and leverage the integration with Vertex AI and other Google Cloud services.
The other options are not optimal for the following reasons:
* A. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with 4 NVIDIA P100 GPUs is not a good option, as it has higher cost and lower performance than the v3-8 TPU. The NVIDIA P100 GPUs are the previous generation of GPUs from NVIDIA, which have lower performance, scalability, and efficiency than the latest NVIDIA A100 GPUs or the TPUs. They also have higher price and lower availability than the preemptible TPUs, which can increase the cost and complexity of your solution.
* B. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with an NVIDIA P100 GPU is not a good option, as it has higher cost and lower performance than the v3-8 TPU. It also has less GPU memory and compute power than the option with 4 NVIDIA P100 GPUs, which can limit the size and complexity of your model, and affect the training and inference speed and quality.
* C. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a non- preemptible v3-8 TPU is not a good option, as it has higher cost and lower flexibility than the preemptible v3-8 TPU. The non-preemptible v3-8 TPU has the same performance, scalability, and efficiency as the preemptible v3-8 TPU, but it has higher price and lower availability, as it is reserved for your exclusive use. Moreover, since your model is long-running and checkpointing, you do not need the guarantee of the device not being reclaimed by Google, and you can benefit from the lower cost and higher availability of the preemptible v3-8 TPU.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Cloud TPU
* Vertex AI Workbench user-managed notebooks
* Preemptible VMs
* NVIDIA Tesla P100 GPU
NEW QUESTION # 357
You work in the credit card fraud detection department of a bank that processes millions of transactions per day. You need to create and serve a real-time fraud detection model. To address the challenge of feature engineering at this scale with limited raw data, you plan to create time- related aggregate features, such as the average transaction amount within the last month or the amount of time since the last transaction. How should you process the data for model training and serving?
Answer: C
Explanation:
A streaming Dataflow pipeline can process millions of transaction events from Pub/Sub and use stateful, windowed aggregations to calculate time-dependent features such as monthly average transaction amounts and time since the previous transaction. Storing these engineered values in Agent Platform Feature Store makes consistent features available for both model training and low-latency online serving.
Reference:
https://docs.cloud.google.com/dataflow/docs/concepts/streaming-pipelines
https://docs.cloud.google.com/dataflow/docs/concepts/streaming-with-cloud-pubsub
NEW QUESTION # 358
A Machine Learning Specialist kicks off a hyperparameter tuning job for a tree-based ensemble model using Amazon SageMaker with Area Under the ROC Curve (AUC) as the objective metric. This workflow will eventually be deployed in a pipeline that retrains and tunes hyperparameters each night to model click-through on data that goes stale every 24 hours.
With the goal of decreasing the amount of time it takes to train these models, and ultimately to decrease costs, the Specialist wants to reconfigure the input hyperparameter range(s).
Which visualization will accomplish this?
Answer: B
NEW QUESTION # 359
You recently deployed a scikit-learn model to a Vertex AI endpoint. You are now testing the model on live production traffic. While monitoring the endpoint, you discover twice as many requests per hour than expected throughout the day. You want the endpoint to efficiently scale when the demand increases in the future to prevent users from experiencing high latency. What should you do?
Answer: B
NEW QUESTION # 360
......
Our Professional-Machine-Learning-Engineer practice materials can be understood with precise content for your information, which will remedy your previous faults and wrong thinking of knowledge needed in this exam. As a result, many customers get manifest improvement and lighten their load by using our Professional-Machine-Learning-Engineer Actual Exam. It is well-known that our Professional-Machine-Learning-Engineer study guide can save a lot of time and effort. And with the simpilied content of our Professional-Machine-Learning-Engineer practice questions, you can have a wonderful study experience as well.
Professional-Machine-Learning-Engineer Exam Study Guide: https://www.freecram.com/Google-certification/Professional-Machine-Learning-Engineer-exam-dumps.html
2026 Latest FreeCram Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1MvpyzjFa5kV9oqXB_tnICFXLyfxQFa1r