Actually we eliminate the barriers blocking you from our AI-200 practice materials. All types of our AI-200 exam questions are priced favorably on your wishes. Obtaining our AI-200 study guide in the palm of your hand, you can achieve a higher rate of success. Besides, there are free demos for your careful consideration to satisfy individual needs on our AI-200 learning prep. You can free download them to check if it is the exact one that you want.
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 2: Implement Azure AI solutions | - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search - Implement computer vision solutions |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
We have created a number of reports and learning functions for evaluating your proficiency for the Developing AI Cloud Solutions on Azure (AI-200) exam dumps. In preparation, you can optimize Developing AI Cloud Solutions on Azure (AI-200) practice exam time and question type by utilizing our Microsoft AI-200 Practice Test software. Prep4away makes it easy to download Microsoft AI-200 exam questions immediately after purchase. You will receive a registration code and download instructions via email.
NEW QUESTION # 93
You are developing an AI-powered API that retrieves connection strings and API keys from Azure Key Vault.
You must configure a solution that provides the following security functionality:
- The API must authenticate to Key Vault without storing credentials in any application configuration files.
- The identity used by the API must have only the minimum permissions
necessary to read secrets.
- The configuration must minimize the blast radius if an identity or
credential is compromised.
You need to implement a secure access strategy for the API.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
You should use a system-assigned managed identity, but to minimize the blast radius, you should grant the Key Vault Secrets User role at the secret scope rather than the vault scope.
Authentication (Managed Identity): A system-assigned managed identity perfectly satisfies your first requirement. Azure automatically manages the identity credentials, eliminating the need to store keys or connection strings in application configuration files. Because it shares the lifecycle of your API service, it is automatically deleted if the API is removed.
Authorization (RBAC Role): The Key Vault Secrets User role satisfies the "minimum permissions" requirement because it only grants read permissions (Microsoft.KeyVault/vaults/secrets/getSecret/action and readSecret/action.
Scope (Blast Radius Minimization): Granting this role at the vault scope allows the API to read every secret inside that vault. If your API only needs specific connection strings, you should grant the role at the individual secret scope [0.30]. This restricts the identity so it cannot access any other secrets in the vault if compromised.
Reference:
https://learn.microsoft.com/en-us/azure/api-management/api-management-howto-use-managed-service-identity
NEW QUESTION # 94
You have an Event Grid subscription that triggers an Azure Function.
You need to prevent loss of events in case the endpoint returns an HTTP 400 response.
Which action should you perform?
Answer: D
Explanation:
Configuring a dead-letter destination is exactly the right step to take.
By default, when an endpoint returns an HTTP 400 (Bad Request) or HTTP 413 (Payload Too Large) response, Azure Event Grid immediately stops delivery attempts and drops the message.
It treats these specific errors as non-transient, client-side issues, meaning it skips its standard 24- hour retry policy.
Configuring a dead-letter destination ensures that these dropped events are safely preserved for future troubleshooting and reprocessing.
Reference:
https://turbo360.com/blog/azure-event-grid-dead-letter-monitoring
NEW QUESTION # 95
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.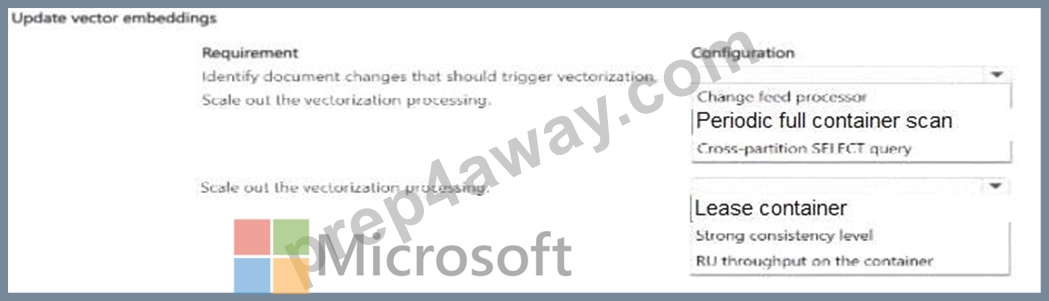
Answer:
Explanation: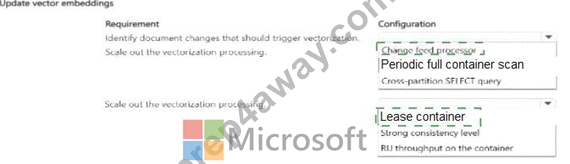
Explanation: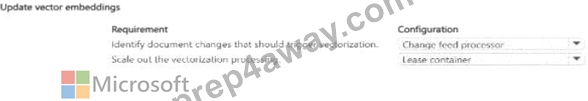
Verified Answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
NEW QUESTION # 96
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to implement trace correlation according to the business requirements.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.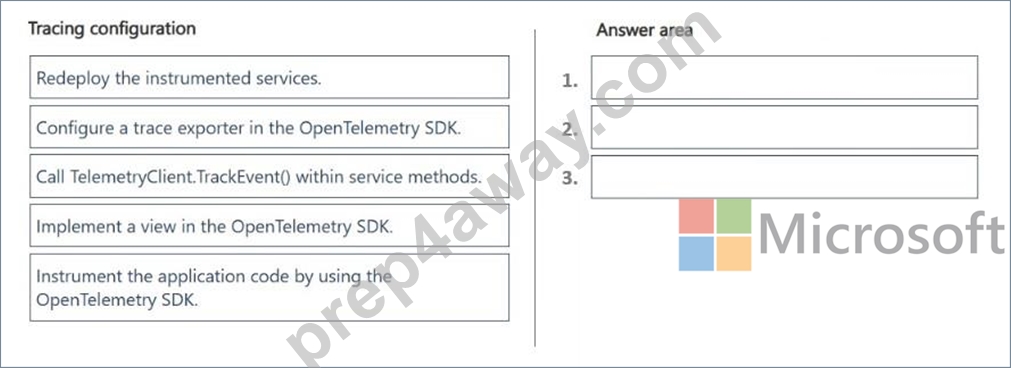
Answer:
Explanation: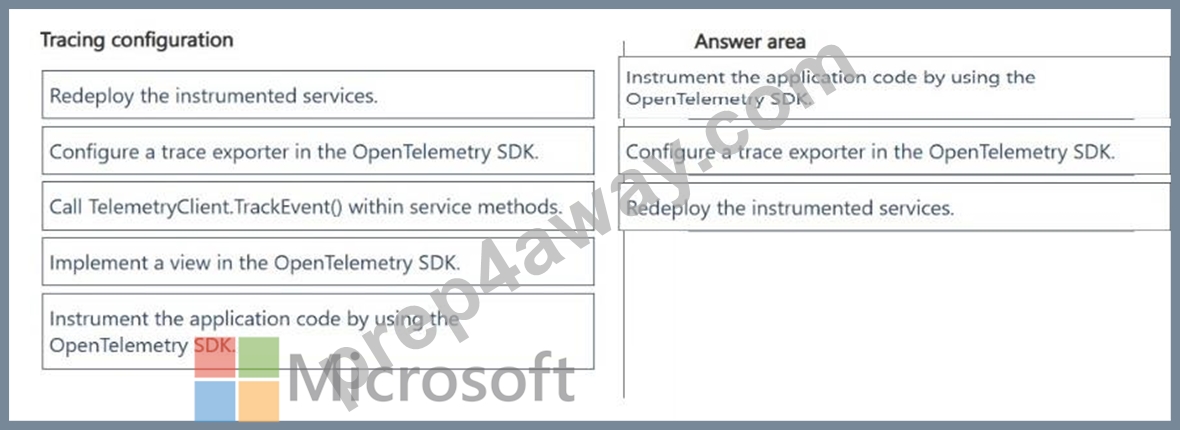
Explanation:
Scenario, Business Requirements
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Step 1: Instrument the application code by using OpenTelemetry SDK
This adds the foundational tracking APIs to your code so it can create and capture trace spans.
Step 2: Configure a trace exporter in the OpenTelemetry SDK
This instructs the initialized SDK where to transmit the captured trace data (e.g., to a local console or a cloud backend).
Step 3: Redeploy the instrumented services
This pushes the modified codebase and configuration changes into your active runtime environment.
Reference:
https://opentelemetry.io/docs/languages/python/instrumentation/
NEW QUESTION # 97
Drag and Drop Question
You are developing a solution for a hospital to support the following use cases:
- The most recent patient status details must be retrieved even if
multiple users in different locations have updated the patient record.
- Patient health monitoring data retrieved must be the current version
or the prior version.
- After a patient is discharged and all charges have been assessed, the patient billing record contains the final charges.
You provision an Azure Cosmos DB for NoSQL database and set the default consistency level for the database account to Strong.
You set the value for Indexing Mode to Consistent.
You need to minimize latency and any impact to the availability of the solution. You must override the default consistency level at the query level to meet the required consistency guarantees for the scenarios.
Which consistency levels should you implement? To answer, drag the appropriate consistency levels to the correct requirements. Each consistency level may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.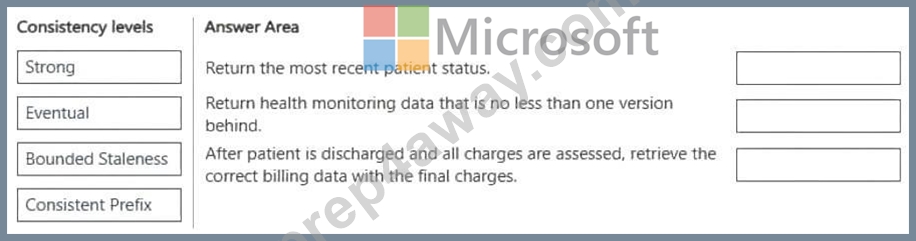
Answer:
Explanation: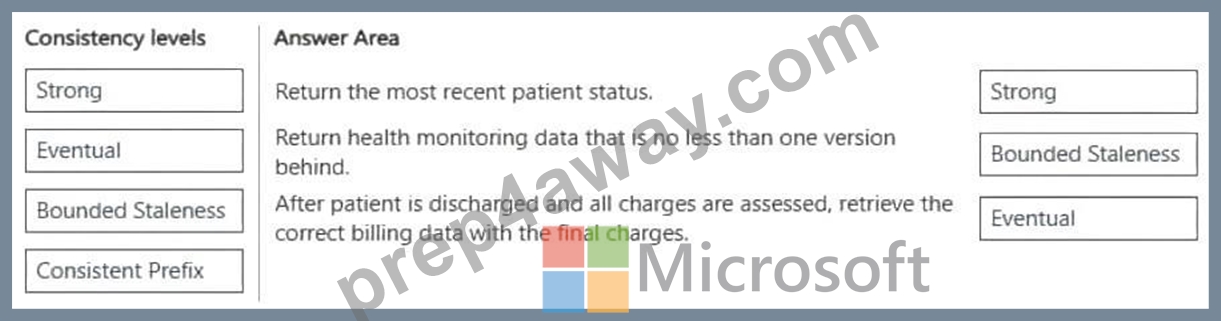
Explanation:
Box 1: Strong
Strong consistency must be used at the query level to meet this requirement.
Linearizability Guarantee: Strong consistency ensures that a read operation always returns the most recent committed version of an item.
Global Consensus: Because multiple users in different locations are updating the patient record, any reader across any region must wait for the updates to be fully committed globally before reading. This prevents any user from reading stale or out-of-order data, which is critical for patient status details.
Box 2: Bounded Staleness
To minimize latency and maximize availability while ensuring that retrieved patient health monitoring data is either the current version or the immediate prior version, you should override the consistency level at the query level to Bounded Staleness.
Version Guarantee: Bounded Staleness ensures that reads are not older than a specific time window or a configured number of versions K versions behind the latest write). Setting the version staleness to 1 (K=1 )guarantees that the data read is either the current version or the prior version.
Lower Latency: Bounded Staleness offers significantly lower latency than the account's default Strong consistency. Strong consistency requires a global majority acknowledgment before a read or write completes, increasing latency.
Higher Availability: By backing down from Strong consistency to Bounded Staleness for this query, you reduce the strict synchronization requirements, thereby minimizing impacts on availability during localized network disruptions.
Box 3: Eventual
Eventual consistency is the correct consistency level to use at the query level for this scenario.
Maximizes Performance: Eventual consistency offers the lowest latency and highest availability among all consistency levels.
Matches Scenario Needs: The billing record is final and no longer changing, so there is no risk of reading stale, in-progress updates.
Optimizes Costs: Eventual consistency queries consume half the Request Units (RUs) compared to Strong or Bounded Staleness queries.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/consistency-levels
NEW QUESTION # 98
......
In this fast-changing world, the requirements for jobs and talents are higher, and if people want to find a job with high salary they must boost varied skills which not only include the good health but also the working abilities. We provide timely and free update for you to get more AI-200 Questions torrent and follow the latest trend. The AI-200 exam torrent is compiled by the experienced professionals and of great value.
AI-200 Simulated Test: https://www.prep4away.com/Microsoft-certification/braindumps.AI-200.ete.file.html