DOWNLOAD the newest DumpsReview Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1HoLZzzgmQ4hQAOMYfF50uk6HjqtDQbVv
Our Databricks-Certified-Data-Engineer-Associate exam cram has been revised for lots of times to ensure all candidates can easily understand all knowledge parts. In the meantime, the learning process is recorded clearly in the system, which helps you adjust your learning plan. On the one hand, our company has benefited a lot from renovation. Customers are more likely to choose our products. On the other hand, the money we have invested is meaningful, which helps to renovate new learning style of the Databricks-Certified-Data-Engineer-Associate Exam. So, why not buy our Databricks-Certified-Data-Engineer-Associate test guide?
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Python for Data Engineering | 10-15% | - Use PySpark for data processing - Implement user-defined functions (UDFs) - Work with Spark APIs in Python |
| Topic 2: Data Pipeline Architecture | 15-20% | - Design data pipelines for batch and streaming - Implement incremental data processing - Monitor and optimize pipeline performance - Understand ELT vs ETL patterns |
| Topic 3: Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts - Describe key Databricks Lakehouse platform components |
| Topic 4: Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing - Create and use Spark DataFrames - Work with structured data types (arrays, maps, structs) - Apply transformations and actions on DataFrames |
| Topic 5: Delta Lake Fundamentals | 20-25% | - Understand ACID transactions and time travel - Write to and read from Delta tables - Create and manage Delta tables - Explain Delta Lake features and benefits |
| Topic 6: Spark SQL and DataFrames | 15-20% | - Join and union DataFrames - Aggregate and group data - Handle null values and data quality - Write and execute Spark SQL queries |
>> Databricks-Certified-Data-Engineer-Associate Top Exam Dumps <<
There are more opportunities for possessing with a certification, and our Databricks-Certified-Data-Engineer-Associate study tool is the greatest resource to get a leg up on your competition. When it comes to our time-tested Databricks-Certified-Data-Engineer-Associate latest practice materials, for one thing, we have a professional team contains a lot of experts who have devoted themselves to development of our Databricks-Certified-Data-Engineer-Associate Exam Guide, thus we feel confident enough under the intensely competitive market. For another thing, conforming to the real exam our Databricks-Certified-Data-Engineer-Associate study tool has the ability to catch the core knowledge. So our customers can pass the exam with ease.
NEW QUESTION # 279
A data engineering team has noticed that their Databricks SQL queries are running too slowly when they are submitted to a non-running SQL endpoint. The data engineering team wants this issue to be resolved.
Which of the following approaches can the team use to reduce the time it takes to return results in this scenario?
Answer: A
Explanation:
Option D is the correct answer because it enables the Serverless feature for the SQL endpoint, which allows the endpoint to automatically scale up and down based on the query load. This way, the endpoint can handle more concurrent queries and reduce the time it takes to return results. The Serverless feature also reduces the cold start time of the endpoint, which is the time it takes to start the cluster when a query is submitted to a non- running endpoint. The Serverless feature is available for both AWS and Azure Databricks platforms.
Databricks SQL Serverless, Serverless SQL endpoints, New Performance Improvements in Databricks SQL
NEW QUESTION # 280
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table: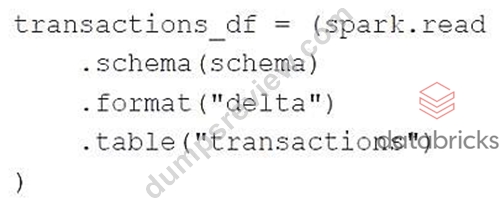
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
Answer: A
Explanation:
To read from a stream source, the data engineer needs to use the spark.readStream method instead of the spark.
read method. The spark.readStream method returns a DataStreamReader object that can be used to specify the details of the input source, such as the format, the schema, the path, and the options. The spark.read method is only suitable for batch processing, not streaming processing. The other changes are not necessary or correct for reading from a stream source. References: Structured Streaming Programming Guide, Read a stream, Databricks Data Sources
NEW QUESTION # 281
A global retail company sells products across multiple categories (e.g.. Electronics, Clothing) and regions (e.
g.. North. South, East. West). The sales team has provided the data engineer with a PySpark dataframe named sales_df as below and the team wants the data engineer to analyze the sales data to help them make strategic decisions.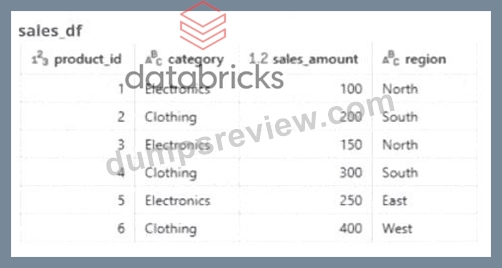
Answer: C
NEW QUESTION # 282
A data engineer needs to determine whether to use the built-in Databricks Notebooks versioning or version their project using Databricks Repos.
Which of the following is an advantage of using Databricks Repos over the Databricks Notebooks versioning?
Answer: A
Explanation:
Databricks Repos is a visual Git client and API in Databricks that supports common Git operations such as cloning, committing, pushing, pulling, and branch management. Databricks Notebooks versioning is a legacy feature that allows users to link notebooks to GitHub repositories and perform basic Git operations. However, Databricks Notebooks versioning does not support the use of multiple branches for development work, which is an advantage of using Databricks Repos. With Databricks Repos, users can create and manage branches for different features, experiments, or bug fixes, and merge, rebase, or resolve conflicts between them. Databricks recommends using a separate branch for each notebook and following data science and engineering code development best practices using Git for version control, collaboration, and CI/CD. References: Git integration with Databricks Repos - Azure Databricks | Microsoft Learn, Git version control for notebooks (legacy) | Databricks on AWS, Databricks Repos Is Now Generally Available - New 'Files' Feature in ..., Databricks Repos - What it is and how we can use it | Adatis.
NEW QUESTION # 283
An engineering manager wants to monitor the performance of a recent project using a Databricks SQL query.
For the first week following the project's release, the manager wants the query results to be updated every minute. However, the manager is concerned that the compute resources used for the query will be left running and cost the organization a lot of money beyond the first week of the project's release.
Which of the following approaches can the engineering team use to ensure the query does not cost the organization any money beyond the first week of the project's release?
Answer: B
Explanation:
In Databricks SQL, you can use scheduled query executions to update your dashboards or enable routine alerts. By default, your queries do not have a schedule. To set the schedule, you can use the dropdown pickers to specify the frequency, period, starting time, and time zone. You can also choose to end the schedule on a certain date by selecting the End date checkbox and picking a date from the calendar. This way, you can ensure that the query does not run beyond the first week of the project's release and does not incur any additional cost. Option A is incorrect, as setting a limit to the number of DBUs does not stop the query from running. Option B is incorrect, as there is no option to end the schedule after a certain number of refreshes.
Option C is incorrect, as there is a way to ensure the query does not cost the organization money beyond the first week of the project's release. Option D is incorrect, as setting a limit to the number of individuals who can manage the query's refresh schedule does not affect the query's execution or cost. References: Schedule a query, Schedule a query - Azure Databricks - Databricks SQL
NEW QUESTION # 284
......
As you know, today's society is changing very fast. We also need new knowledge to fill in as we learn. And our Databricks-Certified-Data-Engineer-Associate learning prep can suit you most in this need for you will get the according certification as well as the latest information. Databricks-Certified-Data-Engineer-Associate Exam simulation is selected by many experts and constantly supplements and adjust our questions and answers. When you use our Databricks-Certified-Data-Engineer-Associate study materials, you can find the information you need at any time.
Databricks-Certified-Data-Engineer-Associate Valid Test Forum: https://www.dumpsreview.com/Databricks-Certified-Data-Engineer-Associate-exam-dumps-review.html
2026 Latest DumpsReview Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1HoLZzzgmQ4hQAOMYfF50uk6HjqtDQbVv