DOWNLOAD the newest Prep4SureReview DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1PpnLEVKbxoi0h0MGoAB_3b5z0MRphu6U
If you Prep4SureReview, Prep4SureReview can ensure you 100% pass Microsoft Certification DP-750 Exam. If you fail to pass the exam, Prep4SureReview will full refund to you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 2: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
Our Microsoft DP-750 practice test software is the most distinguished source for the Microsoft DP-750 exam all over the world because it facilitates your practice in the practical form of the Implementing Data Engineering Solutions Using Azure Databricks certification exam. Moreover, you do not need an active internet connection to utilize Microsoft DP-750 Practice Exam software. It works without the internet after software installation on Windows computers.
NEW QUESTION # 63
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: D
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Column1. Table2 contains a column named Column2.
You run the following query.
SELECT Colum1
FROM Table1
GROUP BY Column1
HAVING COUNT(*) > 1
INTERSECT
SELECT Column2
FROM Table2
GROUP BY Column2
HAVING COUNT(*) > 1;
What occurs when you run the query?
Answer: A
Explanation:
The query will output a single column containing only the values that are duplicated within Table1 and also duplicated within Table2.
Duplicates Isolated First: The GROUP BY and HAVING COUNT(*) > 1 clauses filter each table independently to find only their duplicate rows.
Matching Values Found: The INTERSECT operator compares the filtered results of both tables.
Shared Values Returned: Only values that exist in both filtered datasets are included in the final output.
Automatic Distinct Filtering: INTERSECT automatically removes any duplicate values from the final result set, ensuring each matching value appears exactly once.
Column Naming: The output column will inherit its name from the first SELECT statement (Column1).
Reference:
https://quizlet.com/study-guides/inf3707-chapter-4-data-retrieval-from-2-or-more-tables-
6ec17b26-76a8-4c33-8fa7-18d64154512d
NEW QUESTION # 65
Drag and Drop Question
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1.
You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location. The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.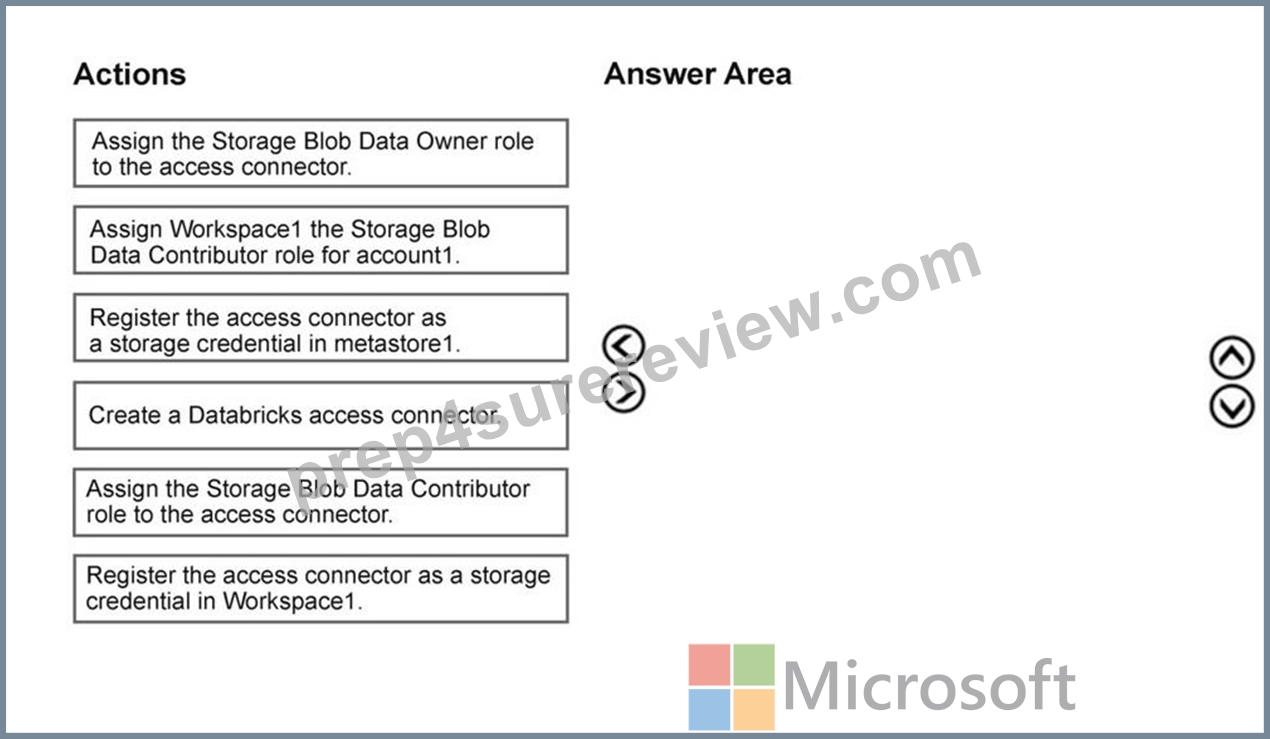
Answer:
Explanation: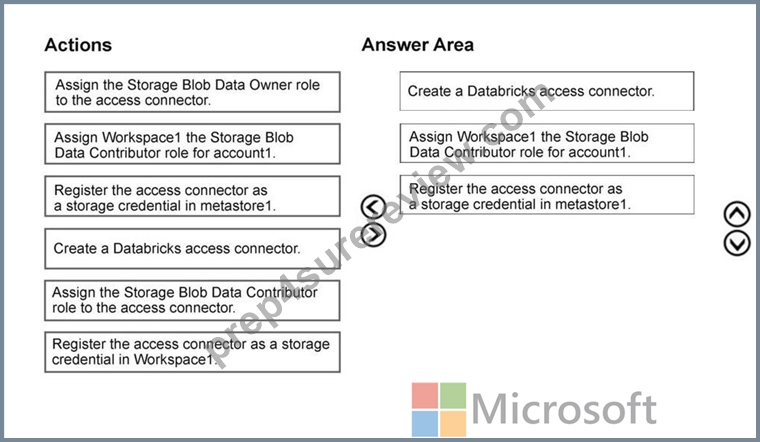
NEW QUESTION # 66
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: C
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 67
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 68
......
It's not easy for most people to get the DP-750 guide torrent, but I believe that you can easily and efficiently obtain qualification certificates as long as you choose our products. Interest is the best teacher, so it is only by letting the user have fun in the boring study that they can better put knowledge into their thinking. How perfect DP-750 Exam Questions are! Maybe you cannot wait to understand our study materials.
Relevant DP-750 Questions: https://www.prep4surereview.com/DP-750-latest-braindumps.html
DOWNLOAD the newest Prep4SureReview DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1PpnLEVKbxoi0h0MGoAB_3b5z0MRphu6U