KoreaDumps는Microsoft AI-200시험에 필요한 모든 문제유형을 커버함으로서 Microsoft AI-200시험을 합격하기 위한 최고의 선택이라 할수 있습니다. Microsoft AI-200시험 Braindump를 공부하면 학원다니지 않으셔도 자격증을 취득할수 있습니다. Microsoft AI-200 덤프정보 상세보기는 이 글의 링크를 클릭하시면 KoreaDumps사이트에 들어오실수 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 2: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Topic 3: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 4: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
AI-200덤프를 퍼펙트하게 공부하시면 보다 쉽게 시험에서 패스할수 있습니다. 다년간 IT업계에 종사하신 전문가들이 AI-200인증시험을 부단히 연구하고 분석한 성과가 AI-200덤프에 고스란히 담겨져 있어 시험합격율이 100%에 달한다고 해도 과언이 아닌것 같습니다.AI-200덤프 구매의향이 있으신 분은 구매페이지에서 덤프 데모문제를 다운받아 보시고 구매결정을 하시면 됩니다.KoreaDumps는 모든 분들이 시험에서 합격하시길 항상 기원하고 있습니다.
질문 # 22
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query returns one row per unique resultCode value with the number of requests in each group.
Does the solution meet the goal?
정답:B
설명:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
질문 # 23
You deploy a production Azure Function app that connects to an Azure SQL Database.
The solution must provide the following functionality:
* Prevent secrets from being exposed in source control.
* Support secret rotation without redeploying the function app.
* Avoid downtime during credential updates.
You need to configure secure and maintainable secret management. What should you configure?
정답:B
설명:
Detailed Explanation: Key Vault references in Function/App Service application settings keep the connection secret outside source control while allowing the platform to resolve it at runtime by identity. When a referenced secret version is not fixed, rotation can be picked up without rebuilding or redeploying the function code. `local.settings.json` is intended for local development and must not be used as a production secret store. A source-controlled parameter file or hard-coded connection string directly violates the security requirement.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions
질문 # 24
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.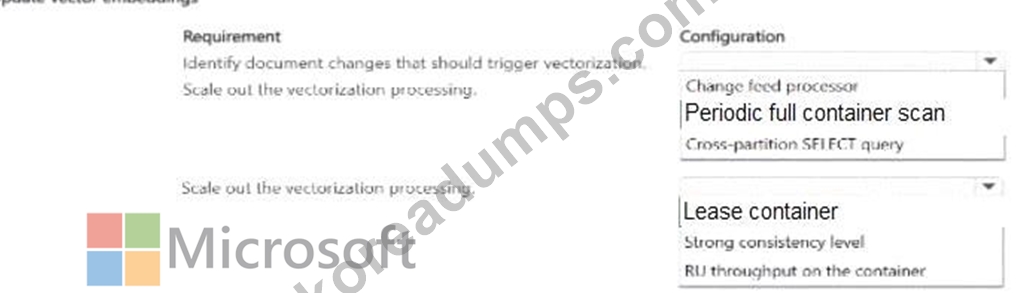
정답:
설명: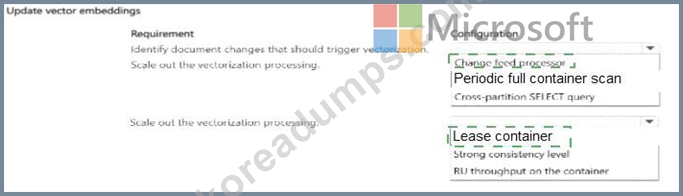
Explanation: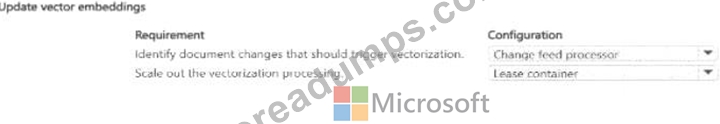
Verified answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
질문 # 25
Hotspot Question
You are creating an Azure Functions app project in your local development environment by using Azure Functions Core Tools.
You must create the project in either Python or C# without using a template.
You need to specify the command and its parameter required to create the Azure Functions app project.
Which command and parameter should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.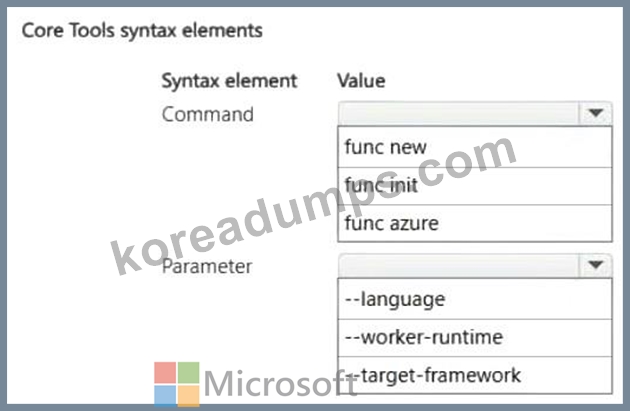
정답:
설명: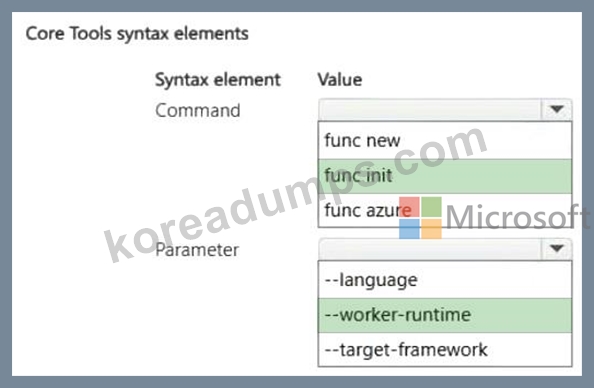
Explanation:
Box 1: func init
To initialize a new Azure Functions app project from the command line using Azure Functions Core Tools without using a specific code template, use the func init command combined with the -
-worker-runtime parameter.
Box 2: --worker-runtime
Reference:
https://r-vm.com/python-on-azure-functions
질문 # 26
You are provisioning and configuring a Service Bus processor for AI batch jobs.
The processor must connect to an existing queue, register handlers for message and error processing, and then begin receiving messages.
You need to provision and configure the Service Bus processor for message and error handling.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.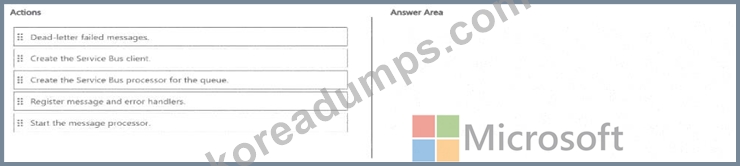
정답:
설명: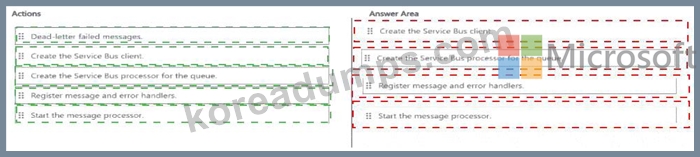
Explanation: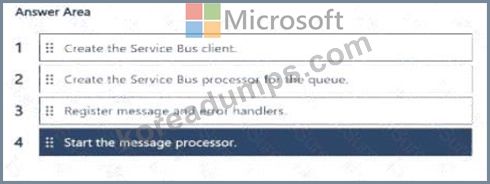
Verified Answer: 1) Create the Service Bus client; 2) create the queue processor/receiver; 3) register message and error handlers; 4) start the message processor.
Detailed Explanation: The processor depends on a namespace client/connection, so the client is created first.
Next, the queue-specific processor or receiver is created from that client. Message and error callbacks must be registered before processing starts so incoming messages and failures have defined handlers. Starting the processor is therefore the final step. Dead-lettering failed messages is an optional application settlement decision and is not a prerequisite for constructing and starting the processor.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
질문 # 27
......
KoreaDumps 질문 풀은 실제시험 변화의 기반에서 스케줄에 따라 업데이트 합니다. 만일 Microsoft AI-200테스트에 어떤 변화가 생긴다면, 적중율이 항상 98% 이상을 유지 할 수 있도록 2일간의 근무일 안에 제품을 업데이트 하도록 합니다. KoreaDumps는 고객들이 테스트에 성공적으로 합격 할 수 있도록 하기 위하여 업데이트 된 버전을 구매후 서비스로 제공해드립니다. 시험에서 불합격받으셨는데 업데이트가 힘든 상황이면 덤프비용을 환불해드립니다.
AI-200합격보장 가능 인증덤프: https://www.koreadumps.com/AI-200_exam-braindumps.html