BONUS!!! Download part of 2Pass4sure ARA-C01 dumps for free: https://drive.google.com/open?id=114JlTdlELZQ-AvMhp4m0B4WXp0jFeY76
2Pass4sure assists people in better understanding, studying, and passing more difficult certification exams. We take pride in successfully servicing industry experts by always delivering safe and dependable ARA-C01 exam preparation materials. For your convenience, 2Pass4sure has prepared authentic SnowPro Advanced Architect Certification (ARA-C01) exam study material based on a real exam syllabus to help candidates go through their ARA-C01 exams.
| Section | Objectives |
|---|---|
| Topic 1: Data Pipelines and Data Engineering | - Data orchestration
|
| Topic 2: Data Architecture and Design | - Design scalable Snowflake architectures
|
| Topic 3: Security, Governance, and Compliance | - Data governance
|
| Topic 4: Performance and Optimization | - Cost optimization
|
| Topic 5: Data Sharing and Collaboration | - Secure data sharing
|
>> New Snowflake ARA-C01 Test Price <<
Our passing rate of ARA-C01 learning quiz is 99% and our ARA-C01 practice guide boosts high hit rate. Our ARA-C01 test torrents are compiled by professionals and the answers and the questions we provide are based on the real exam. The content of our ARA-C01 exam questions is simple to be understood and mastered. To let you get well preparation for the exam, our software provides the function to stimulate the real exam and the timing function to help you adjust the speed. Based on those merits of our ARA-C01 Guide Torrent you can pass the ARA-C01 exam with high possibility.
NEW QUESTION # 81
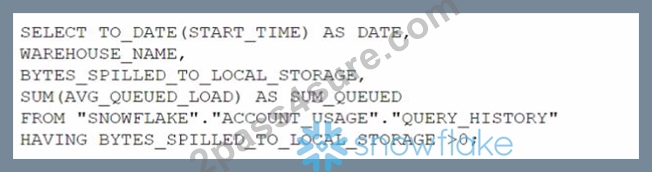
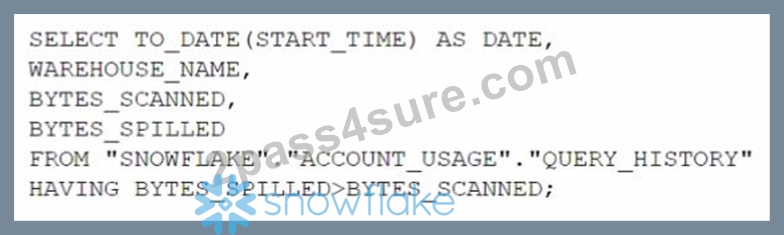
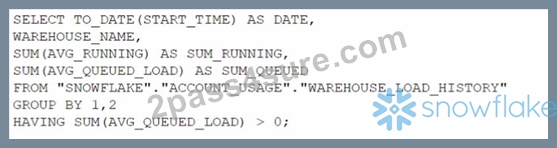
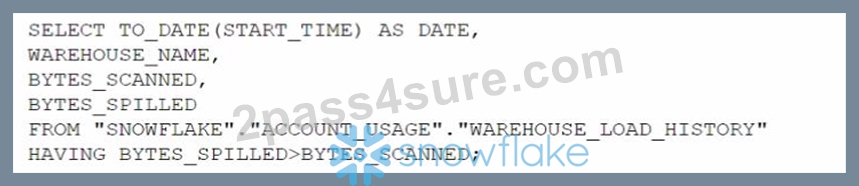
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: D
Explanation:
A multi-cluster warehouse is a virtual warehouse that can scale compute resources by adding or removing clusters based on the workload demand. A multi-cluster warehouse can improve the performance of a particular workload by reducing the query queue time and the data spillage to local storage. To identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse, you need to analyze the query history and look for the following indicators:
High average queued load: This metric shows the average number of queries waiting in the queue for each warehouse cluster. A high value indicates that the warehouse is overloaded and cannot handle the concurrency demand.
High bytes spilled to local storage: This metric shows the amount of data that was spilled from memory to local disk during query processing. A high value indicates that the warehouse size is too small and cannot fit the data in memory.
High variation in workload: This metric shows the fluctuation in the number of queries submitted to the warehouse over time. A high variation indicates that the workload is unpredictable and dynamic, and requires a flexible scaling policy.
The query in option C is the best one to identify these indicators, as it selects the date, warehouse name, bytes spilled to local storage, and sum of average queued load from the query history table, and filters the results where bytes spilled to local storage is greater than zero. This query will show the days and warehouses that experienced data spillage and high queue time, and could benefit from a multi-cluster warehouse with auto-scale mode.
The query in option A is not correct, as it only selects the date and warehouse name, and does not include any metrics to measure the performance of the workload. The query in option B is not correct, as it selects the date, warehouse name, and average execution time, which is not a good indicator of the need for a multi-cluster warehouse. The query in option D is not correct, as it selects the date, warehouse name, and average credits used, which is not a good indicator of the need for a multi-cluster warehouse either.
NEW QUESTION # 82
Based on the Snowflake object hierarchy, what securable objects belong directly to a Snowflake account?
(Select THREE).
Answer: C,D,F
Explanation:
A securable object is an entity to which access can be granted in Snowflake. Securable objects include databases, schemas, tables, views, stages, pipes, functions, procedures, sequences, tasks, streams, roles, warehouses, and shares1.
The Snowflake object hierarchy is a logical structure that organizes the securable objects in a nested manner.
The top-most container is the account, which contains all the databases, roles, and warehouses for the customer organization. Each database contains schemas, which in turn contain tables, views, stages, pipes, functions, procedures, sequences, tasks, and streams. Each role can be granted privileges on other roles or securable objects. Each warehouse can be used to execute queries on securable objects2.
Based on the Snowflake object hierarchy, the securable objects that belong directly to a Snowflake account are databases, roles, and warehouses. These objects are created and managed at the account level, and do not depend on any other securable object. The other options are not correct because:
Schemas belong to databases, not to accounts. A schema must be created within an existing database3.
Tables belong to schemas, not to accounts. A table must be created within an existing schema4.
Stages belong to schemas or tables, not to accounts. A stage must be created within an existing schema or table.
1: Overview of Access Control | Snowflake Documentation
2: Securable Objects | Snowflake Documentation
3: CREATE SCHEMA | Snowflake Documentation
4: CREATE TABLE | Snowflake Documentation
[5]: CREATE STAGE | Snowflake Documentation
NEW QUESTION # 83
An Architect is troubleshooting a query with poor performance using the QUERY function. The Architect observes that the COMPILATION_TIME Is greater than the EXECUTION_TIME.
What is the reason for this?
Answer: D
Explanation:
* The correct answer is B because the compilation time is the time it takes for the optimizer to create an optimal query plan for the efficient execution of the query. The compilation time depends on the complexity of the query, such as the number of tables, columns, joins, filters, aggregations, subqueries, etc. The more complex the query, the longer it takes to compile.
* Option A is incorrect because the query processing time is not affected by the size of the dataset, but by the size of the virtual warehouse. Snowflake automatically scales the compute resources to match the data volume and parallelizes the query execution. The size of the dataset may affect the execution time, but not the compilation time.
* Option C is incorrect because the query queue time is not part of the compilation time or the execution time. It is a separate metric that indicates how long the query waits for a warehouse slot before it starts
* running. The query queue time depends on the warehouse load, concurrency, and priority settings.
* Option D is incorrect because the query remote IO time is not part of the compilation time or the execution time. It is a separate metric that indicates how long the query spends reading data from remote storage, such as S3 or Azure Blob Storage. The query remote IO time depends on the network latency, bandwidth, and caching efficiency. References:
* Understanding Why Compilation Time in Snowflake Can Be Higher than Execution Time: This article explains why the total duration (compilation + execution) time is an essential metric to measure query performance in Snowflake. It discusses the reasons for the long compilation time, including query complexity and the number of tables and columns.
* Exploring Execution Times: This document explains how to examine the past performance of queries and tasks using Snowsight or by writing queries against views in the ACCOUNT_USAGE schema. It also describes the different metrics and dimensions that affect query performance, such as duration, compilation, execution, queue, and remote IO time.
* What is the "compilation time" and how to optimize it?: This community post provides some tips and best practices on how to reduce the compilation time, such as simplifying the query logic, using views or common table expressions, and avoiding unnecessary columns or joins.
NEW QUESTION # 84
You have created a table as below
CREATE TABLE TEST_01 (NAME STRING(10));
What data type SNOWFLAKE will assign to column NAME?
Answer: B
NEW QUESTION # 85
You have created a table as below
CREATE TABLE SNOWFLAKE (FLAKE_ID INTEGER, UDEMY_COURSE VARCHAR);
Which of the below select query will fail for this table?
Answer: D
NEW QUESTION # 86
......
Another great way to assess readiness is the Snowflake ARA-C01 web-based practice test. This is one of the trusted online Snowflake ARA-C01 prep materials to strengthen your concepts. All specs of the desktop software are present in the web-based Snowflake ARA-C01 Practice Exam.
Best ARA-C01 Preparation Materials: https://www.2pass4sure.com/SnowPro-Advanced-Certification/ARA-C01-actual-exam-braindumps.html
BTW, DOWNLOAD part of 2Pass4sure ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=114JlTdlELZQ-AvMhp4m0B4WXp0jFeY76