Databricks Certified-Data-Engineer-Professional인기자격증시험덤프 & Certified-Data-Engineer-Professional덤프공부자료

IT업종 종사자분들은 모두 승진이나 연봉인상을 위해 자격증을 취득하려고 최선을 다하고 계실것입니다. 하지만 쉴틈없는 야근에 시달려서 공부할 시간이 없어 스트레스가 많이 쌓였을것입니다. PassTIP의Databricks인증 Certified-Data-Engineer-Professional덤프로Databricks인증 Certified-Data-Engineer-Professional시험공부를 해보세요. 시험문제커버율이 높아 덤프에 있는 문제만 조금의 시간의 들여 공부하신다면 누구나 쉽게 시험패스가능합니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 2: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Topic 4: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 5: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 6: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Topic 7: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 8: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 10: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Databricks Certified-Data-Engineer-Professional인기자격증 시험덤프 <<
시험패스 가능한 Certified-Data-Engineer-Professional인기자격증 시험덤프 인증공부자료
Databricks Certified-Data-Engineer-Professional 인증시험은 최근 가장 핫한 시험입니다. 인기가 높은 만큼Databricks Certified-Data-Engineer-Professional시험을 패스하여 취득하게 되는 자격증의 가치가 높습니다. 이렇게 좋은 자격증을 취득하는데 있어서의 필수과목인Databricks Certified-Data-Engineer-Professional시험을 어떻게 하면 한번에 패스할수 있을가요? 그 비결은 바로PassTIP의 Databricks Certified-Data-Engineer-Professional덤프를 주문하여 가장 빠른 시일내에 덤프를 마스터하여 시험을 패스하는것입니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q104-Q109):
질문 # 104
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- B. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
- C. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
- D. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
정답:D
설명:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
질문 # 105
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table.
The profile metrics table (prod_catalog.prod_schema.customer_data_profile_metrics) stores hourly percent_null values.
The team wants to:
Trigger an alert when the daily average of percent_null exceeds 5% for
three consecutive days.
Ensure that notifications are not spammed during sustained issues.
- A. SELECT SUM(CASE WHEN percent_null > 5 THEN 1 ELSE 0 END) AS violation_days FROM prod_catalog.prod_schema.customer_data_profile_metrics WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY Alert Condition: violation_days >= 3 Notification Frequency: Just once
- B. WITH daily_avg AS (
SELECT DATE_TRUNC('DAY', window.end) AS day,
AVG(percent_null) AS avg_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
GROUP BY DATE_TRUNC('DAY', window.end)
)
SELECT day, avg_null
FROM daily_avg
ORDER BY day DESC
LIMIT 3
Alert Condition: ALL avg_null > 5 for the latest 3 rows
Notification Frequency: Just once - C. SELECT percent_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '1' DAY
Alert Condition: percent_null > 5
Notification Frequency: At most every 24 hours - D. SELECT AVG(percent_null) AS daily_avg
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY
Alert Condition: daily_avg > 5
Notification Frequency: Each time alert is evaluated
정답:B
설명:
The key requirement is to detect when the daily average of percent_null is greater than 5% for three consecutive days.
Option A only checks the last 24 hours, not consecutive days. It would trigger too frequently and cause spam.
Option C calculates an average across all records in the last 3 days, but this could be skewed by one high or low day -- it does not ensure consecutive daily violations.
Option D simply counts days where the threshold was exceeded, but it does not guarantee that those days were consecutive. This could incorrectly trigger on non-adjacent violations.
Option B is correct:
It aggregates hourly values into daily averages.
It checks that the last 3 consecutive days all had averages above 5%.
It avoids redundant alerts by using Notification Frequency: Just once.
This matches Databricks Lakehouse Monitoring best practices, where SQL alerts should be designed to aggregate metrics to the correct granularity (daily here) and ensure consecutive threshold violations before triggering.
질문 # 106
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
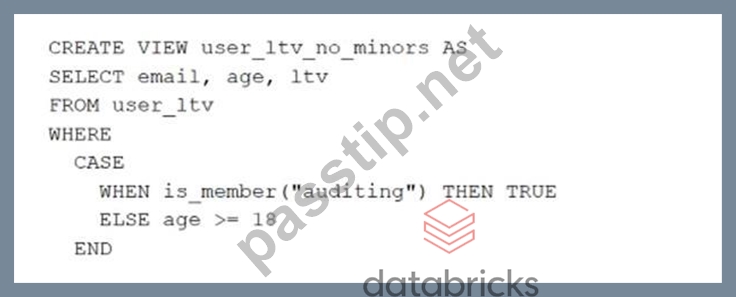
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- B. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- C. All records from all columns will be displayed with the values in user_ltv.
- D. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- E. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
정답:B
설명:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
질문 # 107
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
- A. Use Lakeflow Declarative Pipelines for batch and streaming ingestion, define a PII masking function, and apply it during Bronze ingestion before writing to Delta Lake.
- B. Allow PII to be stored unmasked in Bronze for lineage tracking, then apply masking logic in Gold tables used for reporting.
- C. Ingest both batch and streaming data using Lakeflow Declarative Pipelines, and apply masking via Unity Catalog column masks at read time to avoid modifying the data during ingestion.
- D. Load batch data with notebooks and ingest streaming data with SQL Warehouses; use Unity Catalog column masks on Silver tables to redact fields after storage.
정답:A
설명:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
질문 # 108
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
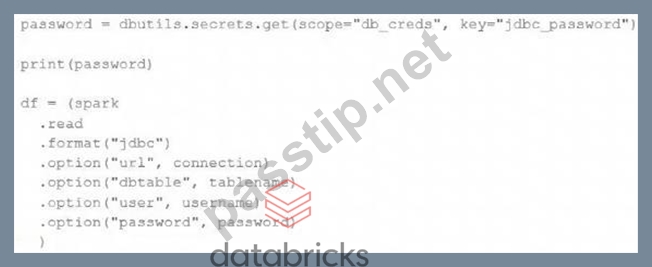
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will fail; the string "redacted" will be printed.
- B. The connection to the external table will succeed; the string value of password will be printed in plain text.
- C. The connection to the external table will succeed; the string "redacted" will be printed.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- E. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
정답:C
설명:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
질문 # 109
......
경쟁율이 점점 높아지는 IT업계에 살아남으려면 국제적으로 인증해주는 IT자격증 몇개쯤은 취득해야 되지 않을가요? Databricks Certified-Data-Engineer-Professional시험으로부터 자격증 취득을 시작해보세요. Databricks Certified-Data-Engineer-Professional 덤프의 모든 문제를 외우기만 하면 시험패스가 됩니다. Databricks Certified-Data-Engineer-Professional덤프는 실제 시험문제의 모든 유형을 포함되어있어 적중율이 최고입니다.
Certified-Data-Engineer-Professional덤프공부자료: https://www.passtip.net/Certified-Data-Engineer-Professional-pass-exam.html
- Certified-Data-Engineer-Professional퍼펙트 최신 덤프자료 👰 Certified-Data-Engineer-Professional높은 통과율 인기 덤프문제 🦐 Certified-Data-Engineer-Professional퍼펙트 공부자료 🪑 지금⇛ www.koreadumps.com ⇚에서《 Certified-Data-Engineer-Professional 》를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional시험유효자료
- Certified-Data-Engineer-Professional인기자격증 시험덤프 완벽한 시험 최신 덤프 🧈 ➥ Certified-Data-Engineer-Professional 🡄를 무료로 다운로드하려면「 www.itdumpskr.com 」웹사이트를 입력하세요Certified-Data-Engineer-Professional덤프샘플 다운
- 시험패스 가능한 Certified-Data-Engineer-Professional인기자격증 시험덤프 덤프공부 🆘 무료로 쉽게 다운로드하려면▶ www.passtip.net ◀에서▷ Certified-Data-Engineer-Professional ◁를 검색하세요Certified-Data-Engineer-Professional덤프샘플 다운
- Certified-Data-Engineer-Professional인기자격증 시험덤프 완벽한 시험 최신 덤프 🤨 무료 다운로드를 위해 지금➥ www.itdumpskr.com 🡄에서《 Certified-Data-Engineer-Professional 》검색Certified-Data-Engineer-Professional높은 통과율 인기 덤프문제
- Certified-Data-Engineer-Professional덤프샘플 다운 😪 Certified-Data-Engineer-Professional시험대비 덤프 최신문제 💔 Certified-Data-Engineer-Professional높은 통과율 인기 덤프문제 ▶ 《 www.pass4test.net 》에서「 Certified-Data-Engineer-Professional 」를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional시험대비 덤프공부자료
- Certified-Data-Engineer-Professional시험대비덤프 😆 Certified-Data-Engineer-Professional최고덤프공부 ↗ Certified-Data-Engineer-Professional최신버전 시험덤프문제 🍘 무료로 쉽게 다운로드하려면➥ www.itdumpskr.com 🡄에서✔ Certified-Data-Engineer-Professional ️✔️를 검색하세요Certified-Data-Engineer-Professional높은 통과율 인기 덤프문제
- Certified-Data-Engineer-Professional인기자격증 시험덤프 100% 유효한 덤프공부자료 😤 ⮆ www.itdumpskr.com ⮄웹사이트를 열고《 Certified-Data-Engineer-Professional 》를 검색하여 무료 다운로드Certified-Data-Engineer-Professional시험패스 가능 덤프자료
- Certified-Data-Engineer-Professional시험대비 덤프 최신문제 🤗 Certified-Data-Engineer-Professional최신 덤프데모 ⚒ Certified-Data-Engineer-Professional최신 덤프데모 🕡 무료로 다운로드하려면▷ www.itdumpskr.com ◁로 이동하여▷ Certified-Data-Engineer-Professional ◁를 검색하십시오Certified-Data-Engineer-Professional시험패스 가능한 인증공부자료
- 시험패스 가능한 Certified-Data-Engineer-Professional인기자격증 시험덤프 덤프공부 ⤴ 무료 다운로드를 위해 지금【 www.exampassdump.com 】에서《 Certified-Data-Engineer-Professional 》검색Certified-Data-Engineer-Professional퍼펙트 최신 덤프자료
- Certified-Data-Engineer-Professional퍼펙트 공부자료 😨 Certified-Data-Engineer-Professional시험대비 최신버전 덤프샘플 🖕 Certified-Data-Engineer-Professional시험대비 덤프공부자료 📼 무료로 다운로드하려면《 www.itdumpskr.com 》로 이동하여☀ Certified-Data-Engineer-Professional ️☀️를 검색하십시오Certified-Data-Engineer-Professional퍼펙트 인증덤프자료
- Certified-Data-Engineer-Professional시험대비 최신버전 덤프샘플 ❇ Certified-Data-Engineer-Professional퍼펙트 인증덤프자료 🧿 Certified-Data-Engineer-Professional시험패스 가능 덤프자료 📶 지금➠ kr.fast2test.com 🠰을(를) 열고 무료 다운로드를 위해{ Certified-Data-Engineer-Professional }를 검색하십시오Certified-Data-Engineer-Professional퍼펙트 공부자료
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes