無料でクラウドストレージから最新のShikenPASS SPS-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1crSdp9ISYJBpDEJXl8YefNmN69Md8PWM
当社SnowflakeのSPS-C01学習教材は、複数のエクスペリエンスモードを提供できます。3つの主要なモードから選択できます:PDF、ソフトウェア、オンライン。 まず、ShikenPASSPDFバージョンは印刷可能です。 第二に、SPS-C01試験問題のソフトウェアバージョンでは、実際の試験環境をシミュレートして、試験体験をより鮮明にできます。 第三に、オンライン版はすべてのWebブラウザをサポートしているため、すべてのオペレーティングシステムで動作します。 また、SPS-C01学習教材は、よりリラックスした学習環境でSPS-C01試験に合格するのに役立ちます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and DataFrame Operations | 35% | - Window functions - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Complex data pipelines - Using built-in functions |
| Topic 2: Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Transformations vs. Actions - Stored procedures and conditional logic - Client-side vs. Server-side execution - Snowpark architecture and core concepts |
| Topic 3: Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Minimizing data transfer - Debugging and explain plans - Warehouse sizing for Snowpark - Caching strategies - Query pushdown and optimization |
| Topic 4: Snowpark API for Python | 30% | - Working with Semi-structured data - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - Reading and writing data |
あなたより優れる人は存在している理由は彼らはあなたの遊び時間を効率的に使用できることです。どのようにすばらしい人になれますか?ここで、あなたに我々のSnowflake SPS-C01試験問題集をお勧めください。弊社ShikenPASSのSPS-C01試験問題集を介して、速く試験に合格してSPS-C01試験資格認定書を受け入れる一方で、他の人が知らない知識を勉強して優れる人になることに近くなります。
質問 # 370
You are tasked with creating a secure UDF in Snowflake using Snowpark Python API that encrypts sensitive customer data before storing it. The UDF should be accessible only to users with specific roles. You have the following code snippet. What needs to be done to make it secure and operationalize for multiple users?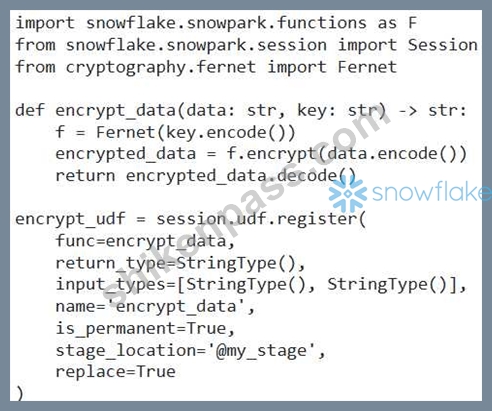
Considering Security best practices, what steps are critical for securing the UDF and granting appropriate permissions to other users?
正解:D、E
解説:
Storing the encryption key directly in the UDF code is a major security vulnerability. Snowflake's Secret object provides a secure way to store and manage sensitive information like encryption keys. Granting EXECUTE privilege on the UDF and USAGE privilege on the database and schema is essential for allowing authorized users to execute the UDF. USAGE privilege on the database and schema allows users to 'see' the UDF. Option C is incorrect because granting global USAGE privilege on the stage location is overly permissive. Option E is incorrect as bypassing role-based access control is insecure.
質問 # 371
You have a Snowpark DataFrame 'df containing customer data with columns 'customer_id', 'signup_date' (TIMESTAMP NTZ), and 'country'. You need to create a new DataFrame that calculates the number of days since each customer signed up, but only for customers in 'USA' and 'Canada'. Furthermore, you want to filter out records where the signup was more than 365 days ago. Which of the following Snowpark code snippets will achieve this most efficiently?





正解:D
解説:
Option E is the most efficient. It first filters the DataFrame by country using 'isin' , which is optimized for multiple values. Then, it calculates 'days_since_signup' using 'datediff and finally filters based on the number of days. Option A is correct but not as efficient as using 'isin-. Option B calculates 'days_since_signup' before filtering, which is less efficient. Option C uses 'to_number' which would result in the difference being represented in milliseconds and would require further conversion. Also using 'to_number' may lead to data loss. Option D has incorrect operator precedence in the 'where' clause, making it functionally wrong.
質問 # 372
You are developing a Snowpark application that involves creating a set of stored procedures and UDFs to process data'. To ensure proper version control and dependency management, you decide to package your Python code into a single Python Wheel file and deploy it to Snowflake. Which of the following methods are valid for deploying and utilizing this Python Wheel file within Snowflake, considering best practices for maintainability and security? (Select TWO)
正解:B、D
解説:
Options D and E are the correct answers. Creating a Conda environment file and deploying it to Snowflake (Option D) allows for explicit version control and dependency management, ensuring consistent execution across environments. You need to upload the environment.yml which contains the packages and custom wheel you need to add. Using 'snowflake-cli' to push wheel as a package (Option E) is the approach for using custom packages. These are the recommended approaches. Uploading wheel files to internal or external stages and referencing them using the 'USING' clause (Options A and B) might work, but it lacks the structured dependency management provided by Conda environments. Snowsight cannot be used to directly upload wheels for environment setup (Option C).
質問 # 373
You are developing a Snowpark stored procedure in Python to perform sentiment analysis on customer reviews. The procedure relies on a custom Python library, 'sentiment_analyzer.py' , which is not available in Snowflake's default Anaconda channel. You also need to include the 'nltk' library. Which of the following approaches is the MOST efficient and recommended way to make both dependencies available to your stored procedure within Snowflake?
正解:E
解説:
Option C is the most efficient and recommended approach. Snowflake allows importing dependencies from a stage as a ZIP file. This avoids the complexity of creating a custom Anaconda package (Option B) or manually managing dependencies on each virtual warehouse node (Option D), which is not supported. Directly including the code (Option E) makes the procedure large and difficult to manage. Using (Option A) is generally discouraged as it's less robust for dependency management in Snowpark stored procedures.
質問 # 374
You have a Snowflake view named 'SALES SUMMARY VW' that joins several large tables and performs complex aggregations. You need to create a Snowpark DataFrame from this view Which of the following considerations are MOST important to ensure optimal performance and resource utilization when working with this DataFrame?
正解:B、C
解説:
Options A and C are crucial. Option A highlights the danger of bringing large datasets into the client environment. Option C emphasizes the importance of Snowpark's core principles for efficiency. Option B is incorrect; Snowpark can efficiently infer the schema. Option D is generally less optimal than using 'session.table()' directly for views because 'session.table()' provides more opportunities for optimization by Snowpark. Option E materializes the view which would consume storage and may not be ideal unless intermediate results needs to be re-used multiple times. Furthermore temporary tables are only viable in current session context
質問 # 375
......
優れたSPS-C01試験問題を使用すると、SPS-C01認定資格を取得して自分自身を向上させ、より良い未来とより良い未来を実現することができます。 SPS-C01トレーニングガイドを使用すると、職業で認められます。 SPS-C01試験のブレーンダンプは、より大きな会社に注目させる能力を証明できます。 その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。 SPS-C01試験問題を試してみてはいかがですか。SPS-C01試験問題が最高の準備資料であることに驚かれることでしょう。
SPS-C01絶対合格: https://www.shikenpass.com/SPS-C01-shiken.html
ちなみに、ShikenPASS SPS-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1crSdp9ISYJBpDEJXl8YefNmN69Md8PWM