P.S. KaoGuTi在Google Drive上分享了免費的、最新的DAA-C01考試題庫:https://drive.google.com/open?id=1tAiJeZWGNdbCUbTEWk4czcurqsIHPkiT
人生有太多的變數和未知的誘惑,所以我們趁年輕時要為自己打下堅實的基礎,你準備好了嗎?KaoGuTi Snowflake的DAA-C01考試培訓資料將是最好的培訓資料,它的效果將是你終生的伴侶,作為IT行業的你,你體會到緊迫感了嗎?選擇KaoGuTi,你將打開你的成功之門,裏面有最閃耀的光芒等得你去揮灑,加油!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Perform Simple Data Transformations for Analysis | 15–20% | - Handling NULLs and structuring datasets - Views, materialized views, CTEs - Data cleansing, standardization, type conversion |
| Topic 2: Prepare and Present Data | 10–15% | - Align outputs with business requirements - Data visualization and reporting - Snowsight dashboards and sharing results |
| Topic 3: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Query optimization and troubleshooting - Complex joins, subqueries, window functions - Semi-structured data processing |
| Topic 4: Prepare and Load Data | 15–20% | - External tables and data validation - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe |
| Topic 5: Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis - Anomaly detection and root cause analysis |
| Topic 6: Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Topic 7: Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
KaoGuTi的DAA-C01考古題的命中率很高,可以幫助大家一次通過考試。這是經過很多考生證明過的事實。所以不用擔心這個考古題的品質,這絕對是最值得你信賴的考試資料。如果你還是不相信的話,那就趕快自己來體驗一下吧。你绝对会相信我的话的。
問題 #36
You are analyzing customer churn for a subscription-based service. You have a table 'SUBSCRIPTIONS' with columns: 'CUSTOMER_ID, 'START_DATE', 'END_DATE', 'SUBSCRIPTION TYPE, and 'REVENUE'. You want to classify customers who are likely to churn based on their past subscription behavior. Which Snowflake SQL code snippet is MOST efficient for calculating the number of months each customer was subscribed and identifying those who subscribed for less than 3 months as potential churn candidates?




答案:D
解題說明:
Option D is the most efficient. It calculates the 'MONTHS SUBSCRIBED directly in the SELECT statement and filters the results in the 'WHERE clause. Option A will produce an error because you cannot refer to an alias (MONTHS_SUBSCRIBED) in the same 'WHERE clause where it's defined. Option B creates a temporary table, which is unnecessary overhead for this simple calculation. Option C uses HAVING& which is used for filtering aggregated results, not individual rows before aggregation. Snowflake does not natively support MONTHS_BETWEEN, thus option E would result in an error.
問題 #37
You are working with a table named 'PRODUCT DESCRIPTIONS that contains product descriptions in a 'description' (VARCHAR) column. You need to implement a solution to identify potentially sensitive information within these descriptions, specifically looking for mentions of credit card numbers or social security numbers (SSNs). You want to flag any description that contains either of these patterns. Which of the following Snowflake SQL snippets, leveraging scalar string functions and regular expressions, provides the most efficient and accurate way to achieve this? (Assume that valid credit card numbers are 16 digits and valid SSNs are in the format 'XXX-XX-XXXX'). Select all correct options.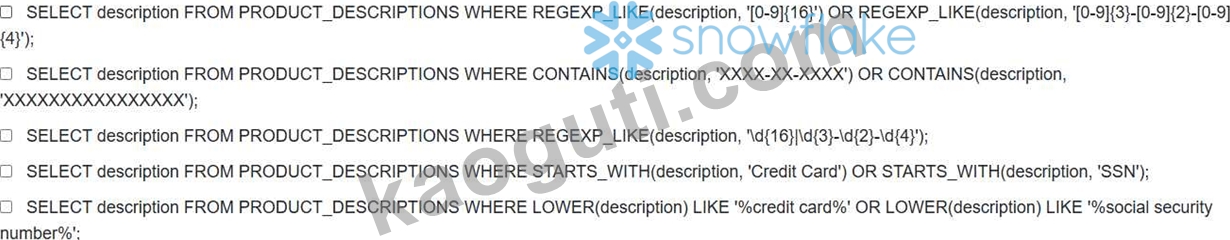
答案:B,C
解題說明:
Options A and C are both correct. Option A uses 'REGEXP_LIKE with two separate regular expressions to search for a 16-digit number (credit card) and a 'XXX-XX-XXXX' pattern (SSN). Option C uses a single 'REGEXP LIKE' function with an alternation to combine both patterns into one regular expression , which is generally more efficient. Option B relies on 'CONTAINS' which performs a simple substring search, not regular expression matching; this will not accurately identify the patterns. Option D uses 'STARTS WITH' which will only identify descriptions that begin with the specified keywords, missing most cases. Option E uses 'LIKE operator for the mentioned words in the sentence that can be 'Credit Card' or 'Social Security Number', but this isn't a search for Credit card numbers or SSNs.
問題 #38
In Snowflake, how does the implementation of primary keys for tables contribute to data integrity?
答案:B
解題說明:
Primary keys enforce uniqueness in table rows, ensuring data integrity by preventing duplicate entries within a table.
問題 #39
You are preparing a CSV file for ingestion into Snowflake, and you need to ensure that the data types are correctly interpreted. The CSV contains a column named 'transaction_amount' that sometimes contains values with leading zeros (e.g., '00123.45'). You want to load this data into a Snowflake table where 'transaction_amount' is defined as NUMBER(IO, 2). Without modifying the CSV file itself, how can you ensure that the leading zeros are handled correctly during the COPY INTO operation?
答案:B
解題說明:
Option E is the correct approach. Snowflake implicitly handles leading zeros when casting a VARCHAR column to a NUMBER type using during the COPY INTO operation. This avoids modifying the original CSV file or requiring a separate transformation step after loading. Option A is incorrect, as implicit type conversion might not always work as expected. Option B and C are incorrect because 'STRIP NULL_VALUE' is not relevant in the case of leading zeros. Option D is viable, but less efficient than handling during load time.
問題 #40
A financial institution uses Snowflake to store customer transaction data'. They need to create a dashboard that visualizes daily transaction volume and average transaction amount for fraud detection purposes. This dashboard needs to be automatically updated every hour. The current dashboard query performance is slow, especially during peak hours. Given that the 'TRANSACTIONS table contains billions of rows, which of the following strategies would BEST optimize both the query performance and the automated update process?
答案:B
解題說明:
Materialized views are designed for pre-computation of aggregations, providing significant performance improvements. Scheduling a task to refresh the materialized view ensures automatic updates. Regular views are calculated at query time and would not improve performance. Increasing warehouse size (C) might help, but it's not the most efficient solution. Temporary tables are not persistent and truncation/reload is inefficient. Dashboard caching (E) does not solve underlying Snowflake performance issues.
問題 #41
......
DAA-C01 認證可代表豐富且多樣化的工作角色及責任。因此,取得特定的認證將可做為具備成功執行重要IT功能所需之能力的最佳證明。由於受到全世界企業專家的熱烈支持,DAA-C01 認證仍是達到長期事業目標的最有效率的方法之一,並且是公司用來開發及留住重要IT人員的不二法門。但是如何在第一次嘗試中就能有效的通過Snowflake 的 DAA-C01 認證考試?這個問題的答案隨著 KaoGuTi 產生已經不再是問題了。
最新DAA-C01考古題: https://www.kaoguti.com/DAA-C01_exam-pdf.html
順便提一下,可以從雲存儲中下載KaoGuTi DAA-C01考試題庫的完整版:https://drive.google.com/open?id=1tAiJeZWGNdbCUbTEWk4czcurqsIHPkiT