참고: KoreaDumps에서 Google Drive로 공유하는 무료 2026 Snowflake DAA-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1_C7KmvfqcAwbxhLAhE9pAA4Ag5QhbD41
KoreaDumps의Snowflake인증 DAA-C01덤프는 고객님의 IT인증자격증을 취득하는 소원을들어줍니다. IT업계에 금방 종사한 분은 자격증을 많이 취득하여 자신만의 가치를 업그레이드할수 있습니다. KoreaDumps의Snowflake인증 DAA-C01덤프는 실제 시험문제에 대비하여 연구제작된 퍼펙트한 시험전 공부자료로서 시험이 더는 어렵지 않게 느끼도록 편하게 도와드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Topic 2: Prepare and Present Data | 10–15% | - Snowsight dashboards and sharing results - Data visualization and reporting - Align outputs with business requirements |
| Topic 3: Prepare and Load Data | 15–20% | - External tables and data validation - Data ingestion methods: COPY INTO, stages, Snowpipe - File formats: CSV, JSON, Parquet, Avro |
| Topic 4: Perform Simple Data Transformations for Analysis | 15–20% | - Views, materialized views, CTEs - Handling NULLs and structuring datasets - Data cleansing, standardization, type conversion |
| Topic 5: Use Built-in Functions and Create UDFs | 10–15% | - Scalar, aggregate, table, system functions - User-Defined Functions (UDFs) |
| Topic 6: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Query optimization and troubleshooting - Complex joins, subqueries, window functions - Semi-structured data processing |
| Topic 7: Perform Descriptive and Diagnostic Analysis | 10–15% | - Anomaly detection and root cause analysis - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis |
KoreaDumps는 모든 IT관련 인증시험자료를 제공할 수 있는 사이트입니다. 우리KoreaDumps는 여러분들한테 최고 최신의 자료를 제공합니다. KoreaDumps을 선택함으로 여러분은 이미Snowflake DAA-C01시험을 패스하였습니다. 우리 자료로 여러분은 충분히Snowflake DAA-C01를 패스할 수 있습니다. 만약 시험에서 떨어지셨다면 우리는 백프로 환불은 약속합니다. 그리고 갱신이 된 최신자료를 보내드립니다. 하지만 이런사례는 거이 없었습니다.모두 한번에 패스하였기 때문이죠. KoreaDumps는 여러분이Snowflake DAA-C01인증시험 패스와 추후사업에 모두 도움이 되겠습니다. Pass4Tes의 선택이야말로 여러분의 현명한 선택이라고 볼수 있습니다. Pass4Tes선택으로 여러분은 시간도 절약하고 돈도 절약하는 일석이조의 득을 얻을수 있습니다. 또한 구매후 일년무료 업데이트버전을 바을수 있는 기회를 얻을수 있습니다.
질문 # 36
Which Snowflake feature allows users to encapsulate a series of SQL statements into a reusable database object, facilitating modular code development?
정답:A
질문 # 37
You are responsible for loading data into a Snowflake table named 'CUSTOMER DATA' from a series of compressed JSON files located in a Google Cloud Storage (GCS) bucket. The data volume is significant, and the loading process needs to be as efficient as possible. The JSON files are compressed using GZIP, and they contain a field called 'registration date' that should be loaded as a DATE type in Snowflake. However, some files contain records where the 'registration_date' is missing or has an invalid format. Your goal is to load all valid data while skipping any files that contain invalid dates, and log any files that contain invalid records. You want to choose the most efficient approach. Which of the following options represents the best strategy to achieve this?
정답:E
설명:
The correct answer is E. Using gracefully handles invalid dates by returning NULL, which can be managed using a default value on the target table. 'ON ERROR = CONTINUE' ensures the loading process doesn't halt. Combining this with a default value provides for a fast, efficient load. Option A skips the entire file, which is not desired if only some records are invalid. Option B will halt the load process if the target field cannot accept a value. Option C is valid but requires a separate process. Option D makes the manual handling more complex since Snowpipe is designed for near real time instead of batch. E is the best option as all invalid fields will be populated with the default value and load will be unaffected.
질문 # 38
Which aspects are crucial for making predictions based on data for forecasting purposes? (Select all that apply)
정답:A,B
설명:
Incorporating statistical methods and considering trends/anomalies are crucial for accurate predictions in forecasting.
질문 # 39
Consider the following chart.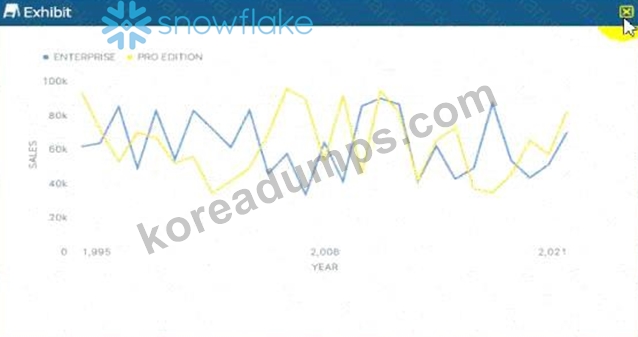
What can be said about the correlation for sales over time between the two categories?
정답:D
설명:
In Data Analysis, correlation refers to a statistical relationship between two variables. When analyzing a time- series chart like the one provided, a Data Analyst looks for patterns in how the two categories-"Enterprise" (blue line) and "Pro Edition" (yellow line)-move in relation to one another over the X-axis (Year).
A Positive Correlation would be indicated if both lines generally moved in the same direction at the same time (e.g., when Enterprise sales increase, Pro Edition sales also increase). A Negative Correlation (or inverse correlation) would be shown if the lines moved in opposite directions consistently (e.g., when one peaks, the other troughs).
Looking closely at the provided exhibit, the fluctuations for both editions are highly erratic and appear independent of each other. For instance, around the year 2008, the Pro Edition (yellow) shows a significant peak while the Enterprise edition (blue) experiences a sharp decline. Conversely, in other sections of the chart, they both dip or rise simultaneously by chance, but there is no sustained, predictable pattern of movement. The peaks and valleys do not align in a way that suggests one variable's movement is tied to the other.
Statistically, this lack of a discernible relationship indicates a Correlation Coefficient near zero. In the context of the Snowflake Snowpro Advanced: Data Analyst exam, identifying "No Correlation" is a key skill for interpreting Snowsight visualizations. It tells the analyst that the factors driving sales for the Enterprise tier are likely distinct from those driving the Pro Edition, and they should be analyzed as independent segments rather than interdependent variables. Therefore, based on the visual evidence of random, non- synchronous movement across the timeline, the only supported conclusion is that there is no correlation.
질문 # 40
You are tasked with cleaning a 'COMMENTS table that contains user-generated comments in a column (VARCHAR). The comments often contain HTML tags, excessive whitespace, and potentially malicious scripts. Your goal is to remove all HTML tags, trim leading and trailing whitespace, and escape any remaining HTML entities to prevent script injection vulnerabilities. Which combination of Snowflake scalar functions provides the most robust and secure way to achieve this data cleaning?
정답:D
설명:
Option B is the most robust and secure method. Here's why: 'REGEXP REPLACE(comment_text, Y', "Y: This removes HTML tags. This attempts to parse the remaining text as XML. If there are still any unescaped or malformed HTML entities, this step will help to isolate them and get rid of the tags. If the text cannot be parsed as XML, PARSE_XML returns NULL. '$').$: This extracts the text content of the XML. Crucially, 'XMLGET' inherently performs HTML entity decoding, effectively escaping potentially dangerous characters (e.g., becomes This prevents script injection. This removes leading and trailing whitespace. Option A only removes the HTML tags and trims the text, but doesn't handle HTML entity encoding, and thus it is vulnerable to script injection. Option C is not correct as HTML ENTITY DECODE' is not an existing function in Snowflake. Option D is not correct as the text needs to be cleaned irrespective of whether it contains XML or not. Option E - if parsing the XML returns null then original value gets returned , which we don't want , we would need to make the value NULL.
질문 # 41
......
KoreaDumps의 Snowflake인증 DAA-C01덤프는 거의 모든 실제시험문제 범위를 커버하고 있습니다.Snowflake인증 DAA-C01시험덤프를 구매하여 덤프문제로 시험에서 불합격성적표를 받을시KoreaDumps에서는 덤프비용 전액 환불을 약속드립니다.
DAA-C01학습자료: https://www.koreadumps.com/DAA-C01_exam-braindumps.html
그리고 KoreaDumps DAA-C01 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1_C7KmvfqcAwbxhLAhE9pAA4Ag5QhbD41